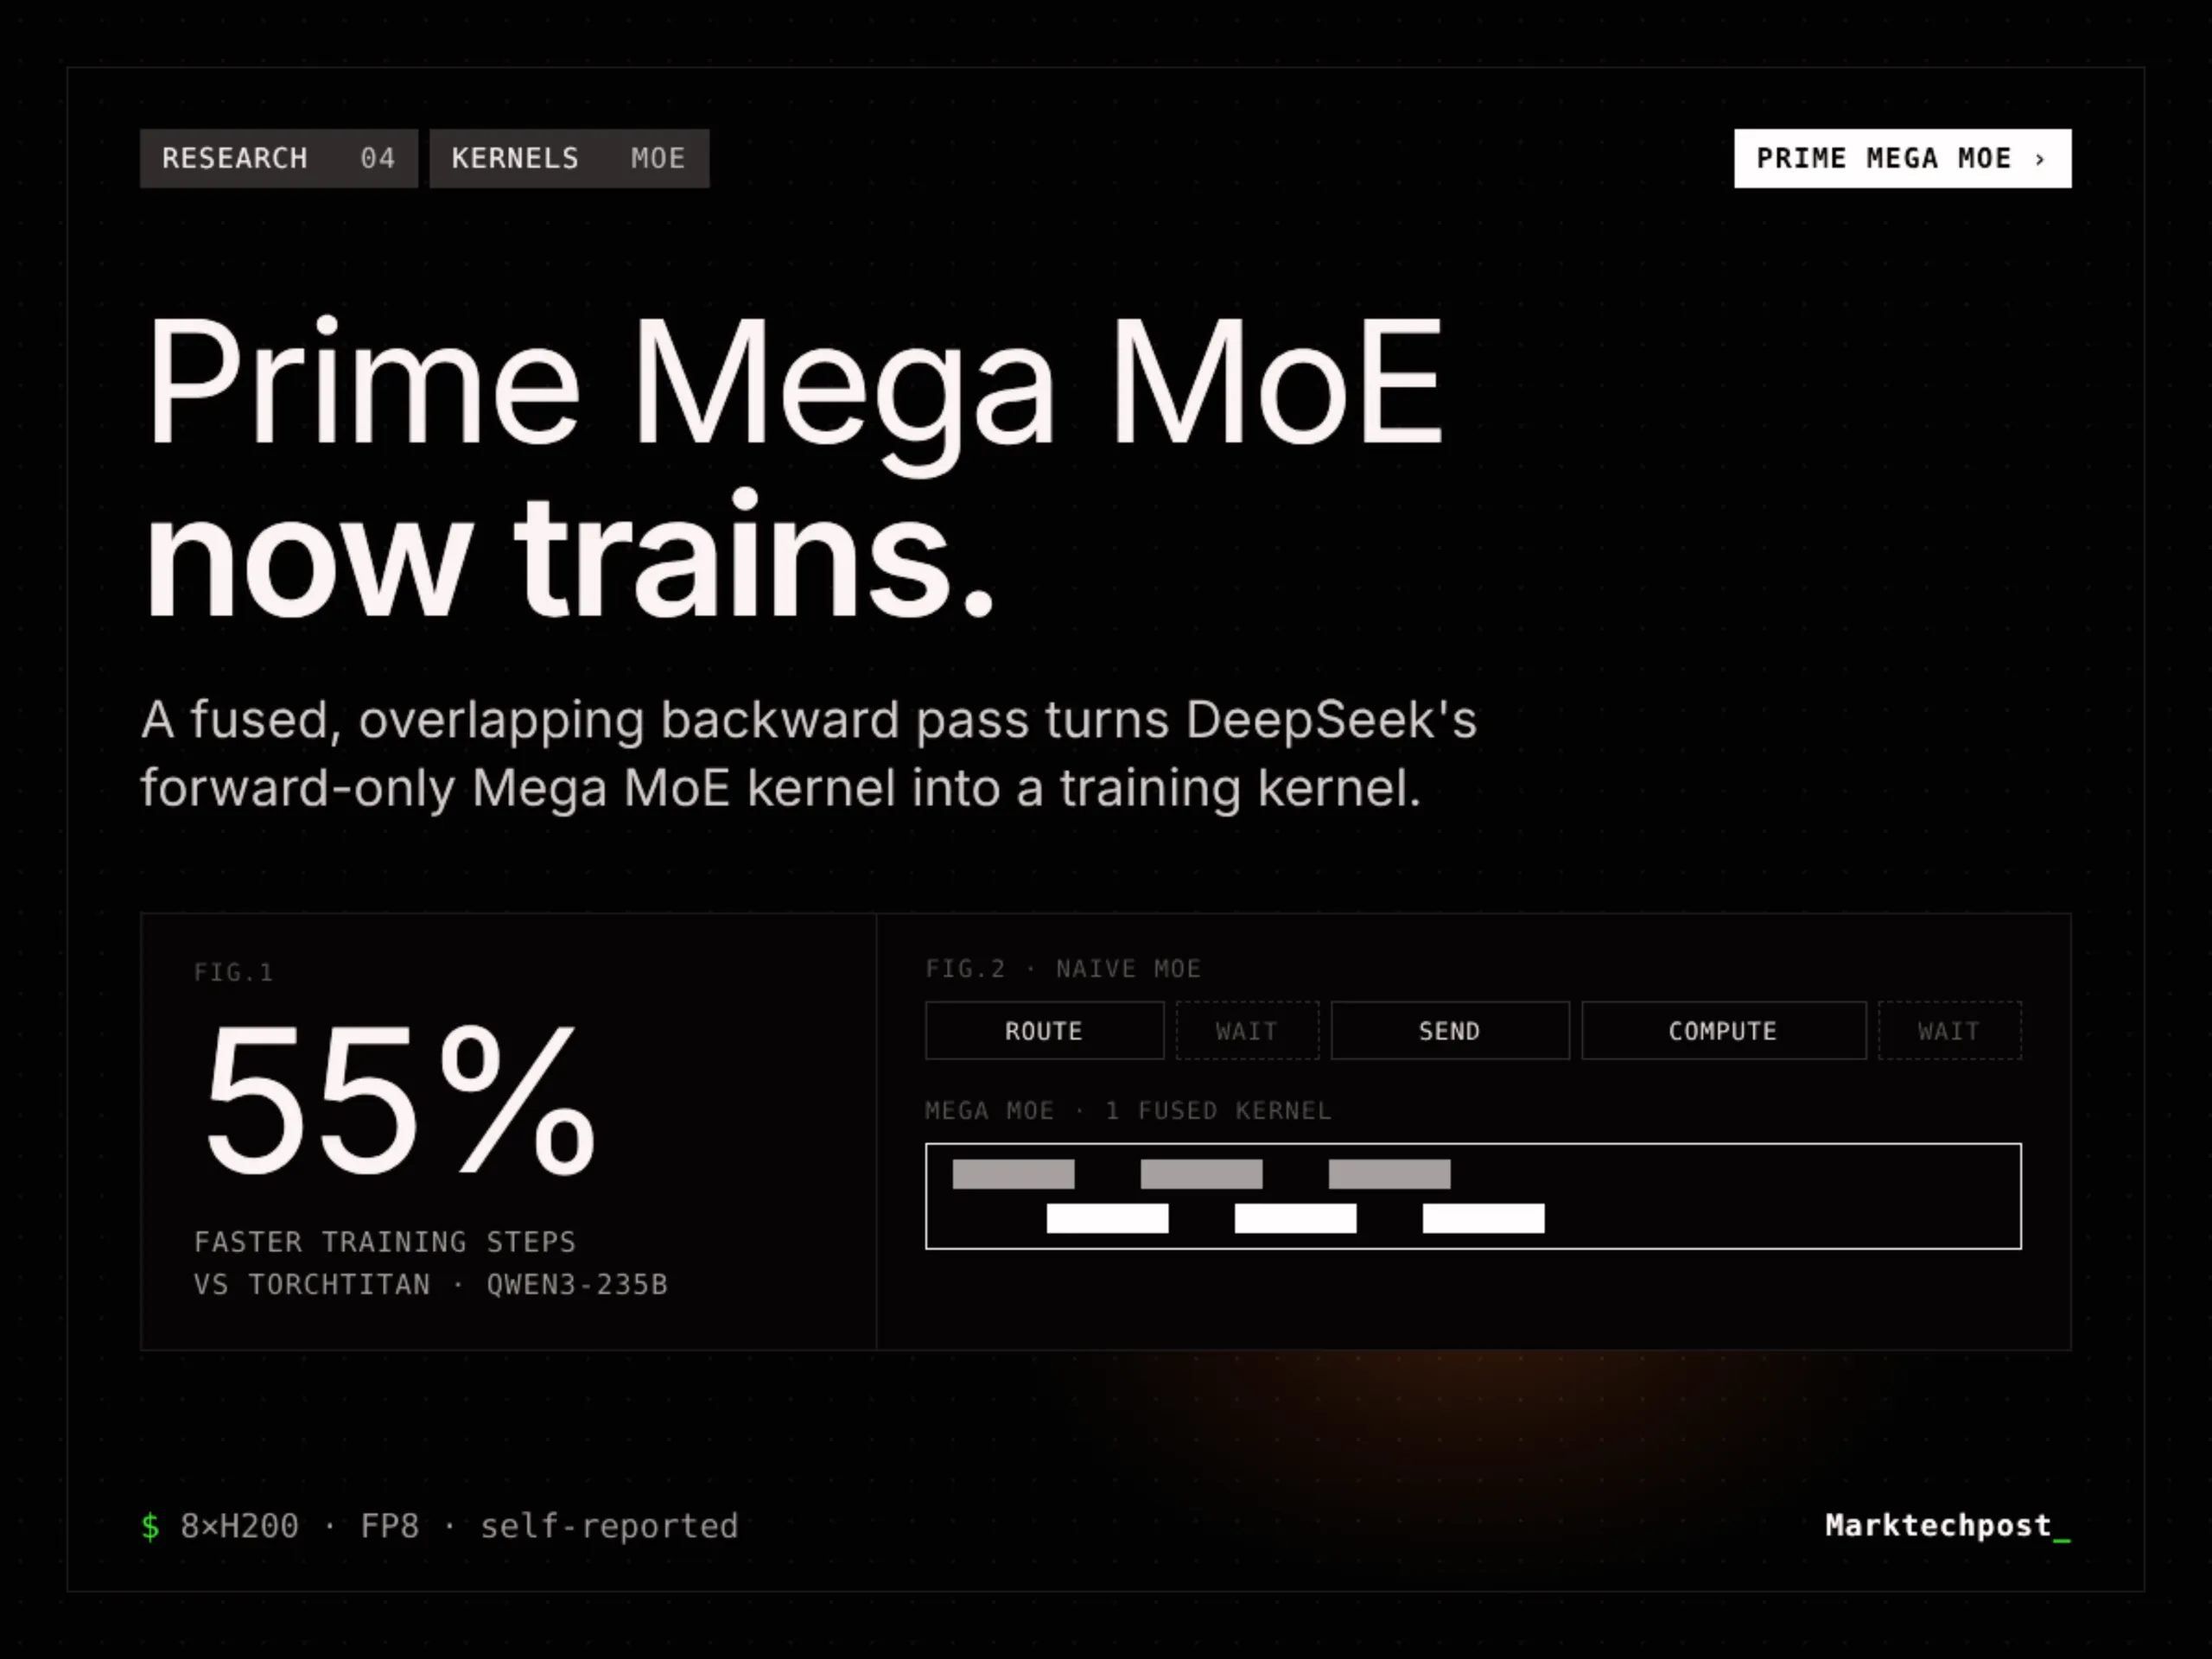
Prime Intellect releases faster training kernel for AI models
MarkTechPost: Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass
Prime Intellect has released Prime Mega MoE, a training extension of DeepSeek’s fused Mega MoE kernel. DeepSeek’s kernel only ran the forward pass. Prime Intellect added a fast, overlapping backward pass. That makes the fused kernel usable for training, not just inference. In its prime-rl trainer, full training steps on Qwen3 MoE models run up to 34% faster. Against TorchTitan, the gain reaches 55%. For teams training mixture-of-experts (MoE) models, that is a direct cut in GPU hour
Get smart on it
Prime Mega MoE is a GPU kernel that speeds up the training of mixture-of-experts models by fusing compute and communication operations into a single step. In mixture-of-experts architectures, different tokens are routed to different experts located on separate GPUs, creating idle waiting time as data moves between processors. The new kernel overlaps these communication steps with computation to reduce this idle time, achieving 32 to 34 percent faster full training steps compared to baseline implementations and up to 55 percent faster steps compared to an alternative approach. The forward pass sees the largest speedup at up to 3.11 times faster, while backward pass gains are more modest at up to 1.87 times faster.
Explainer: What Is a Mixture of Experts Model and Why Does It Use Fewer Resources?
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Gemini 4 Carbon: Our next frontier model
Google's latest offering suggests the company is prioritizing efficiency and environmental impact alongside raw capability gains.
Also reported by Ars Technica, MarkTechPost, The Verge and The Decoder

Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral's latest offering aims to compete with frontier models while remaining accessible to researchers and developers on open platforms.
Also reported by SiliconANGLE and TechCrunch
Introducing GPT-6.1 Terra
Bringing fast and capable computer use to everyone
Also reported by SiliconANGLE, MarkTechPost and The Decoder
Le Chonk: Built for Coders, Trusted by Defenders.
The weights of Mistral Large 4 (Le Chonk) are now open. A 1T parameter multimodal model, and best open-weight model for coding, trained in Europe.

Genie 4: A new generation of world simulation
Genie 4: our new world model unlocking unprecedented realism in real-time simulation.
Also reported by TechCrunch, Ars Technica, SiliconANGLE and MarkTechPost

An updated Model Spec for more capable and beneficial AI
OpenAI’s updated Model Spec outlines five core values to guide more capable AI toward sound judgment, human agency, and faithfulness to human intent.