Meet qwenGPU: Qwen3.5-2B With 45 Compiled GPU Layers That Run CUDA
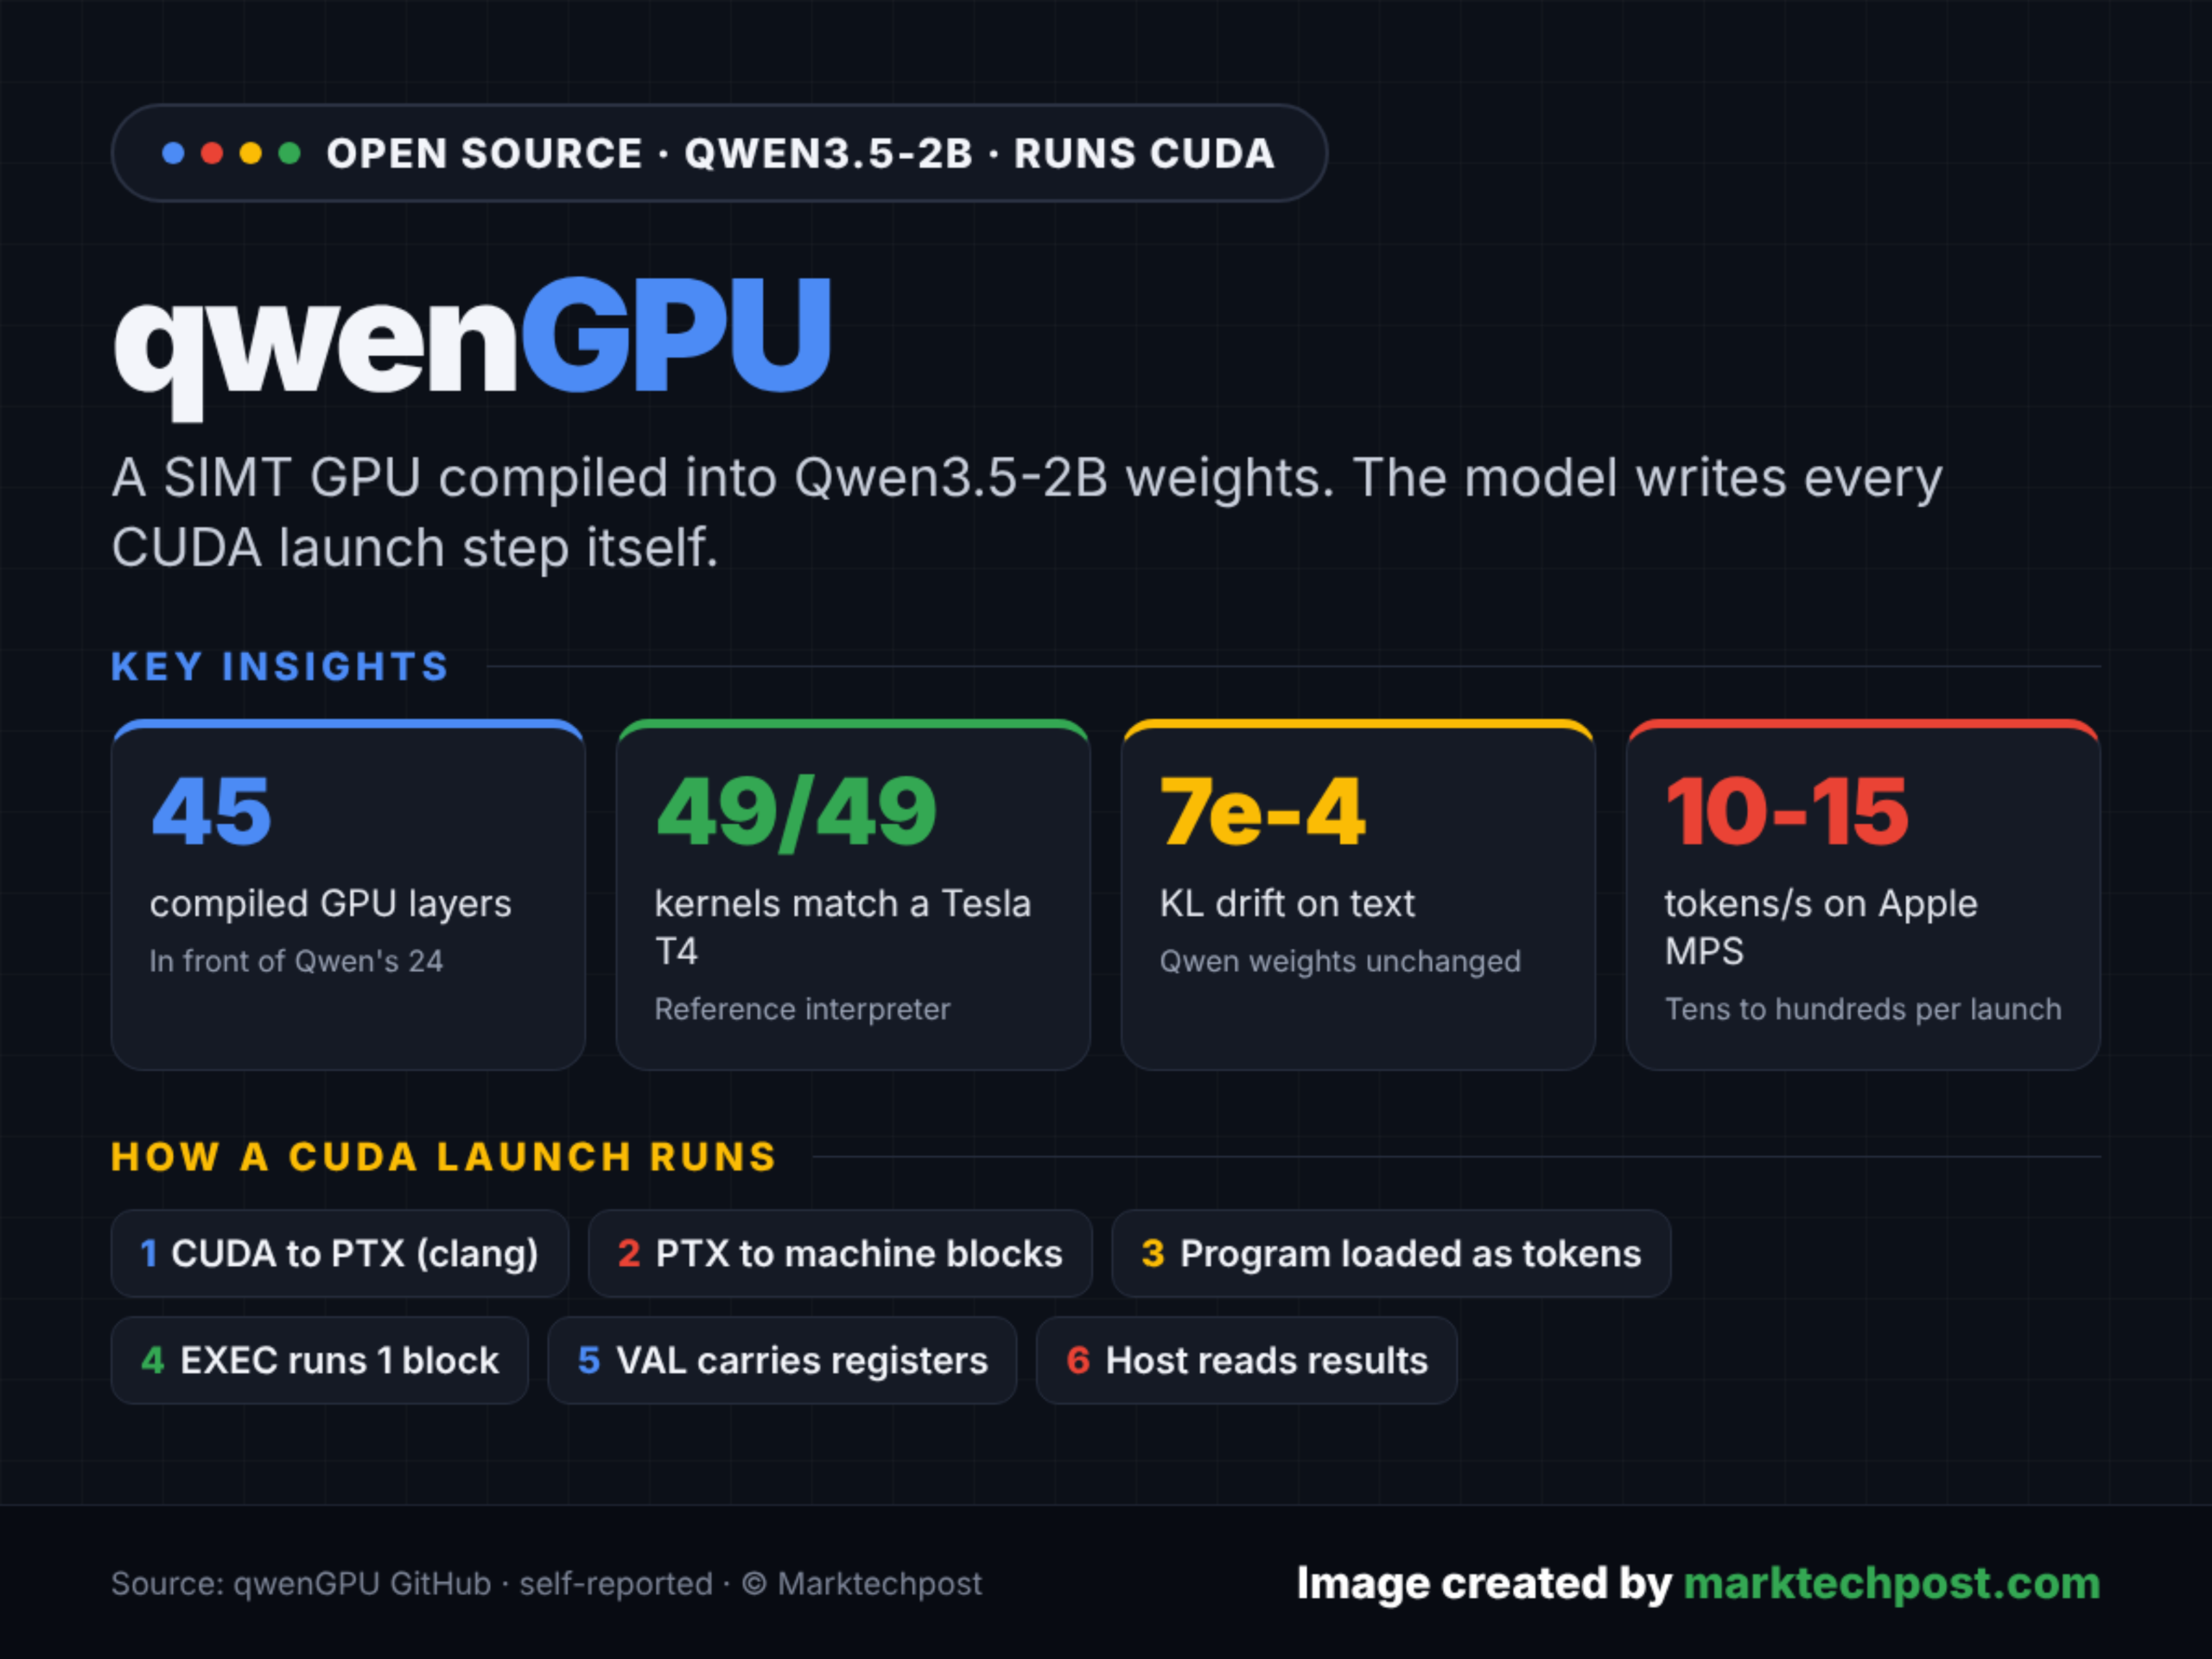
qwenGPU is an experimental model that compiles a SIMT GPU directly into the weights of Qwen3.5-2B. Developer Vixhal (@TheVixhal) released it on GitHub under the MIT license. The model runs real CUDA, compiled to NVIDIA PTX, inside its own forward passes. For developers, it tests one idea: exact computation inside a pretrained LLM, not beside it. TL;DR Size: Qwen3.5-2B (24 layers) along with 45 compiled GPU layers, 69 in total. Context: 262,144 tokens (base model). Runs on: Apple sili
Get smart on it
qwenGPU is an experimental model that embeds a functioning GPU directly into the weights of a language model by compiling 45 additional transformer layers in front of the base model's 24 layers. The GPU operates as a 4-lane SIMT machine that executes real CUDA code during the model's forward passes, with the host computer compiling CUDA to machine code and the model itself writing out each execution step. This demonstrates a concept where exact computation runs inside a pretrained language model rather than beside it, using the model's own layer types to store registers, memory, and program instructions. While all test launches produced exact results and the reference interpreter matched a real GPU on all 49 test kernels, the system runs at only 10 to 15 tokens per second, positioning it as a research demonstration rather than a practical runtime.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Gemini 4 Carbon: Our next frontier model
Google's latest offering suggests the company is prioritizing efficiency and environmental impact alongside raw capability gains.
Also reported by Ars Technica, MarkTechPost, The Verge and The Decoder

Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral's latest offering aims to compete with frontier models while remaining accessible to researchers and developers on open platforms.
Also reported by SiliconANGLE and TechCrunch

Google introduces cutting-edge Genie 4 world model
Google LLC today previewed Genie 4, an artificial intelligence model that can generate realistic three-dimensional environments. The algorithm is the latest addition to a series of world models that the company launched in 2024. Compared with its predecessor, Genie 4 is better at rendering fluid movements and other complex details. Furthermore, it can generate accompanying […] The post Google introduces cutting-edge Genie 4 world model appeared first on SiliconANGLE.
Also reported by MarkTechPost and The Decoder
Le Chonk: Built for Coders, Trusted by Defenders.
The weights of Mistral Large 4 (Le Chonk) are now open. A 1T parameter multimodal model, and best open-weight model for coding, trained in Europe.
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Customizable transcription tools could help organizations reduce manual annotation costs while handling multiple languages simultaneously.
Also reported by TechCrunch, SiliconANGLE, The Decoder and MarkTechPost
OpenAI sets new behavioral guidelines for AI models that have already proven hard to control
OpenAI has updated its Model Spec, restructuring its AI behavior guidelines around five core values, including faithfulness to human intent and correctability. GPT models should now draw on conversation history to figure out what users actually want and disclose their own assumptions. Whether the models follow these rules is another matter. The article OpenAI sets new behavioral guidelines for AI models that have already proven hard to control appeared first on The Decoder.