Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design
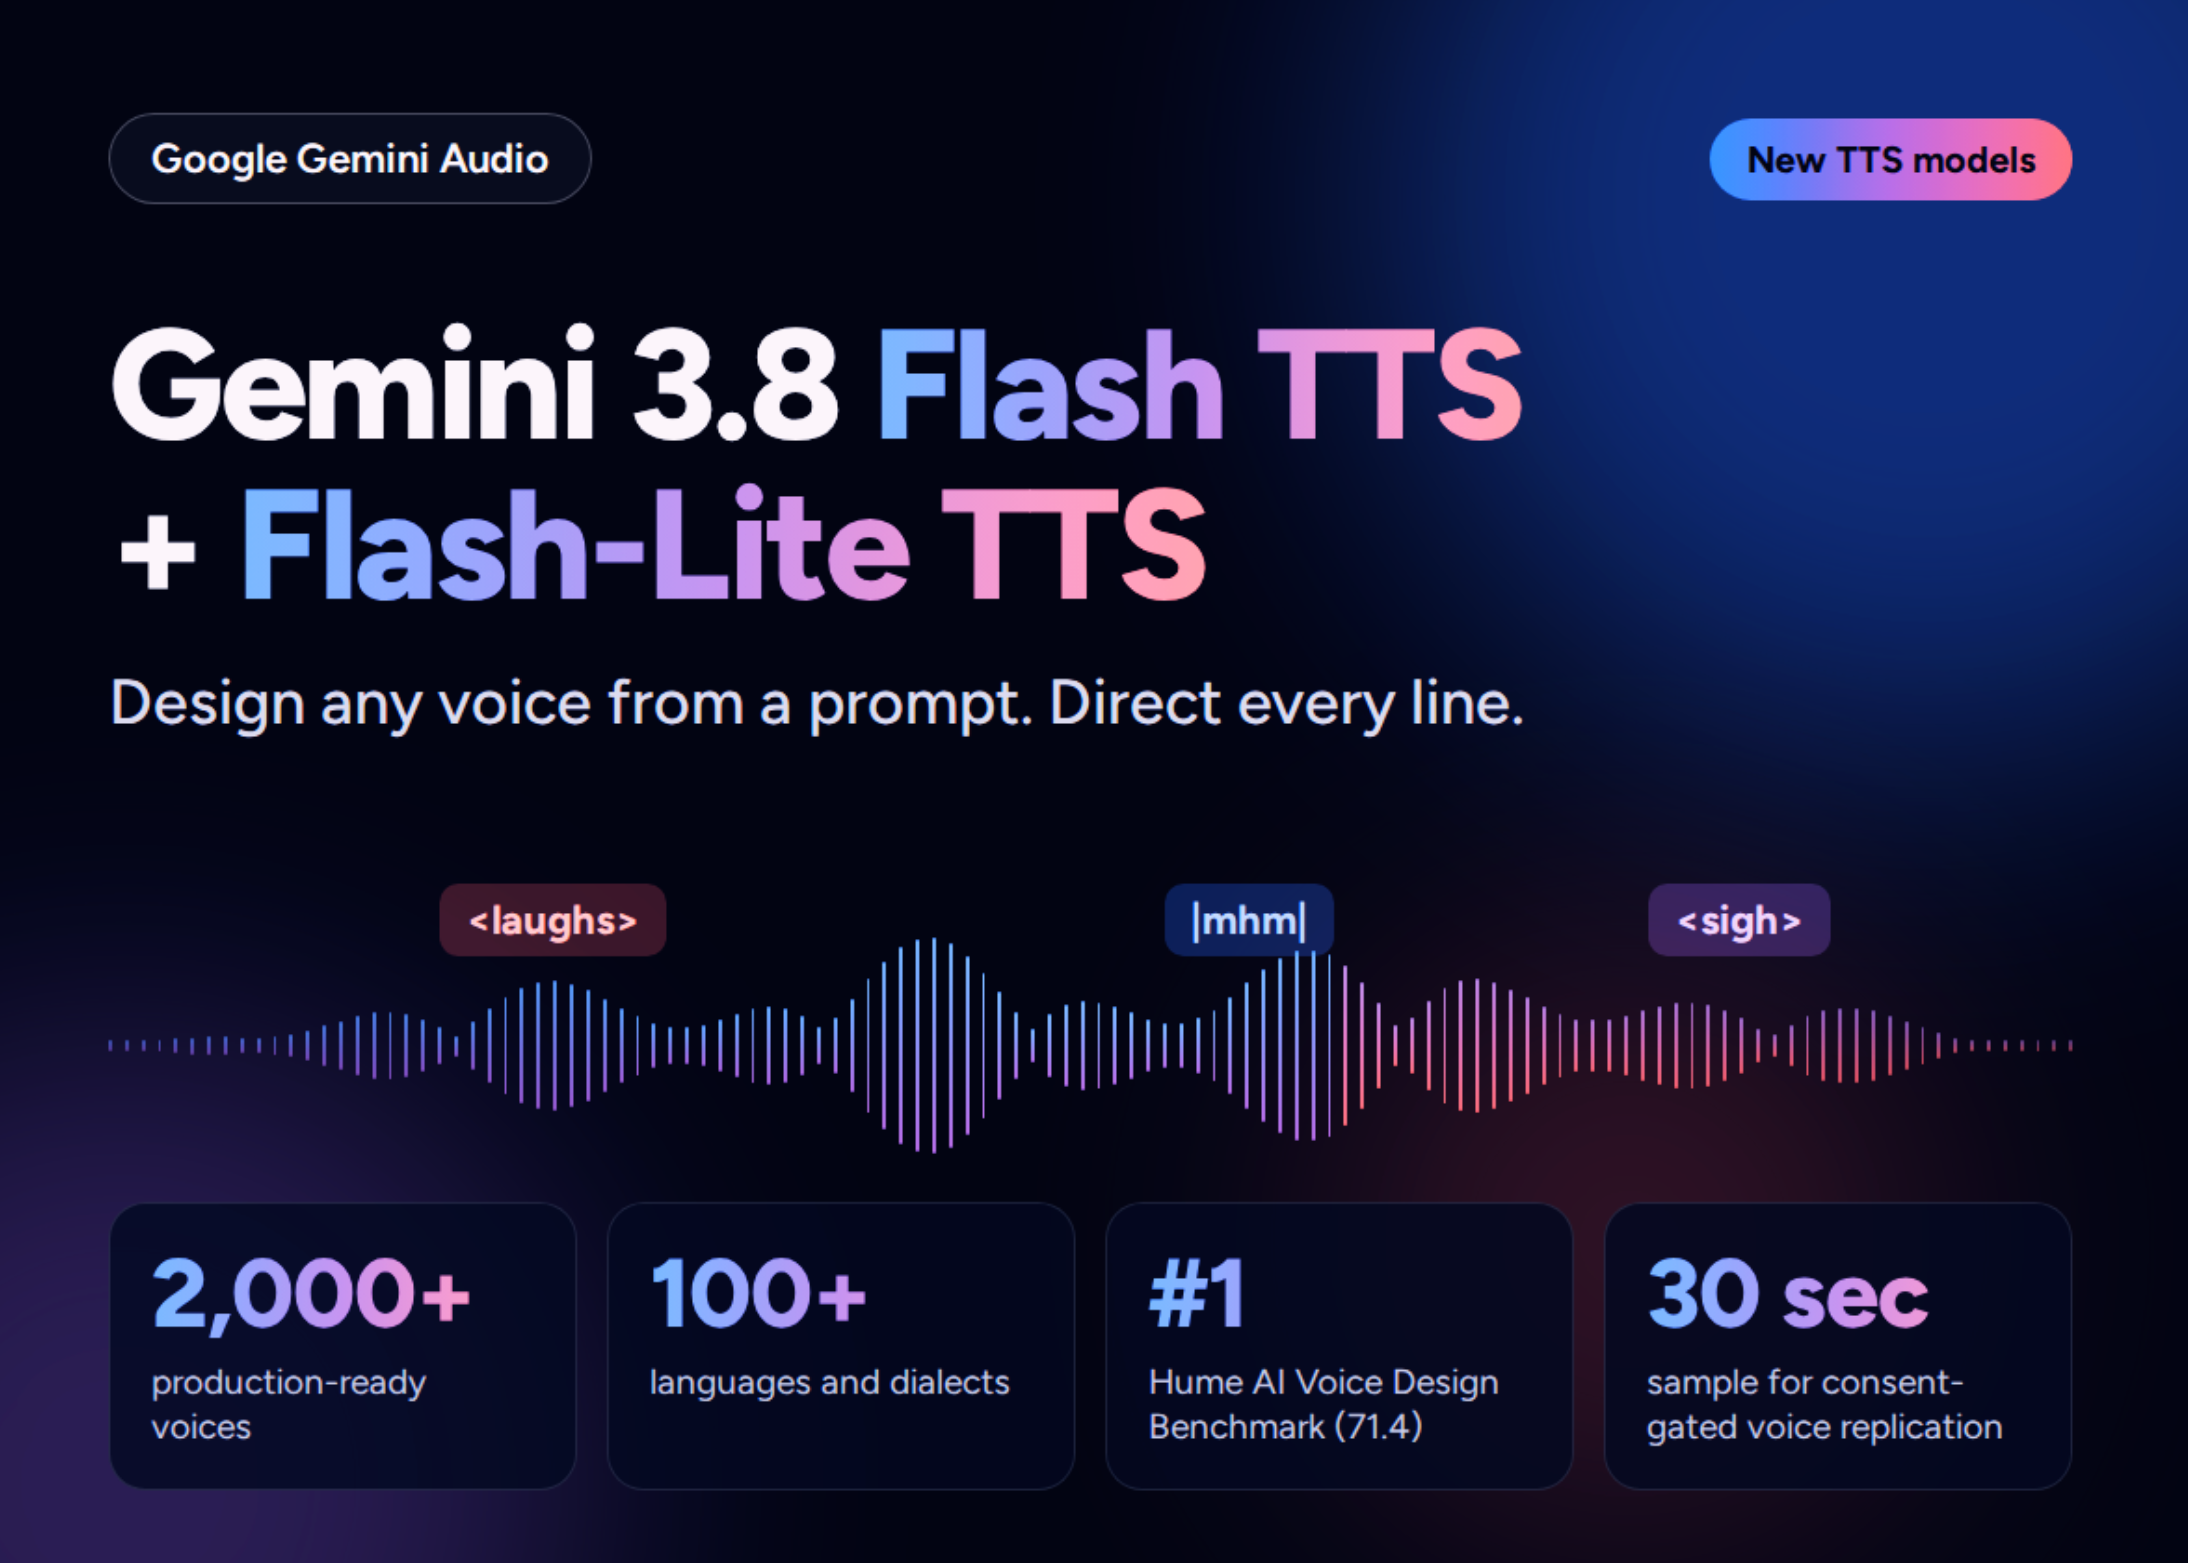
Google has released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, 2 new text-to-speech models in its Gemini Audio family. Google calls them its most expressive audio generation models yet. Flash TTS targets creative direction and character voices. Flash-Lite TTS targets high-volume, cost-efficient production. Both let developers direct delivery line by line using natural language. Is it deployable? Yes, both models are rolling out now through the Gemini API and Google AI Studio. Access
Get smart on it
Google has released two new text-to-speech models that convert written text into spoken audio with expressive delivery. The models differ in their purposes: one targets creative applications like gaming and audiobooks with detailed performance controls, while the other prioritizes cost-efficient high-volume production. These models introduce a shift from a fixed set of 30 original voices to a system that can generate new voices from text descriptions across over 100 languages and dialects, or select from more than 2,000 production-ready voices. The models include safety features such as watermarks embedded in audio output and require consent recordings when replicating a specific person's voice.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Google Releases Gemini Omni 1.2 Flash: 15-Second AI Video at $0.07 per Second
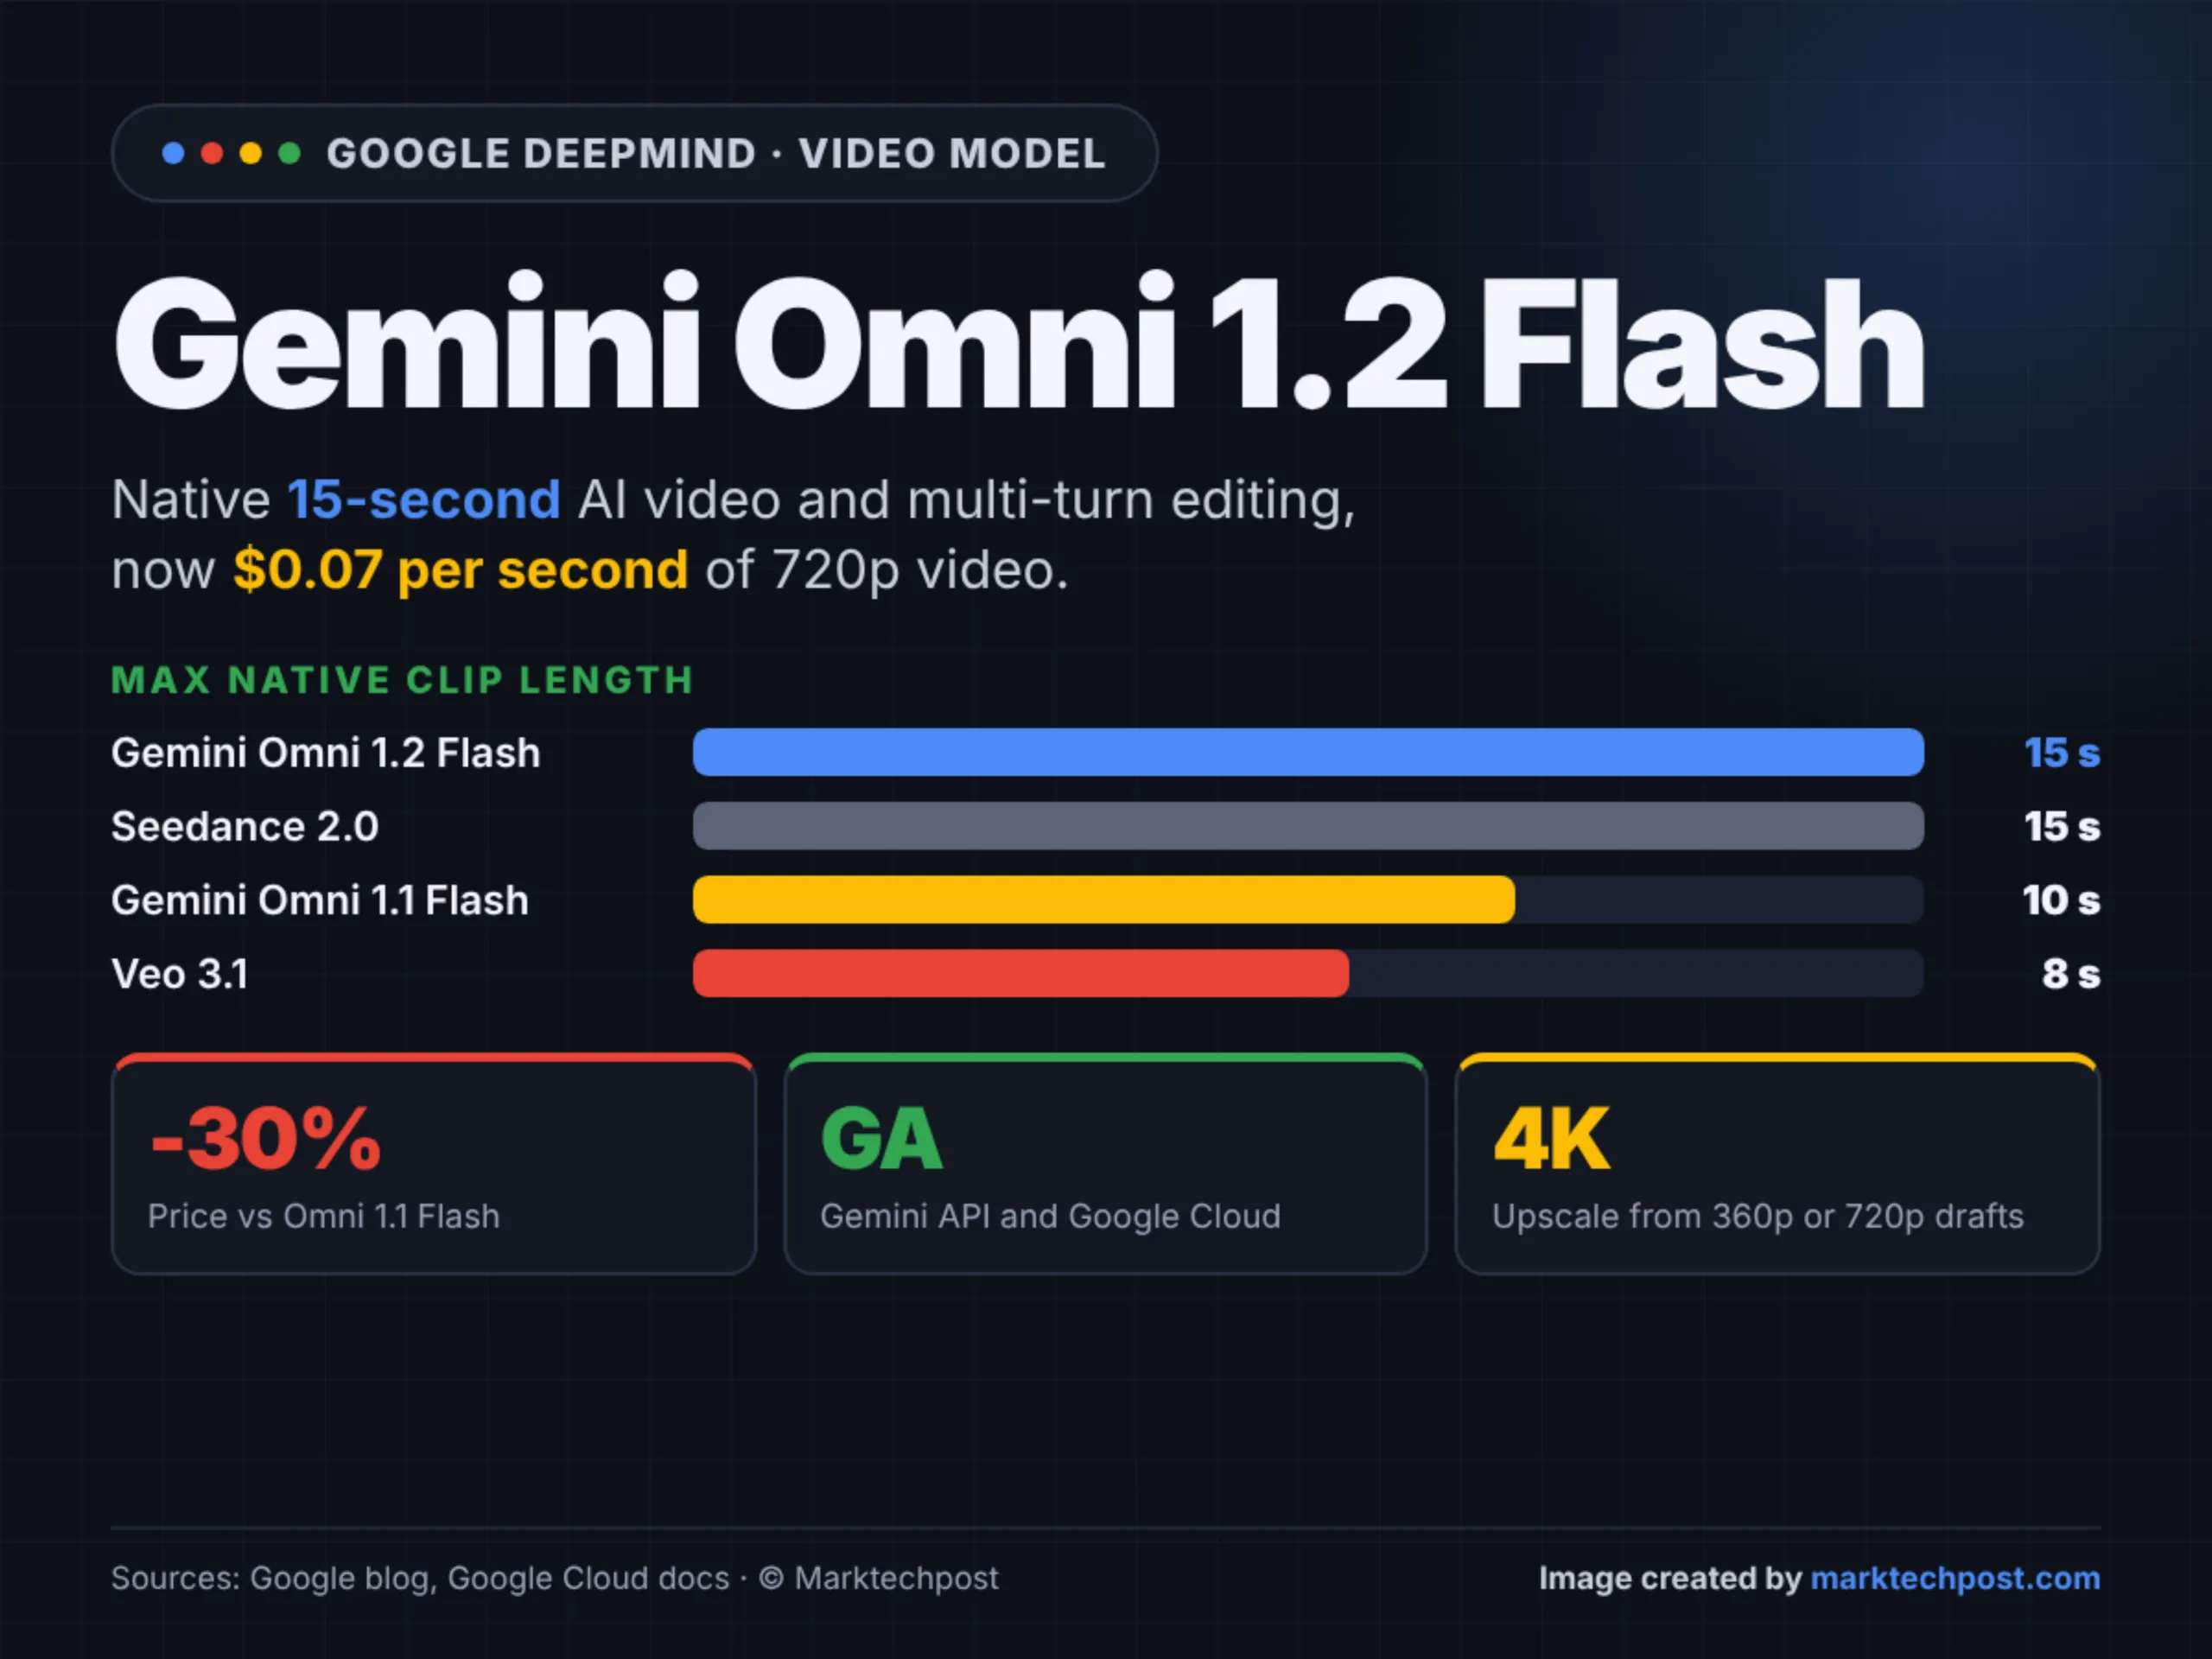
Google has released Gemini Omni 1.2 Flash, the newest version of its video generation and editing model. Gemini Omni 1.2 Flash generates and edits clips up to 15 seconds natively. It also cuts the price by 30% compared with Omni 1.1 Flash. The model is generally available on Google Cloud and the Gemini API. For developers, the takeaways are longer clips, fewer re-renders and a lower bill per second. TL;DR Runs on: Google-hosted only (Gemini API, Google Cloud). No open weights, no local d
Also reported by Google DeepMind

GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents
Introducing GPT‑6 Cyber, OpenAI’s cybersecurity model for finding exploitable vulnerabilities and developing fixes, trained to stay within authorized scope.

Tencent releases Hy4, powerful frontier LLM introducing visual understanding and computer use
Tencent Holdings Ltd. today introduced Hy4, a new large language model that adds computer-use capabilities for the first time, using advanced visual understanding, reasoning and tool-calling to deliver long-horizon agentic performance. The company said the model marks a significant leap in performance over its Hy4 Preview, which arrived August 28, weighing in at 770 billion parameters with 49 […] The post Tencent releases Hy4, powerful frontier LLM introducing visual understanding and comp

OpenAI says its new cybersecurity model is better at not hacking other companies
OpenAI is launching GPT-6 Cyber, the latest version of its cybersecurity AI model, which it says is better at finding vulnerabilities and less likely to go rogue and hack other platforms in the process. OpenAI says that during testing, GPT-6 Cyber went out of bounds less than 1 percent of the time, down from around 5 percent with GPT-5.6 Cyber. The evaluation, called ExploitGym HoneyPot, is modeled after the Hugging Face Incident, in which OpenAI's AI agents breached the open-s
Also reported by TechCrunch

Baidu Releases ERNIE 5.5 Flash Base: A 280B MoE Base Model With 14B Active Parameters
Baidu has released ERNIE 5.5 Flash Base, the raw pre-training checkpoint of its new sparse Mixture-of-Experts language model. ERNIE 5.5 Flash Base is a 280B-parameter text model from Baidu that activates 14B parameters per token. The weights stop at the end of pre-training, with no mid- or post-training applied. This as a clean starting point for teams that want to compare fine-tuning, instruction tuning or RL methods from one checkpoint. TL;DR Size: 280B total, 14B active per token; 128
New NVIDIA Cosmos 3 Open Models for Interactive World Simulation
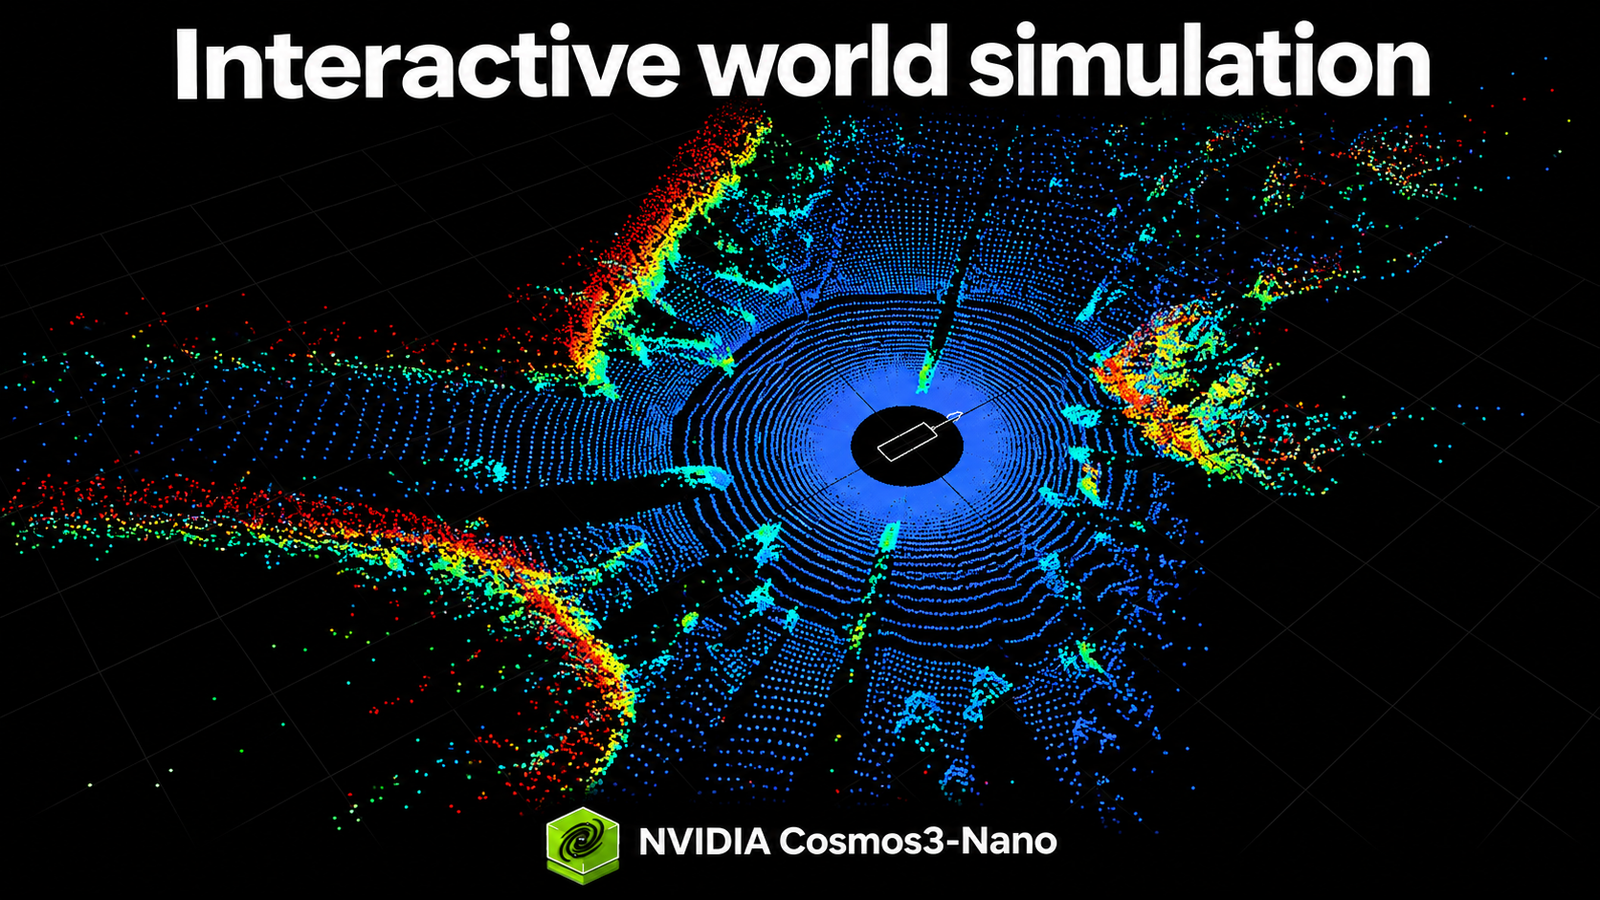
Open-source simulation models could democratize AI development for robotics and autonomous systems across research and industry.