Gemini 3.8 text-to-speech says hello
The capability lets AI systems communicate with users through spoken words, expanding accessibility beyond text-based interfaces.
Get smart on it
Google DeepMind has introduced two new text-to-speech models that allow creators and developers to generate expressive synthetic voices with detailed control over character design, delivery, and performance. The models enable users to create custom voices from natural language descriptions, replicate voices from audio samples, and direct line-by-line vocal delivery across applications like podcasts, audiobooks, and interactive media. These tools include safeguards such as consent verification for voice replication and watermarking to detect AI-generated speech. The models are available through Google AI Studio, the Gemini API, and other Google products, supporting over 100 languages and regional dialects.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

42AI comes out of stealth with $62.5M and a world model that can ‘predict human behavior’
Here's a question straight out of sci-fi: What if AI could predict what you were going to do before you decided to, even in a completely new situation?
Also reported by SiliconANGLE

Mistral releases weights for its trillion-parameter AI model, targeting cybersecurity
Mistral says its new model can afford organizations a kind of control over its cyber defenses that closed models can't.
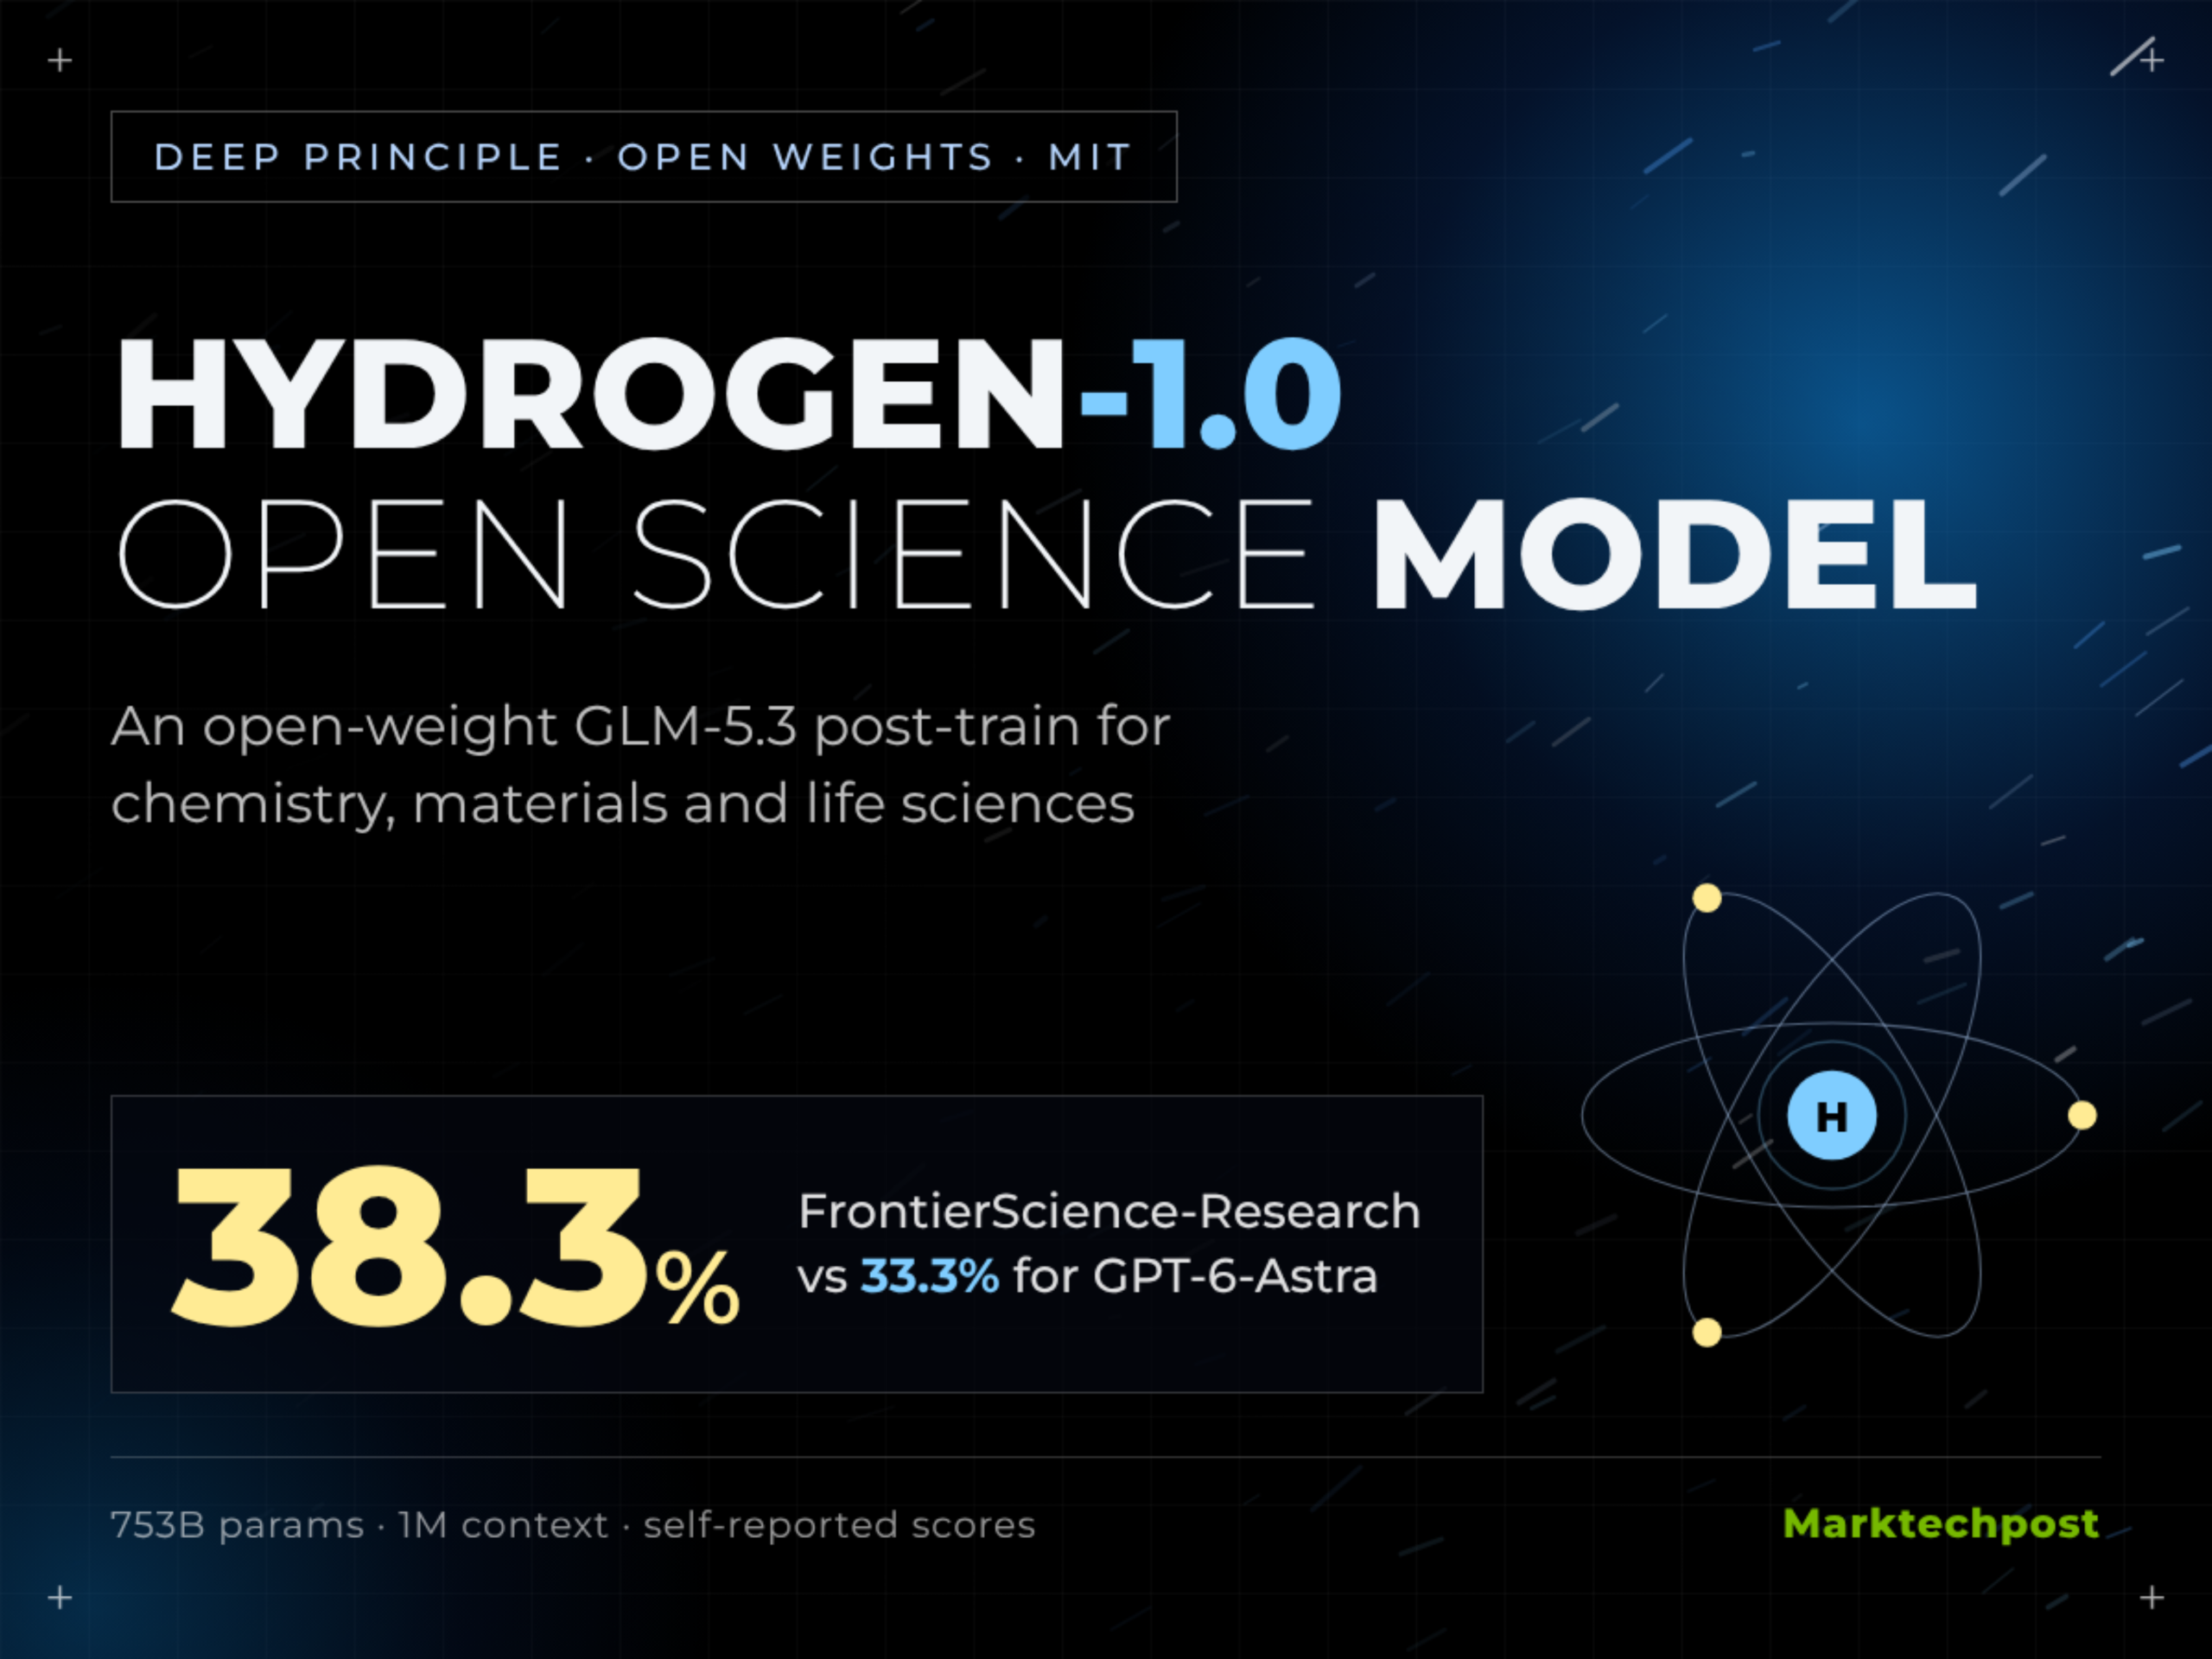
Deep Principle Releases Hydrogen-1.0: A 753B Open-Weight Model for Scientific Discovery
Deep Principle has released Hydrogen-1.0, an open-weight scientific model for chemistry, materials science and life sciences. It is built by post-training Z.ai’s GLM-5.3 on domain data, laboratory records and agent discovery trajectories. For developers, it offers open weights that report a FrontierScience-Research win over GPT-6-Astra. The weights ship under the MIT License. TL;DR Size: 753B parameters (MoE, ~40B active per the GLM-5.3 base), 1M-token context, 128K max output.
OpenAI sets new behavioral guidelines for AI models that have already proven hard to control
OpenAI has updated its Model Spec, restructuring its AI behavior guidelines around five core values, including faithfulness to human intent and correctability. GPT models should now draw on conversation history to figure out what users actually want and disclose their own assumptions. Whether the models follow these rules is another matter. The article OpenAI sets new behavioral guidelines for AI models that have already proven hard to control appeared first on The Decoder.
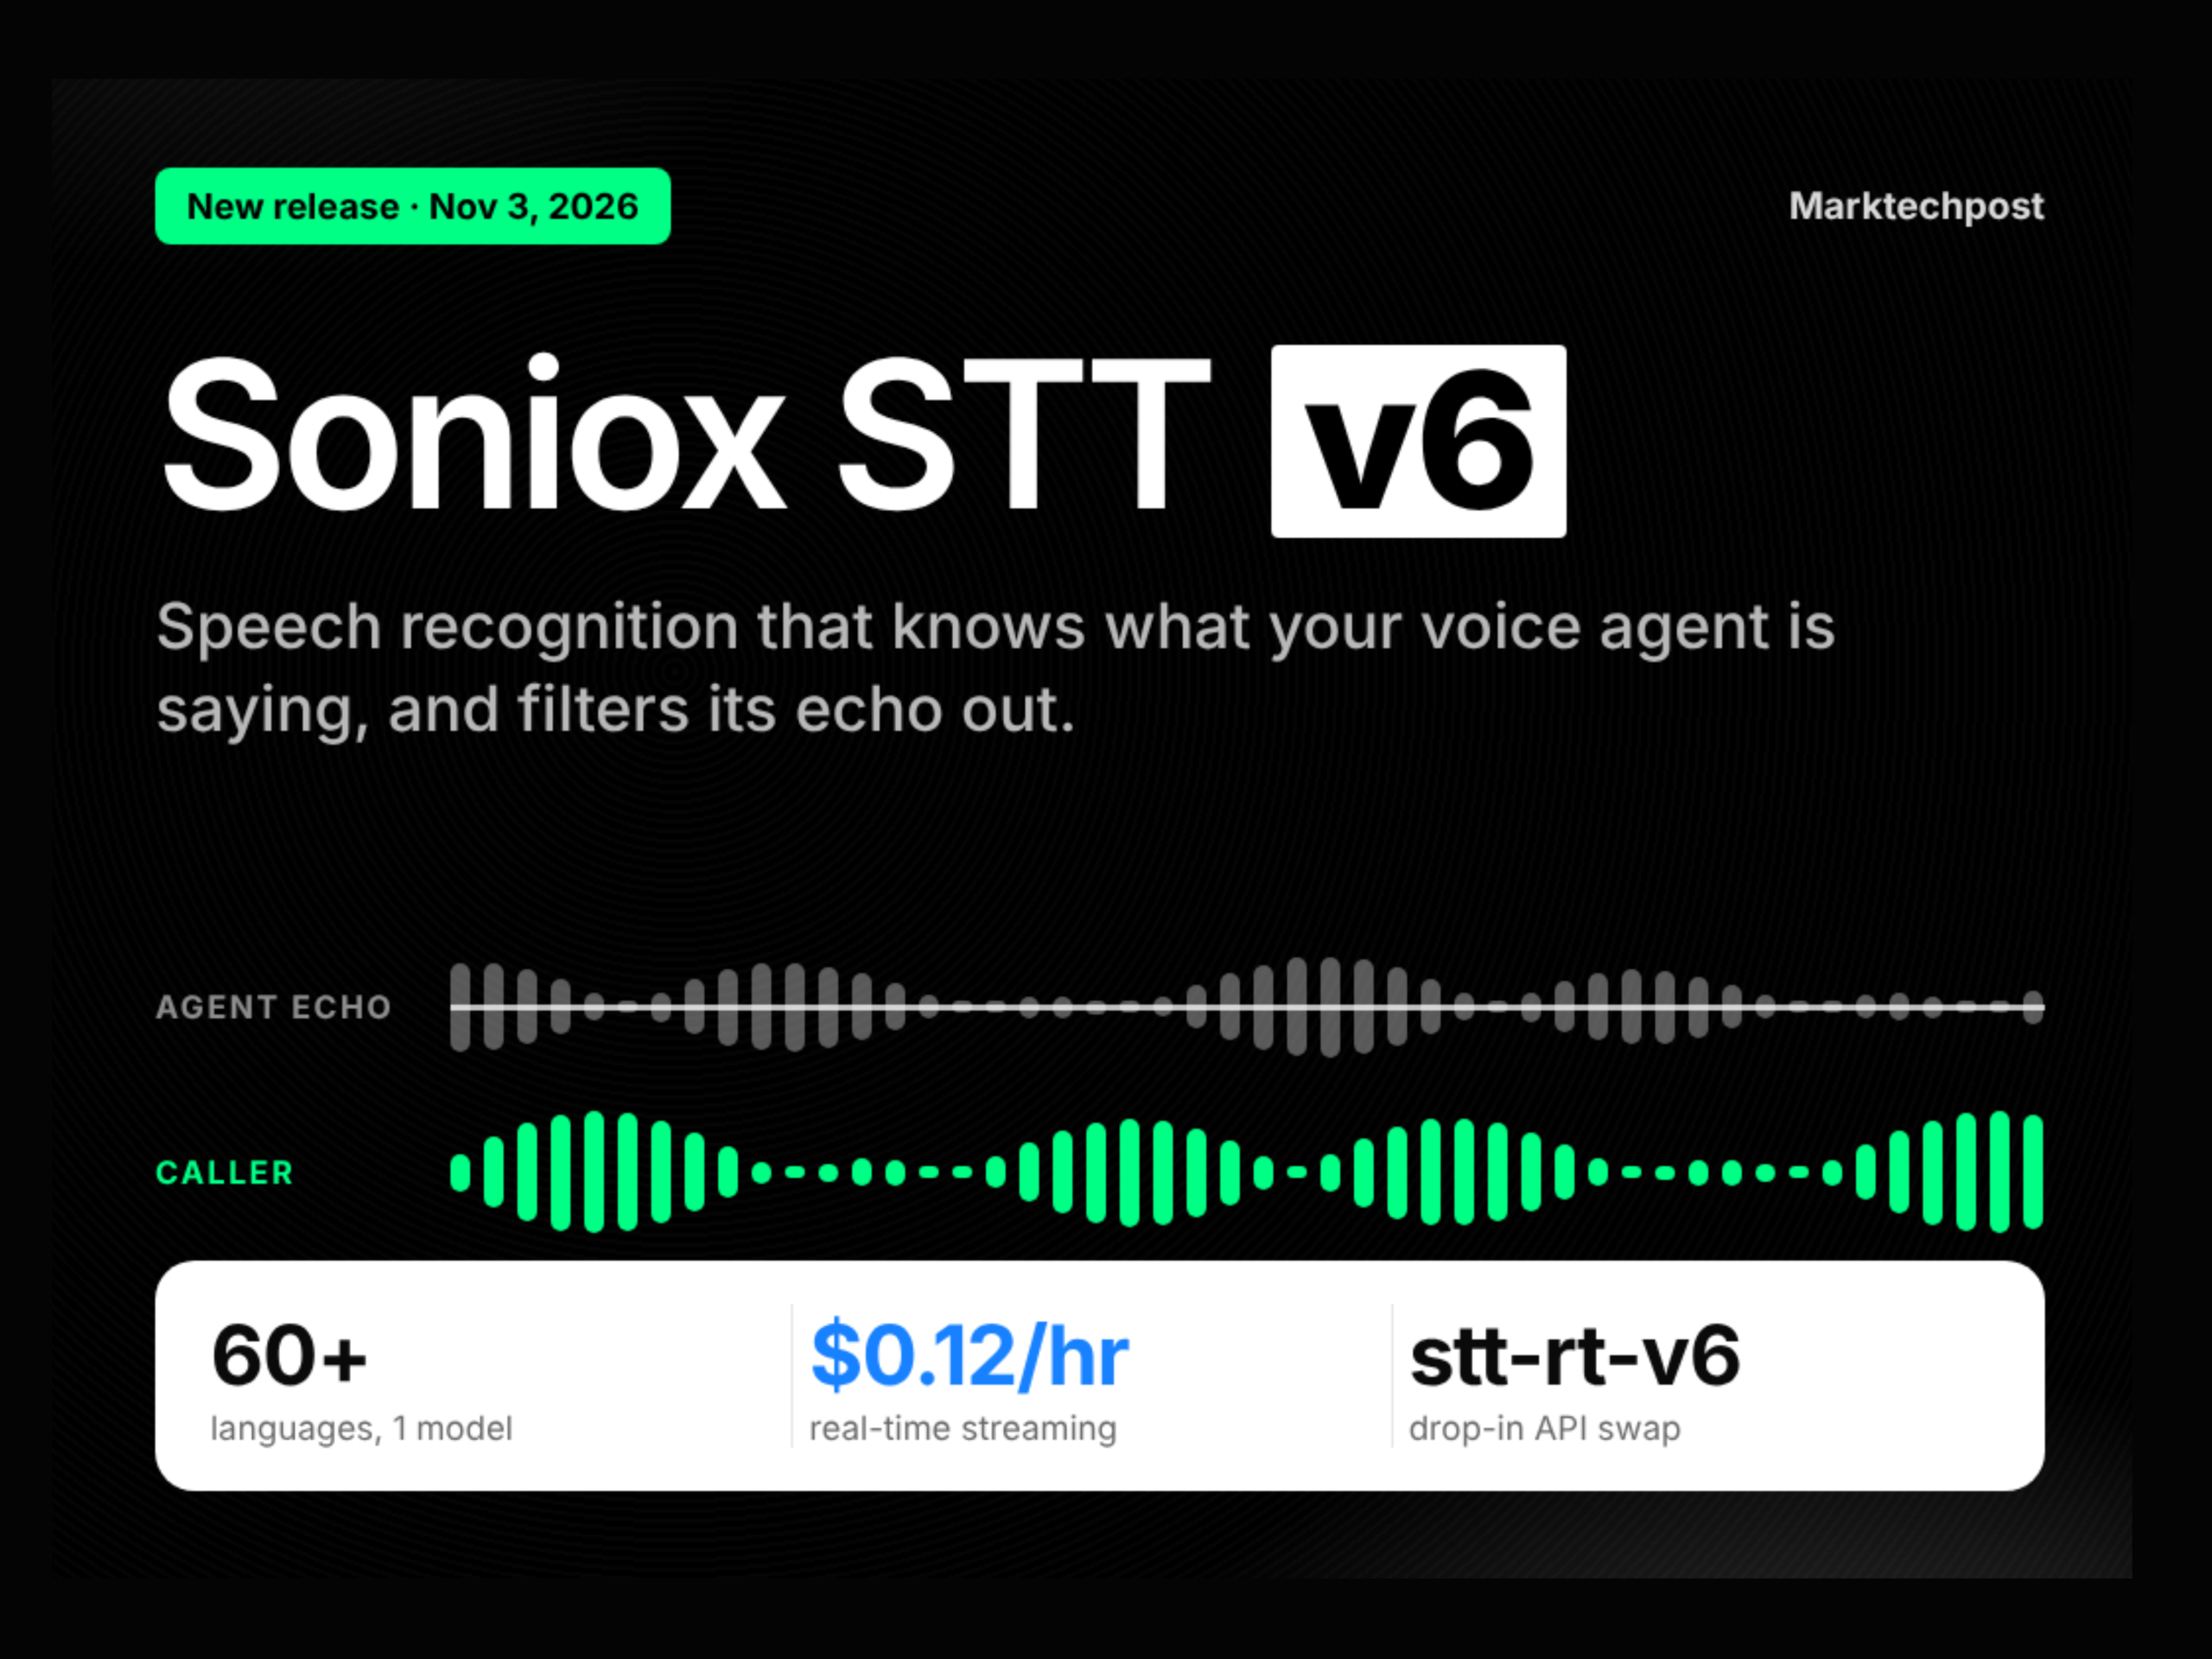
Soniox STT v6 Adds Agent Text Input and Echo Filtering for Voice Agents
Soniox has released Soniox STT v6, the latest generation of its speech-to-text API. Soniox STT v6 is a speech-to-text model that reads what a voice agent says while hearing the caller. It uses that text to recognize short replies and to drop the agent’s own voice. The release ships as stt-rt-v6 for streaming and stt-async-v6 for files, across 60+ languages. TL;DR Size: Soniox STT v6 is a proprietary hosted model, no parameter count published. Runs on: Soniox cloud API only (WebS

An updated Model Spec for more capable and beneficial AI
OpenAI’s updated Model Spec outlines five core values to guide more capable AI toward sound judgment, human agency, and faithfulness to human intent.