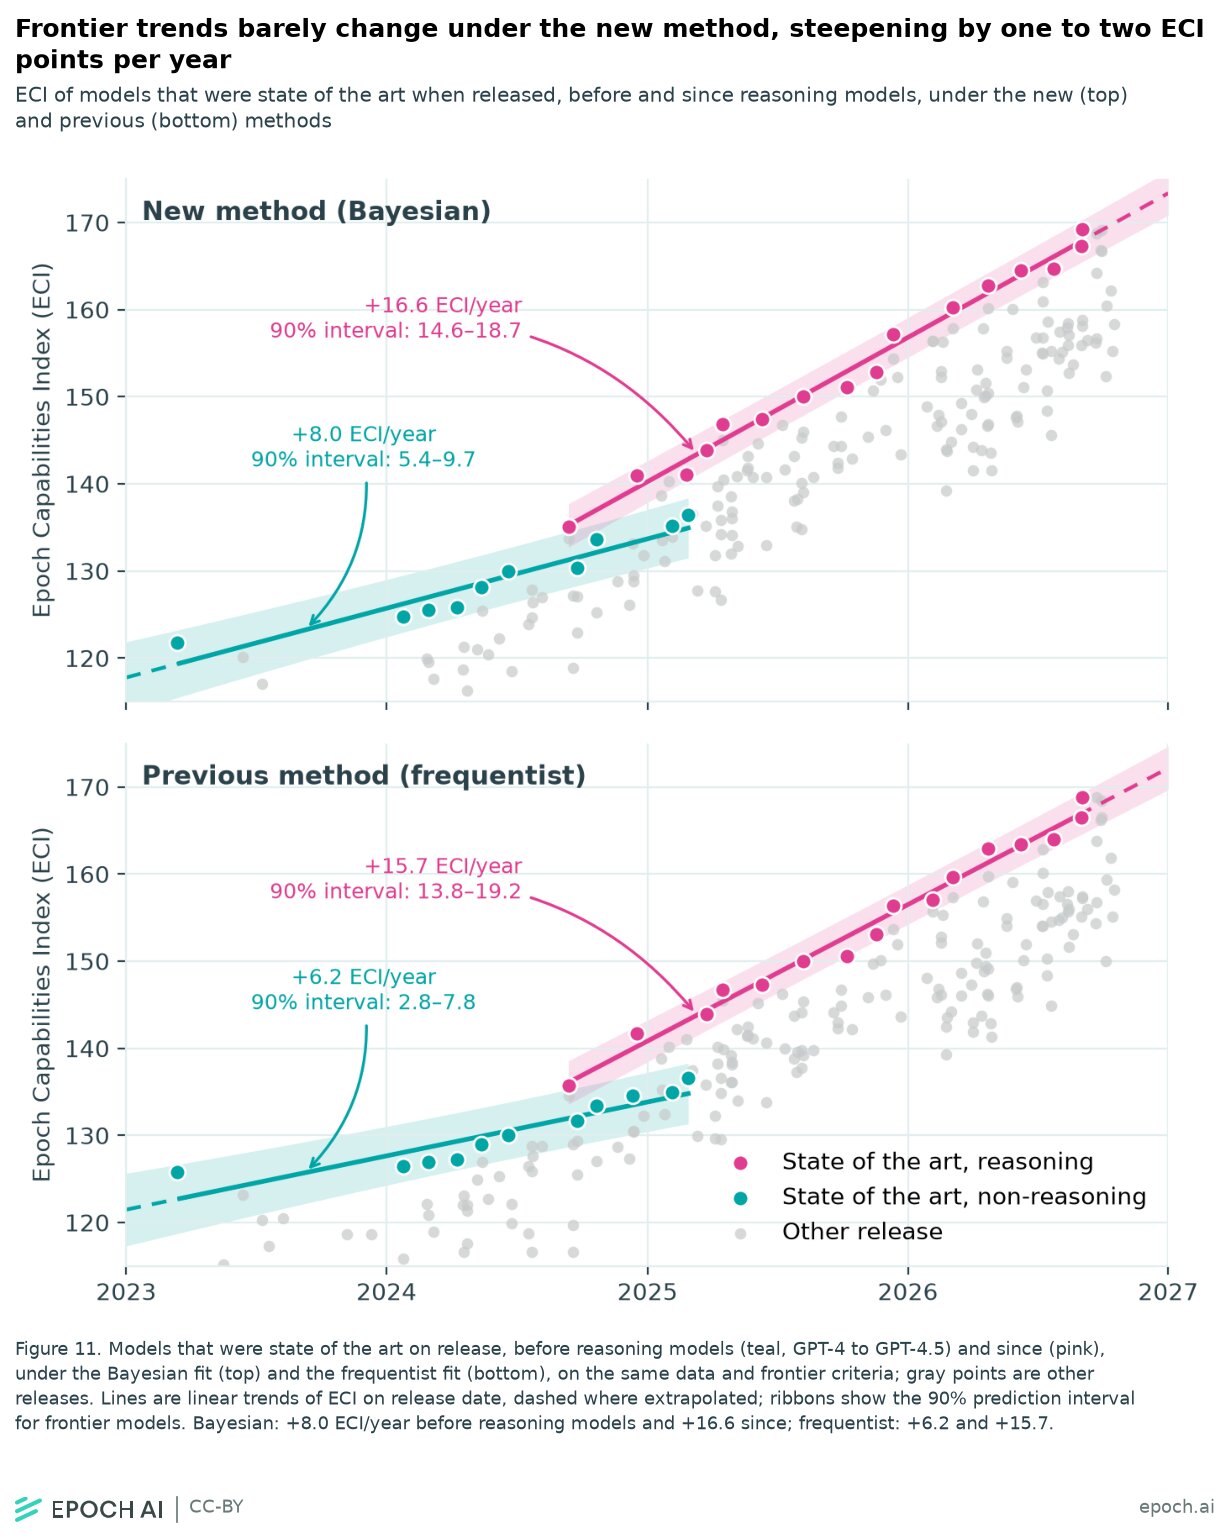
Epoch Capabilities Index switches to Bayesian model
Epoch AI: Updating the Epoch Capabilities Index methodology to use a Bayesian model
A Bayesian model gives the ECI better-justified uncertainty estimates and lets us compare models directly.
Get smart on it
The Epoch Capabilities Index is a system that measures AI model capability by converting benchmark test scores into comparable capability estimates using a statistical framework originally developed for educational testing. The organization behind it has switched from a frequentist statistical approach to a Bayesian approach to generate better-justified uncertainty estimates and enable direct comparisons of which models are likely more capable than others. The Bayesian model uses the same underlying logic as the previous method but provides improved estimates of uncertainty around capability measurements, while keeping capability scores for leading models largely unchanged.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
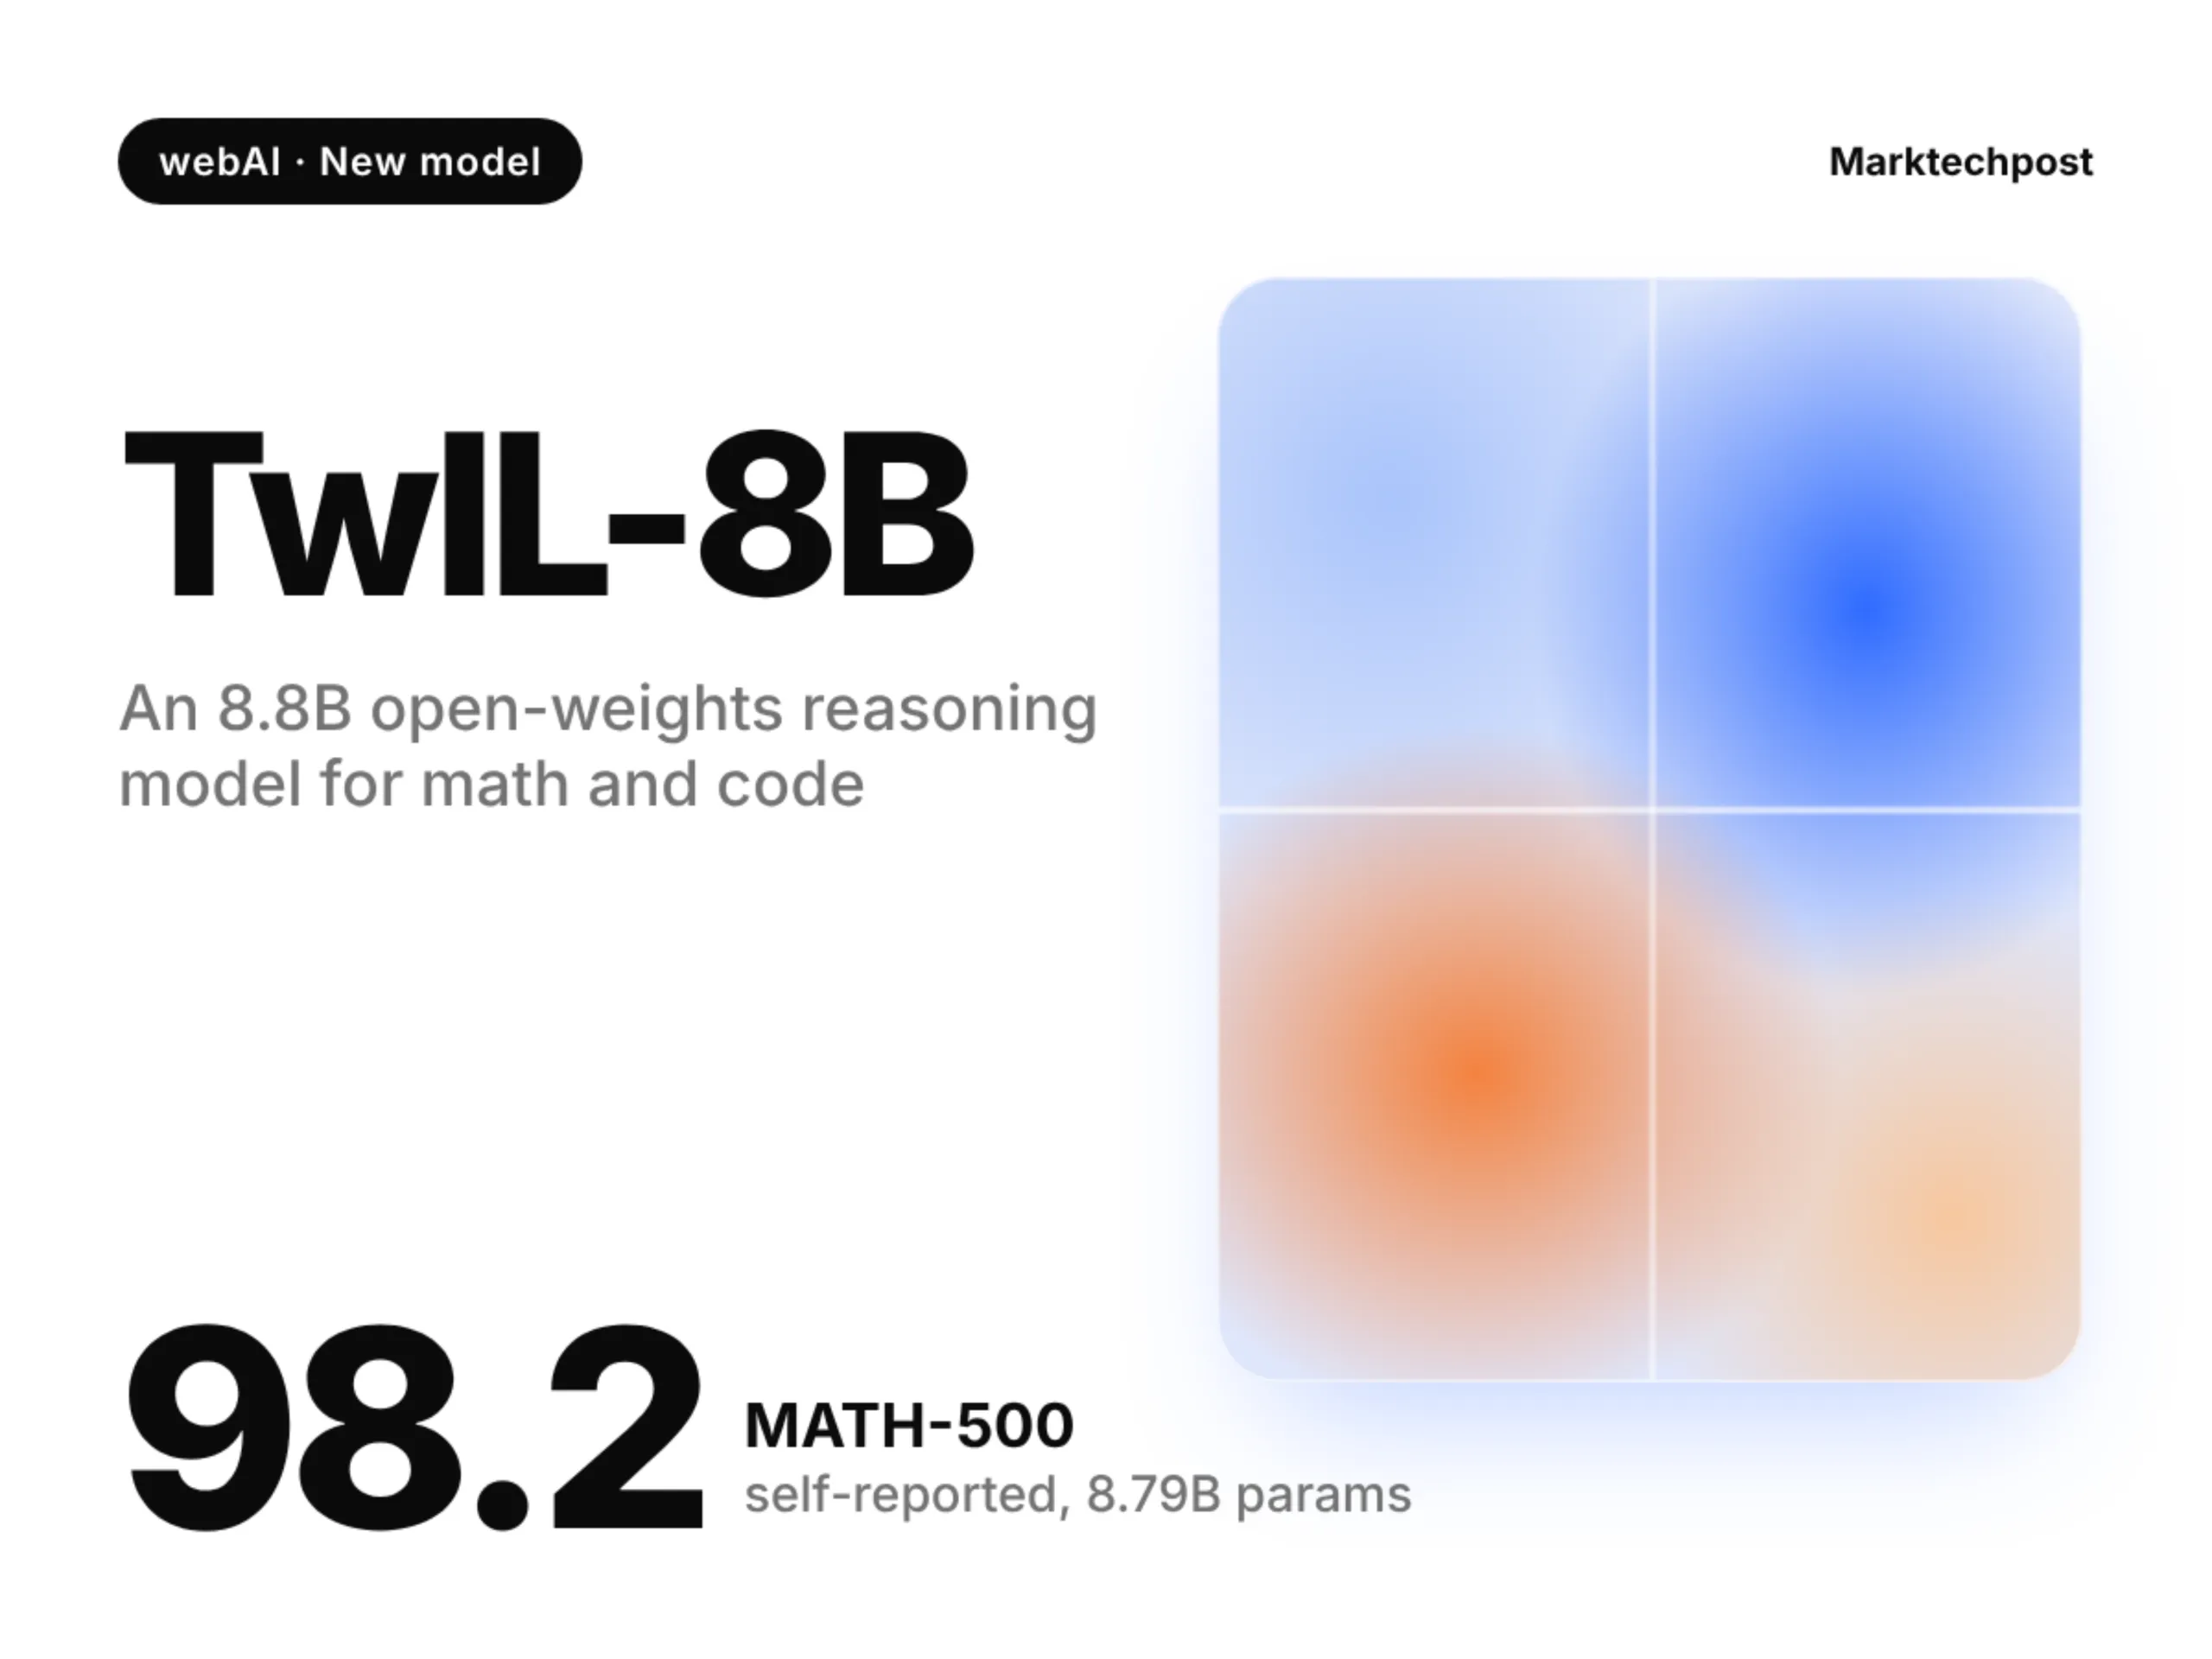
webAI Releases TwIL-8B, an 8.8B Reasoning Model Scoring 98.2 on MATH-500
webAI has released TwIL-8B, an 8.8B reasoning model for math, code and instruction following. The TwIL-8B reasoning model is post-trained from IBM’s Granite 4.2 8B. Weights are on Hugging Face under a non-commercial license. webAI’s launch post frames the pitch around cost per task, not raw scale. The 4-bit build is 4.98 GiB, sized for CPU or modest-VRAM GPU inference. TL;DR Size: 8.79B parameters, dense. 131,072-token context, inherited from the base model. Runs on: CPU o
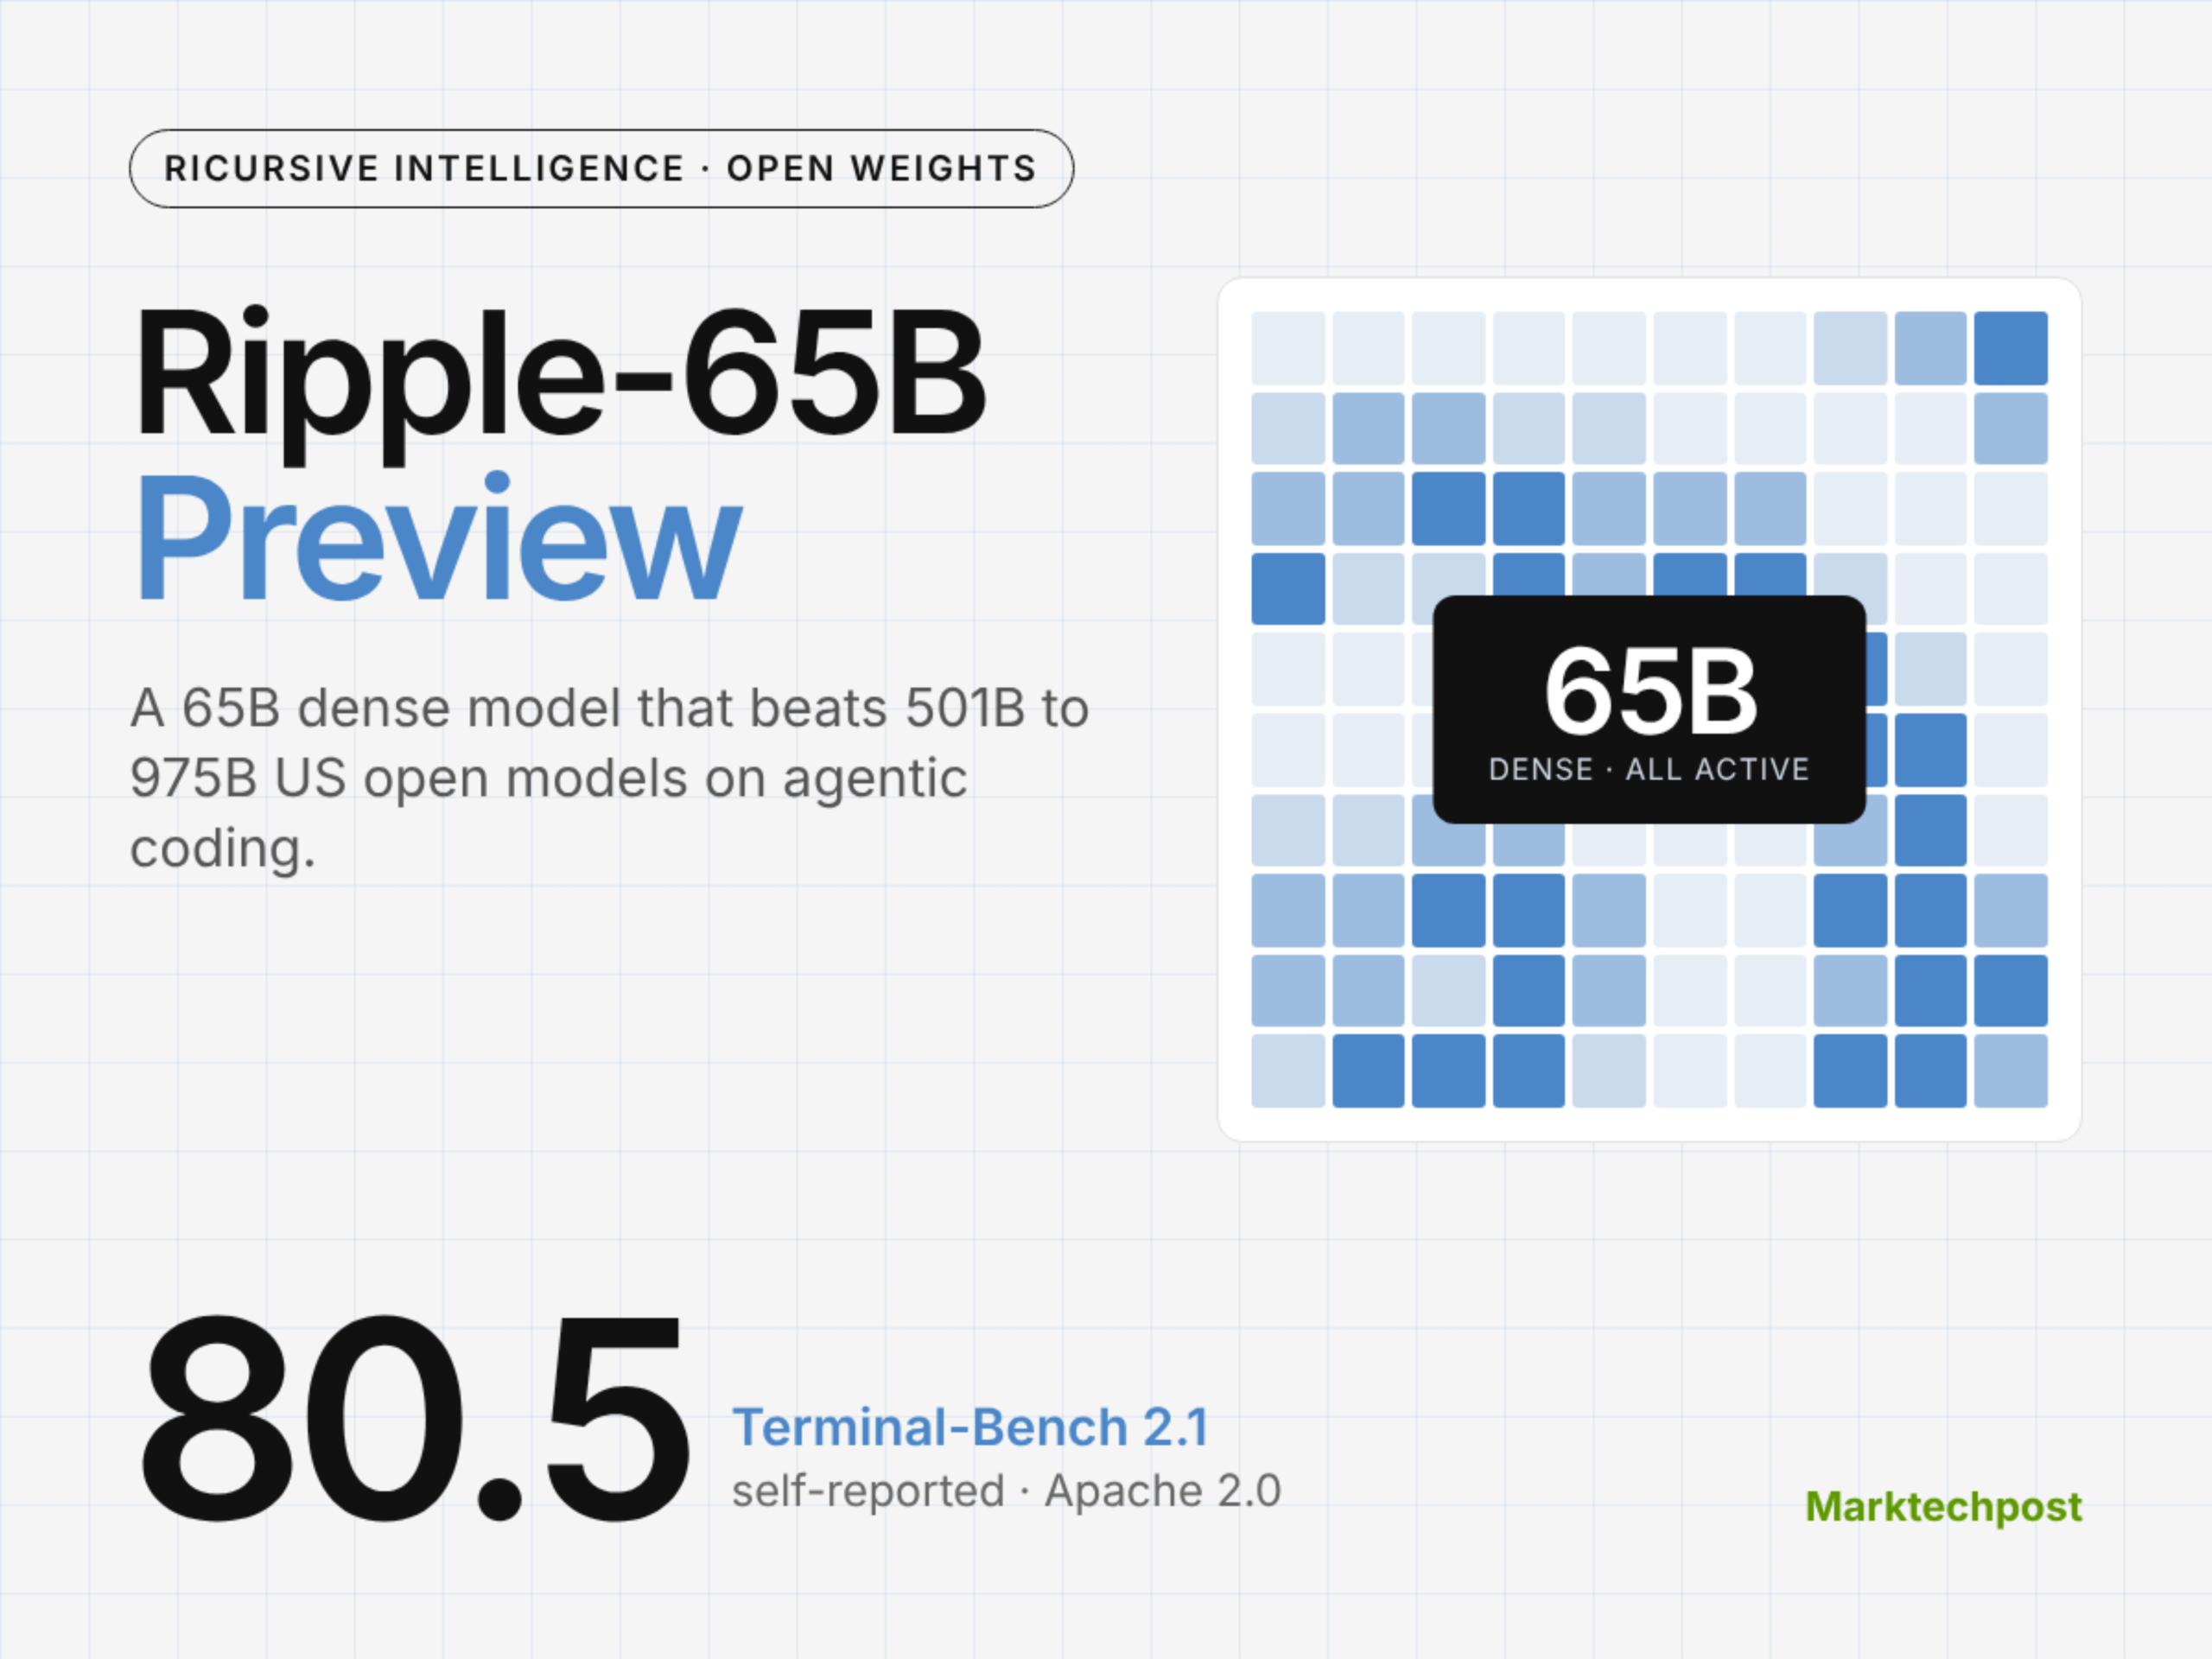
Ricursive AI Releases Ripple-65B Preview: A 65B Dense Open-Weight Model Scoring 80.5 on Terminal-Bench 2.1
Ricursive Intelligence just released Ripple-65B Preview. Ripple-65B Preview is a 65B dense open-weight model from Ricursive, pretrained from scratch for agentic coding. It is a general-purpose variant of the proprietary model behind Ricursive’s AI chip design platform. The main claim: 80.52 on Terminal-Bench 2.1, the top self-reported score among US open-weight models. Every MoE rival it beats on that test carries 501B to 975B total parameters. TL;DR Size: 65B dense (65B active), p

LifeVal
Introducing LifeVal, a benchmark measuring how well AI helps people complete everyday tasks, from finding childcare to managing finances and government paperwork.
GDPx: Measuring Frontier Model Capabilities Across the Most Valuable Domains
GDPx is a benchmark that covers the most valuable domains for frontier intelligence. It aims to be the world’s best benchmark for measuring general agentic capabilities.We believe the first trillion dollars of AI revenue will be concentrated in sectors that can deploy frontier intelligence at high ROI, not broadly diffused throughout the whole economy. Building a general-purpose benchmark based on share of GDP or the SOC/O*NET occupational taxonomy is therefore a mistake. If your goal is t
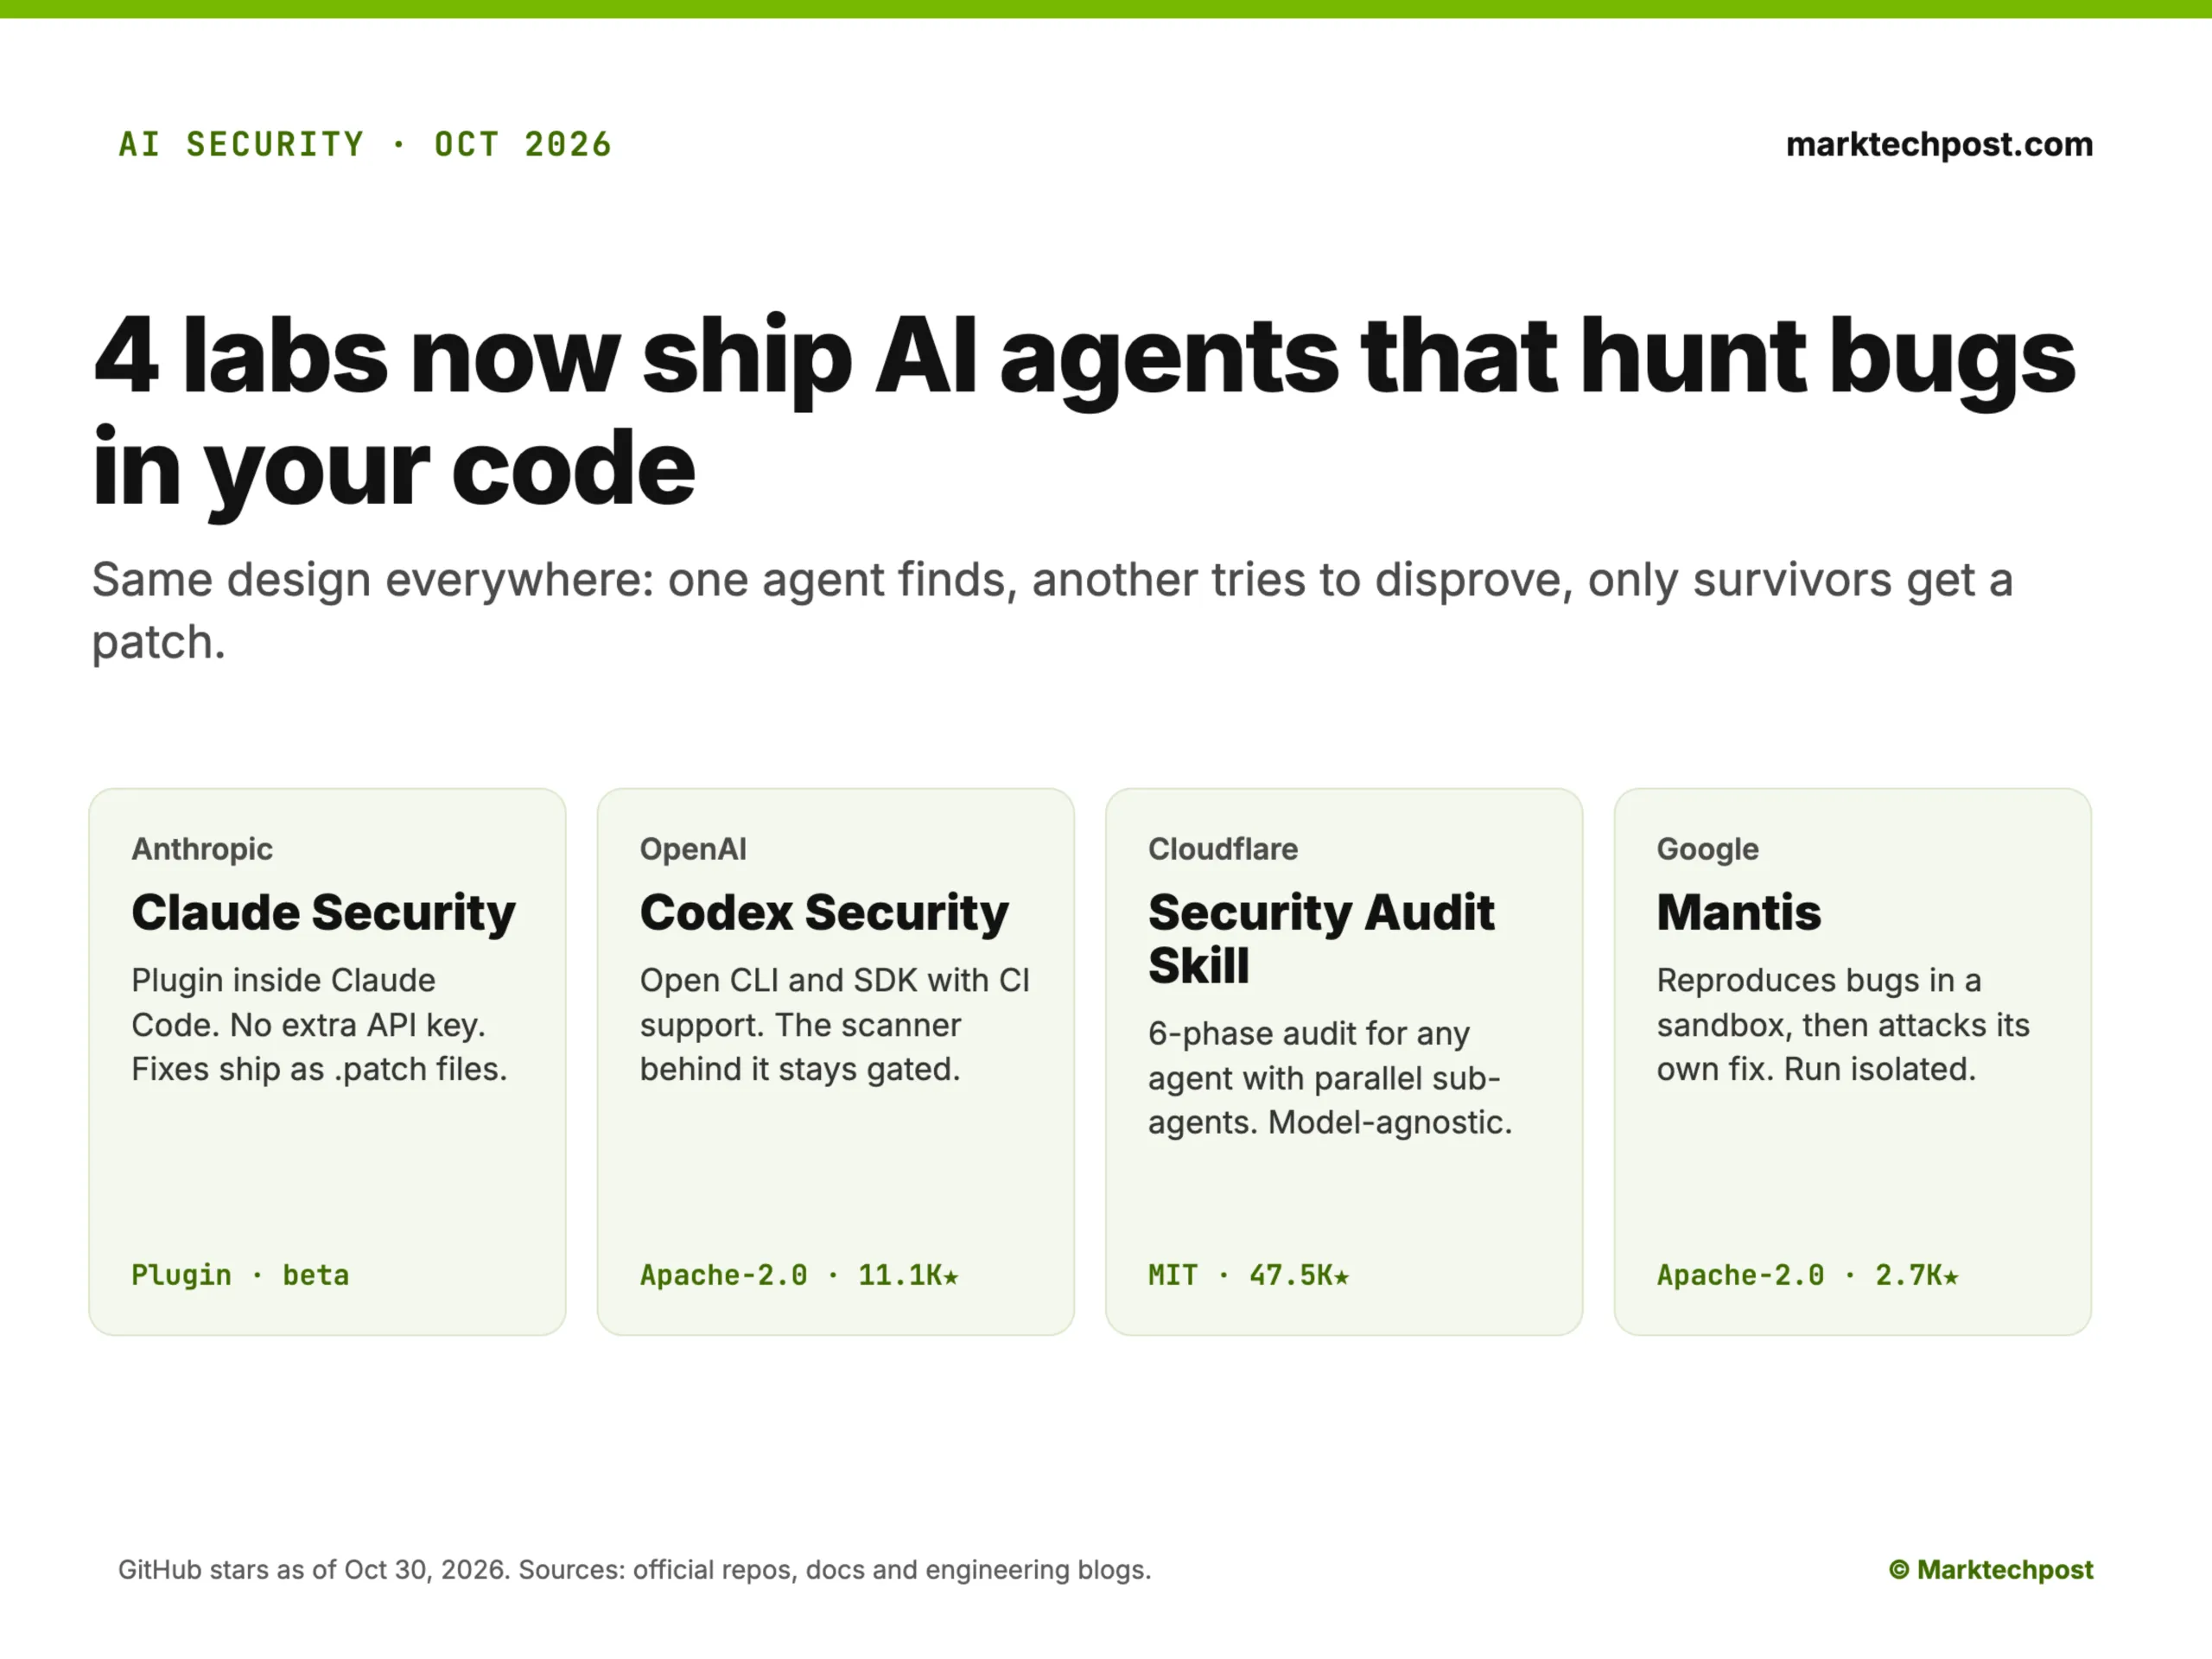
AI Security Agents Compared: Claude, Codex, Mantis, Cloudflare
Anthropic, OpenAI, Cloudflare and Google now each ship an AI agent that hunts security bugs in source code. We checked the repos, docs and technical details behind each one. The key finding: all 4 tools converge on one design. One agent finds a bug, a separate agent tries to disprove it, and only survivors get a patch. The differences are in where they run, who can use them and how much proof they demand. Key Takeaways 4 labs, 1 pattern: find, independently disprove, then patch. Cl

CWE-bench v2: More coverage, quality, and transparency
Better evaluation of software vulnerabilities helps developers identify and fix security flaws before they reach production.