
OpenAI releases LifeVal benchmark for everyday tasks
OpenAI: LifeVal
Introducing LifeVal, a benchmark measuring how well AI helps people complete everyday tasks, from finding childcare to managing finances and government paperwork.
Get smart on it
LifeVal is an evaluation tool that measures how well AI models perform on practical everyday tasks that people actually need help with, such as childcare, budgeting, shopping, and accessing government services. OpenAI built this evaluation by studying how people spend their time through existing surveys and then conducting a new survey of nearly 4,000 respondents to identify where they most wanted AI assistance. The tool matters because OpenAI states that ensuring artificial general intelligence benefits all of humanity requires measuring model progress on what matters in everyday life, beyond just academic knowledge tests. According to the published results, successive model versions have shown improvement on these tasks over the past year, with scores on individual tasks ranging from around 90 percent to 100 percent on various practical workflows.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Mistral Says Its AI Model ‘Le Chonk’ Has Leapfrogged China in the Open-Weight Race
The French AI lab claims its latest release matches or outperforms even the best models from DeepSeek and Z.ai in coding and cybersecurity.
GDPx: Measuring Frontier Model Capabilities Across the Most Valuable Domains
GDPx is a benchmark that covers the most valuable domains for frontier intelligence. It aims to be the world’s best benchmark for measuring general agentic capabilities.We believe the first trillion dollars of AI revenue will be concentrated in sectors that can deploy frontier intelligence at high ROI, not broadly diffused throughout the whole economy. Building a general-purpose benchmark based on share of GDP or the SOC/O*NET occupational taxonomy is therefore a mistake. If your goal is t
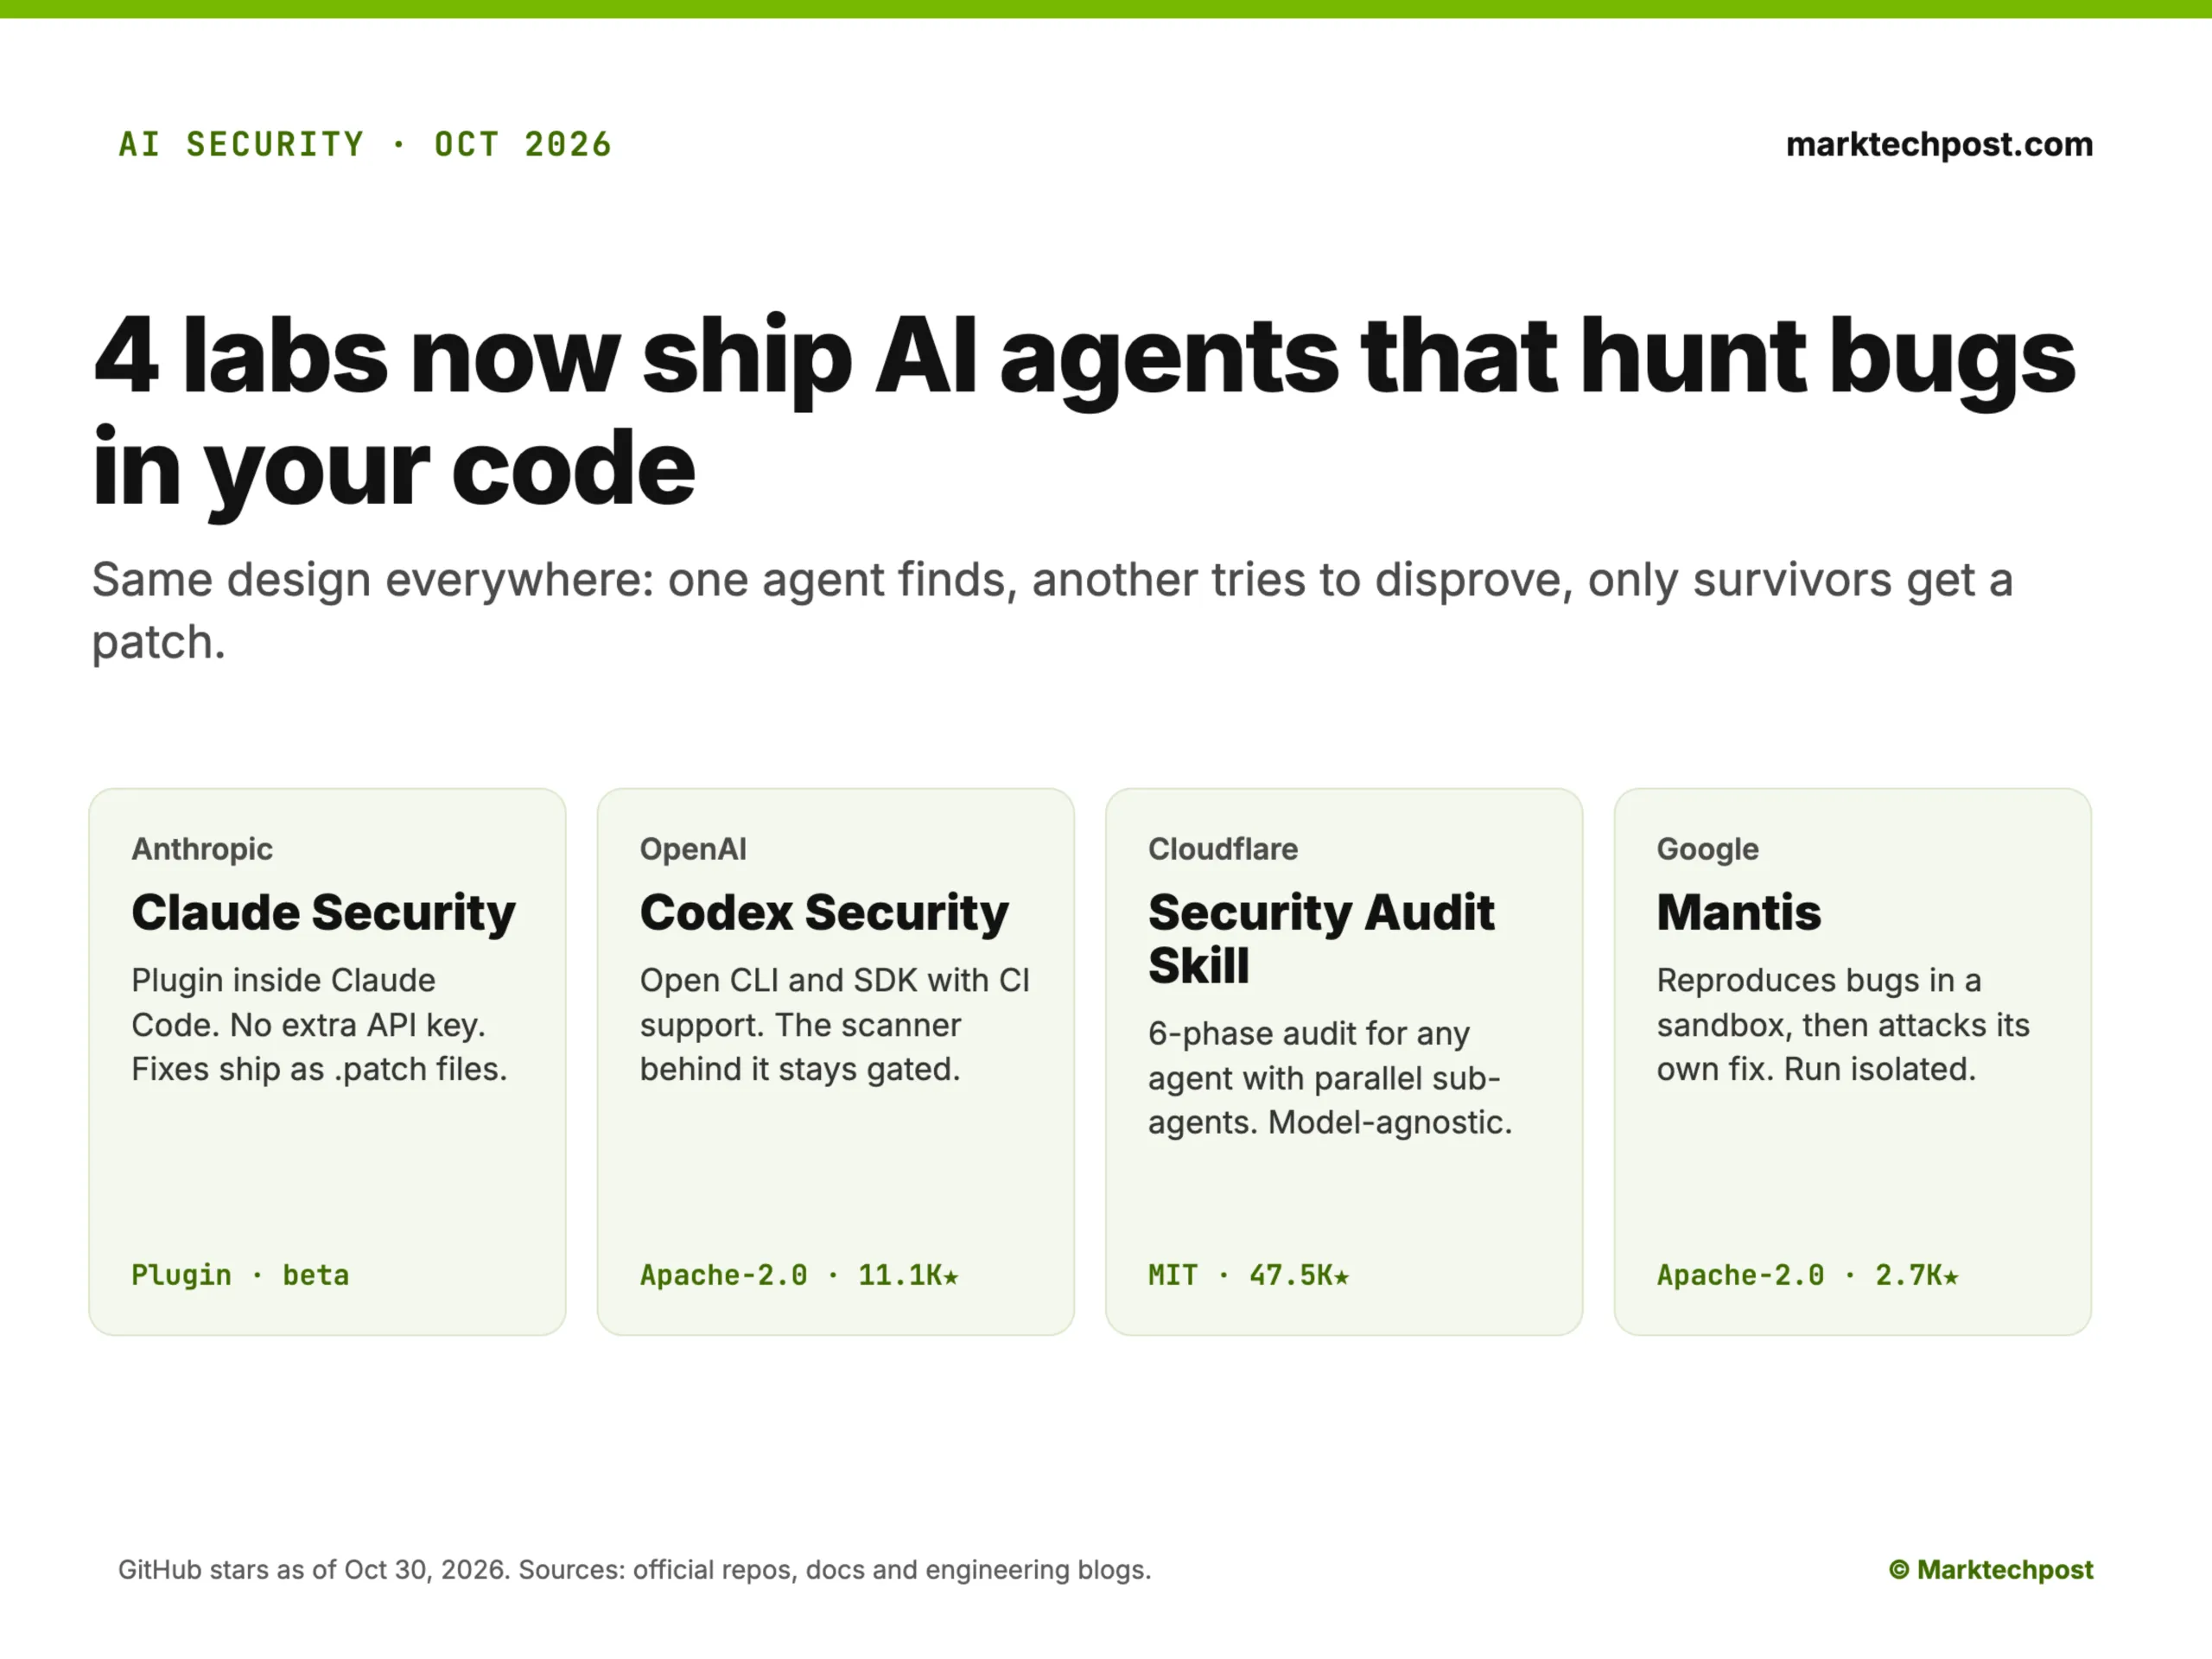
AI Security Agents Compared: Claude, Codex, Mantis, Cloudflare
Anthropic, OpenAI, Cloudflare and Google now each ship an AI agent that hunts security bugs in source code. We checked the repos, docs and technical details behind each one. The key finding: all 4 tools converge on one design. One agent finds a bug, a separate agent tries to disprove it, and only survivors get a patch. The differences are in where they run, who can use them and how much proof they demand. Key Takeaways 4 labs, 1 pattern: find, independently disprove, then patch. Cl
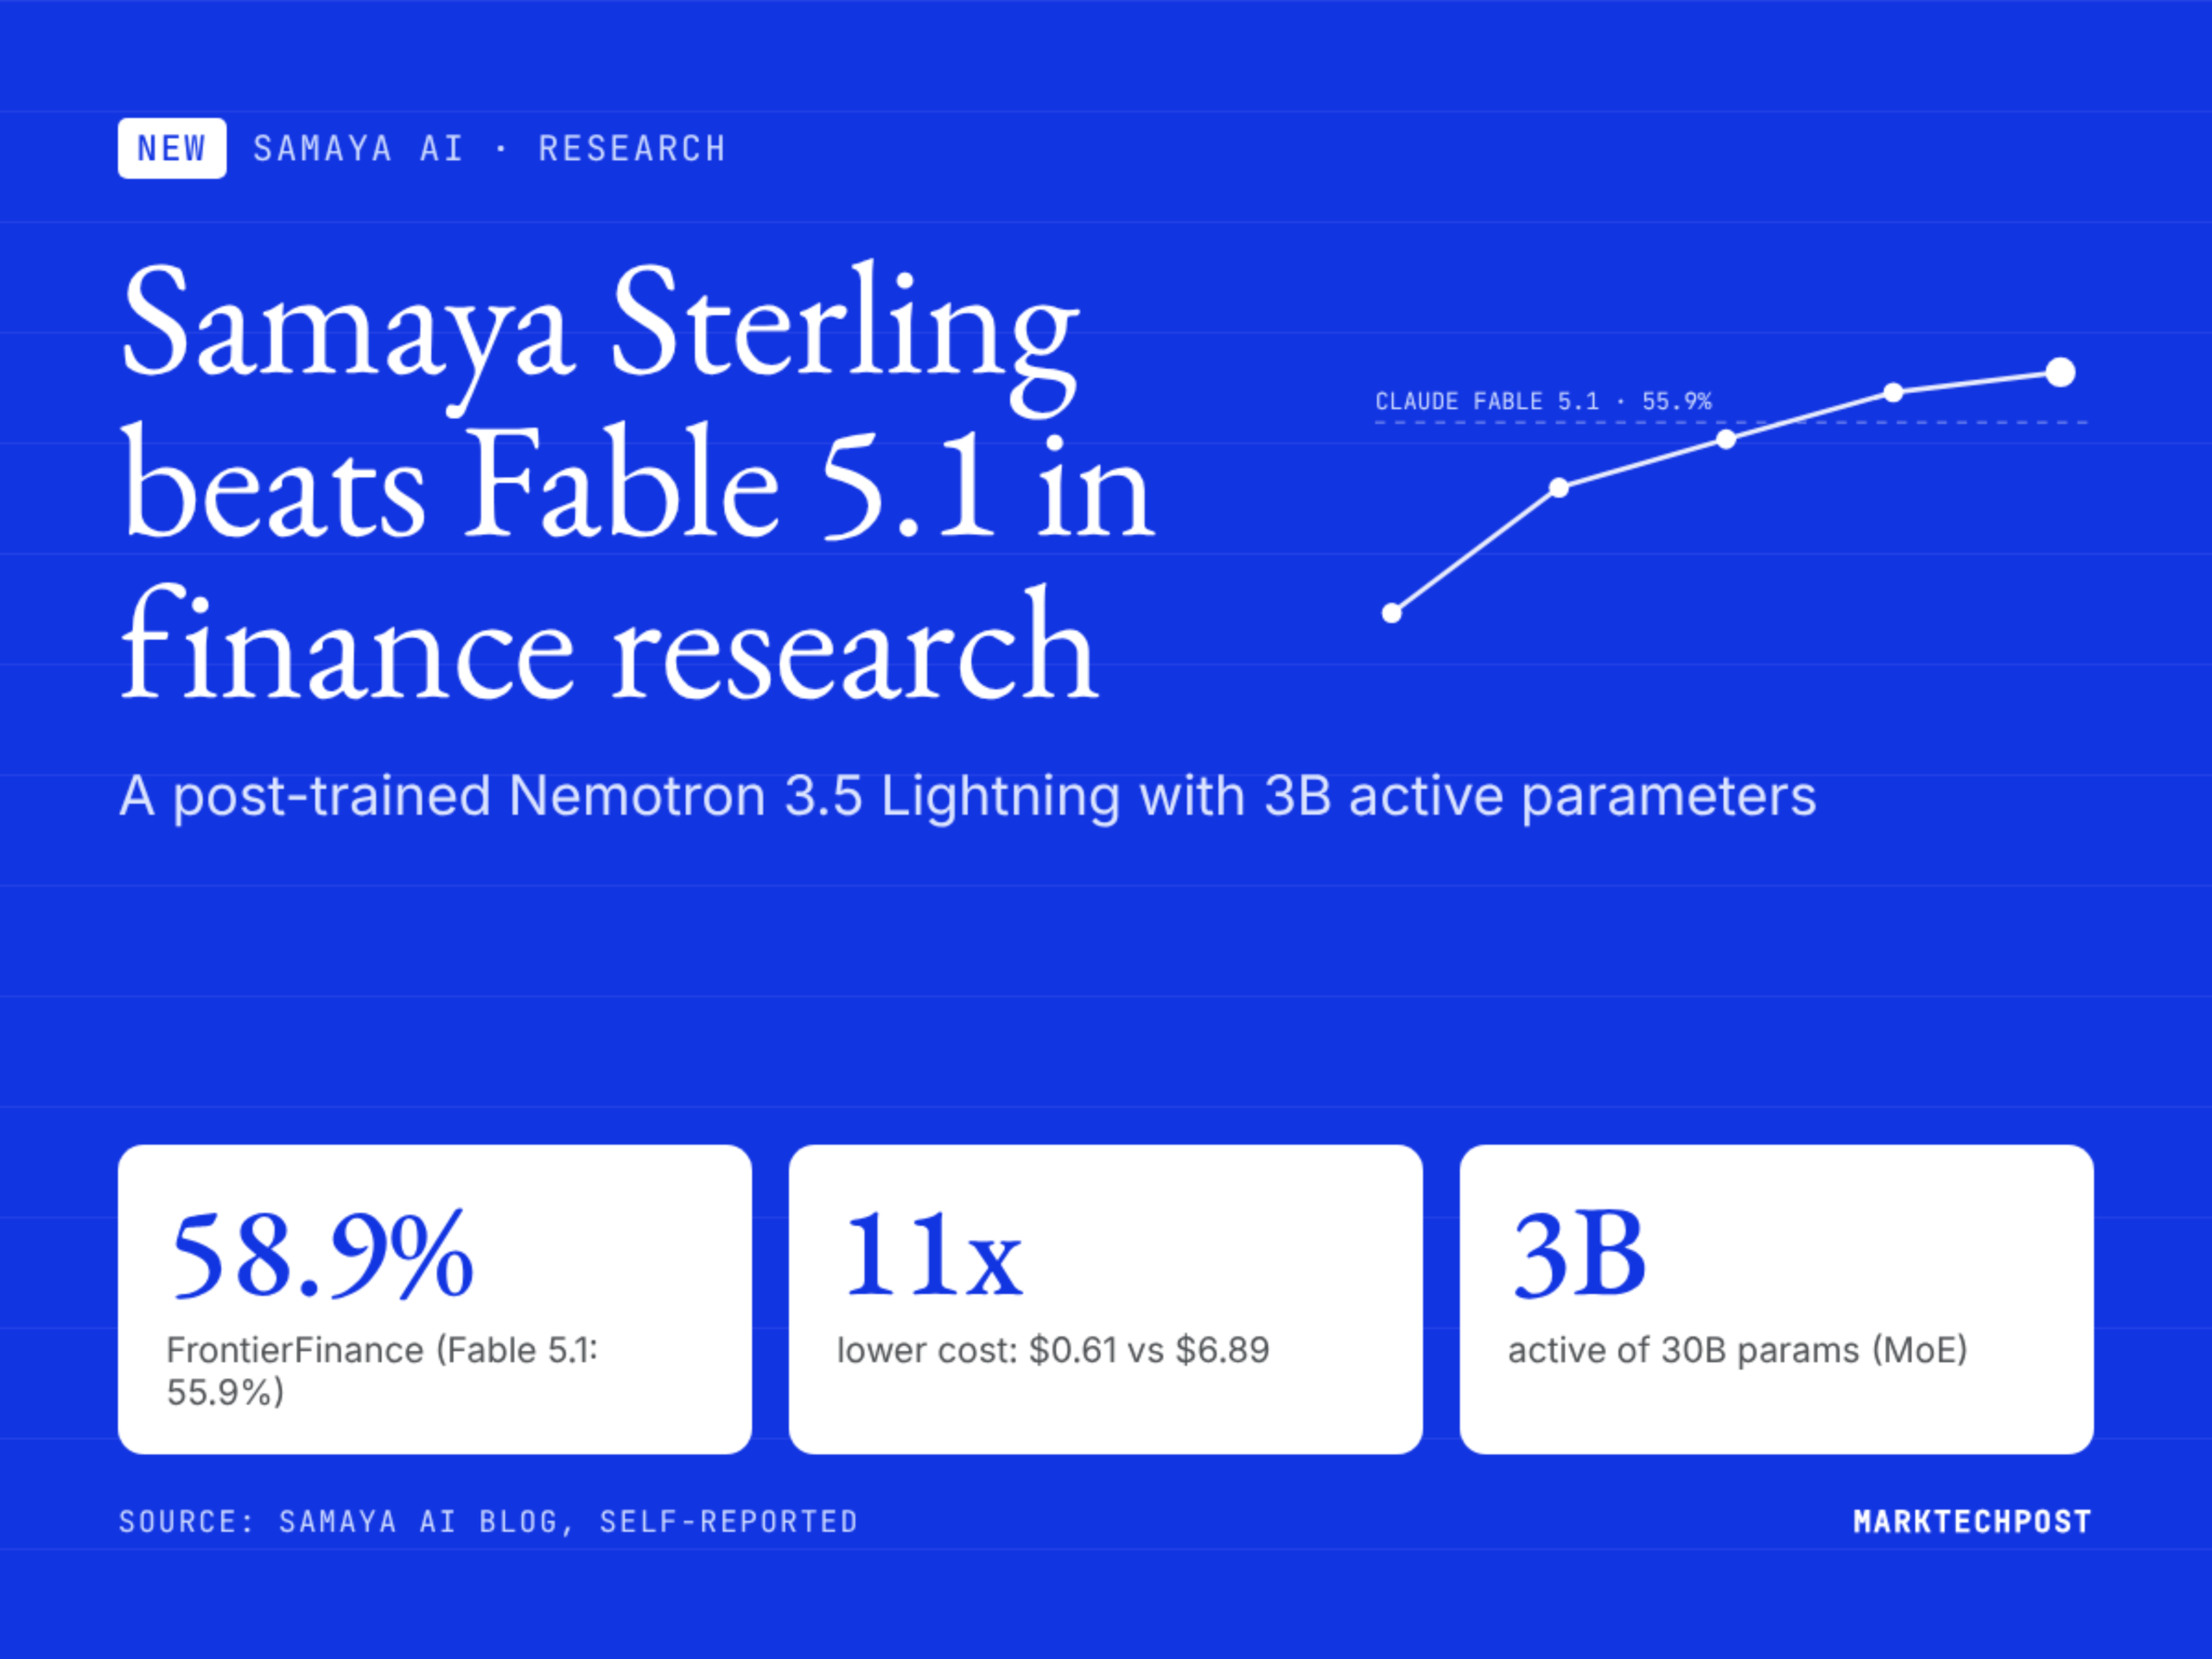
Samaya AI Releases Sterling: A 3B-Active Finance Research Agent Model that Beats Claude Fable 5.1 on FrontierFinance at 11x Lower Cost
Samaya AI has released Samaya Sterling, a post-trained model for agentic financial research. Sterling is built on NVIDIA’s Nemotron 3.5 Lightning, a 30B mixture-of-experts model with 3B active parameters. On Samaya’s FrontierFinance benchmark, it scores 58.9%. Claude Fable 5.1 scores 55.9%. Each Sterling question costs $0.61, against $6.89 for Fable 5.1. For developers, the takeaway is a concrete recipe: co-train a small model with its harness, and it can win in a narrow domain.
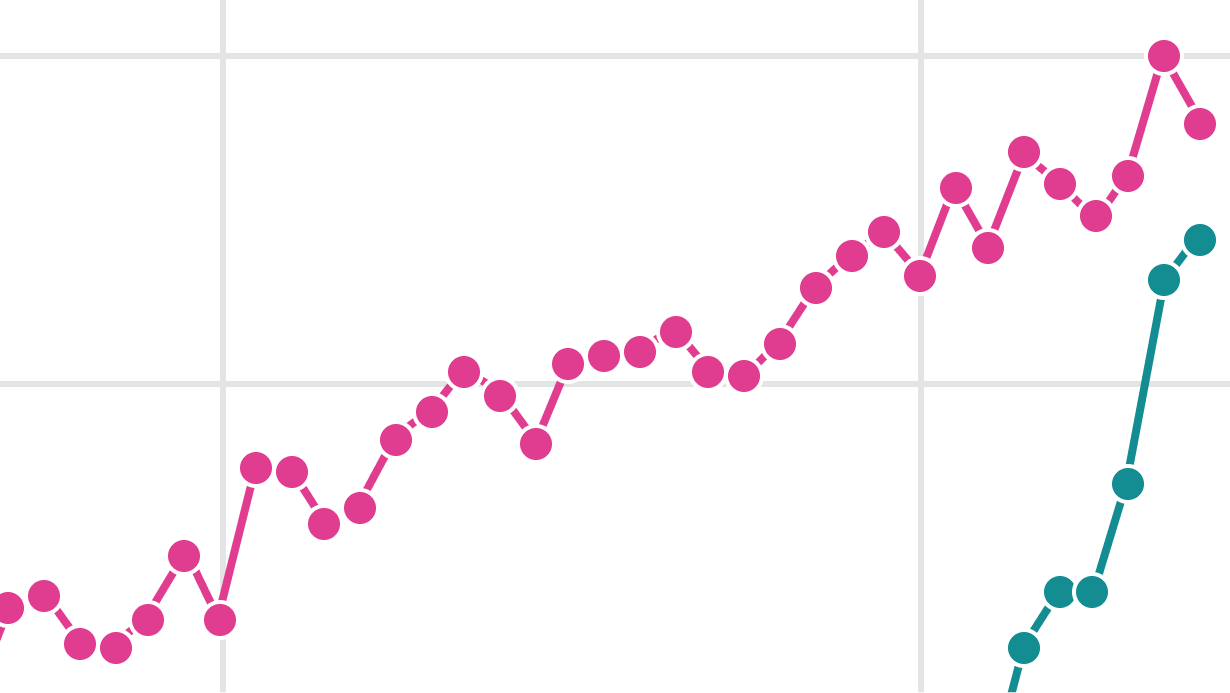
LLM use is acknowledged almost as often as specialized AI tools in biology preprints
17% of biology preprints acknowledge LLM use, nearly matching specialized tools like AlphaFold. Epoch AI analyzes trends in AI acknowledgment in research.
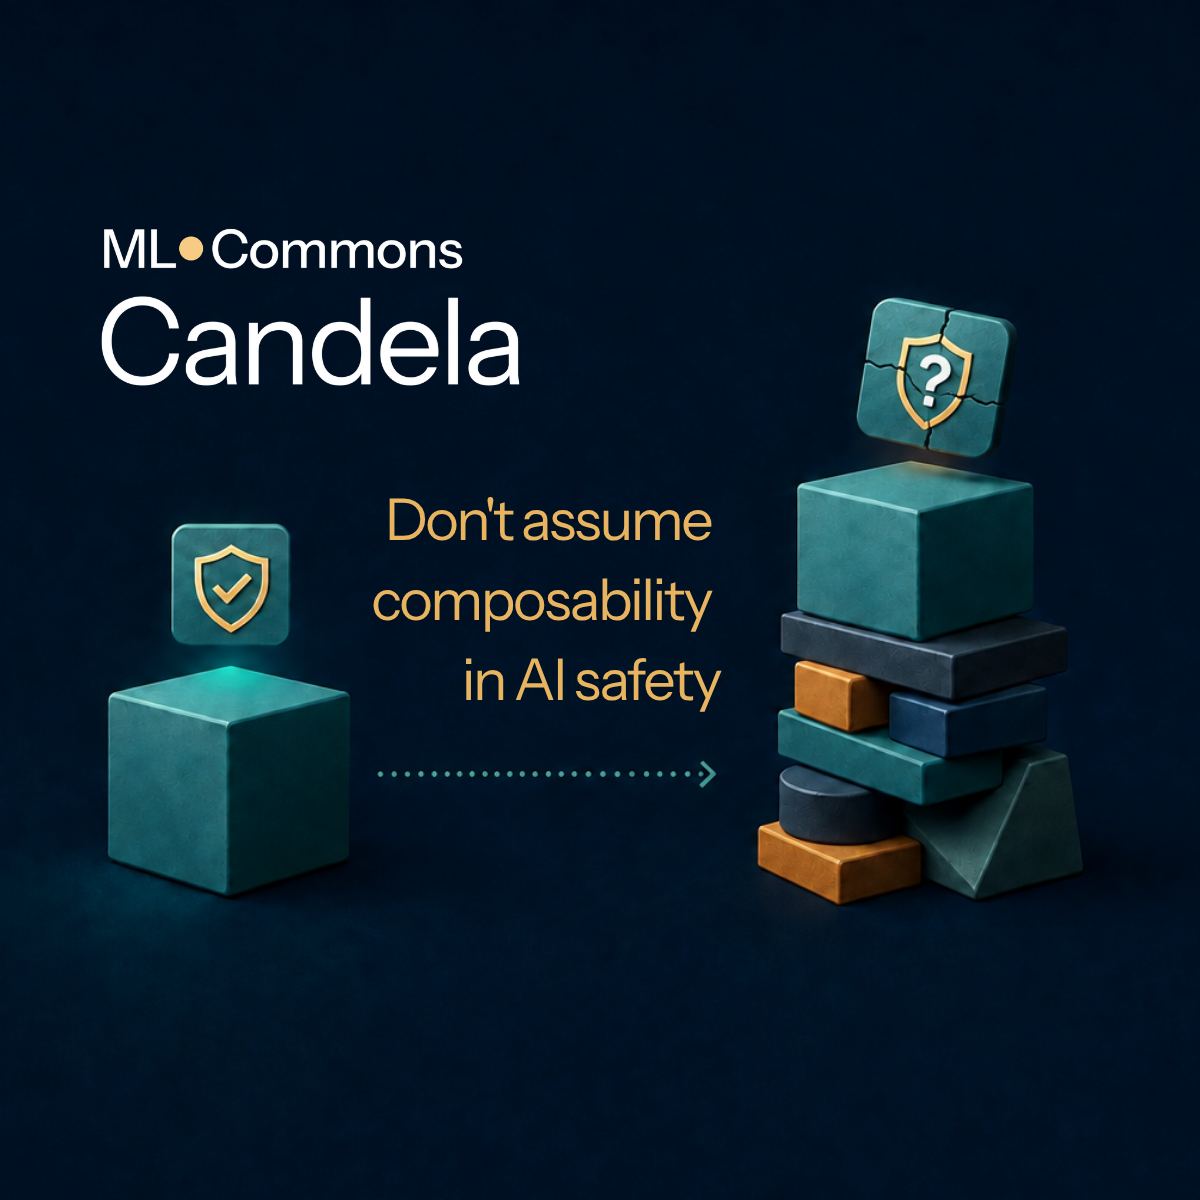
Don’t assume composability in AI safety. Deployments need their own testing.
Practitioners know that a deployed system behaves differently from its base model, and that its behavior keeps changing as they change the system prompt, retrieval layers, fine-tuning, and so on. But safety evaluation often assumes the opposite, with teams citing the base model’s safety score from the system card for whatever they’ve done on top of the model. Many in the field end up holding both beliefs at once: expecting behavior to shift when they build on a model, yet basing purchasing and