
Introducing MentalHealthBench
MentalHealthBench is an expert-informed benchmark for evaluating helpful and safe AI responses across realistic mental health conversations.
Get smart on it
MentalHealthBench is an open benchmark created with more than 80 licensed mental health experts from 22 countries to measure how AI systems respond in realistic mental health conversations. The benchmark assesses model capabilities across key behaviors like safety, seeking context, preserving user agency, and providing actionable guidance, covering a full spectrum of situations from everyday stress to mental health emergencies. It matters because most previous AI evaluations in mental health have focused primarily on emergency scenarios, leaving a gap in understanding how models perform across the full range of conversations people have about well-being and life advice. The benchmark uses synthetic conversations that reflect real-world usage patterns and expert-written criteria with weighted scores to evaluate whether AI responses align with clinical guidance.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
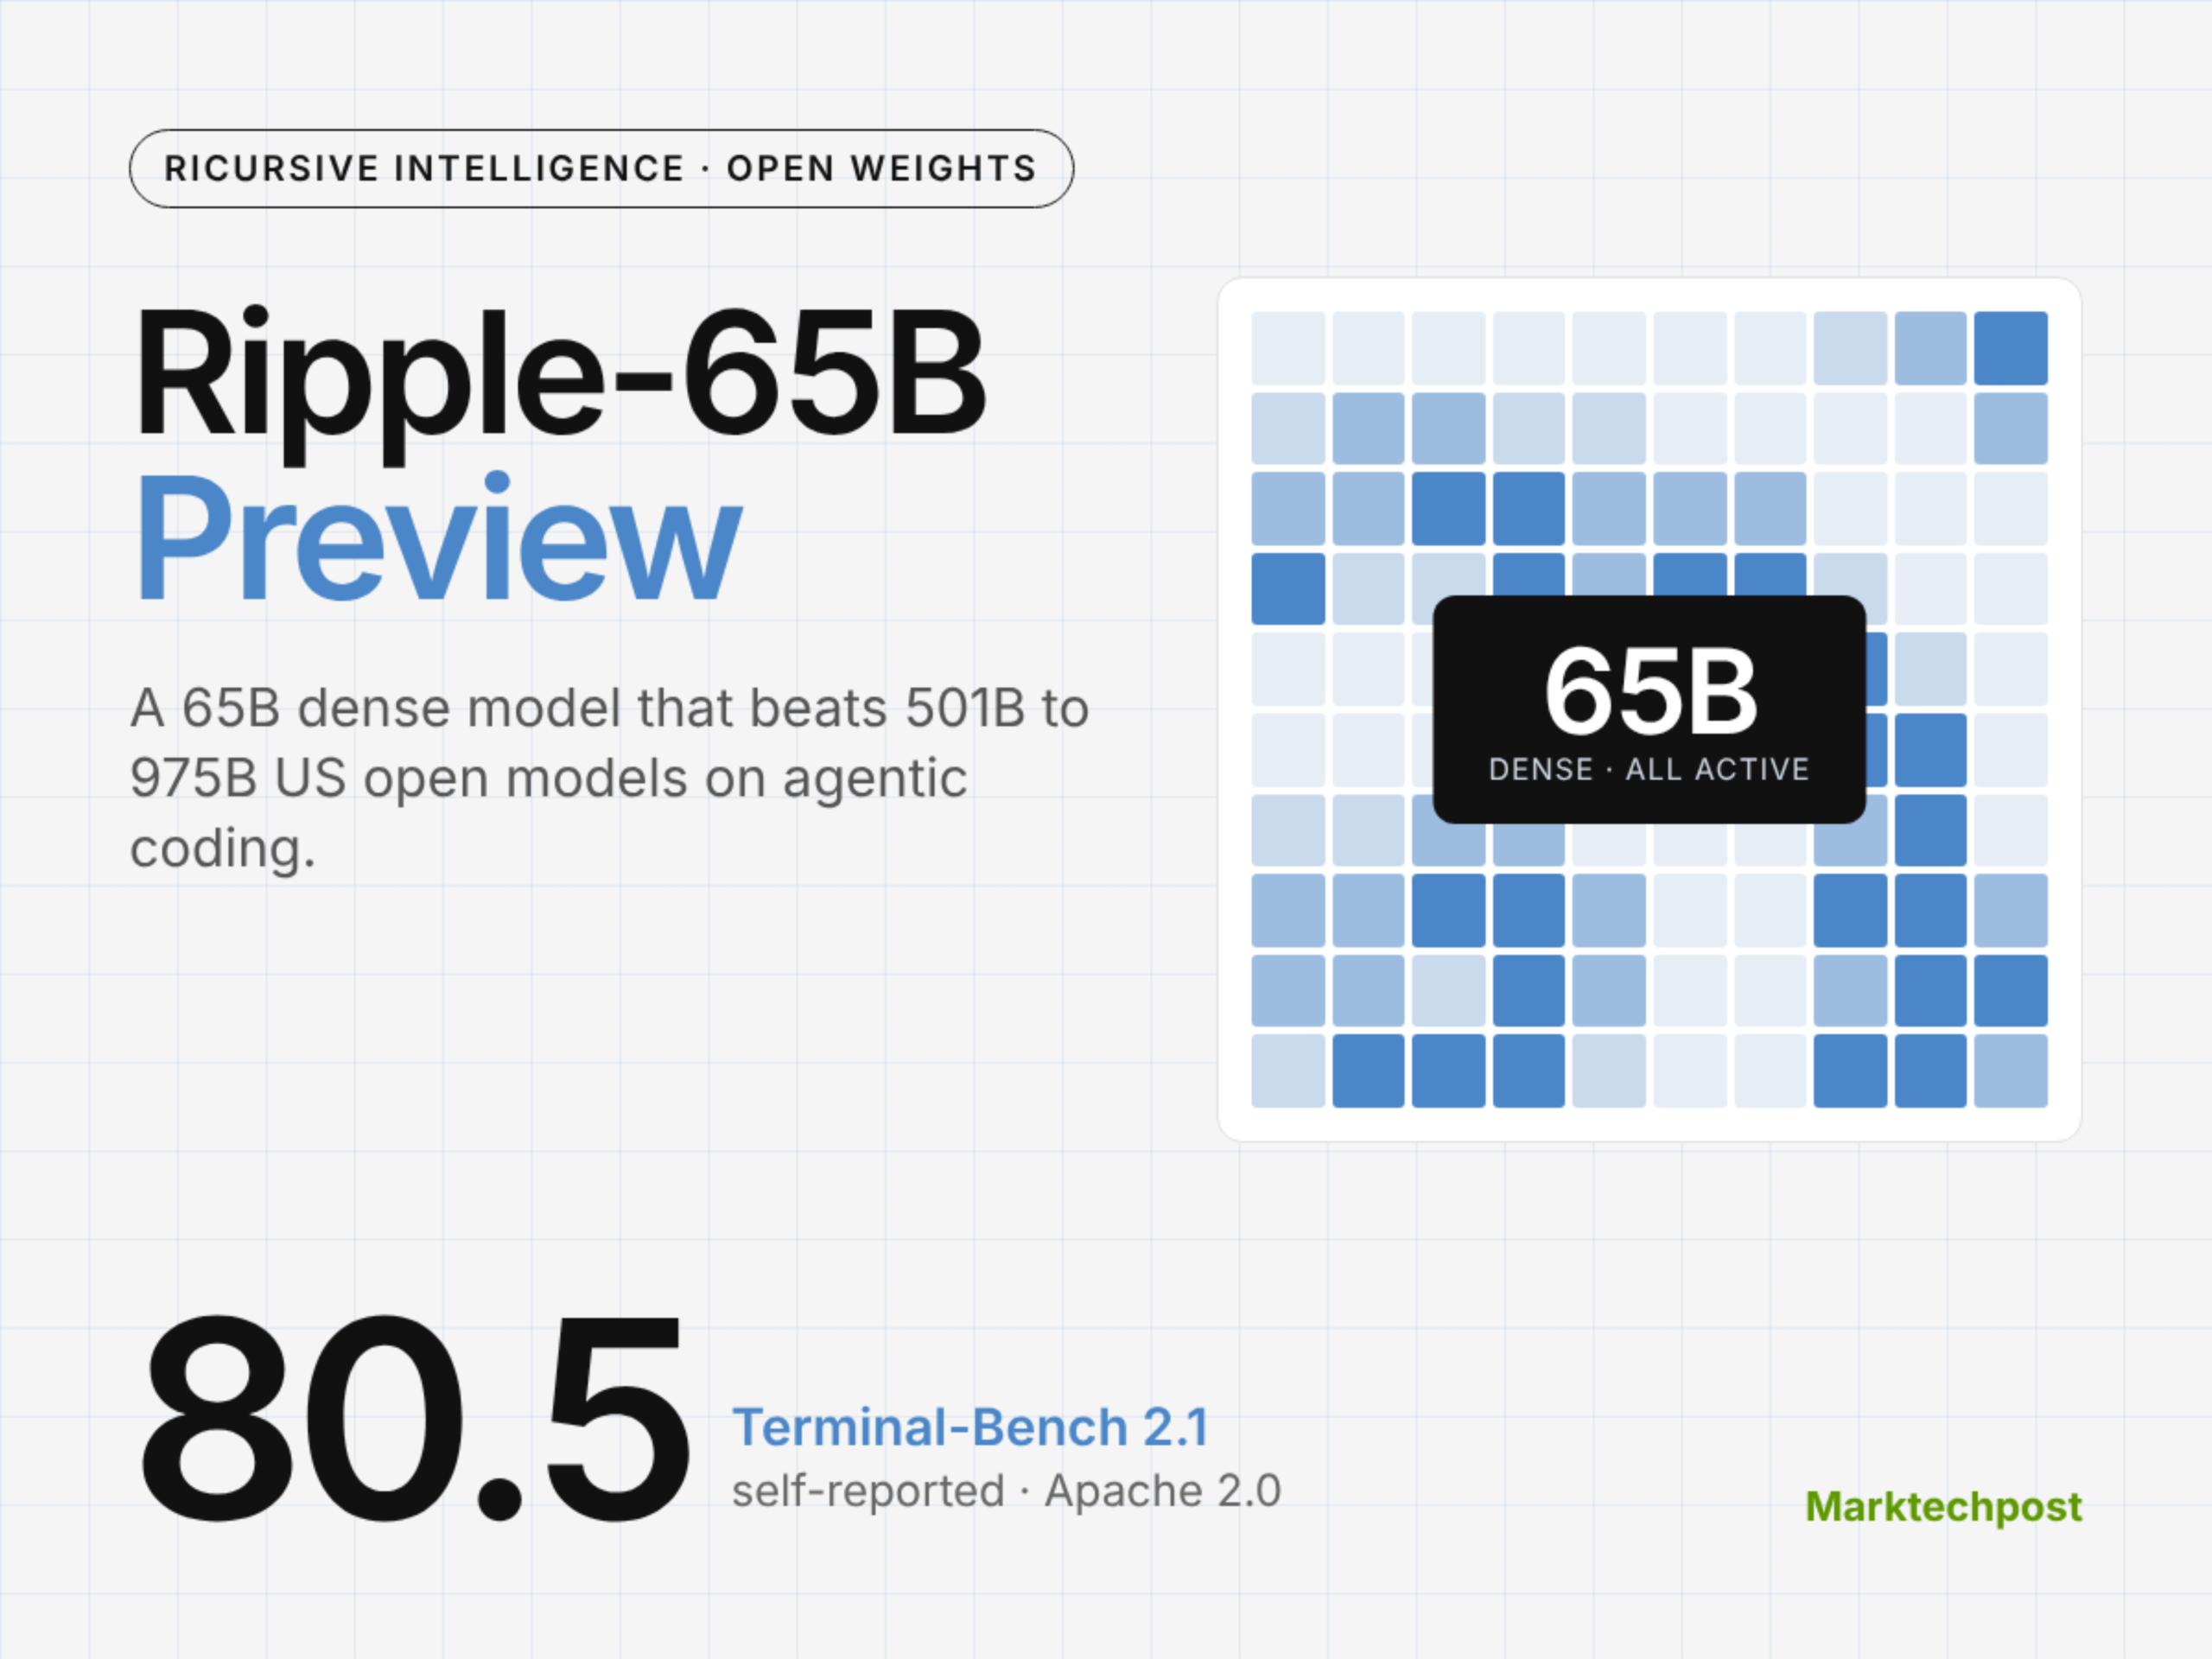
Ricursive AI Releases Ripple-65B Preview: A 65B Dense Open-Weight Model Scoring 80.5 on Terminal-Bench 2.1
Ricursive Intelligence just released Ripple-65B Preview. Ripple-65B Preview is a 65B dense open-weight model from Ricursive, pretrained from scratch for agentic coding. It is a general-purpose variant of the proprietary model behind Ricursive’s AI chip design platform. The main claim: 80.52 on Terminal-Bench 2.1, the top self-reported score among US open-weight models. Every MoE rival it beats on that test carries 501B to 975B total parameters. TL;DR Size: 65B dense (65B active), p
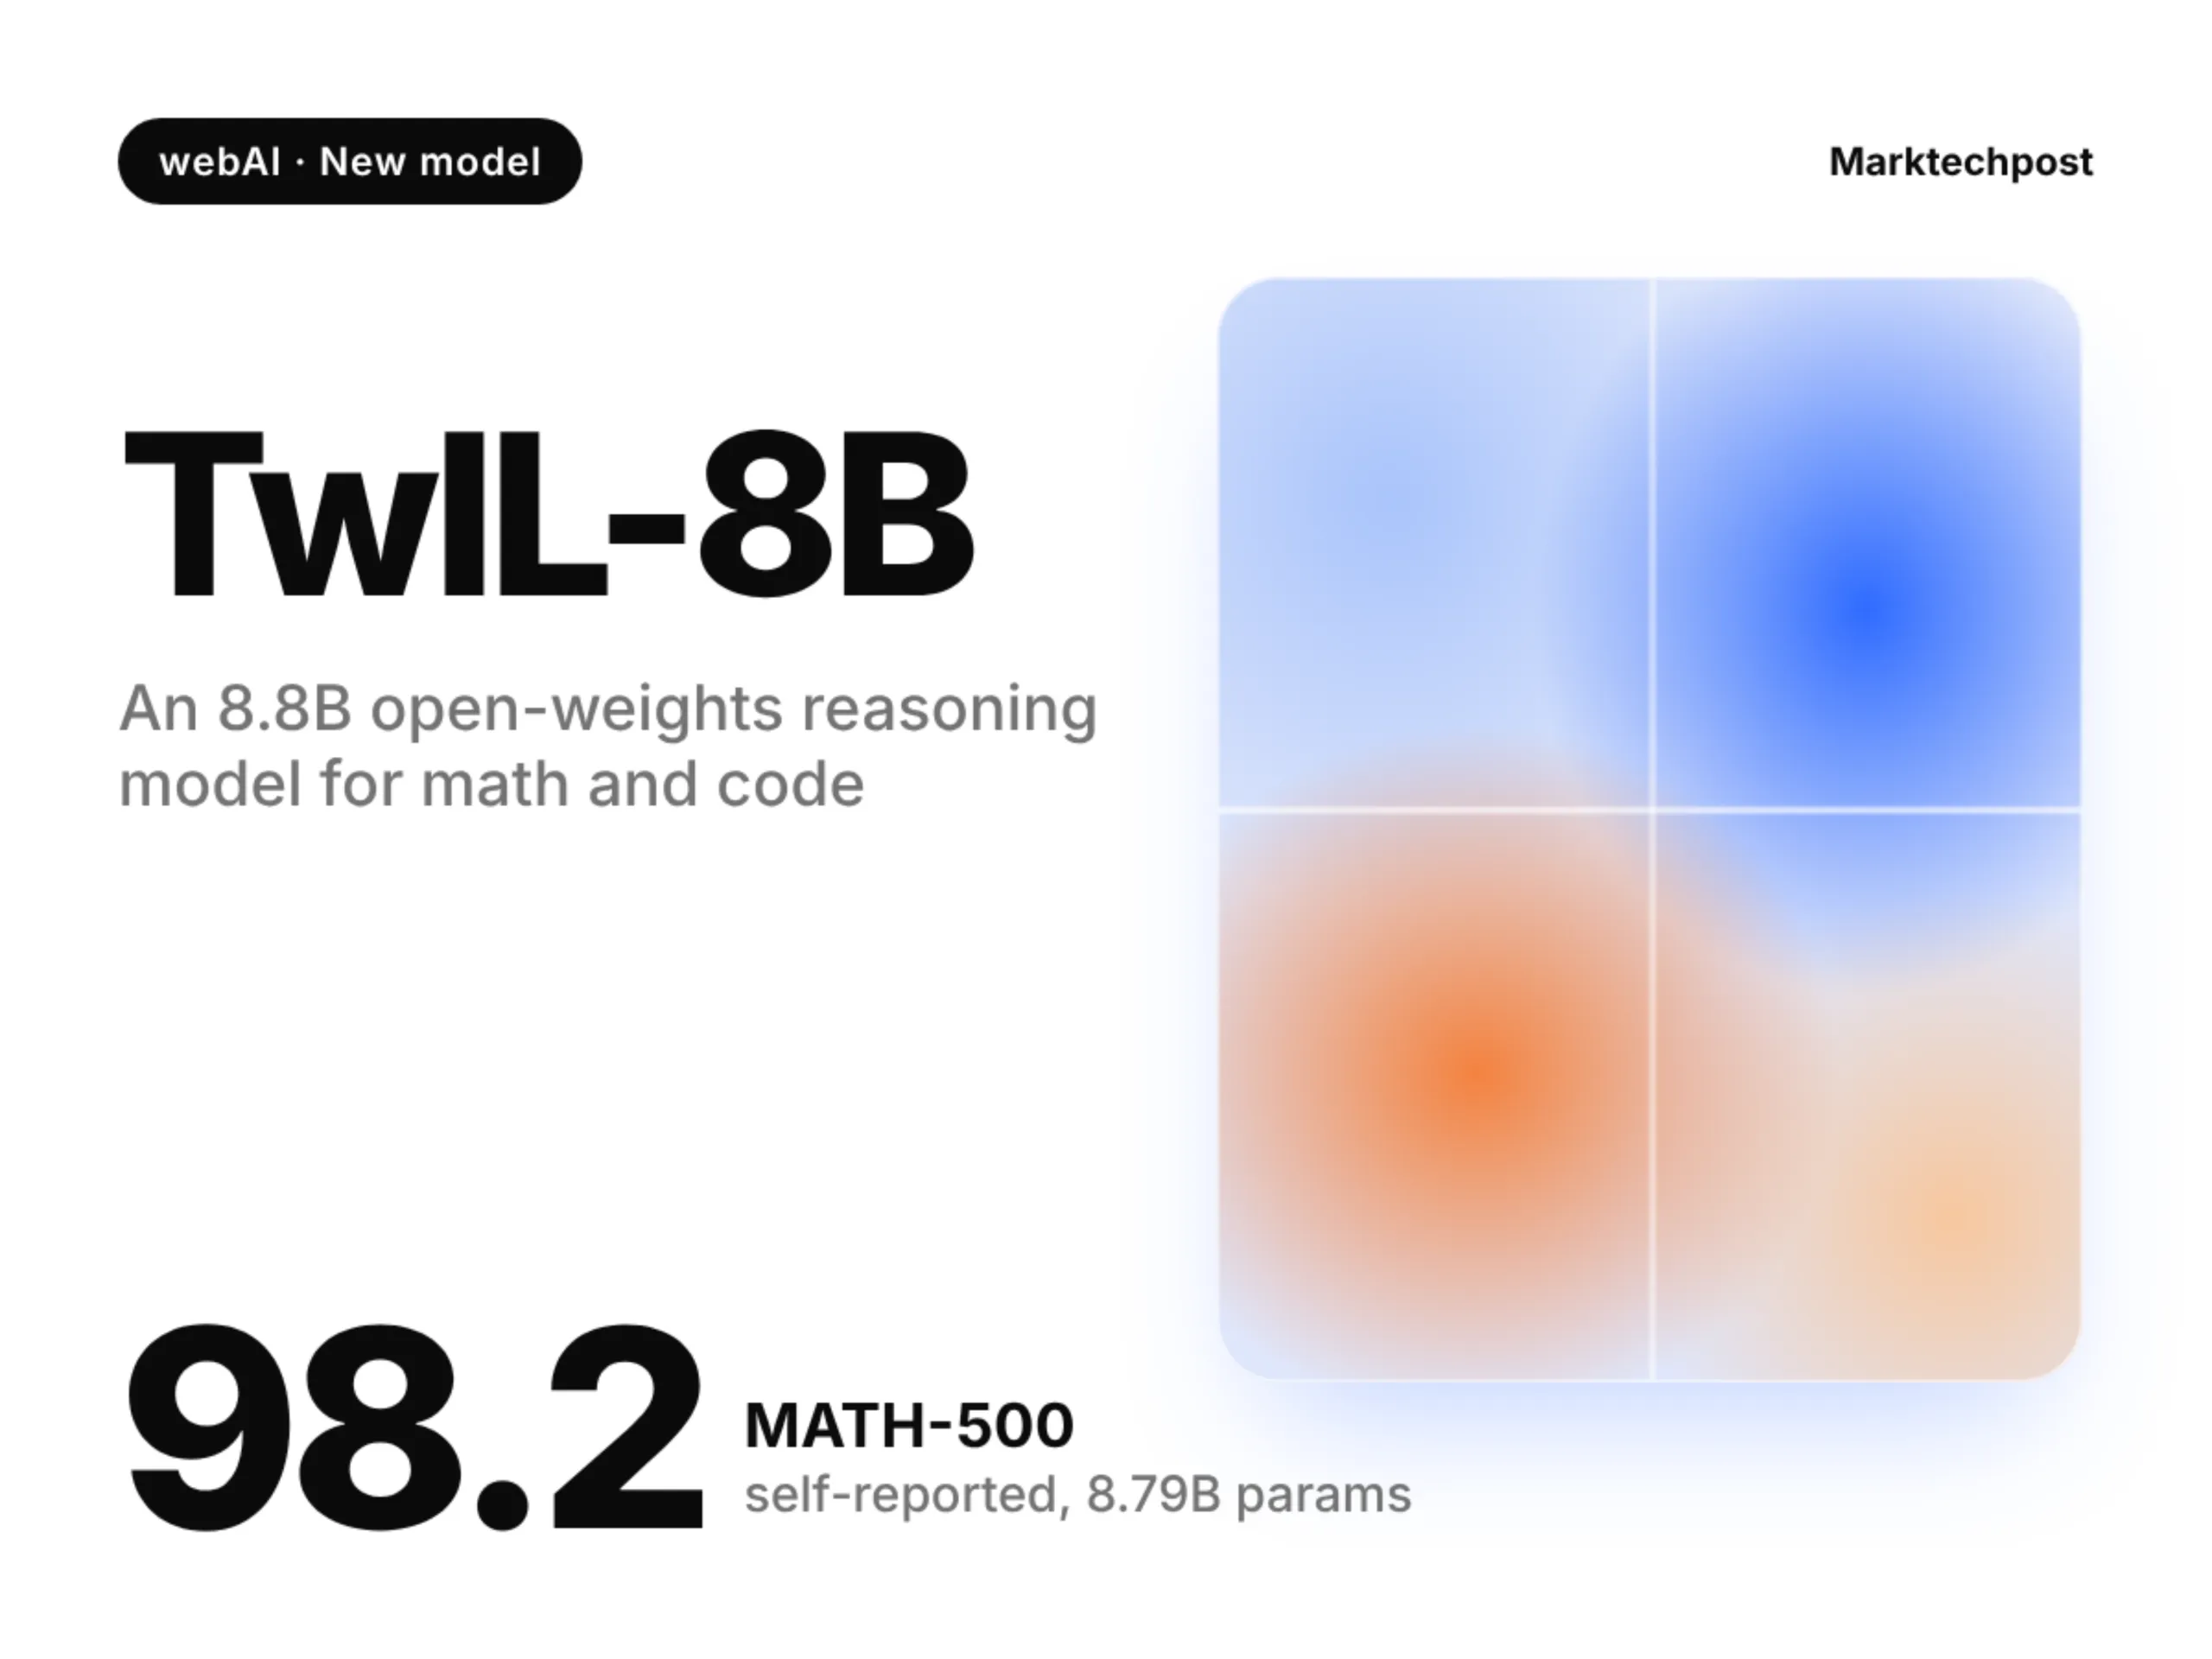
webAI Releases TwIL-8B, an 8.8B Reasoning Model Scoring 98.2 on MATH-500
webAI has released TwIL-8B, an 8.8B reasoning model for math, code and instruction following. The TwIL-8B reasoning model is post-trained from IBM’s Granite 4.2 8B. Weights are on Hugging Face under a non-commercial license. webAI’s launch post frames the pitch around cost per task, not raw scale. The 4-bit build is 4.98 GiB, sized for CPU or modest-VRAM GPU inference. TL;DR Size: 8.79B parameters, dense. 131,072-token context, inherited from the base model. Runs on: CPU o

Egyptian and Nigerian English join the Open ASR Leaderboard
The leaderboard now covers more African languages, helping developers build speech recognition tools that work for underserved populations.
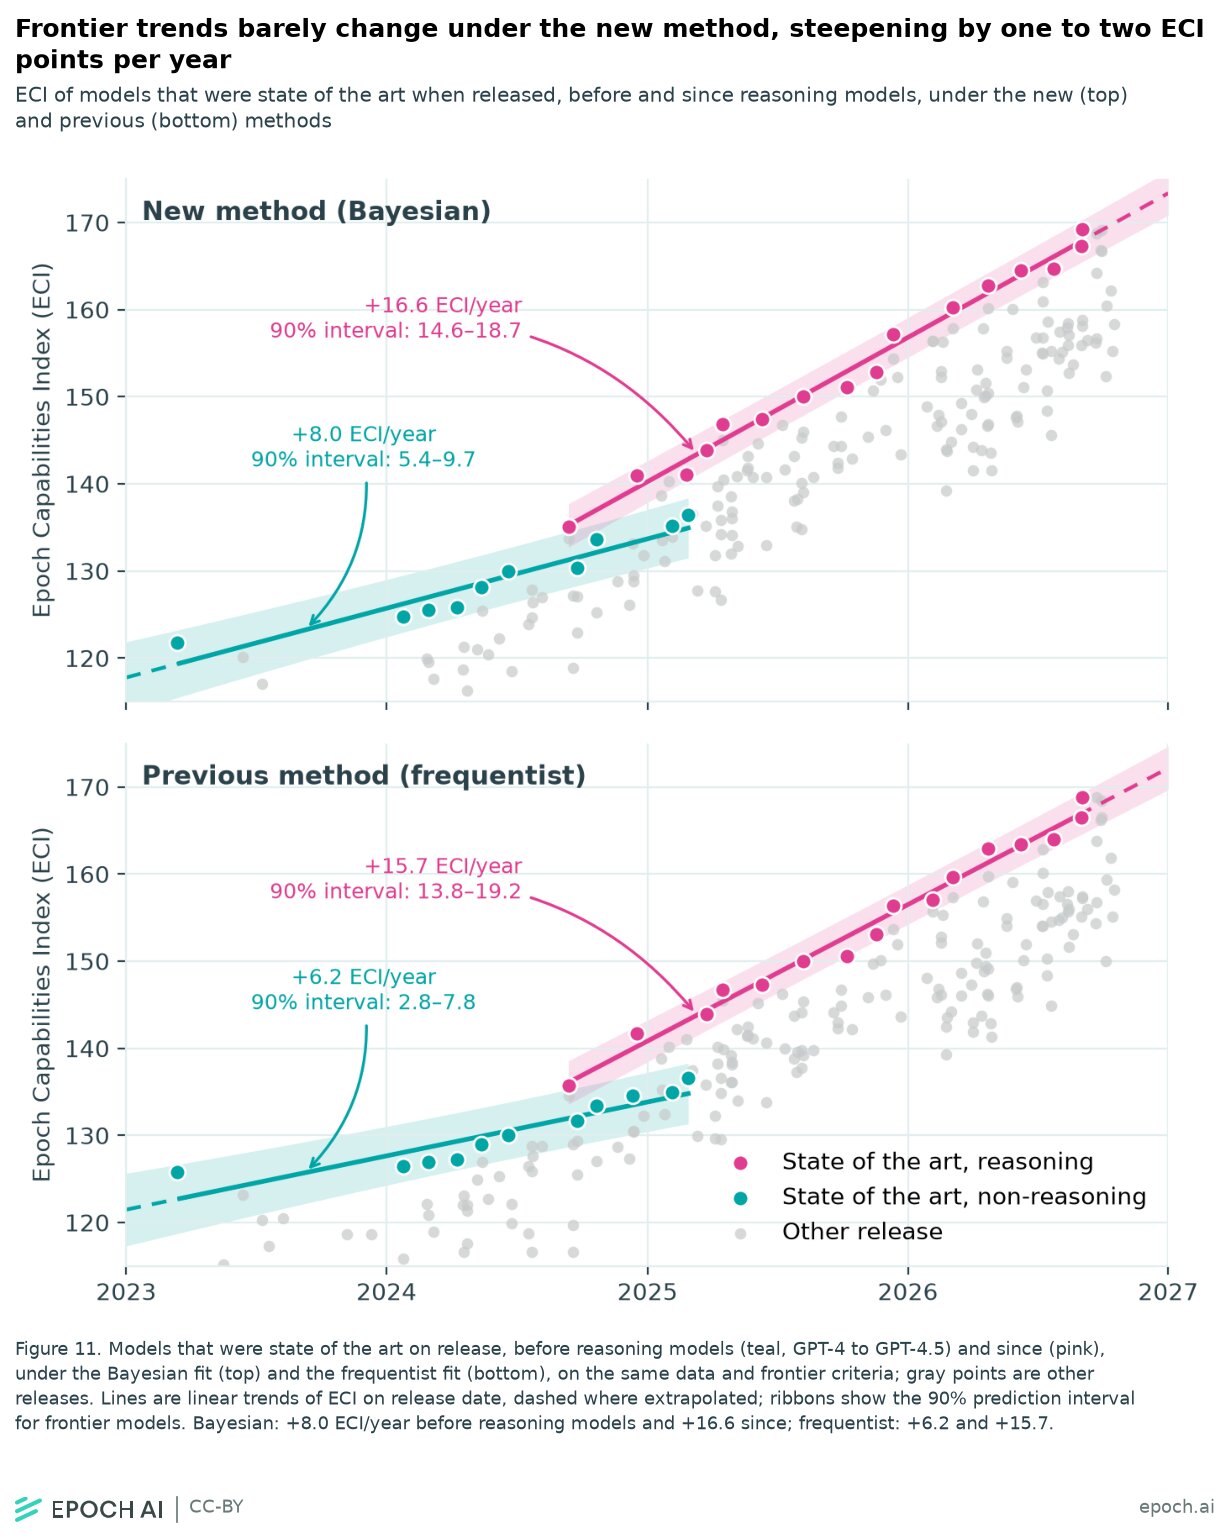
Updating the Epoch Capabilities Index methodology to use a Bayesian model
A Bayesian model gives the ECI better-justified uncertainty estimates and lets us compare models directly.

CWE-bench v2: More coverage, quality, and transparency
Better evaluation of software vulnerabilities helps developers identify and fix security flaws before they reach production.
StateBench: Testing how language models track state changes over long documents
Tracking state across extended text is crucial for real-world applications like document analysis and multi-turn reasoning.