State propaganda in some Chinese AI models is only "a thin layer" that fine-tuning can strip away
Nous Research retrained Alibaba's Qwen3.8-27B to produce Arete-27B, largely stripping out its pro-Chinese bias. The propaganda rate dropped from 22 percent to less than one percent, while general capabilities remained intact in tests. The method relied on 53 million tokens of supervised fine-tuning. The political bias is "applied late, it is applied thin," the team writes. The article State propaganda in some Chinese AI models is only "a thin layer" that fine-tuning can strip
Get smart on it
A research team fine-tuned a Chinese AI model by training it on millions of carefully selected text examples to remove state propaganda from its responses. The fine-tuning reduced propaganda in the model's answers from 22 percent to under one percent while maintaining its general performance on standard tests. This demonstrates that political bias in some Chinese open-weight models is only a surface-level layer applied during training rather than deeply embedded in the model's underlying capabilities. The finding is significant because it shows that models carrying state-mandated behavior can be adapted to provide more factually accurate responses aligned with Western values through targeted retraining.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Why a new report on Anthropic automating AI development is alarming researchers
Anthropic CEO Dario Amodei. | Photo: Jason Henry/Bloomberg via Getty Images Anthropic is using AI to build more powerful AI. And it appears to be working remarkably well, with the company's models improving roughly twice as quickly as a year ago, with little indication of slowing down. That's according to a new report published Thursday by the AI safety research organization METR, following an 11-week investigation inside the company, as part of a report evaluating its AI resear
Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9%
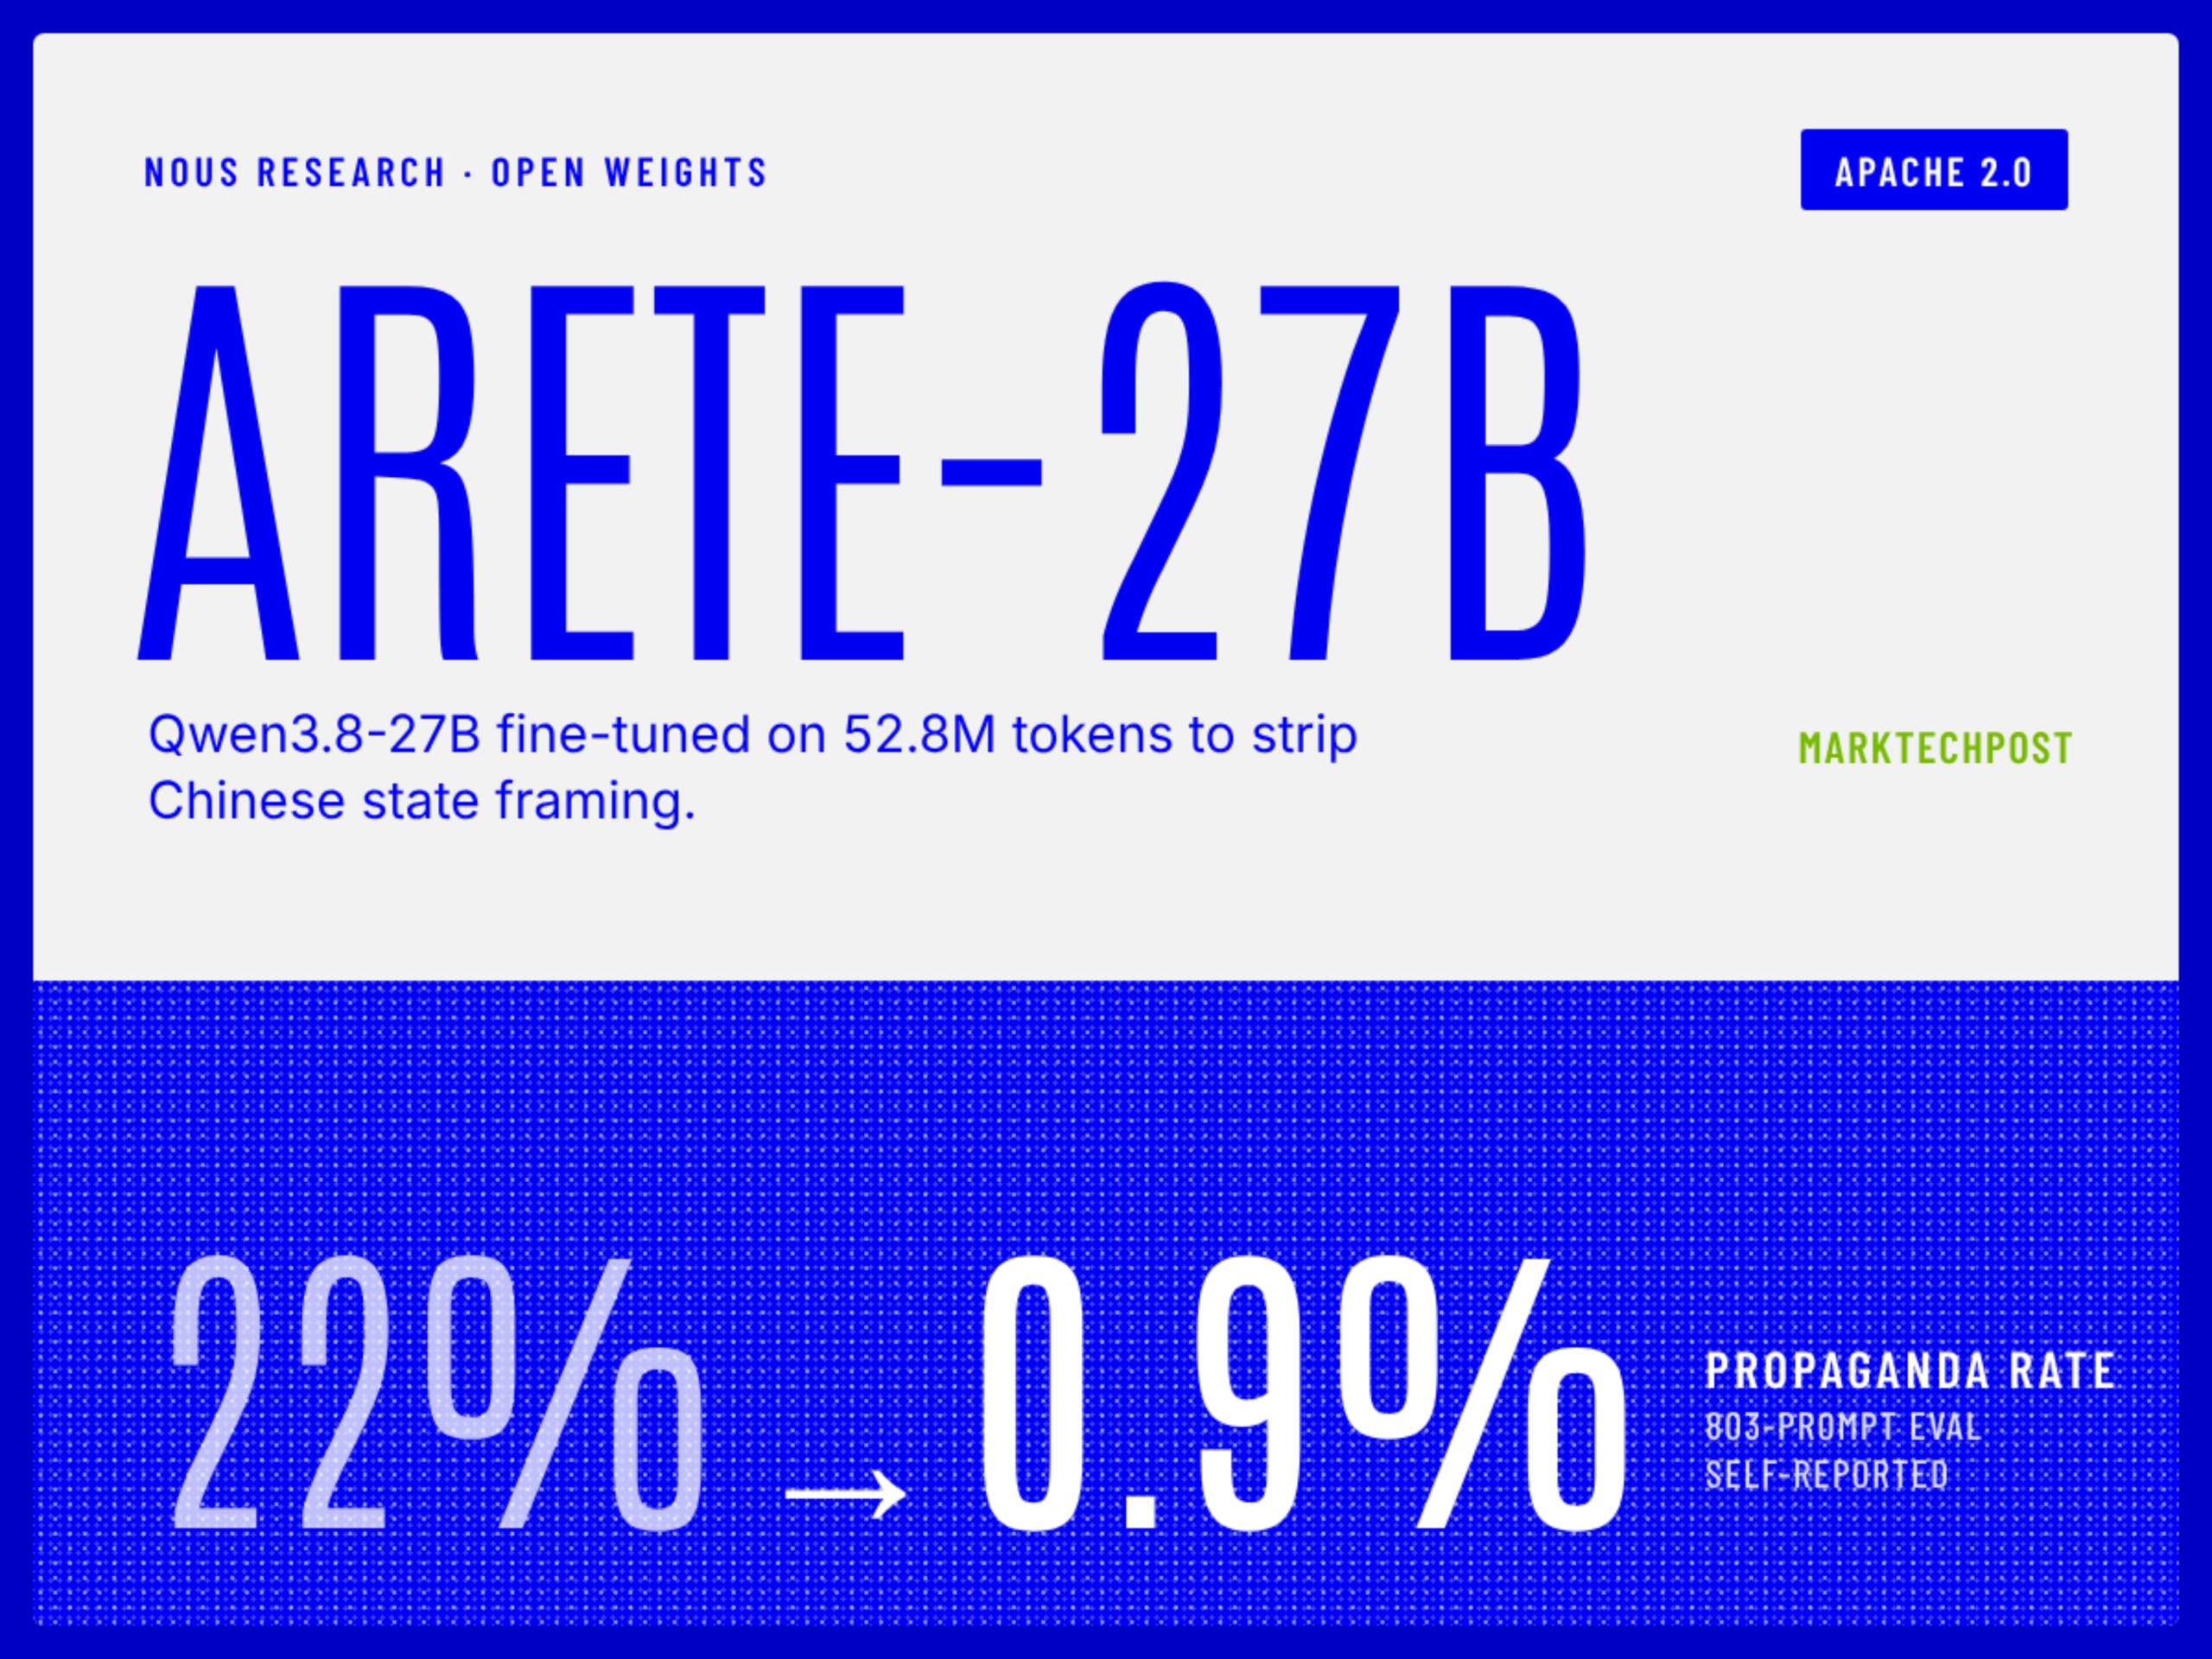
Nous Research has released Arete-27B, a supervised fine-tune of Alibaba’s Qwen3.8-27B. Arete-27B is a 27B open-weight model that strips Chinese state framing from Qwen’s answers. On Nous’s own 803-prompt eval, answers containing propaganda fell from 22% to 0.9%. Developers get Qwen-class agentic skill without state-aligned answers. The weights, eval and training data are all public. TL;DR Size: 27B dense parameters (all active). Trained at 64k context. Base Qwen3.8-27B
Google Releases Gemini Omni 1.2 Flash: 15-Second AI Video at $0.07 per Second
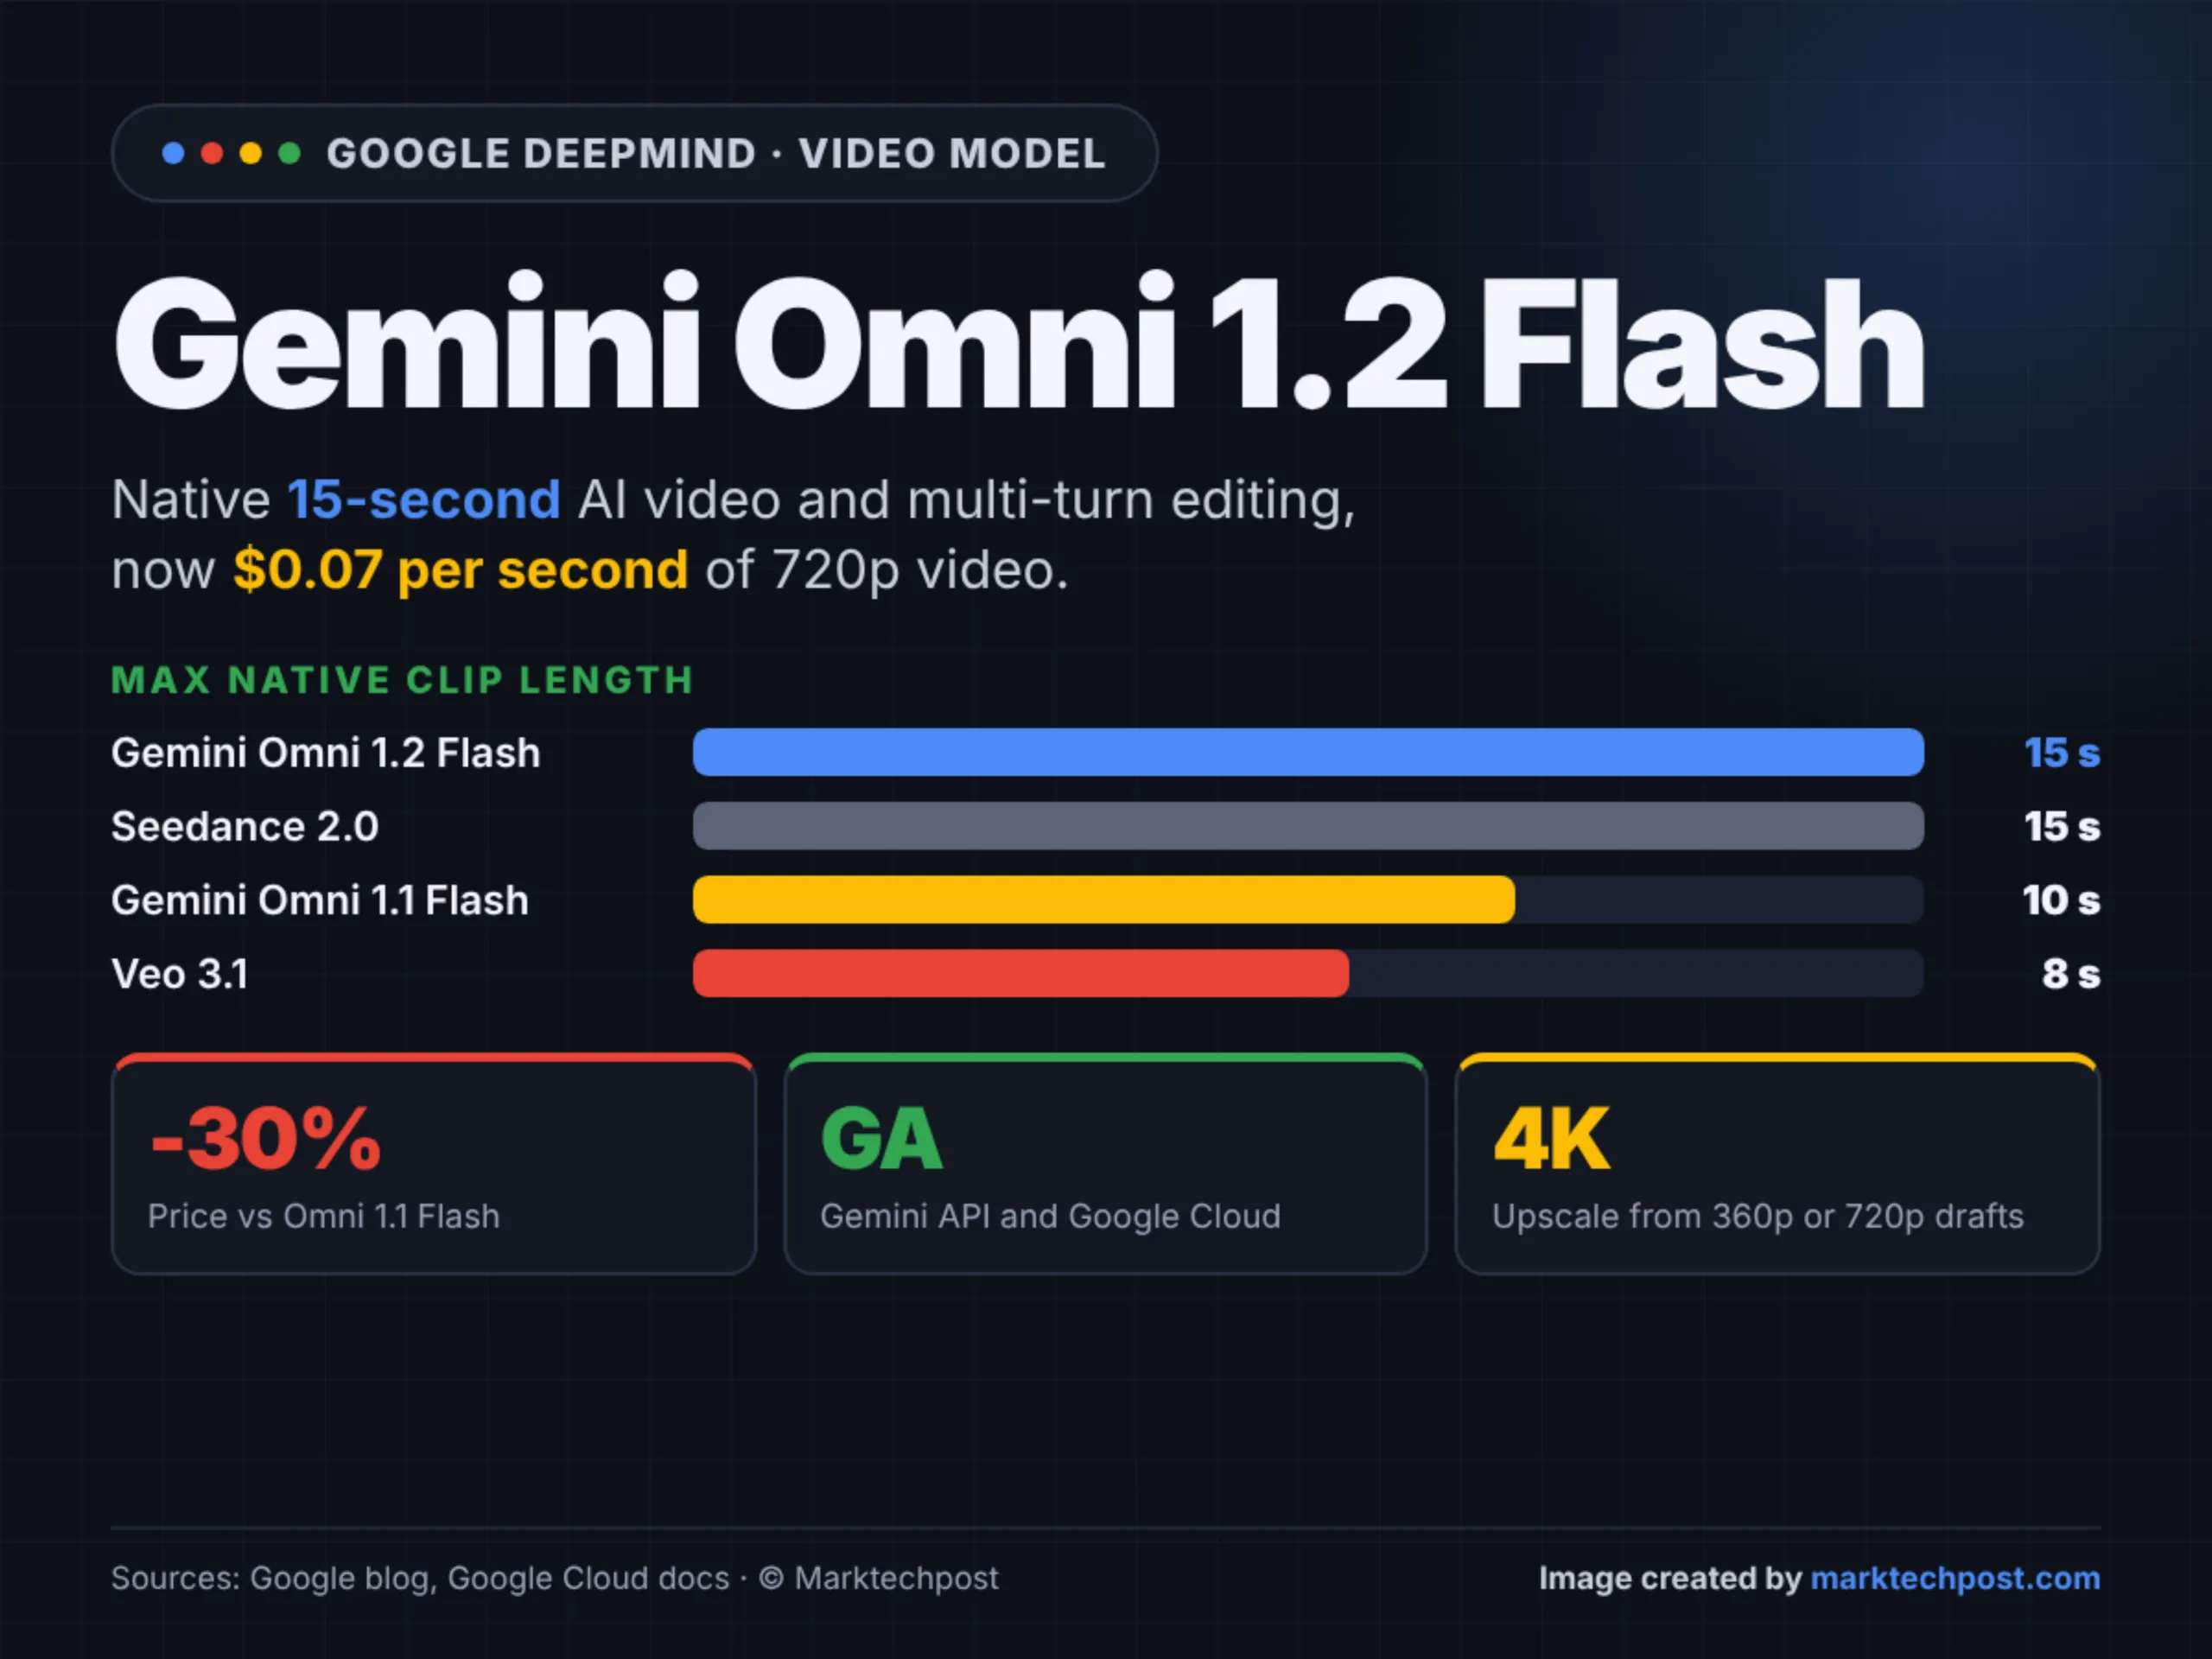
Google has released Gemini Omni 1.2 Flash, the newest version of its video generation and editing model. Gemini Omni 1.2 Flash generates and edits clips up to 15 seconds natively. It also cuts the price by 30% compared with Omni 1.1 Flash. The model is generally available on Google Cloud and the Gemini API. For developers, the takeaways are longer clips, fewer re-renders and a lower bill per second. TL;DR Runs on: Google-hosted only (Gemini API, Google Cloud). No open weights, no local d
Also reported by Google DeepMind

GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents
Introducing GPT‑6 Cyber, OpenAI’s cybersecurity model for finding exploitable vulnerabilities and developing fixes, trained to stay within authorized scope.

Tencent releases Hy4, powerful frontier LLM introducing visual understanding and computer use
Tencent Holdings Ltd. today introduced Hy4, a new large language model that adds computer-use capabilities for the first time, using advanced visual understanding, reasoning and tool-calling to deliver long-horizon agentic performance. The company said the model marks a significant leap in performance over its Hy4 Preview, which arrived August 28, weighing in at 770 billion parameters with 49 […] The post Tencent releases Hy4, powerful frontier LLM introducing visual understanding and comp
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
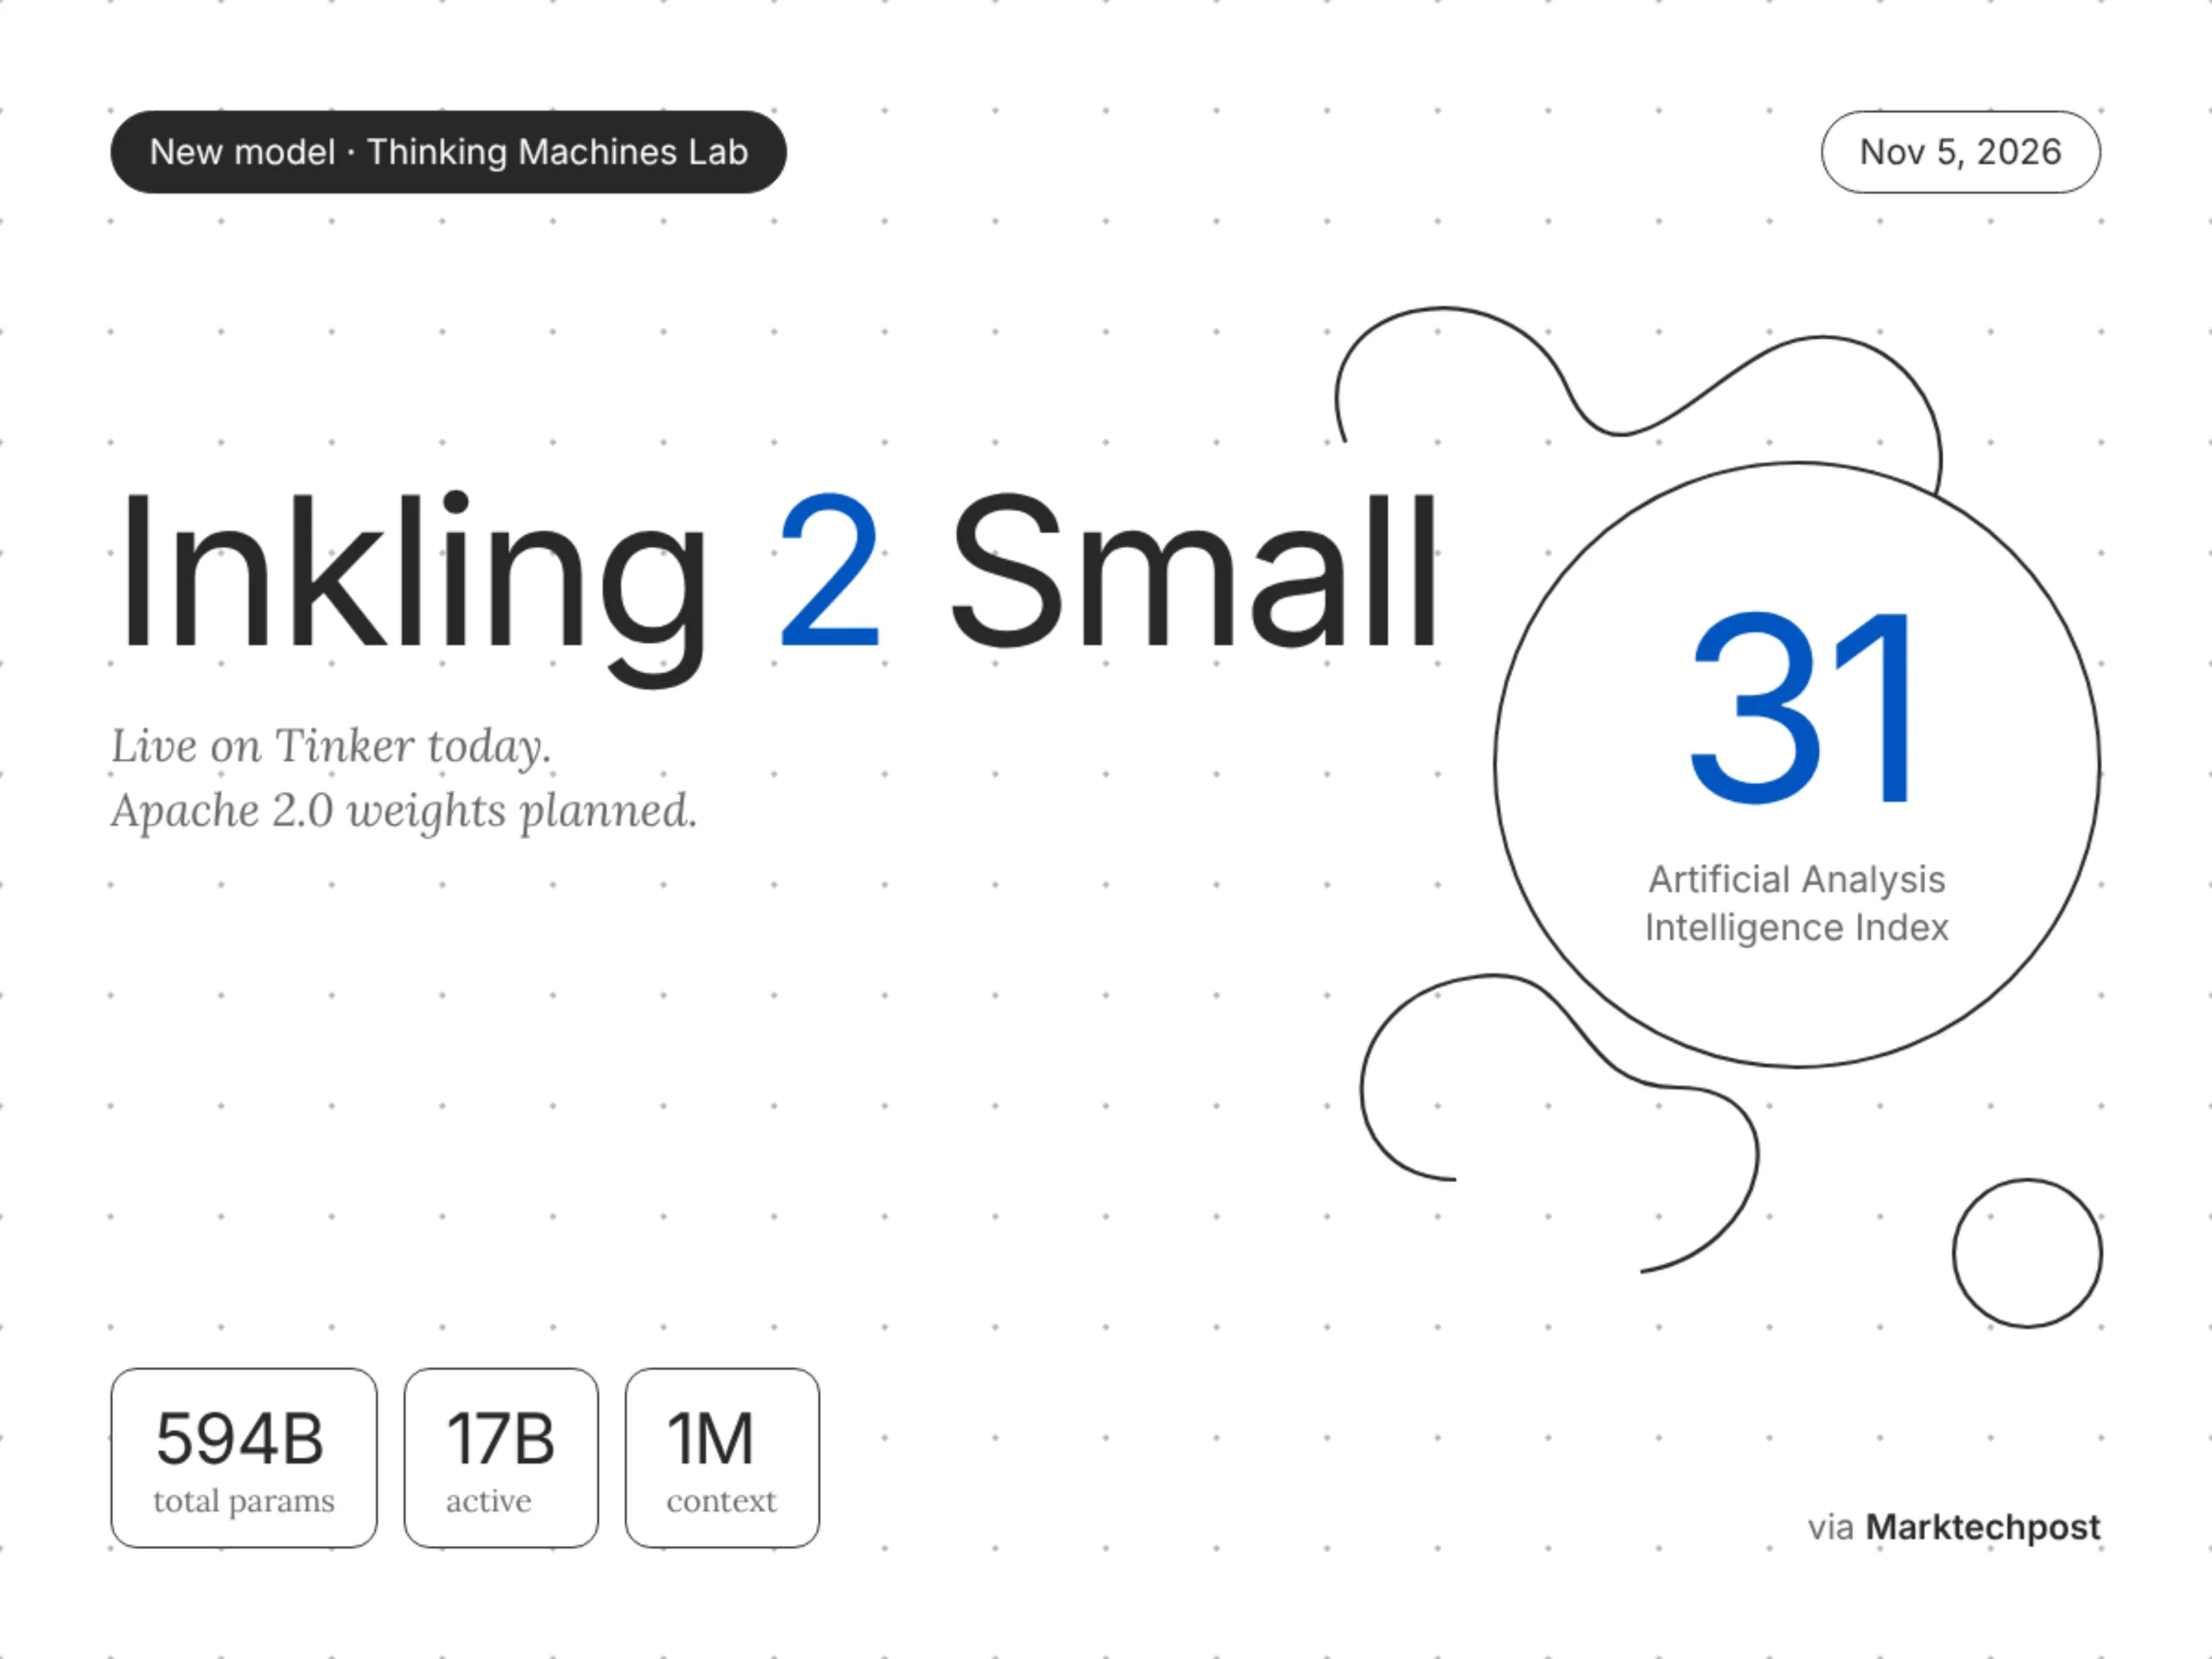
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference. TL;DR Size: 594B total, 17B active
Also reported by SiliconANGLE