NVIDIA releases optimized recipes for Korean AI models
NVIDIA Blog: NVIDIA Dynamo Recipes Bring Korea’s Leading Open Models to Production
NVIDIA is releasing Dynamo-optimized deployment recipes for Korea’s leading open models: A.X K2 from SK Telecom, K-EXAONE 2.0 from LG AI Research, Solar Open 2 from Upstage and Motif-3 from Motif Technologies. As models grow beyond the capacity of a single GPU, they must be split across multiple GPUs, requiring careful coordination of request routing and communication to maintain performance. NVIDIA Dynamo is an open source, distributed inference-serving framework built to deploy models in mult
Get smart on it
NVIDIA is releasing optimized deployment recipes for several Korean open-source AI models to help them run on multiple GPUs in data center environments. When AI models become too large for a single GPU, they must be distributed across multiple GPUs, which requires specialized software to manage request routing and communication. NVIDIA Dynamo is an open source framework designed to handle this distribution and maximize inference performance, and these new recipes are optimized for NVIDIA B200 GPUs to deliver up to 2x performance improvement out of the box. The recipes aim to make it faster and easier for developers to bring these Korean models into production as widely accessible AI services.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Anthropic releases new Mythos and Fable models amid RSI concerns
Anthropic says the new models "show improvements in areas like coding, reasoning, and vision," as well as in communicating more clearly with users.
Also reported by The Verge

Meta releases Muse Ember, a new lightweight model for agent execution
At 10 cents per million input tokens, Ember is significantly cheaper than frontier competitors like Haiku and Luna.
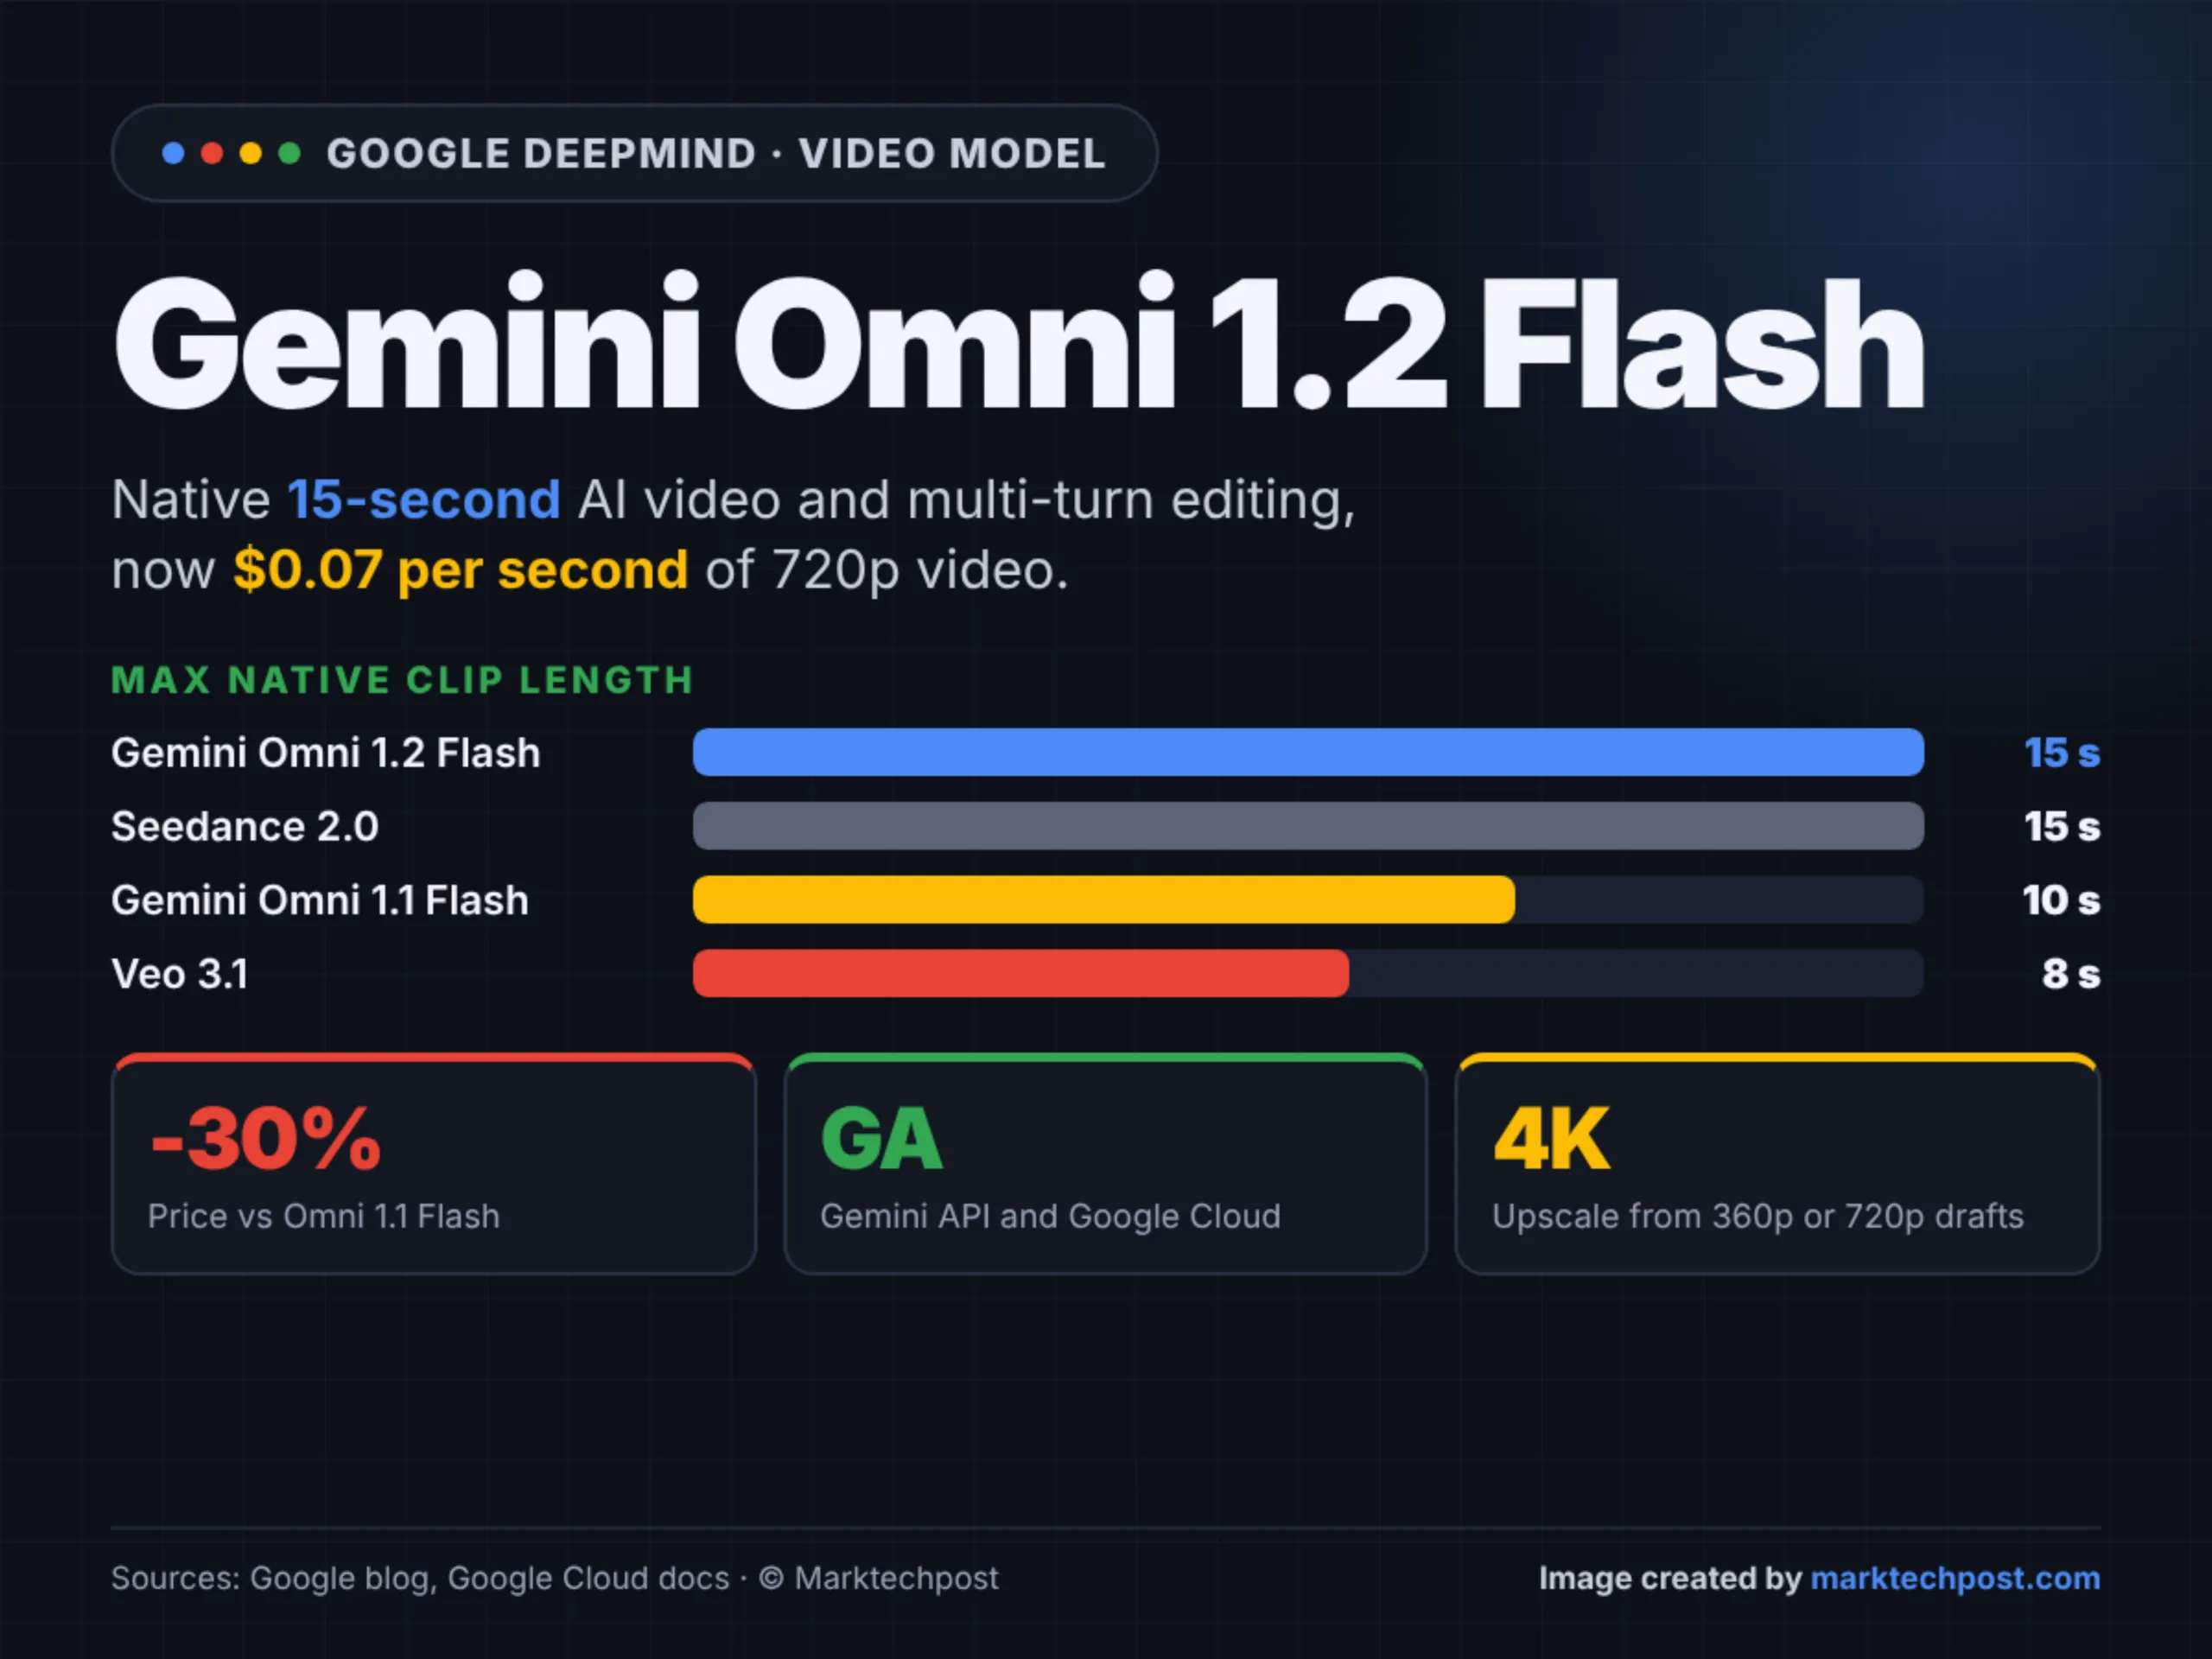
Google Releases Gemini Omni 1.2 Flash: 15-Second AI Video at $0.07 per Second
Google has released Gemini Omni 1.2 Flash, the newest version of its video generation and editing model. Gemini Omni 1.2 Flash generates and edits clips up to 15 seconds natively. It also cuts the price by 30% compared with Omni 1.1 Flash. The model is generally available on Google Cloud and the Gemini API. For developers, the takeaways are longer clips, fewer re-renders and a lower bill per second. TL;DR Runs on: Google-hosted only (Gemini API, Google Cloud). No open weights, no local d
Also reported by Google DeepMind

Why a new report on Anthropic automating AI development is alarming researchers
Anthropic CEO Dario Amodei. | Photo: Jason Henry/Bloomberg via Getty Images Anthropic is using AI to build more powerful AI. And it appears to be working remarkably well, with the company's models improving roughly twice as quickly as a year ago, with little indication of slowing down. That's according to a new report published Thursday by the AI safety research organization METR, following an 11-week investigation inside the company, as part of a report evaluating its AI resear

Reason Machines Open-Sources Aspen, a Git Server Built for AI Agents
Reason Machines has released Aspen, an open-source Git server for AI agent traffic. It targets repositories that hundreds of agents push to at once. Aspen independently implements the design OpenAI described for Pando. TL;DR Size: One Rust binary. Branches live in PostgreSQL (or SQLite), packs live in object storage. Runs on: A laptop (aspen dev), one host via Docker Compose, or Helm and Terraform clouds. Performance: Pushes to different branches never wait on each other, and fetc

GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents
Introducing GPT‑6 Cyber, OpenAI’s cybersecurity model for finding exploitable vulnerabilities and developing fixes, trained to stay within authorized scope.