Liquid AI launches RIPL inference engine for faster responses
MarkTechPost: Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs
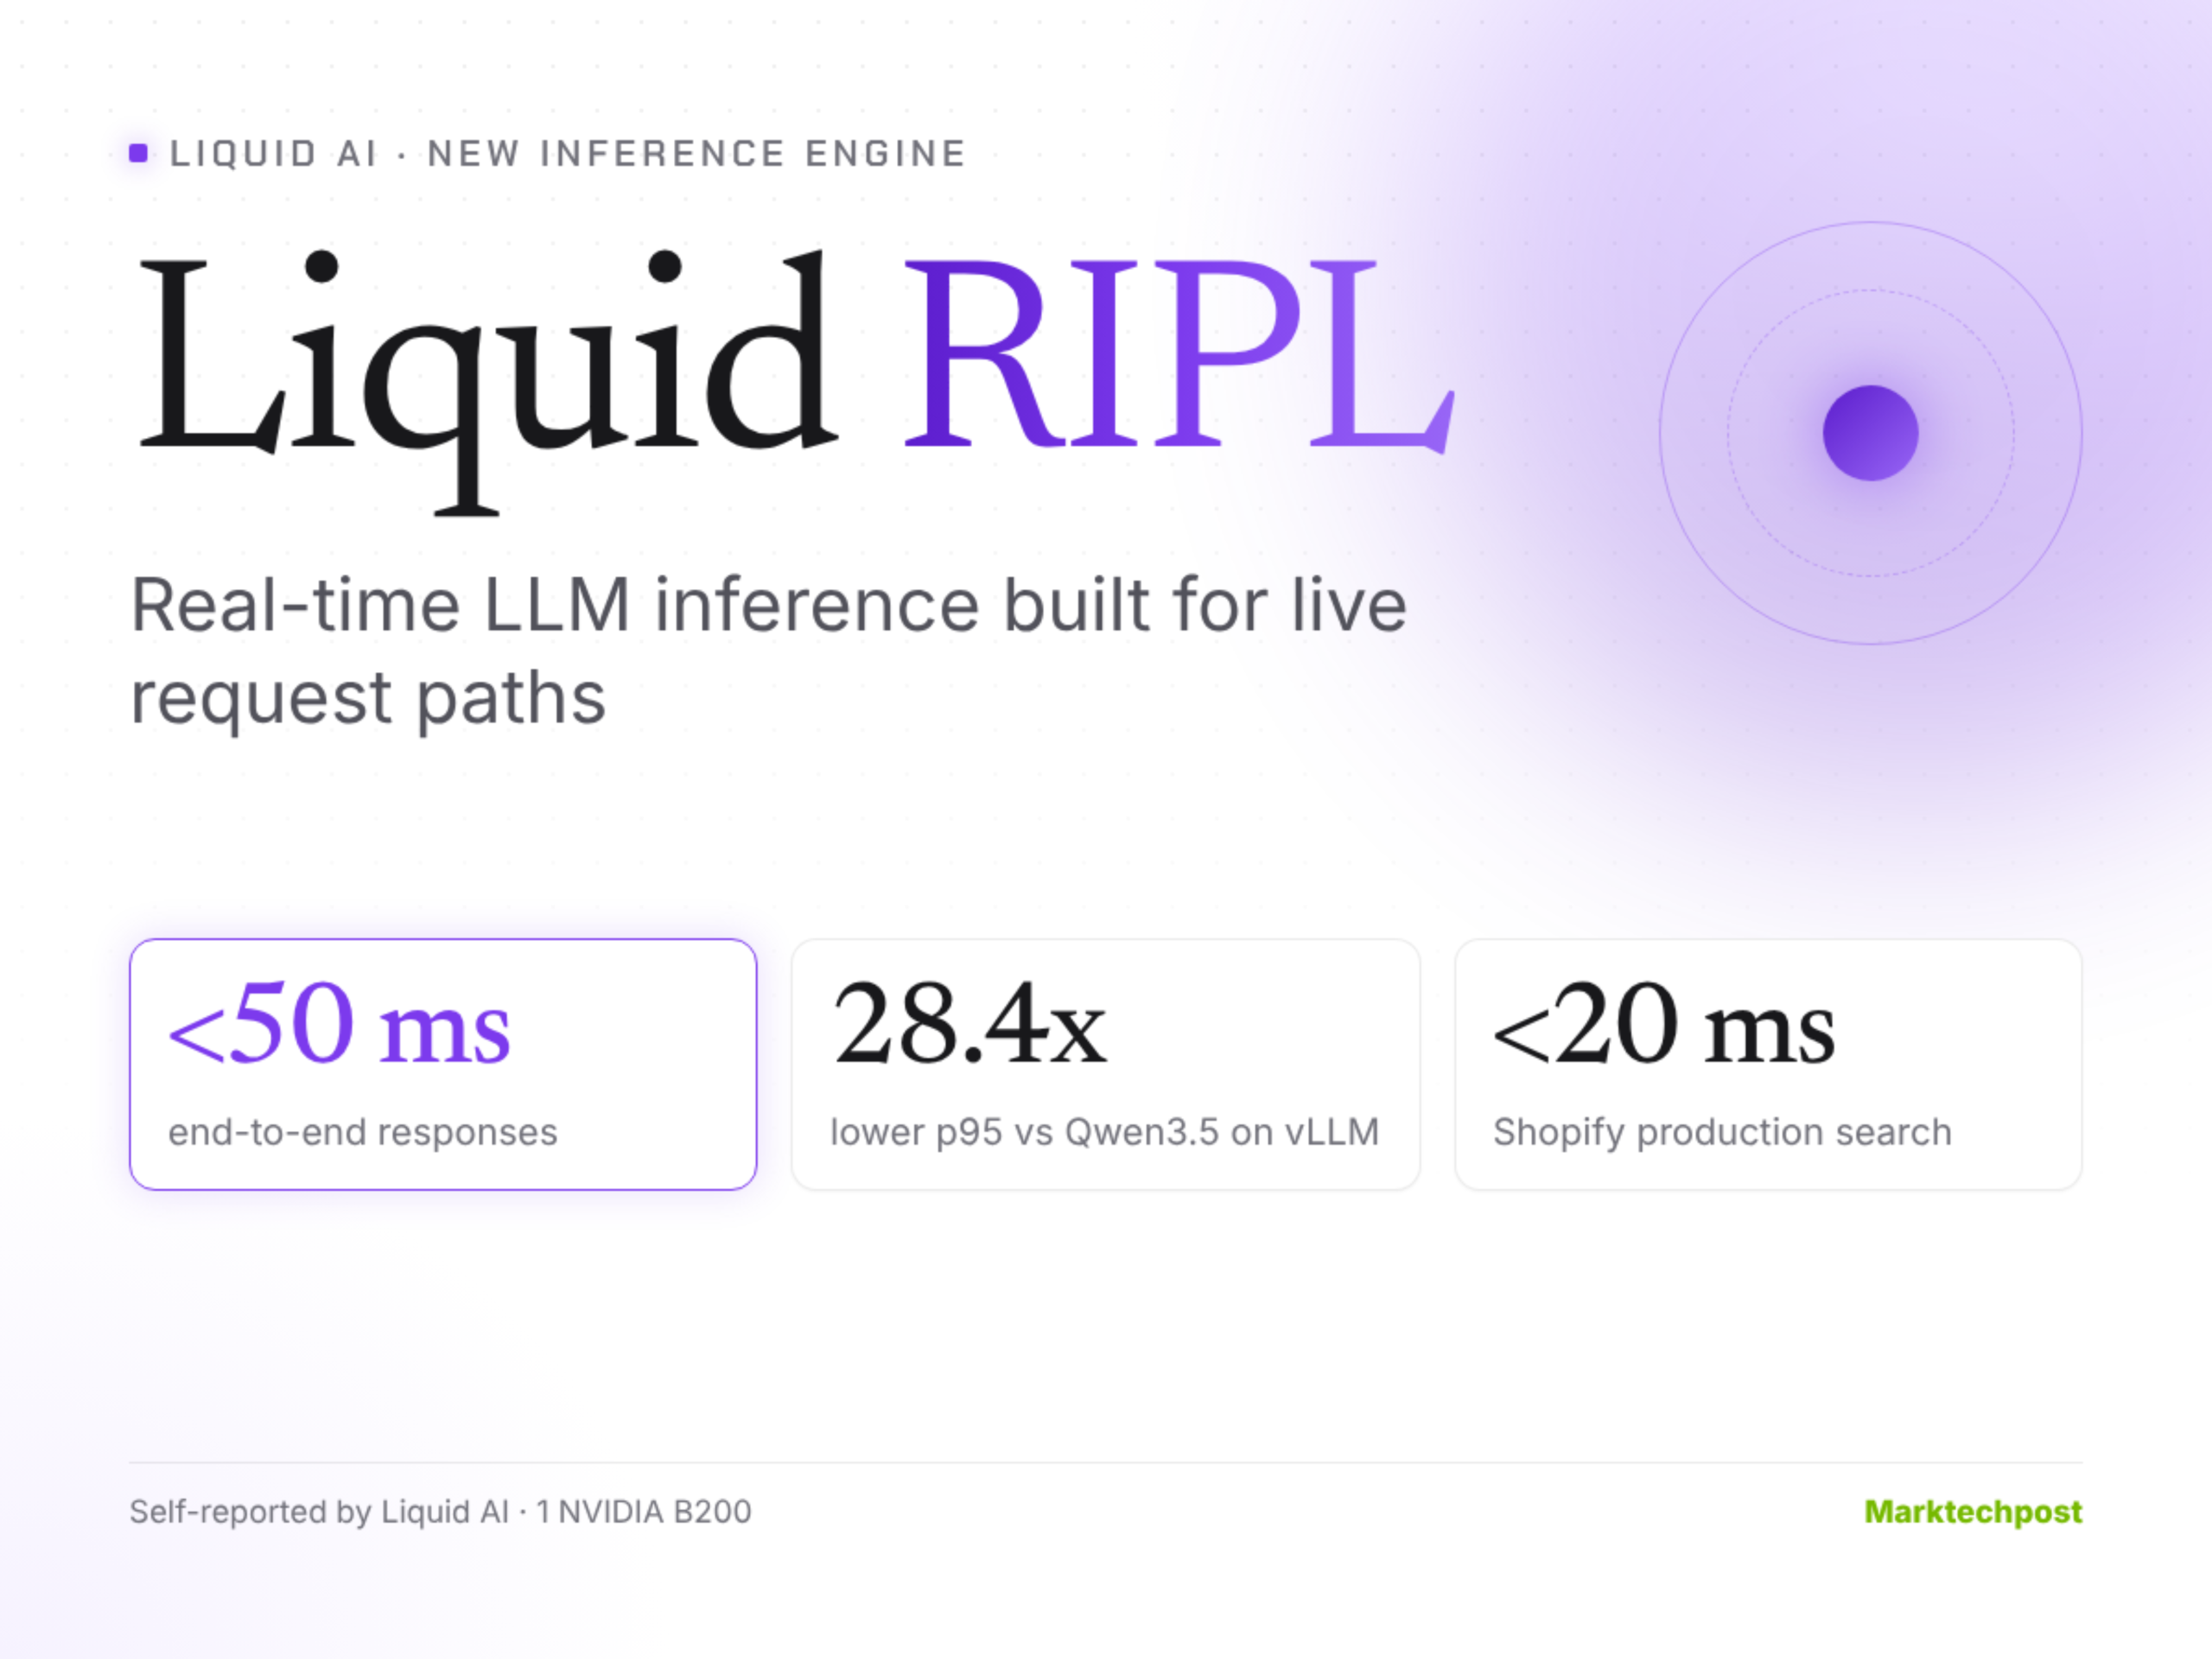
Liquid AI just announced Liquid RIPL, short for Real-time Inference Pipeline. RIPL is a low-latency engine that serves Liquid Foundation Models (LFMs) inside a live request path. It returns complete generated responses end-to-end in under 50 ms. It also claims that latency holds while traffic arrives continuously at peak load. For developers, the message is simple. Swap gradient-boosted trees for a generative model, and keep the latency budget. TL;DR Engine: Serves LFM2.5 models from 230
Get smart on it
Liquid AI launched RIPL, a real-time inference engine that serves language foundation models and returns complete responses in under 50 milliseconds. Most AI serving systems are designed for large batches and longer processing times, but applications like search ranking, fraud checks, and payment authorization require millisecond-speed answers, creating demand for faster inference. According to Liquid AI's benchmarks, RIPL achieves 5.6 to 28.4 times lower latency compared to vLLM when serving similar-sized models, with performance holding steady during continuous peak traffic. The engine is currently enterprise-only and has been deployed in production by at least one major company for latency-sensitive workloads.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time
Mistral AI launched Voxtral 3, a new family of language models built for real-time voice agents. The system combines speech-to-text, text-to-speech, and a voice agent SDK, supports more than 50 languages, and lets agents tap into external tools during live conversations. It can run on your own infrastructure or through EU-hosted APIs to keep data under your control. The article Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time appeared
Also reported by MarkTechPost

Ai2 releases OlmoEarth v1.3 state-of-the-art AI-ready satellite embeddings for the whole planet
Ai2, the Allen Institute for Artificial Intelligence, today released a satellite map embedding model called OlmoEarth v1.3 and precomputed annual embeddings for the whole planet at various resolutions with a browser-based map-making tool. The model compresses a year of satellite observations into a numerical fingerprint for each 10-by-10-meter patch of ground at the smallest resolution, […] The post Ai2 releases OlmoEarth v1.3 state-of-the-art AI-ready satellite embeddings for the whole pl
Also reported by Hugging Face

Recursive launches Flint, a laptop coding model it says was largely built by AI
Startup Recursive has released Flint, a free, laptop-sized coding model built largely by its own AI research system, as an early test of AI that improves itself.
Also reported by Wired AI and MarkTechPost

Beyond tree cover: mapping the world’s forest types
A global map categorizing every 10-meter patch of land on Earth into distinct forest types.
Voxtral 3
Voxtral 3: Mistral's voice agent SDK for real-time speech in 50+ languages — accurate transcription, emotional TTS, deep tool use. EU-hosted or self-deployed.
Hugging Face’s New AI Biology Model Lets You Chat With DNA
The new open-source model speaks the language of DNA and can help researchers understand the effects of any changes on gene activity and health.