Block releases Dessa speech model
MarkTechPost: Block Unveils Dessa, a Full-Duplex Speech Model Trained Only on Speech
Block’s AI research lab has released Dessa, a full-duplex speech model trained only on human conversation. Block announced it on October 23, 2026 as a research preview. Dessa is a speech-to-speech model from Block that listens and talks at the same time. Block says it used no text and no pretrained models. That is a different design from the text-first stacks behind most voice agents today. TL;DR Runs on: A MacBook Pro M4 Max or better, locally, faster than real time. Performan
Get smart on it
Block's AI research lab released Dessa, a speech-to-speech model that listens and talks simultaneously without using text or pretrained models, trained only on human conversation audio. Unlike most voice systems that chain speech recognition, text processing, and speech synthesis together, Dessa processes audio directly, which the lab argues preserves emotional nuances like laughter, sarcasm, and sighs that get lost in text-based pipelines. The model runs locally on a MacBook Pro M4 Max faster than real time and was trained on a single rack of 72 GPUs, though Block has not published benchmark scores, model weights, or detailed architecture details, making it difficult to assess its actual performance compared to alternatives like Moshi.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Gemini 4 Carbon: Our next frontier model
Google's latest offering suggests the company is prioritizing efficiency and environmental impact alongside raw capability gains.
Also reported by Ars Technica, MarkTechPost, The Verge and The Decoder
Introducing GPT-6.1 Terra
Bringing fast and capable computer use to everyone
Also reported by SiliconANGLE, MarkTechPost and The Decoder

Genie 4: A new generation of world simulation
Genie 4: our new world model unlocking unprecedented realism in real-time simulation.
Also reported by TechCrunch, Ars Technica, SiliconANGLE and MarkTechPost
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Customizable transcription tools could help organizations reduce manual annotation costs while handling multiple languages simultaneously.
Also reported by TechCrunch, SiliconANGLE, The Decoder and MarkTechPost

Google’s next Genie AI model generates more realistic experiences
Google announced today its Genie 4 world model for generating interactive experiences using AI. The company says the model has four main updates: It allows for more realistic worlds, lets users update an experience in real time with a natural language prompt, can generate audio, and uses Gemini 3.8 Flash under the hood to help with its simulations. It also can create experiences that are about two minutes long, up from one minute for the previous Genie 3 model. Google is pitchi
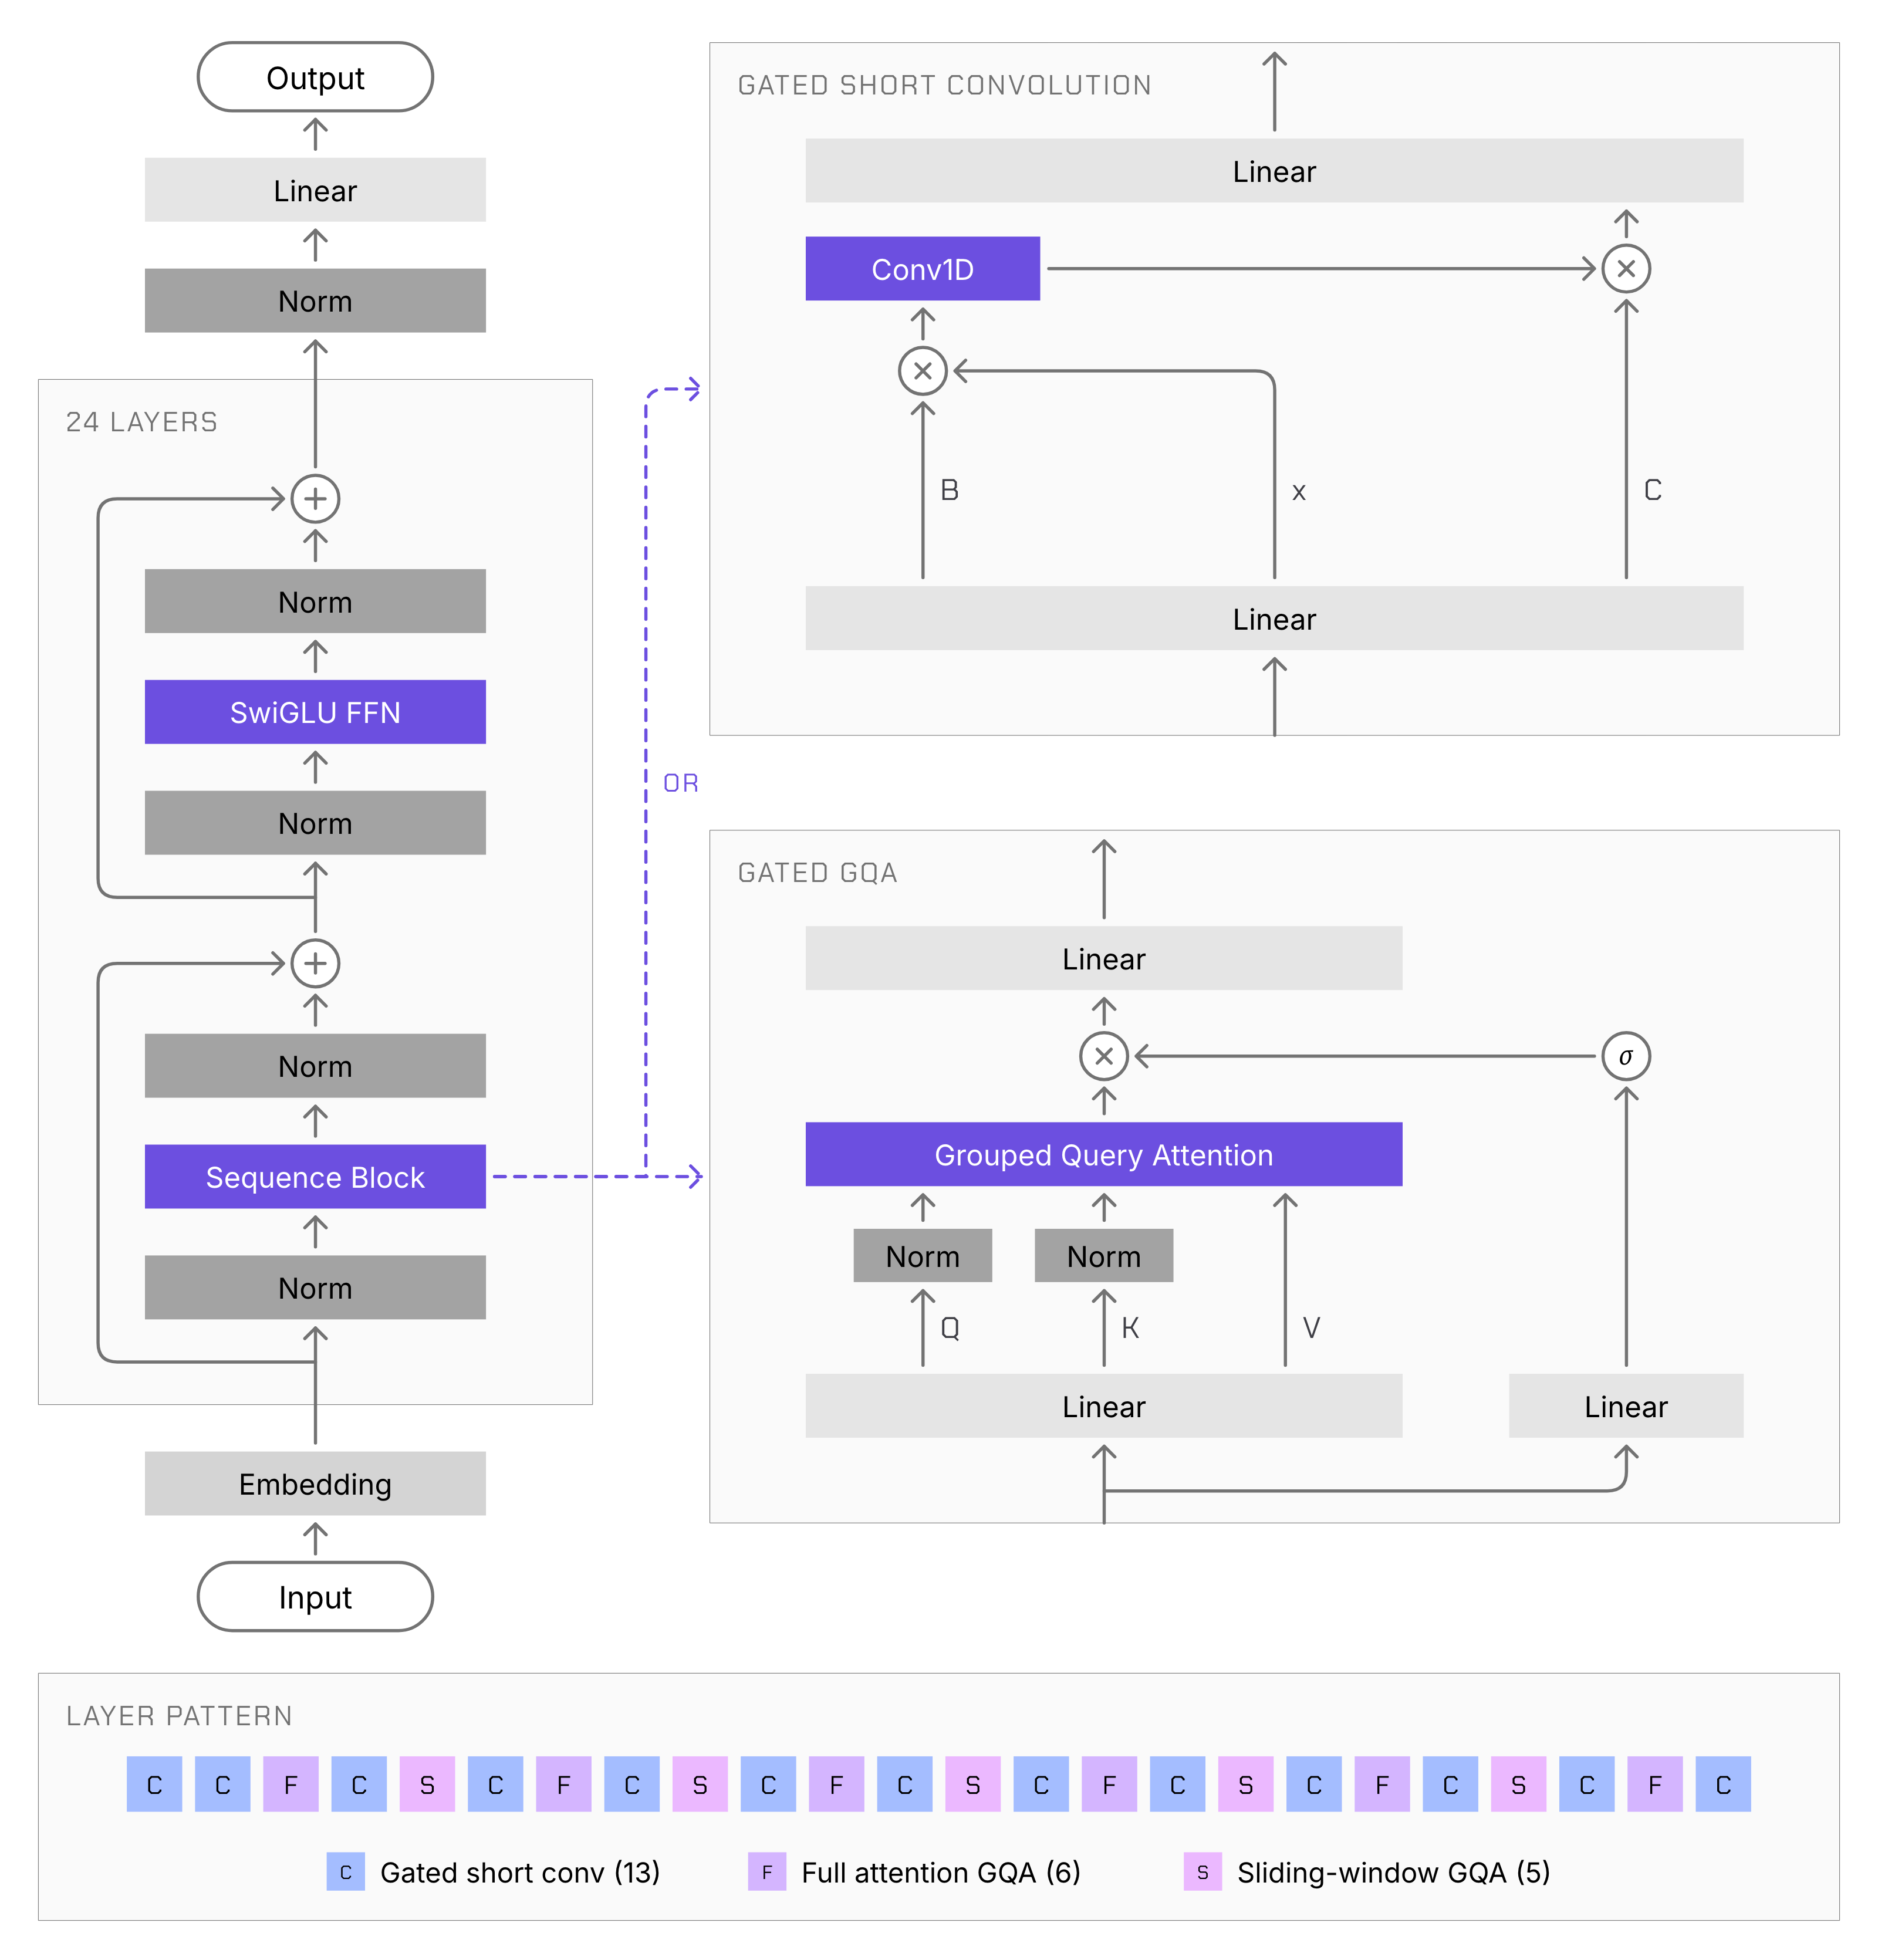
Build specialized multimodal models with LFM3
Organizations can now create custom AI systems combining text, images, and video without building from scratch, lowering barriers to deployment.
Also reported by MarkTechPost