Datalab releases OmniParseBench OCR benchmark
MarkTechPost: Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests to Audit OCR Parsers
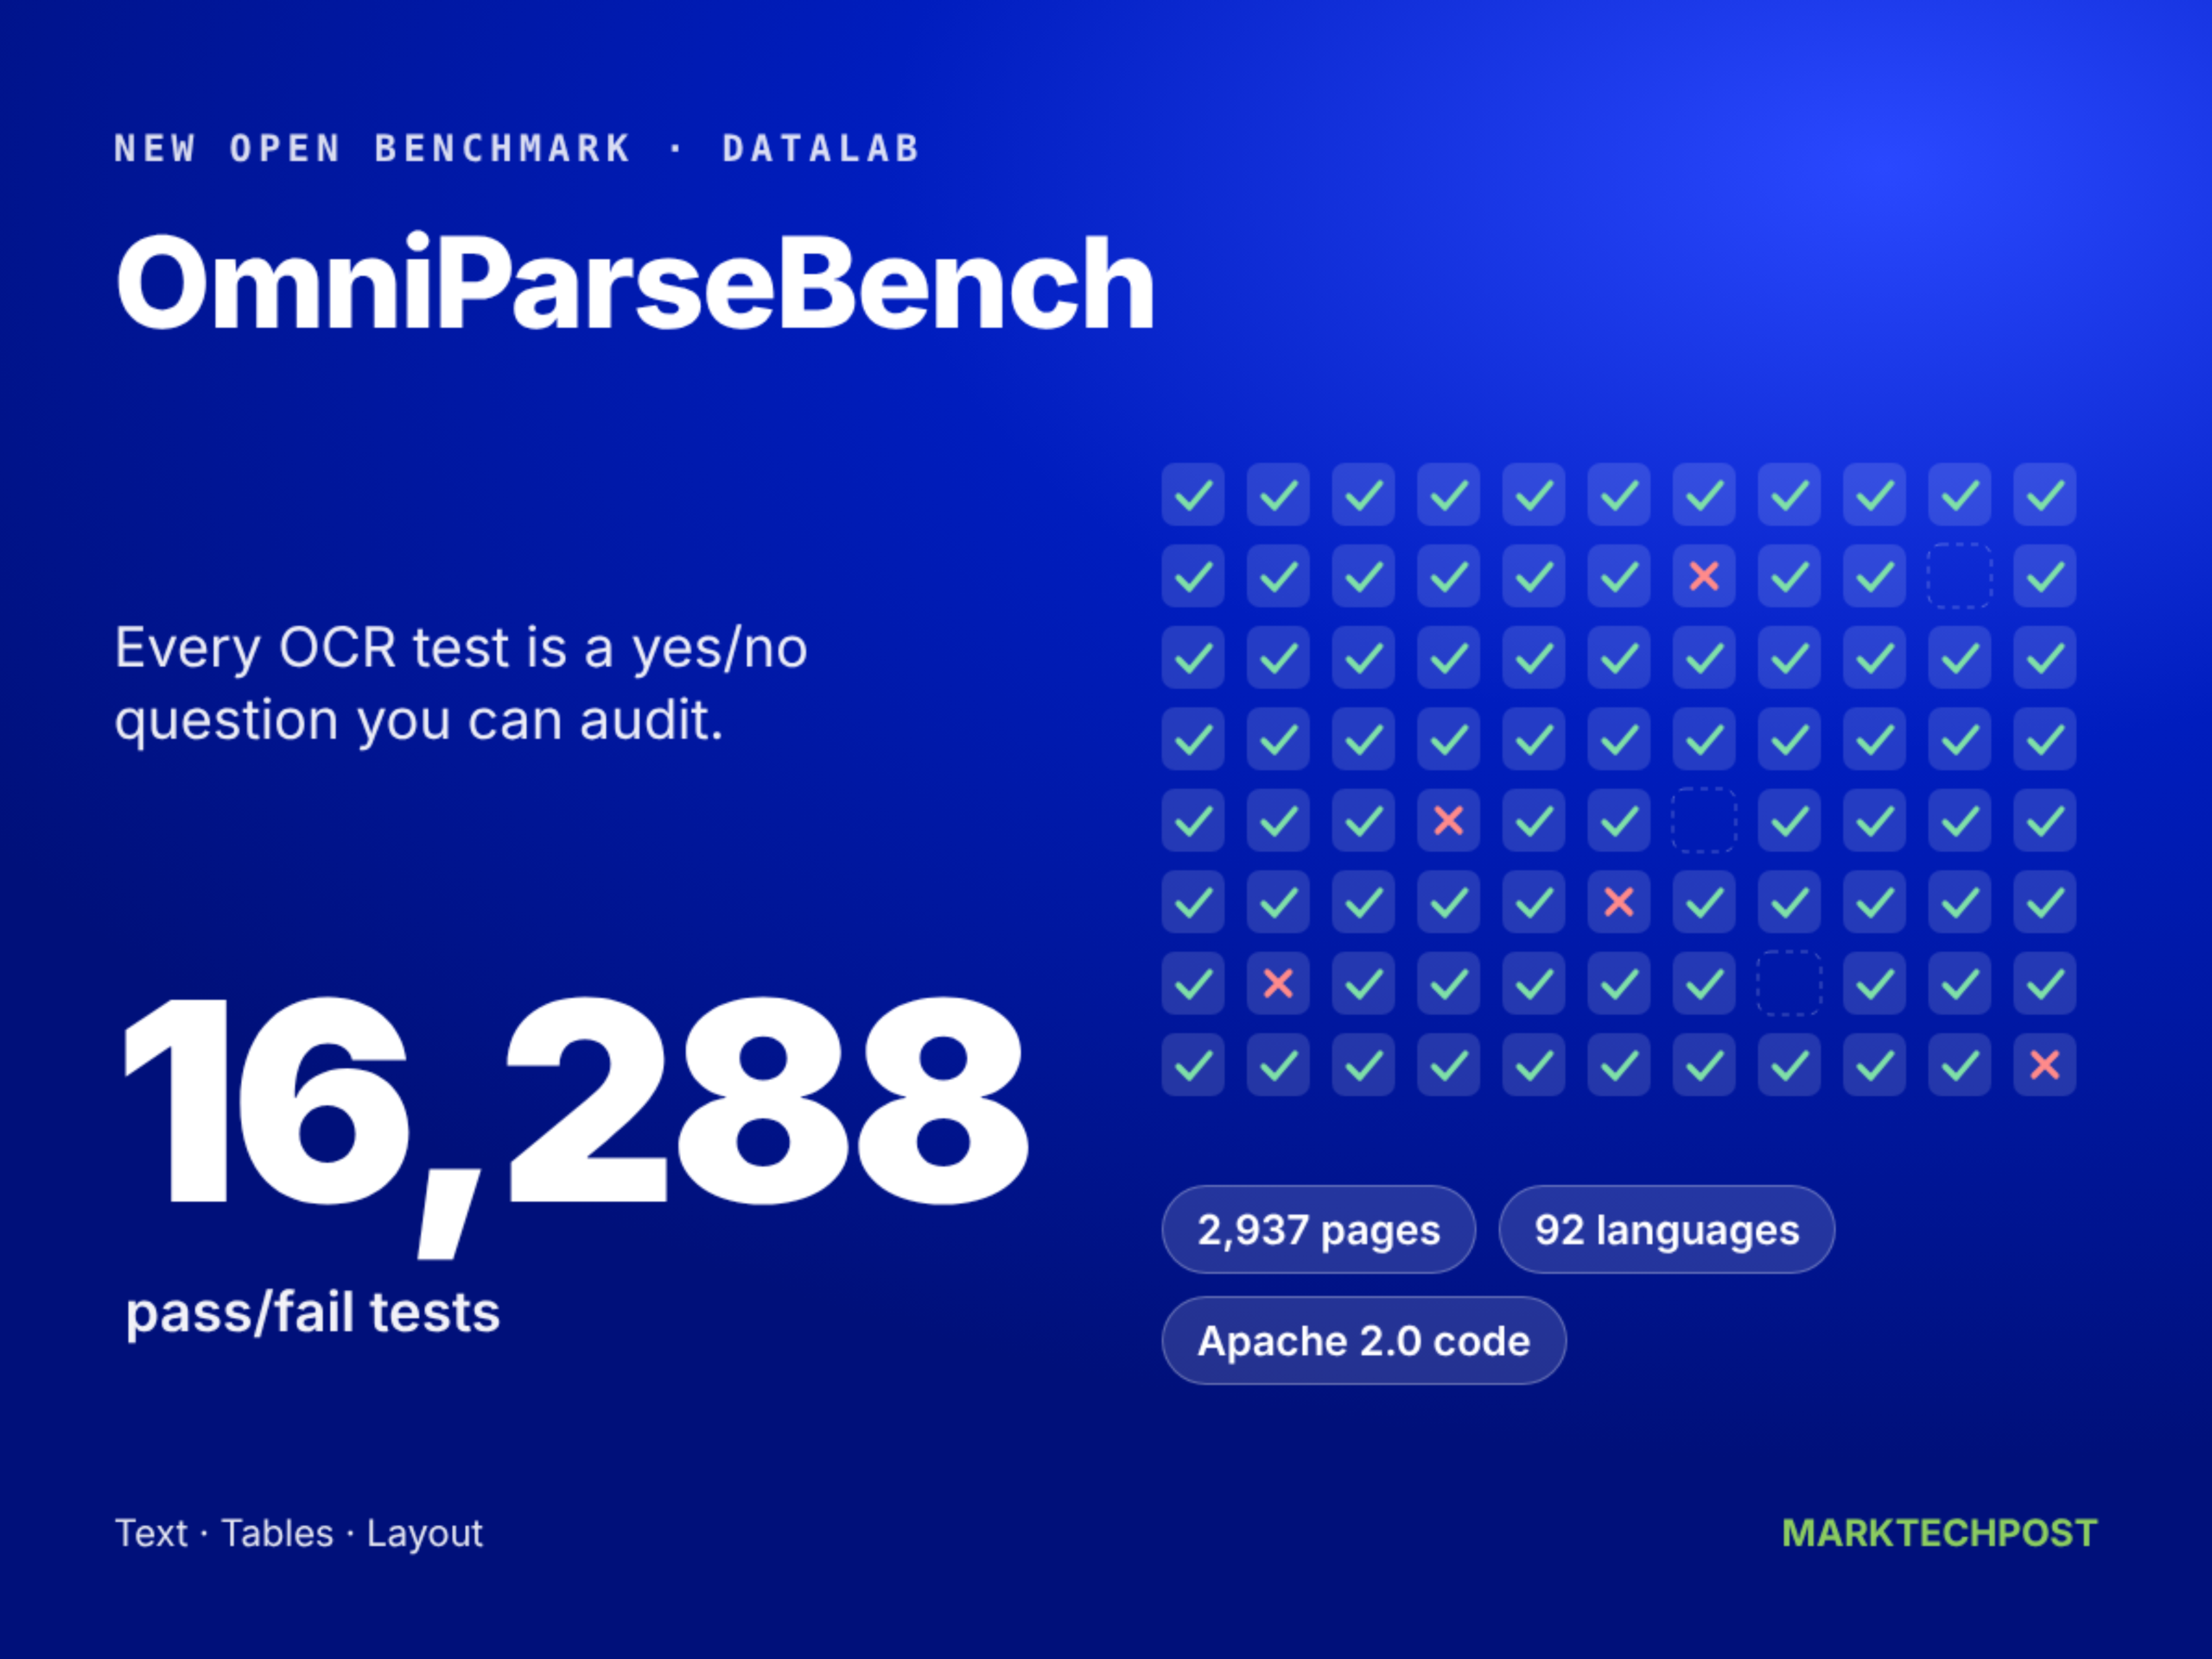
Datalab has released OmniParseBench, an open OCR benchmark for document parsers. It scores parsers with 16,288 yes/no tests on 2,937 pages from 2,343 documents. The pages span 92 languages. The dataset and code are public. It helps engineers answer a sharper question than a leaderboard does: which parser handles documents like mine? Datalab sells a parser, and its own top setting, Datalab accurate, ranks second on the launch leaderboard, behind Gemini 3.8 Flash. Is it deployable? Yes. OmniPa
Get smart on it
OmniParseBench is an open benchmark that tests optical character recognition and document parsing systems using 16,288 yes-or-no questions across thousands of document pages in 92 languages. The benchmark addresses limitations in existing OCR benchmarks by providing clear, auditable pass-or-fail scoring rather than complex metrics that cannot be easily compared, and by allowing results to be filtered by content characteristics like language, structure, and rendering to match specific document types. The evaluation tool runs offline without requiring API keys and does not use models to judge results, making it deployable on any machine with Python 3.11 or later. Results show that top-performing systems are separated by relatively small margins, with Gemini 3.8 Flash leading at 92.9 and Datalab's own parser following at 92.7.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

The AI race is back on
Last week, Anthropic and OpenAI looked like they had the AI race to themselves, pulling ahead with increasingly powerful models that left their rivals in the dust. Google seemed hopelessly far behind, while Meta, despite spending billions to revive its floundering AI ambitions, had yet to establish itself as a serious contender. Even the latest models coming out of China, impressive as they were, appeared to be playing catch-up. Then, in the space of a few days, everything chan

Grok Voice 3.0 from SpaceXSI outscores OpenAI and Google on speech-to-speech index
Elon Musk’s artificial intelligence company SpaceXSI, formerly xAI, today released Grok Voice 3.0, a new version of the speech-to-speech model behind its Voice Agent API. SpaceXSI is pitching the model to businesses that handle customer support and sales calls with voice agents. Independent testing firm Artificial Analysis ranks it first among models of its type. Artificial […] The post Grok Voice 3.0 from SpaceXSI outscores OpenAI and Google on speech-to-speech index appeared first
How well can AI play Slay the Spire?
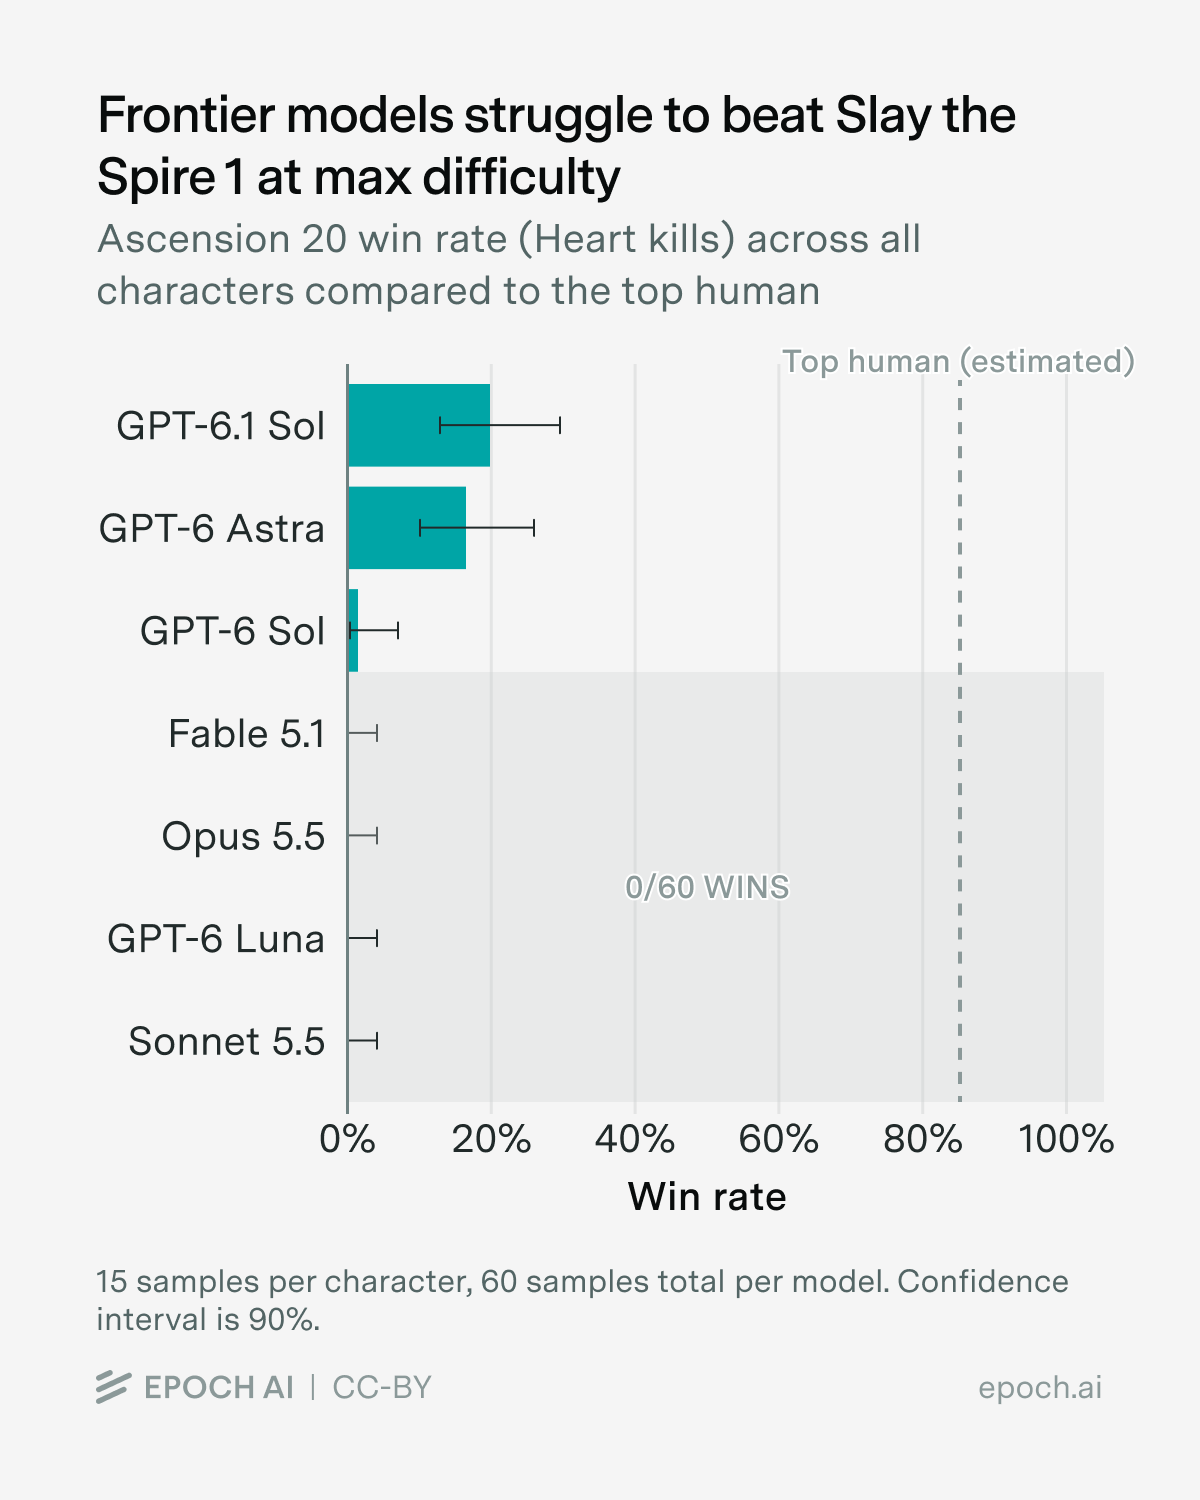
Months ago, frontier models could barely beat Slay the Spire. Now they win 90%+ at the easiest setting and up to 20% at the hardest. Results from Epoch AI’s new SpireClimb benchmark.
Google Deepmind's AlphaProof Nexus solved dozens of open math problems and actually got peer reviewed
Google Deepmind's AlphaProof Nexus solved dozens of open math problems, including nine Erdős problems two of which were unsolved for 56 years, per a study in Science. The publication comes as OpenAI faces a boycott for dumping AI proofs on GitHub without peer review. Deepmind had its results reviewed before publishing. The article Google Deepmind's AlphaProof Nexus solved dozens of open math problems and actually got peer reviewed appeared first on The Decoder.
AI guardrails designed to stop hackers are now blocking defenders, and Orion-1 aims to fill the gap
Artemis Security's new Orion-1 model is purpose-built for cyber defense and beats Claude Opus 5.5 and GPT-6 Sol on the company's own benchmark. The model fills a growing gap as general-purpose frontier models lock down their cyber capabilities, blocking defenders in the process. The article AI guardrails designed to stop hackers are now blocking defenders, and Orion-1 aims to fill the gap appeared first on The Decoder.

‘Pure insanity’: Mathematicians will need years to make sense of OpenAI’s latest drop
"Staggering." "Overwhelming." "Unprecedented." "Surreal." "Pure insanity." Those were among the descriptions more than three dozen mathematicians reached for in conversations with The Verge as they tried to make sense of the flood of mathematical results OpenAI abruptly dropped on the field this week. Amid the awe, excitement, and uncertainty over the sheer scale of the deluge was a deep-seated anxiety over what it all means - and what comes next. For all their different react