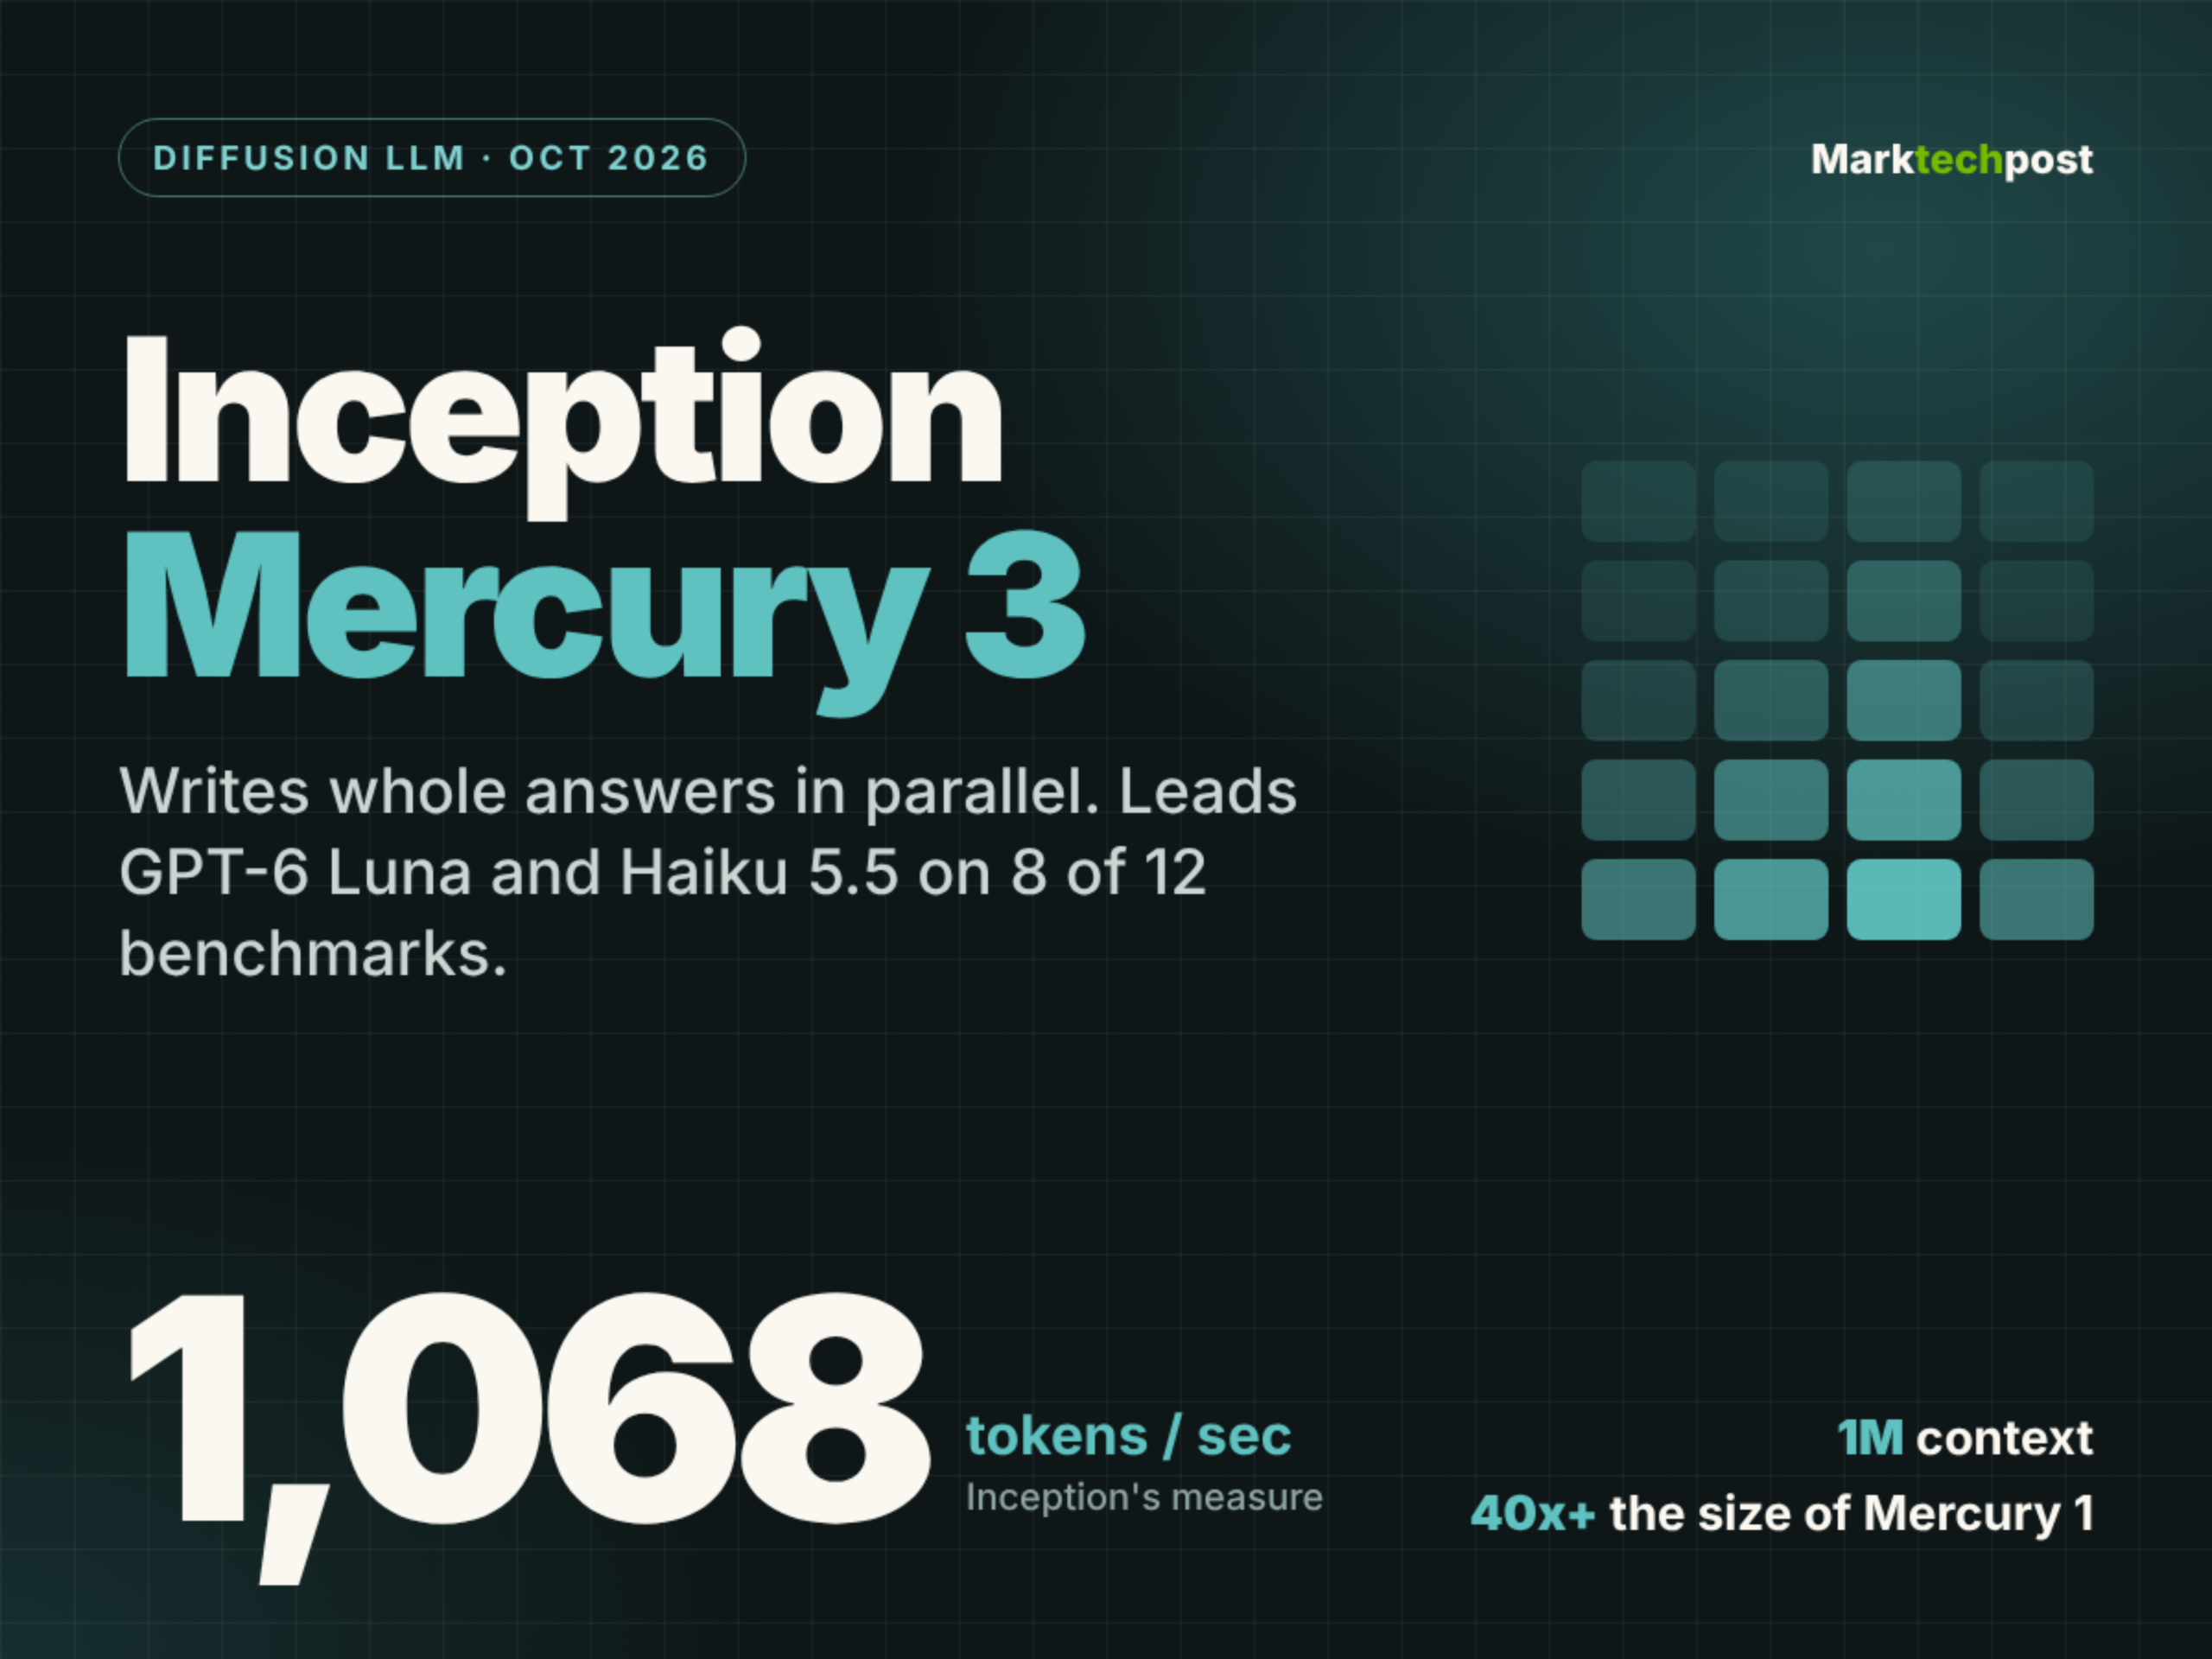
Inception releases Mercury 3 diffusion language model
MarkTechPost: Inception Releases Mercury 3 Diffusion LLM at 1,068 Tokens per Second
Inception has released Mercury 3, the newest version of its diffusion language model. Mercury 3 is a diffusion LLM from Inception that writes answers in parallel, not token by token. Inception reports 1,068 tokens per second on NVIDIA GPUs and a 1M-token context window. On Inception’s own benchmark table, it leads GPT-6 Luna and Claude Haiku 5.5 on 8 of 12 tests. For developers building agents, voice bots and search tools, this is a speed-first model with competitive scores. TL;DR
Get smart on it
Inception has released Mercury 3, a diffusion language model that generates text by refining a full draft in parallel rather than writing one token at a time, achieving 1,068 tokens per second on NVIDIA GPUs with a 1 million token context window. Diffusion models potentially offer speed advantages over traditional autoregressive models by reducing sequential processing steps, and Mercury 3's performance suggests this approach scales effectively as models grow larger. In benchmark comparisons against competing models, Mercury 3 leads on 8 of 12 tests, with particularly strong results on instruction-following and coding tasks, though it underperforms on long-context retrieval and certain coding benchmarks. The model is available through API platforms at a launch price of $0.10 per million input tokens and $0.35 per million output tokens, primarily designed for developers building agents, voice bots, and search tools.
Explainer: Choosing Your Claude Model: Why Cheaper Isn't Always Faster for Agentic Workflows
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time
Mistral AI launched Voxtral 3, a new family of language models built for real-time voice agents. The system combines speech-to-text, text-to-speech, and a voice agent SDK, supports more than 50 languages, and lets agents tap into external tools during live conversations. It can run on your own infrastructure or through EU-hosted APIs to keep data under your control. The article Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time appeared
Voxtral 3
Voxtral 3: Mistral's voice agent SDK for real-time speech in 50+ languages — accurate transcription, emotional TTS, deep tool use. EU-hosted or self-deployed.
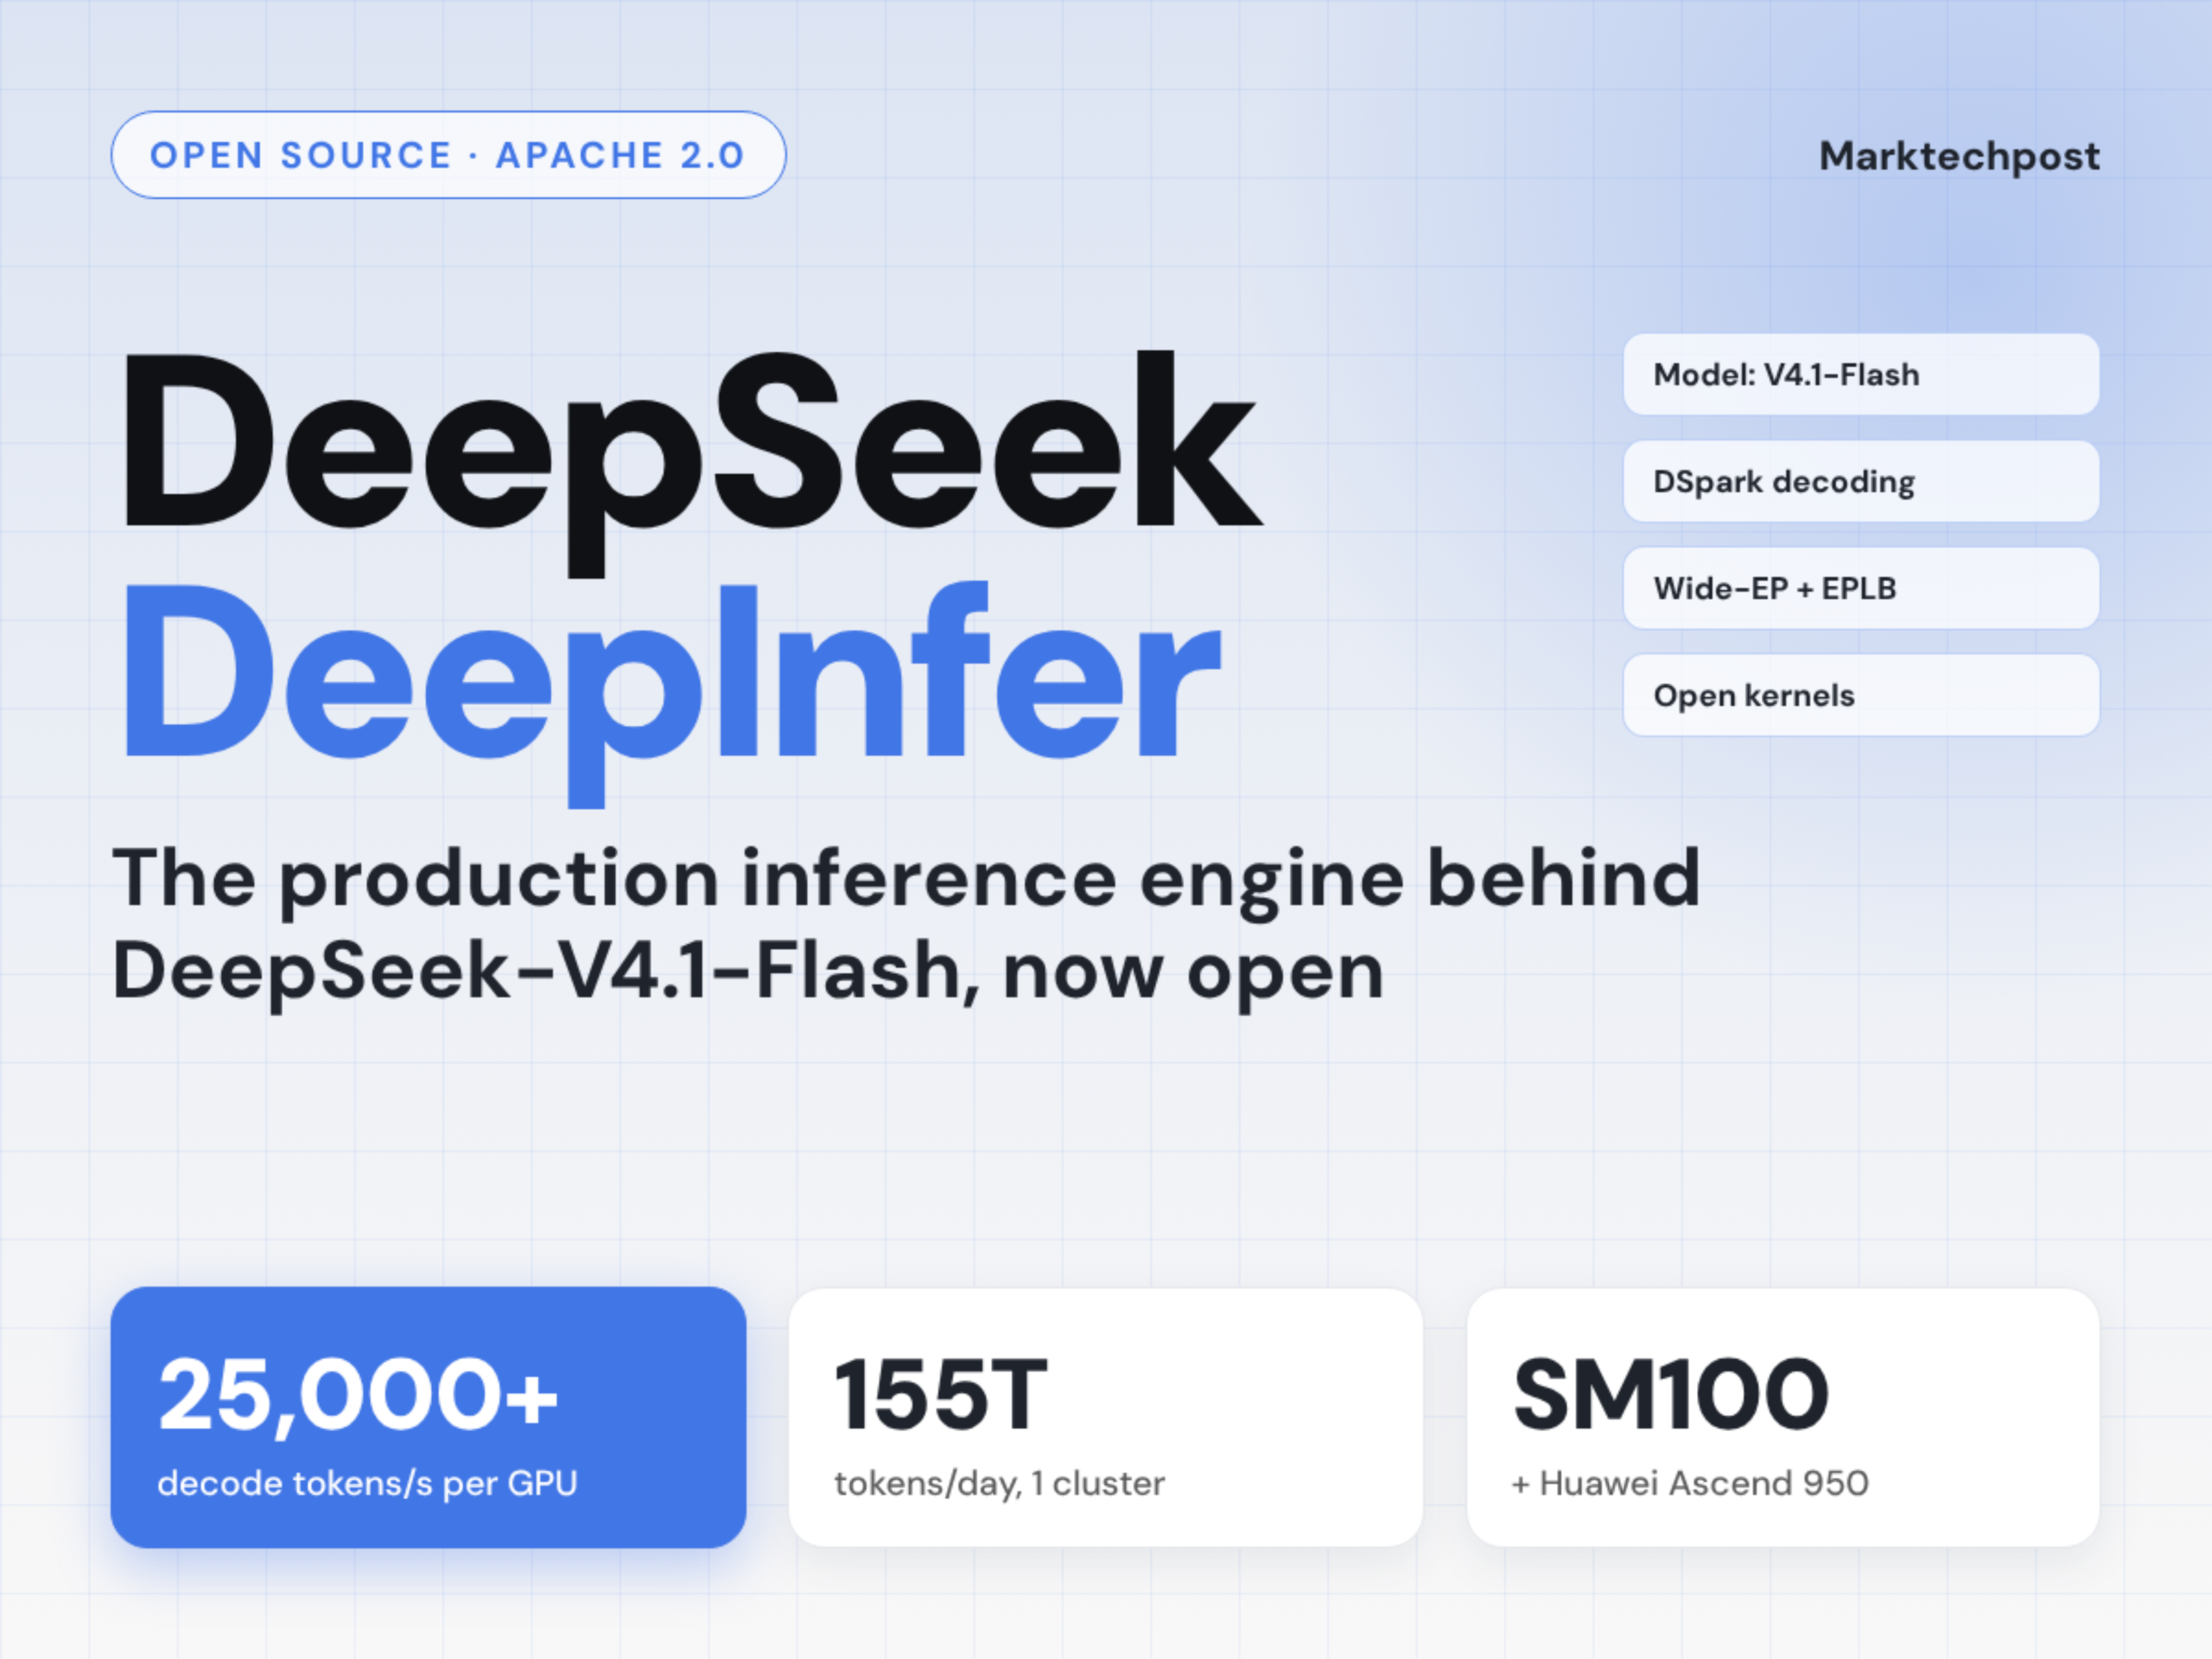
DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash
DeepSeek has open-sourced DeepInfer, the inference framework that runs its production services. The DeepSeek DeepInfer inference framework is the engine behind DeepSeek-V4.1-Flash. It ships under the Apache 2.0 license. DeepSeek also released deepseek-recipe, its MIT-licensed token encoding and decoding layer. For developers, this is a rare look at a frontier lab’s real serving stack. TL;DR Size / scope: 1 supported model (DeepSeek-V4.1-Flash), 1M-token context window per the model
Also reported by The Decoder and SiliconANGLE

Nvidia launches new open models to run agents in the enterprise and on PCs
Nvidia is leaning hard into the trend of enterprise companies wanting to run their own open models in their own data centers and also trying to make on-device, private AI agents a thing.

Meta and Apple team up to make Muse AI models run better on Macs
The new Muse Spark Open AI model can work on M5 Ultra Mac Studios. | Photo: Amelia Holowaty Krales / The Verge Meta announced the Muse Spark Open AI model today, claiming that it's the "most capable US open-weight model to date." But the company also says that it's the "the first model in its class" that can "run on your desktop using two Apple M5 Ultra Mac Studios with the latest MLX framework." Meta and Apple, typically rivals, worked together on the launch and are publicly su
Also reported by The Decoder, TechCrunch, SiliconANGLE and MarkTechPost
Elevenlabs releases two new speech-to-speech models designed for real-time AI conversations
Elevenlabs' new Eleven Realtime speech-to-speech models combine speed and accuracy. The v1 Max variant scores 98.8 percent on the Big Bench Audio benchmark with a 0.57-second response time. Elevenlabs says no model on the Artificial Analysis leaderboard is both faster and more accurate. The article Elevenlabs releases two new speech-to-speech models designed for real-time AI conversations appeared first on The Decoder.