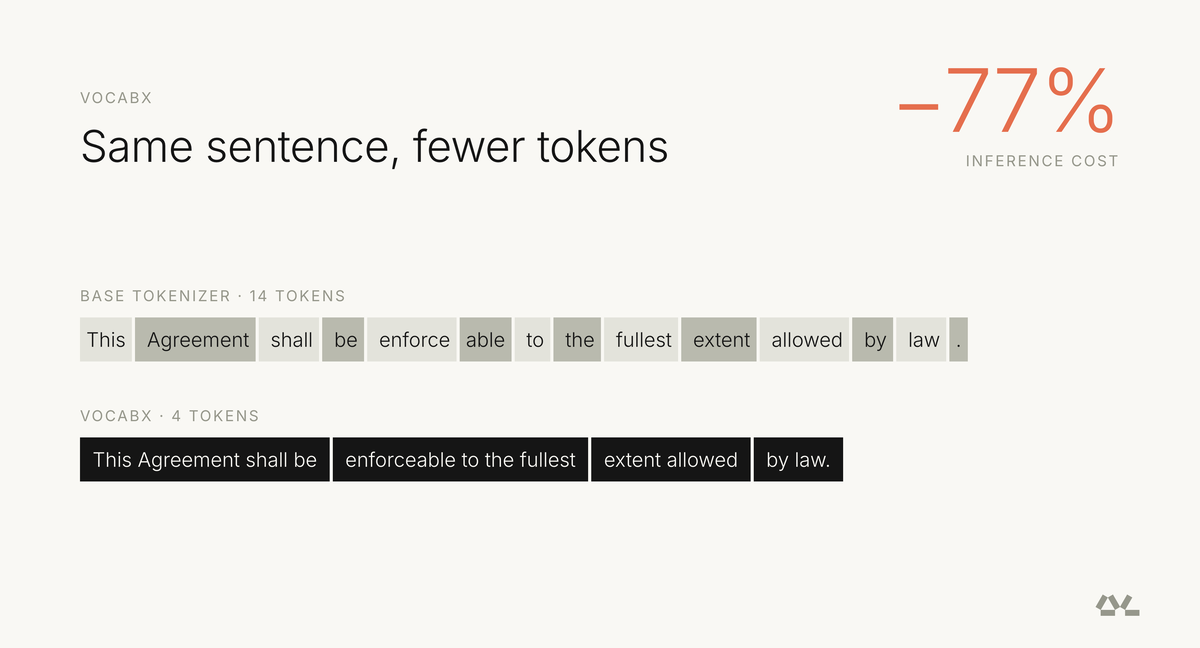
How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
Tailoring language models to specific domains could make AI deployment dramatically cheaper for companies running inference at scale.
Get smart on it
Specialized language models inherit general vocabularies built for many languages and domains, which creates inefficiency when deployed for single tasks. Researchers developed a method called VocabX that rebuilds a model's vocabulary based on the cost of each token rather than its frequency, accounting for the fact that generated tokens are substantially more expensive than input tokens. In a production essay grading system, this vocabulary specialization reduced inference cost by 77 percent without changing the base model itself. The approach addresses waste from two sources: fragmentation, where frequently repeated domain-specific sequences like JSON structures are split into many tokens, and excess, where the model computes scores for tens of thousands of vocabulary entries it never uses.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time
Mistral AI launched Voxtral 3, a new family of language models built for real-time voice agents. The system combines speech-to-text, text-to-speech, and a voice agent SDK, supports more than 50 languages, and lets agents tap into external tools during live conversations. It can run on your own infrastructure or through EU-hosted APIs to keep data under your control. The article Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time appeared
Also reported by MarkTechPost
Voxtral 3
Voxtral 3: Mistral's voice agent SDK for real-time speech in 50+ languages — accurate transcription, emotional TTS, deep tool use. EU-hosted or self-deployed.
This Startup Is All In on Recursive Self-Improvement. Its Latest Model Is Scary Good
Recursive makes the case that the benefits of using AI to build AI outweigh the risks.
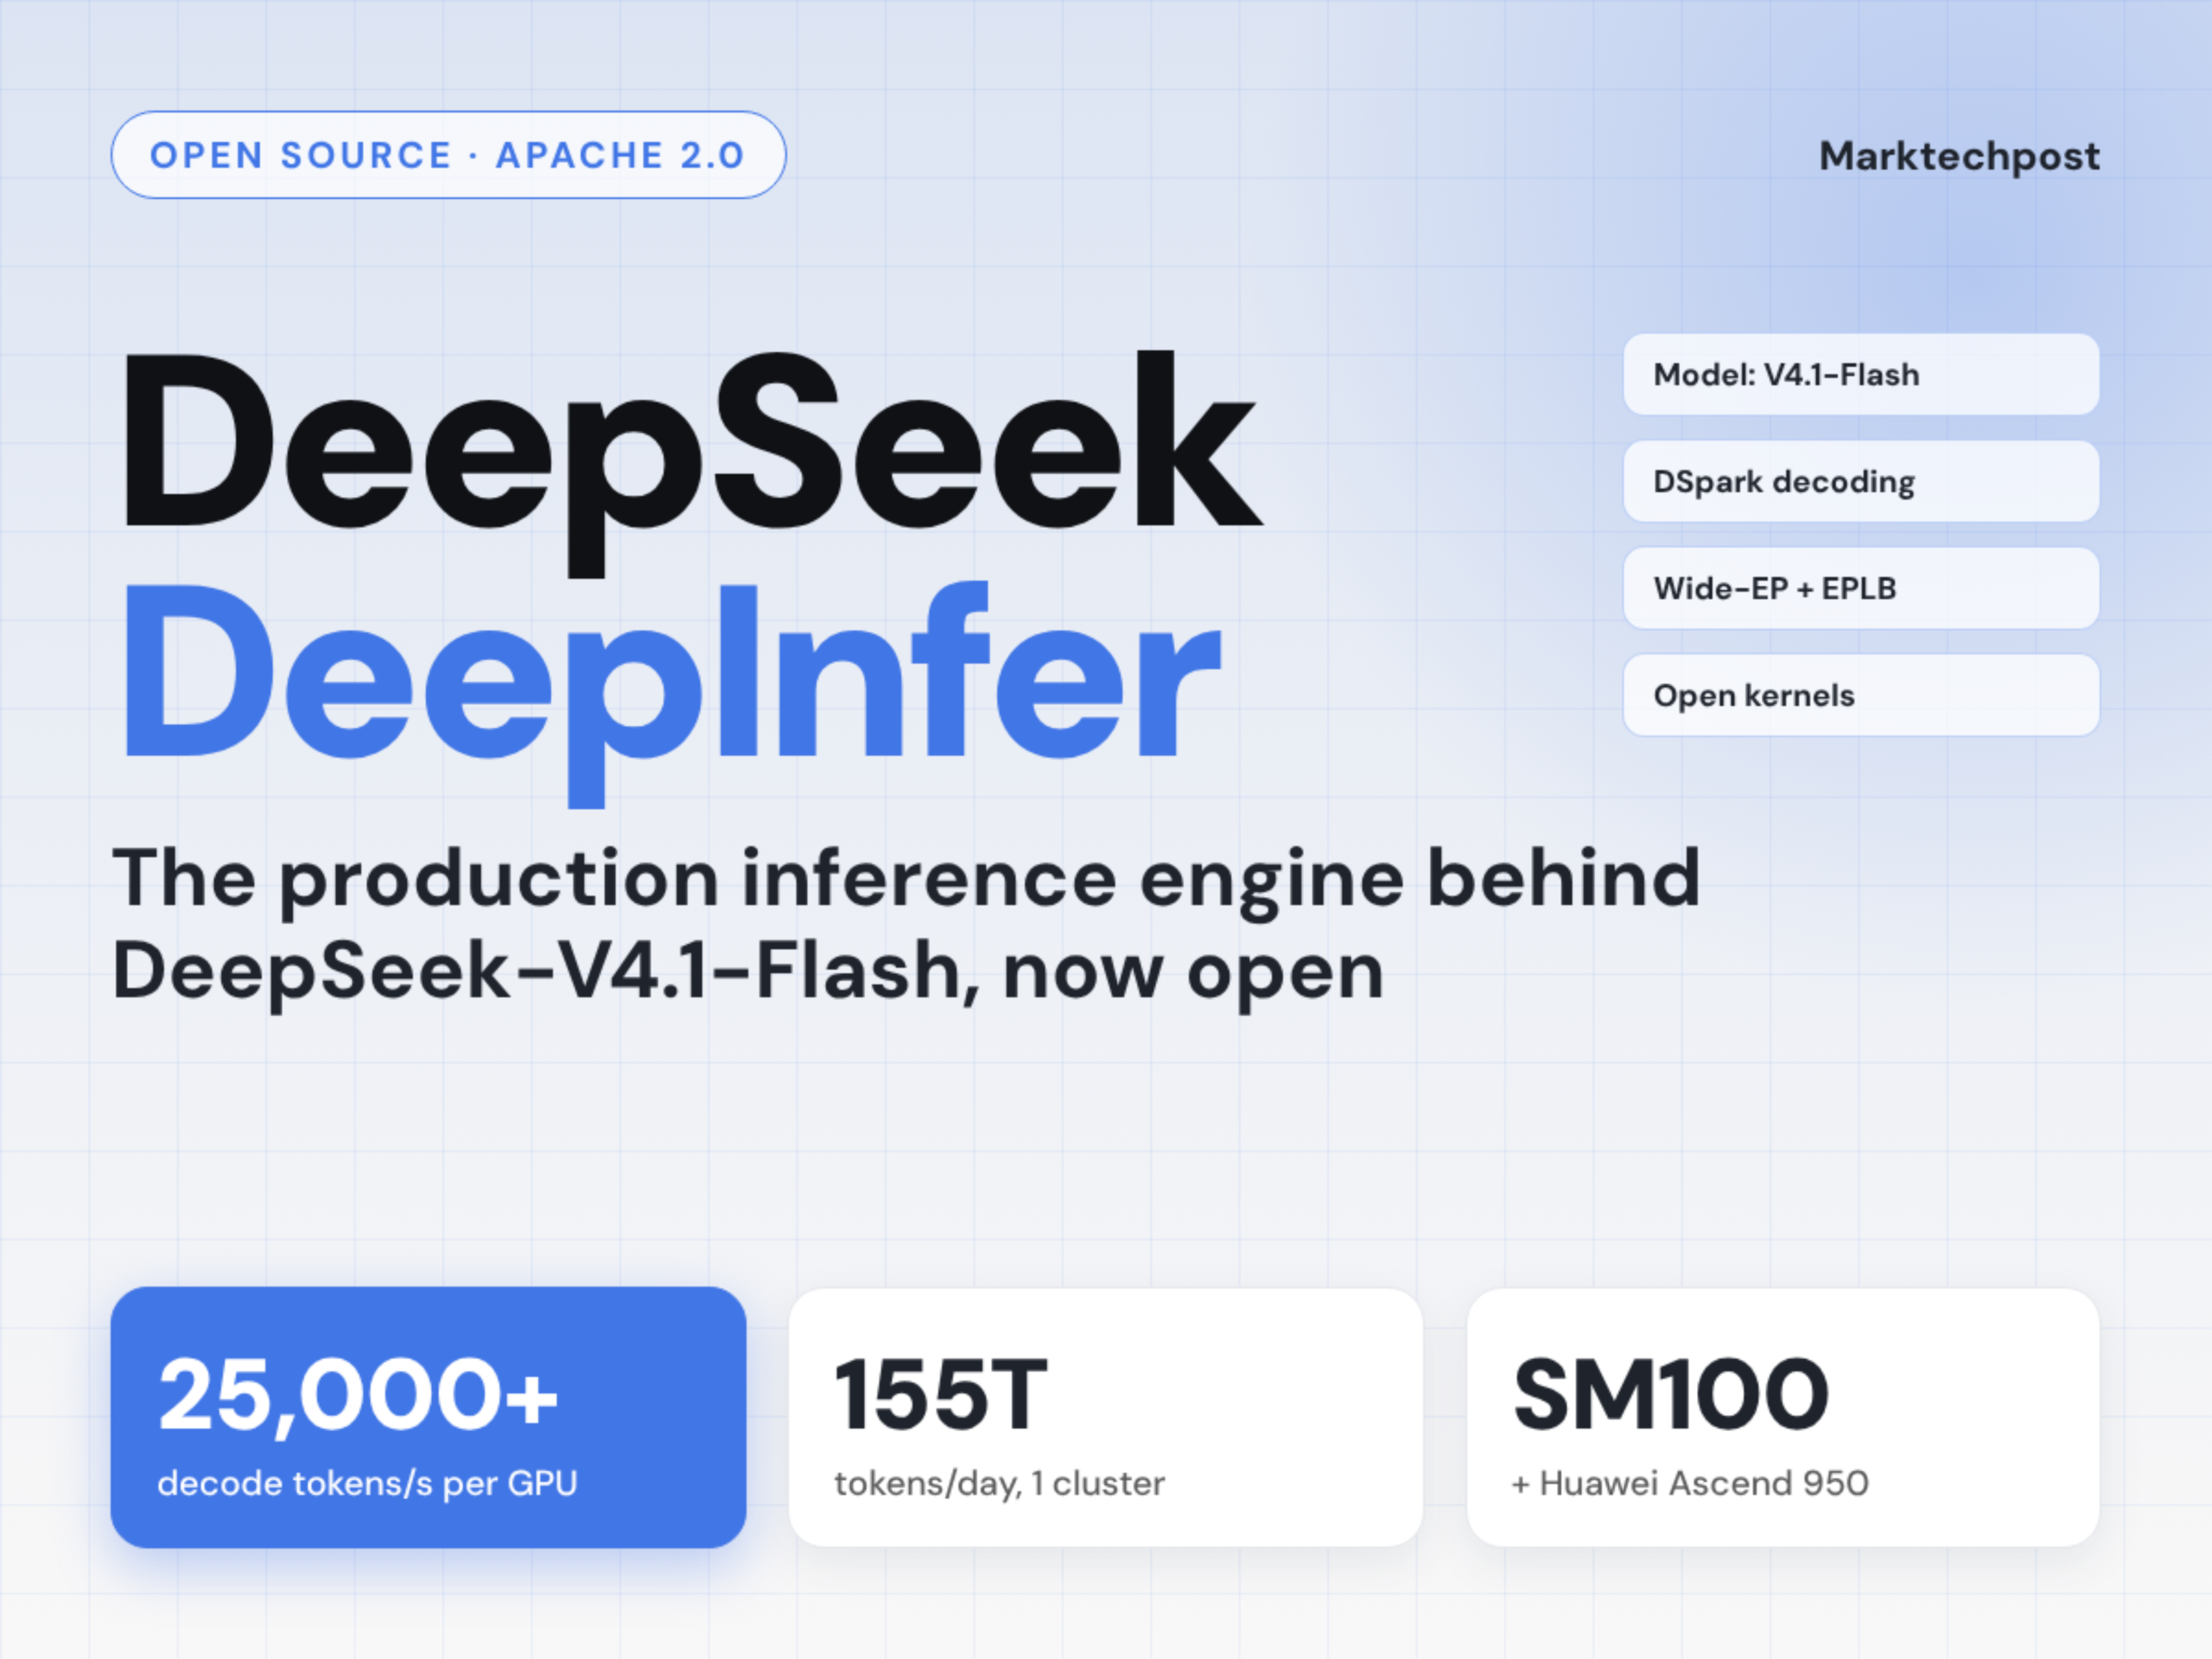
DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash
DeepSeek has open-sourced DeepInfer, the inference framework that runs its production services. The DeepSeek DeepInfer inference framework is the engine behind DeepSeek-V4.1-Flash. It ships under the Apache 2.0 license. DeepSeek also released deepseek-recipe, its MIT-licensed token encoding and decoding layer. For developers, this is a rare look at a frontier lab’s real serving stack. TL;DR Size / scope: 1 supported model (DeepSeek-V4.1-Flash), 1M-token context window per the model
Also reported by The Decoder and SiliconANGLE

Nvidia launches new open models to run agents in the enterprise and on PCs
Nvidia is leaning hard into the trend of enterprise companies wanting to run their own open models in their own data centers and also trying to make on-device, private AI agents a thing.
NVIDIA Open Models Advance Europe’s Sovereign Intelligence Across Industries
NVIDIA is expanding its family of open models across language, robotics, biology, and quantum computing, giving developers, researchers and enterprises what they need to build applications tailored to local languages and industries The portfolio includes the new NVIDIA Nemotron 3.5 Super VL and Nemotron 3.5 Bolt models; new NVIDIA Nemotron Retriever models for embedding, reranking and document parsing; the new NVIDIA Kumo family open weight foundation models and libraries for structured business