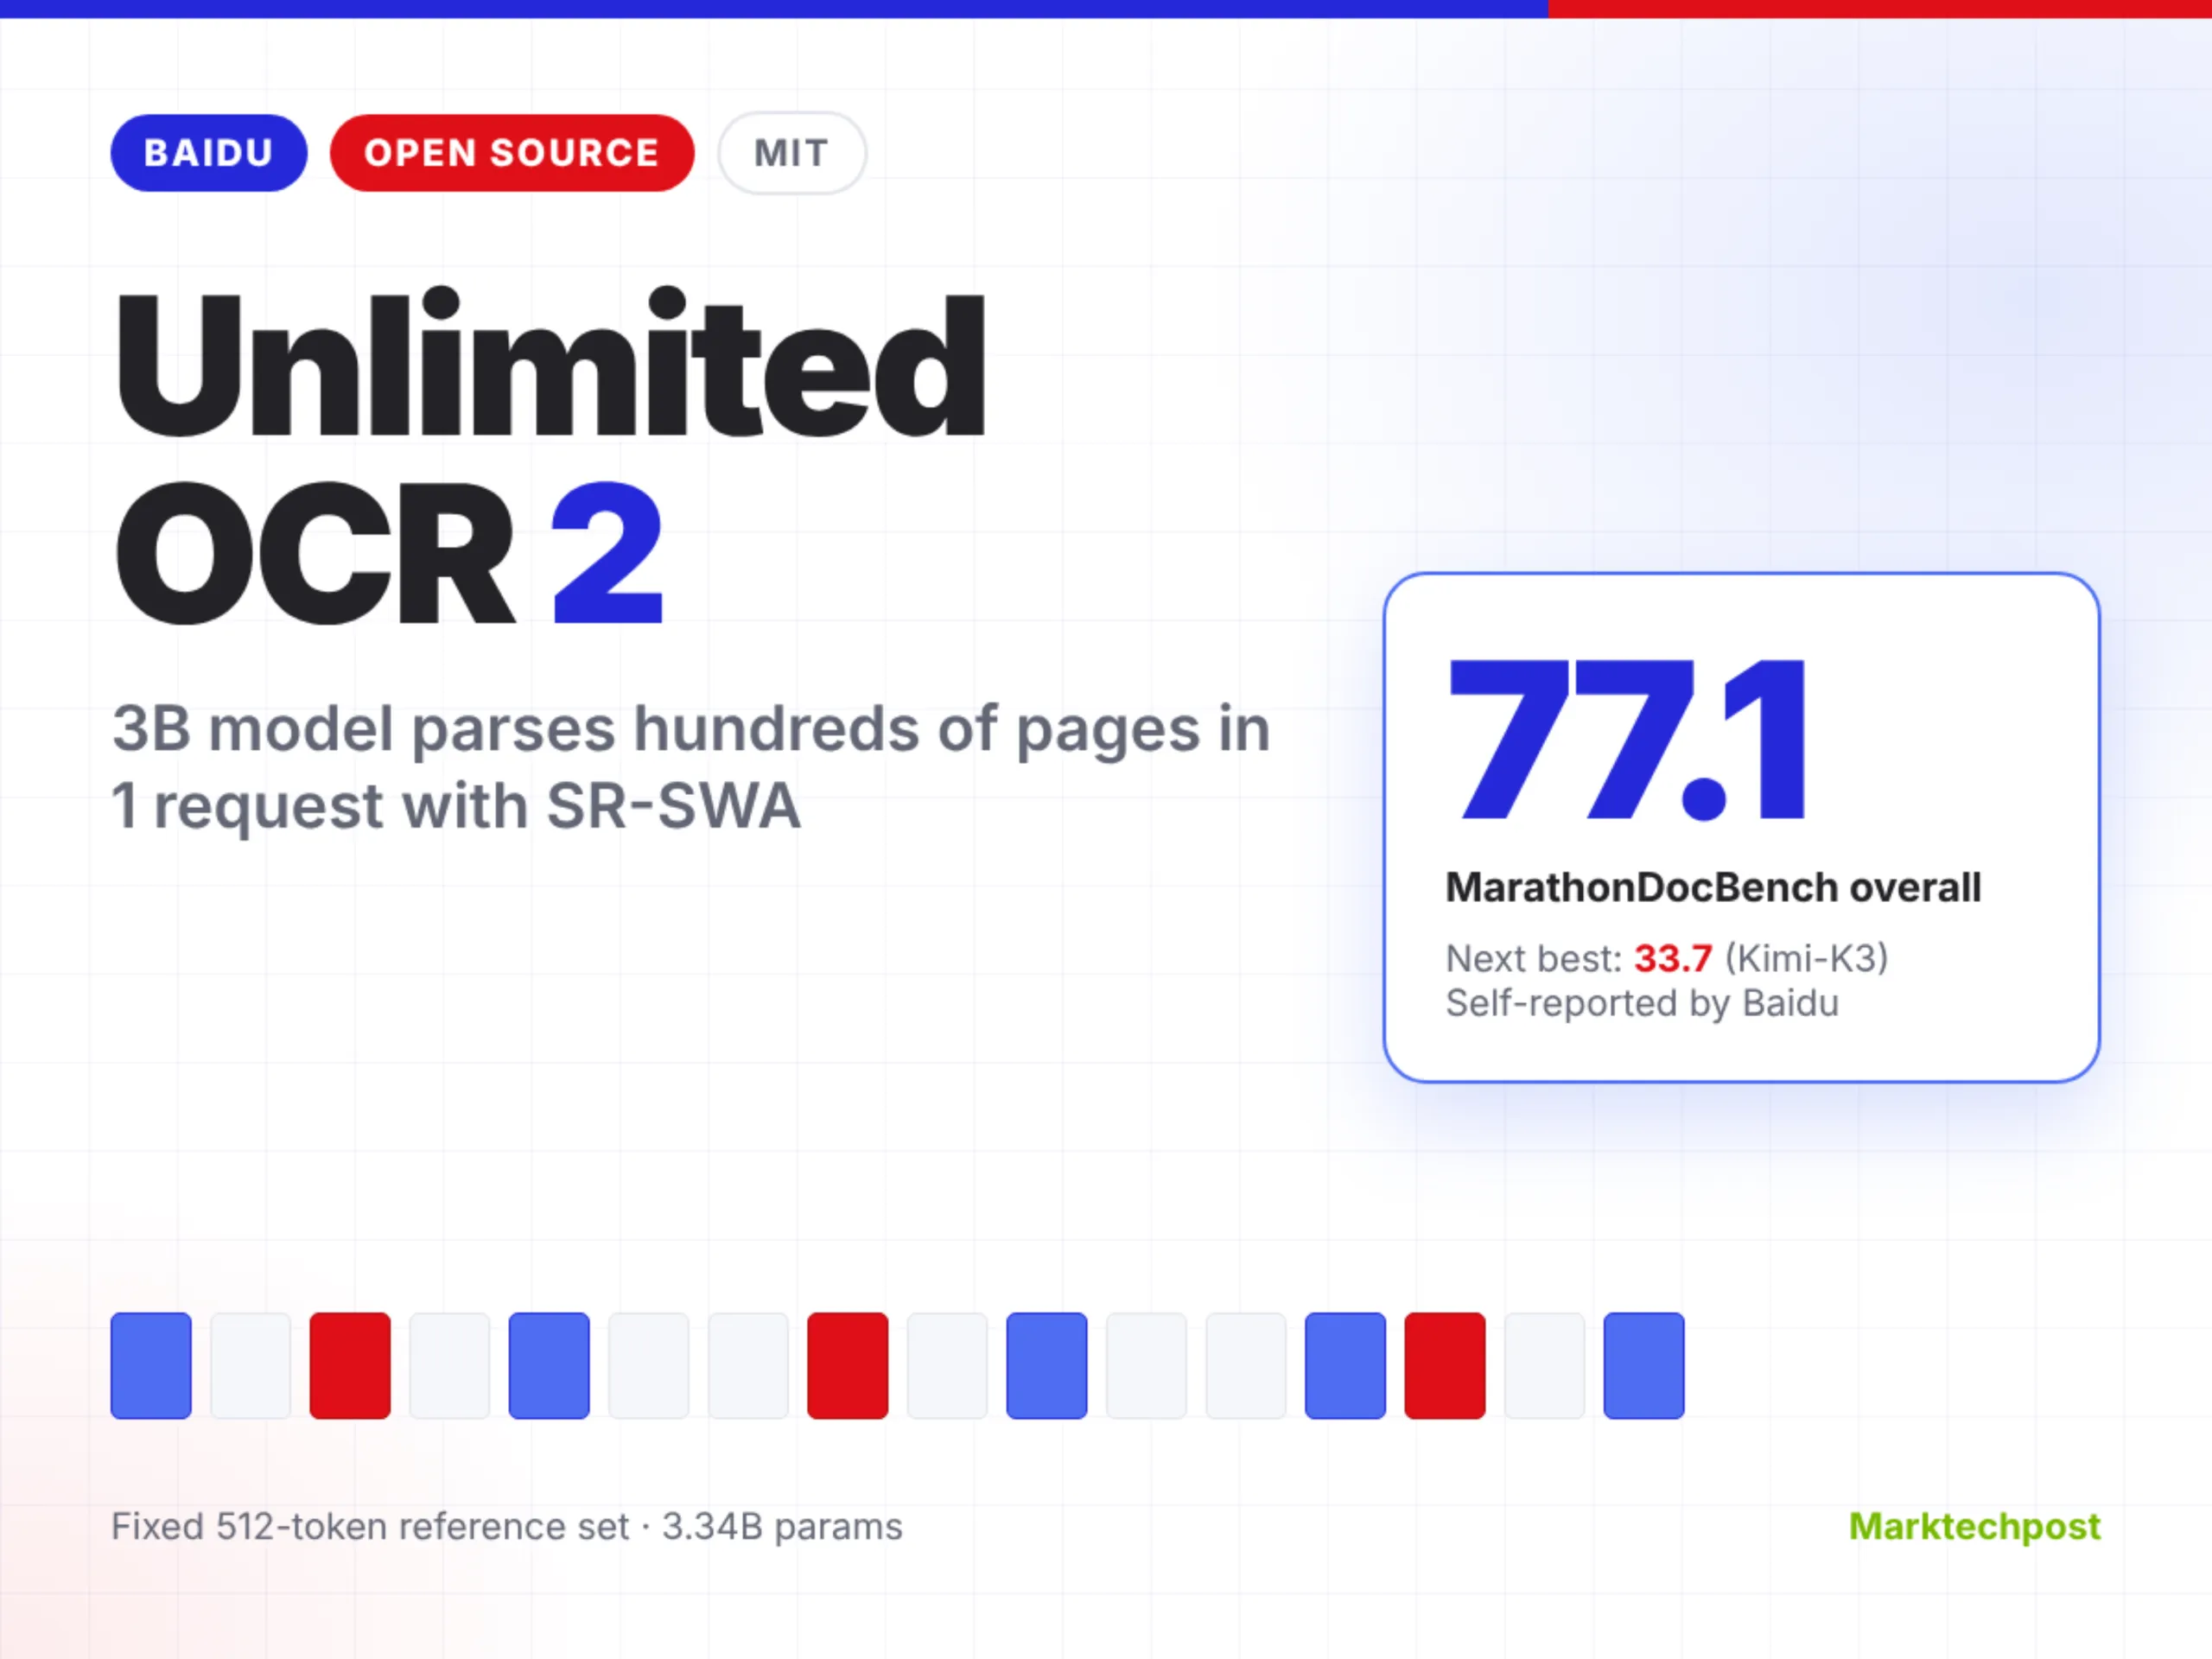
Baidu releases OCR model for hundred-page documents
MarkTechPost: Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing
Baidu has released Unlimited OCR 2, an open-source OCR model built for very long documents. The 3B model parses books, filings and reports of hundreds of pages in one request. Its core change is SR-SWA, a sparse attention scheme that keeps per-step decoding cost nearly flat. Weights ship under the MIT license, with code on GitHub. TL;DR Size: 3.34B parameters. Active parameters not disclosed. Max position length 131,072 tokens. Runs on: 1 CUDA GPU in BF16. Baidu tested on an NVIDIA A8
Get smart on it
An open-source OCR model has been released that can parse very long documents of hundreds of pages in a single request. The model uses a technique called SR-SWA that compresses attention into a fixed set of working references, keeping processing cost nearly constant as documents grow longer rather than increasing dramatically. The model scores significantly higher on benchmarks testing hundred-page documents compared to other available models, though it performs less consistently on tasks like heading hierarchy detection. All benchmark scores reported are self-reported by the developer.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Introducing GPT-6.1 Terra
Bringing fast and capable computer use to everyone
Also reported by SiliconANGLE, MarkTechPost and The Decoder

Genie 4: A new generation of world simulation
Genie 4: our new world model unlocking unprecedented realism in real-time simulation.
Also reported by TechCrunch and Ars Technica

Google’s next Genie AI model generates more realistic experiences
Google announced today its Genie 4 world model for generating interactive experiences using AI. The company says the model has four main updates: It allows for more realistic worlds, lets users update an experience in real time with a natural language prompt, can generate audio, and uses Gemini 3.8 Flash under the hood to help with its simulations. It also can create experiences that are about two minutes long, up from one minute for the previous Genie 3 model. Google is pitchi
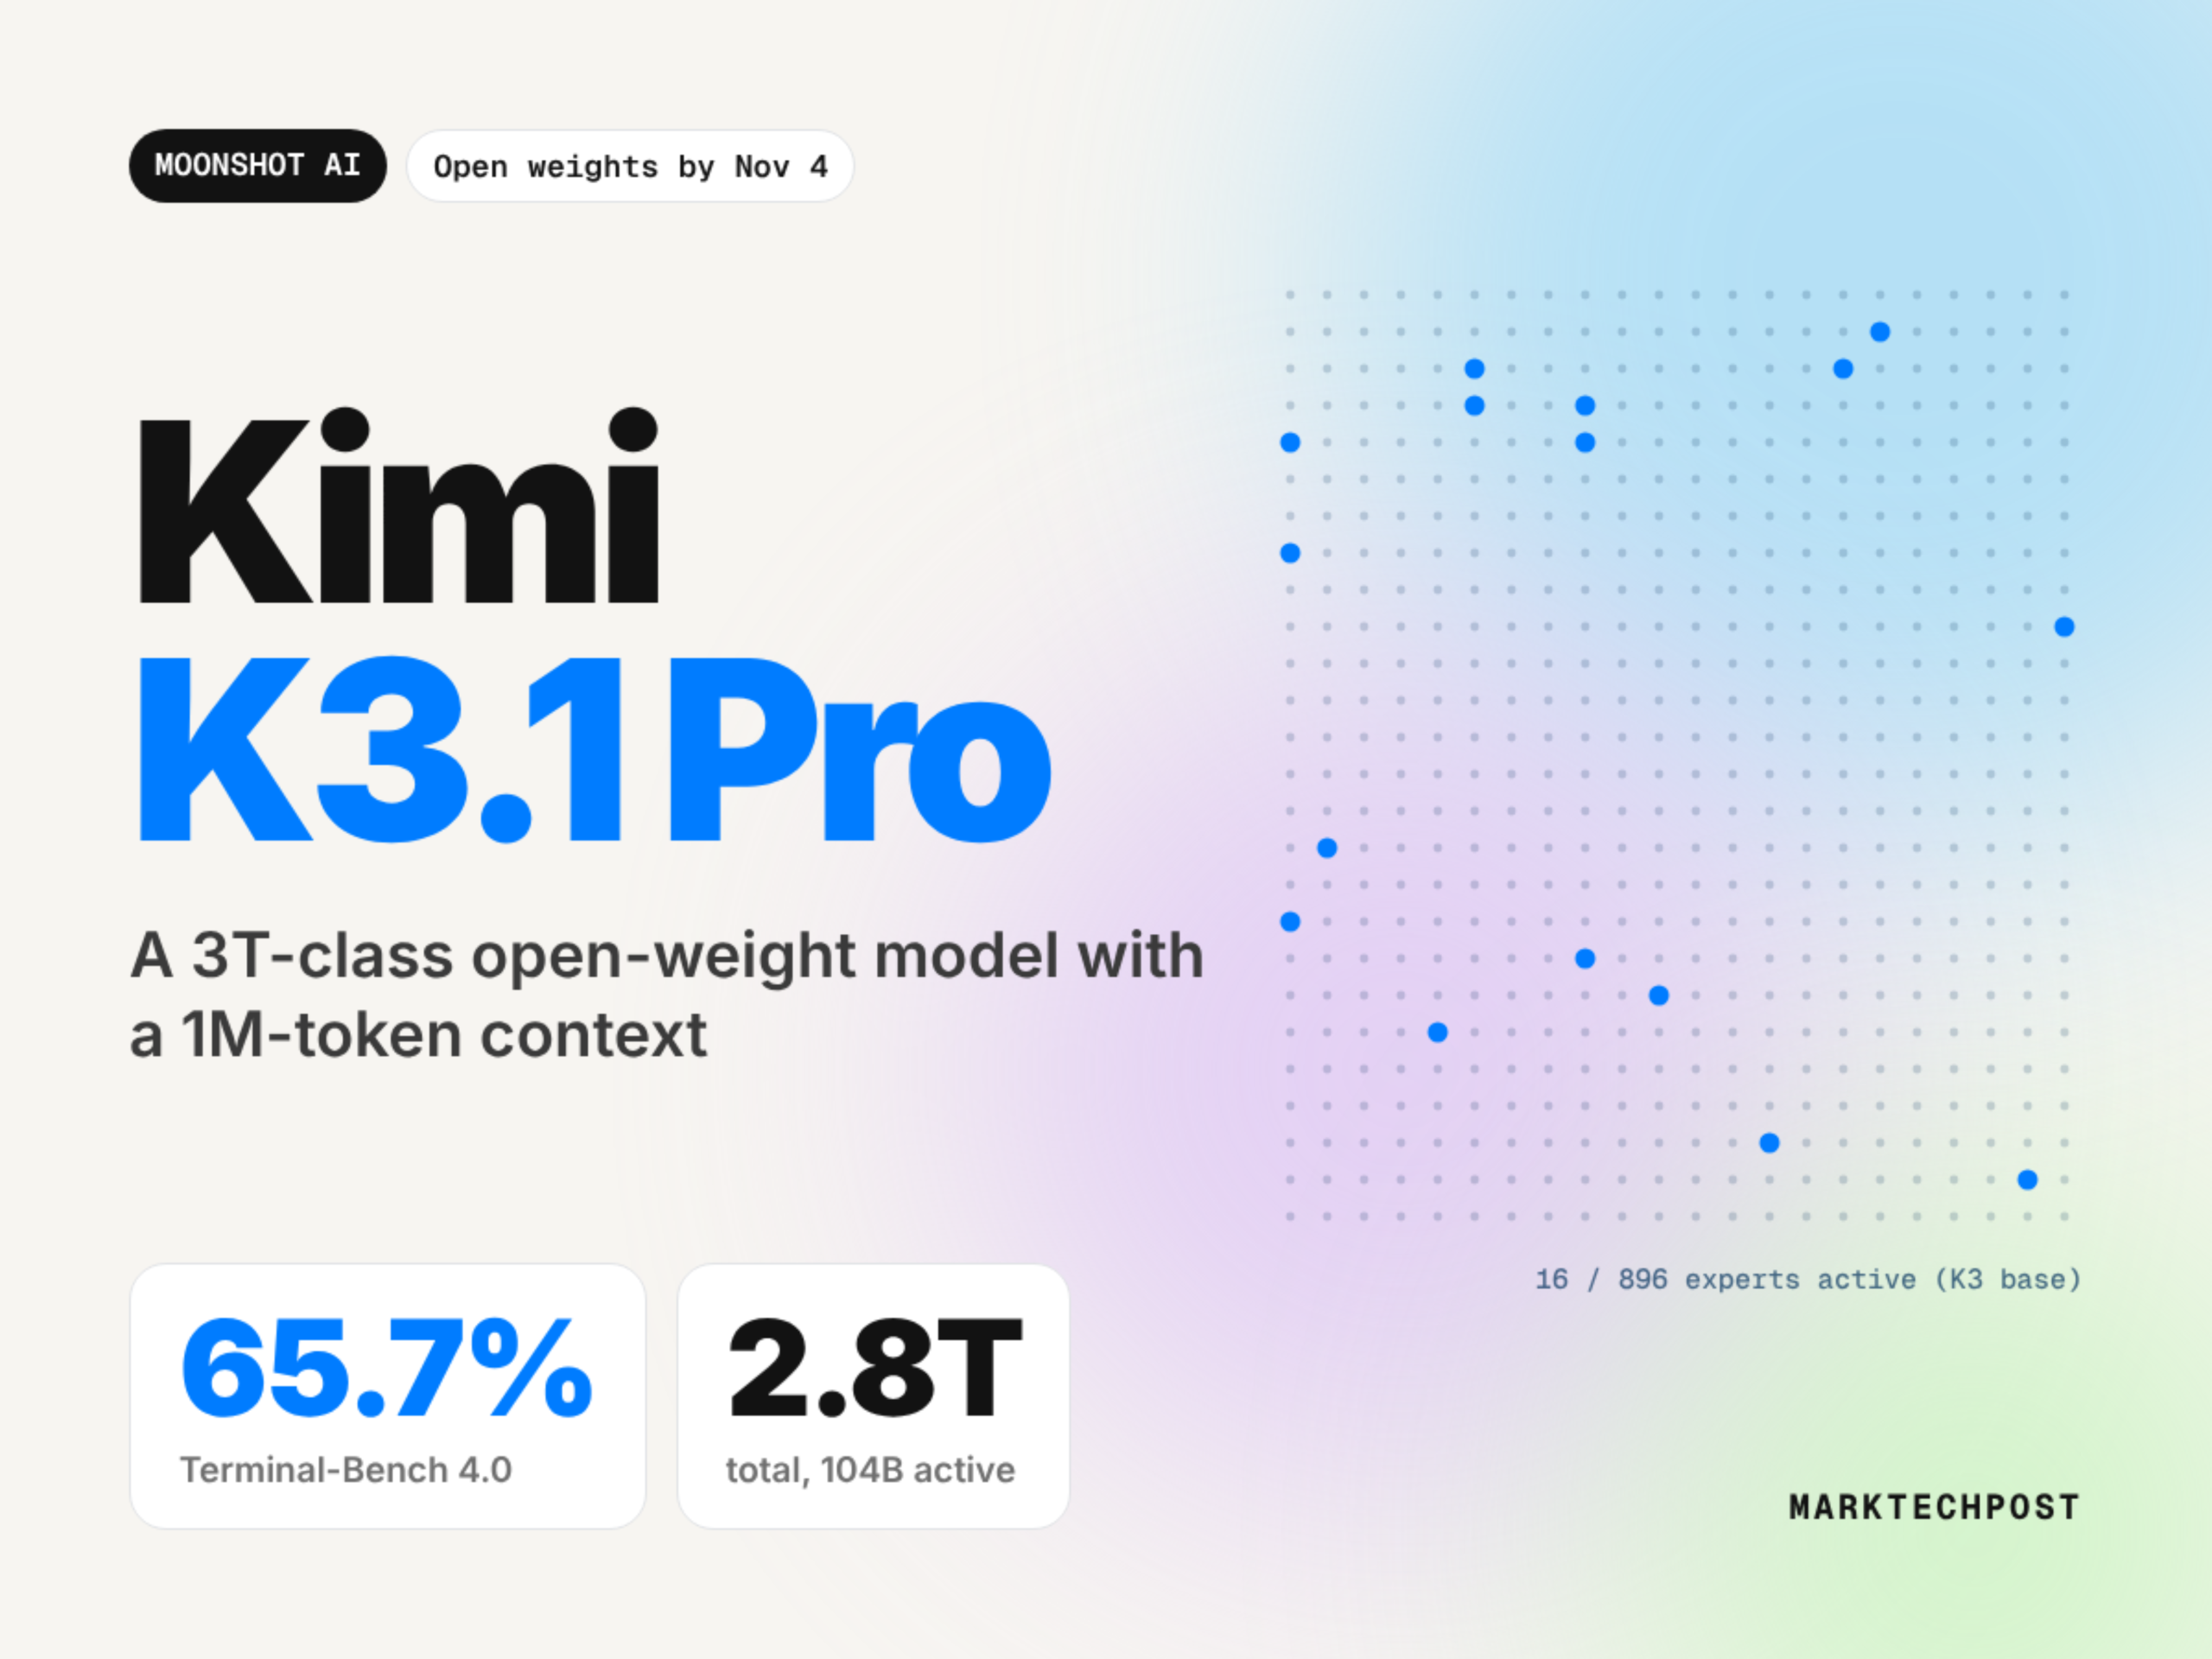
Moonshot AI Releases Kimi K3.1 Pro: A 2.8T Total/104B Active Params (MoE) Model with 1M Context
Moonshot AI has just released Kimi K3.1 Pro, the first model in its K3.1 series. Kimi K3.1 Pro is a 3T-class open-weight* model with a 1-million-token context window. Moonshot team positions it against the strongest proprietary models on coding, agentic and knowledge benchmarks. For developers, it is cheaper API pricing than K3 and open weights yet not available. *open weights are expected to release in November 2026. TL;DR Size: 2.8T total, 104B active parameters (MoE), 1M-token context
Also reported by SiliconANGLE and The Decoder
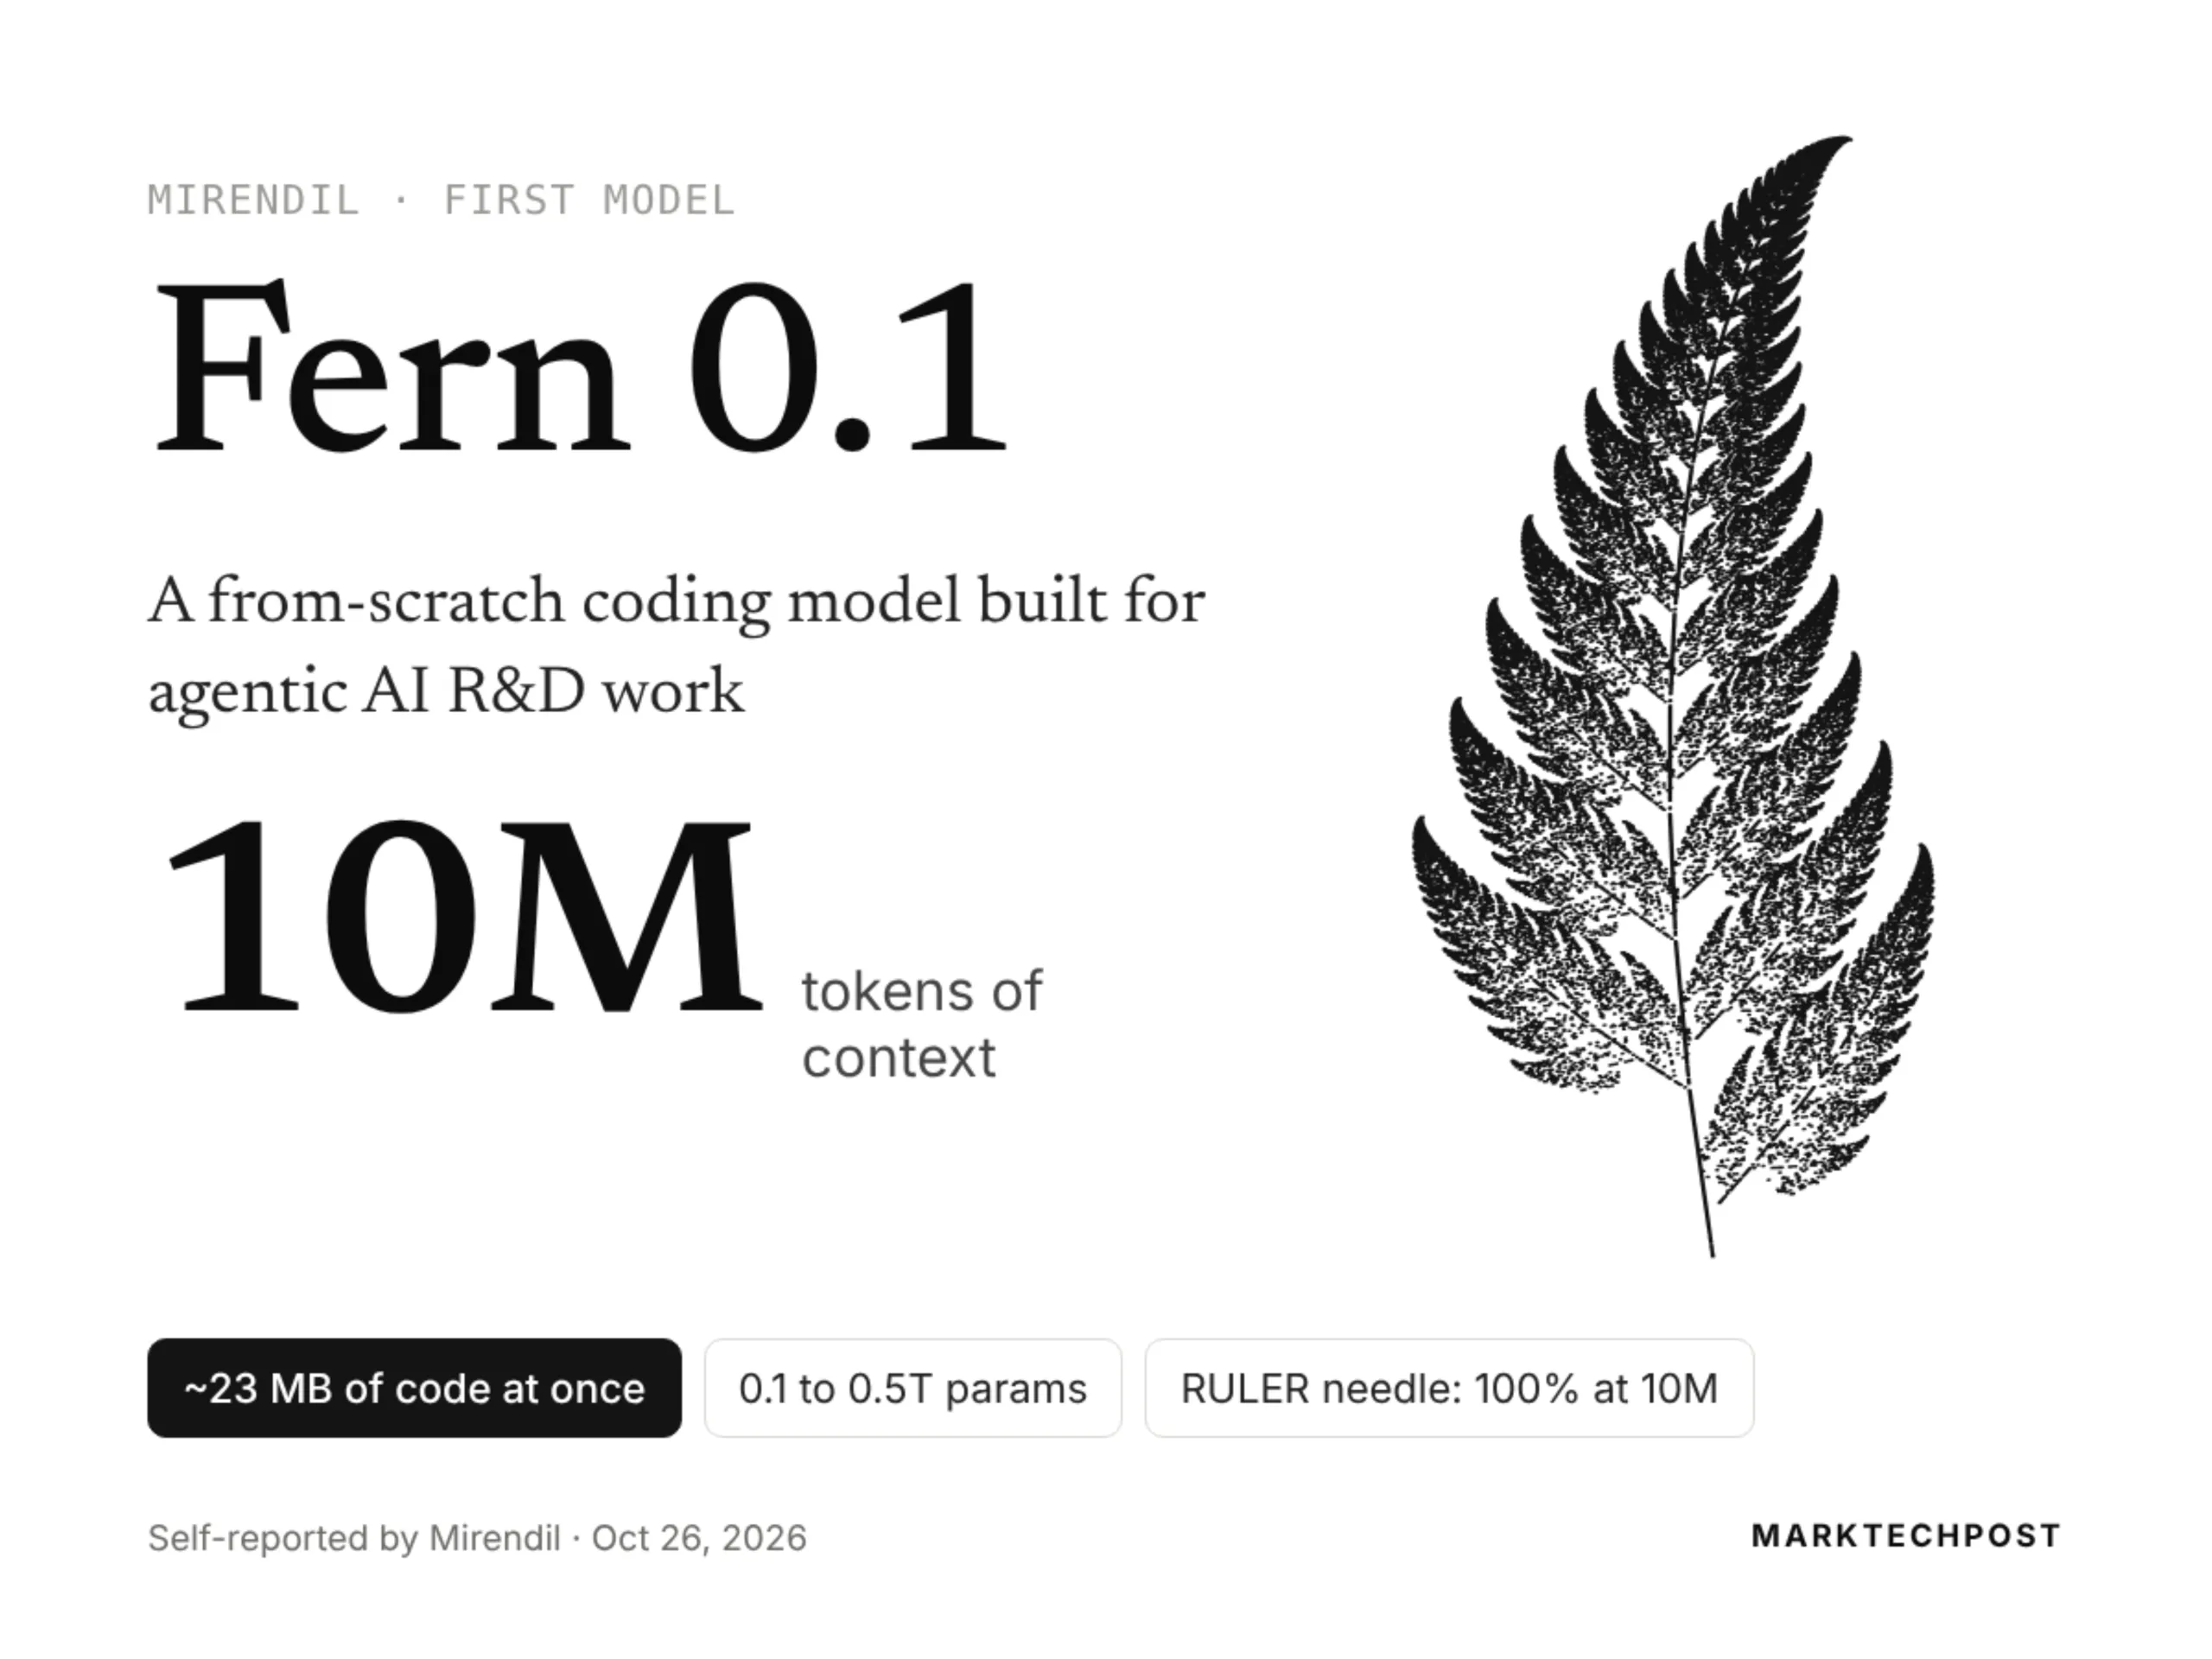
Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context
Mirendil has released Fern, its first AI model. Mirendil Fern is a from-scratch coding model with a context window of up to 10M tokens. Mirendil explains how that equals about 23 MB of code, or roughly half a million lines. That is a codebase on the scale of Megatron-LM, held in context at once. Fern 0.1 is the first version, built from Mirendil-Base after a short round of post-training. For developers, its like, you load a whole repo, a full training log or days of agent traces at once. TL;

Jack Dorsey’s Block made an AI model that talks to you like an awkward new friend
Jack Dorsey's Block announced an AI model called Dessa that's trained "from scratch on nothing but human conversation," and to show off the model, Block shared chats it has had with humans that can occasionally be a little awkward and uncanny. Take this one, for example, shared by Dessa lead Ragavan Thurairatnam. The conversation between the model and the speaker does have a mostly natural back and forth (though for some reason, the model initially mistakes the speaker for some
Also reported by TechCrunch and The Decoder