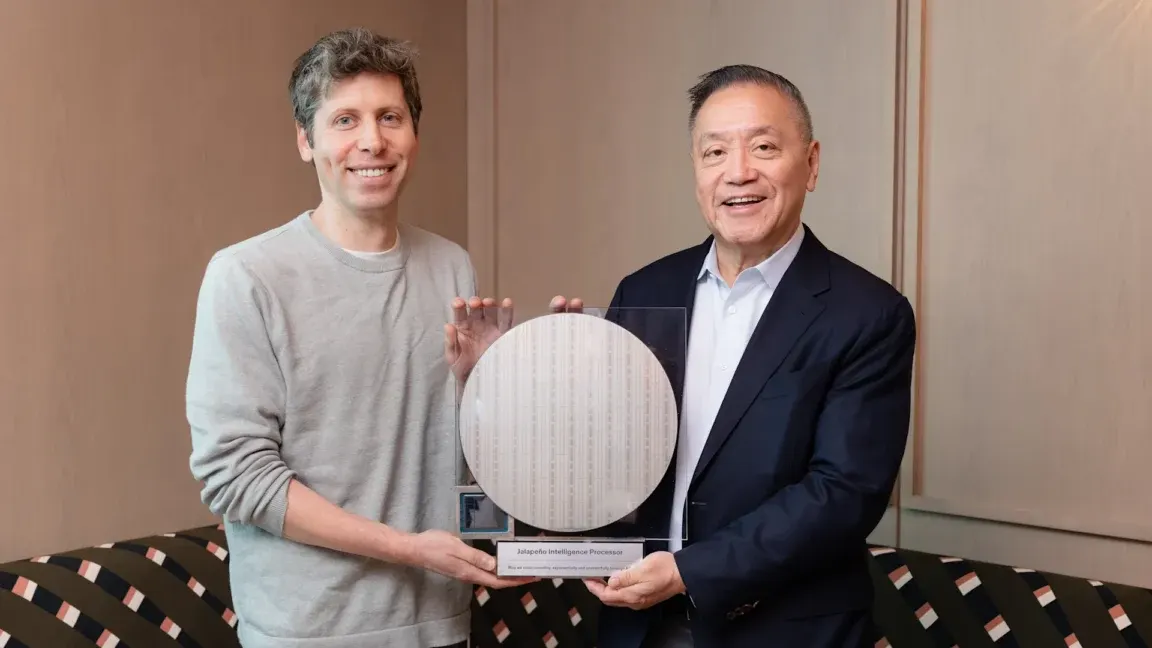
OpenAI and Broadcom announce chip designed for LLM inference at scale
OpenAI, the company behind ChatGPT and Codex and the models those tools utilize, and Broadcom, an established silicon supplier, have announced a new chip called Jalapeño, designed specifically for large language model inference in data centers. The chip is intended to be deployed at large data centers, both companies claim this is just the first generation in a long-term project that will see chips refined over time.Read full article Comments
OpenAI and Broadcom have announced a custom chip called Jalapeño designed specifically for running large language models in data centers. The chip is an application-specific integrated circuit built from scratch based on insights from OpenAI researchers and OpenAI's roadmap for future models, with both companies claiming it will deliver better performance per watt than existing alternatives. This matters because OpenAI is seeking to own the complete technology stack behind its products while reducing dependence on outside chip suppliers like Nvidia, and more broadly, AI companies are pursuing custom chips to address a global shortage of computing capacity.
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven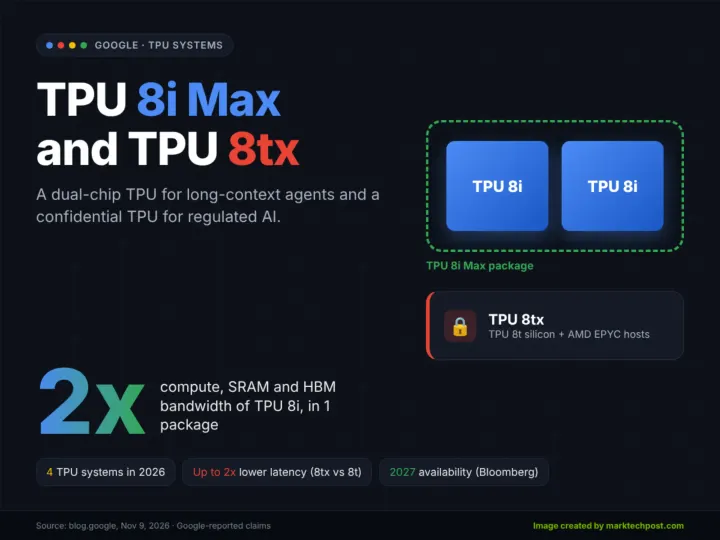
Google Unveils TPU 8i Max and TPU 8tx: A Dual-Chip TPU and a Confidential TPU
Google has added two new systems to its eighth-generation TPU lineup. TPU 8i Max targets massive context windows and rack density. TPU 8tx targets secure, confidential inference. Google TPU 8i Max is a dual-chip package built from 2 TPU 8i chips. Both arrive alongside TPU 8t and TPU 8i, announced in April. TL;DR Size: TPU 8i Max = 2 TPU 8i chips in 1 package. TPU 8tx = TPU 8t silicon plus 5th Gen AMD EPYC hosts. Runs on: Google Cloud TPU systems. Performance: 8i Max doubles TPU 8
Also reported by Data Center Knowledge
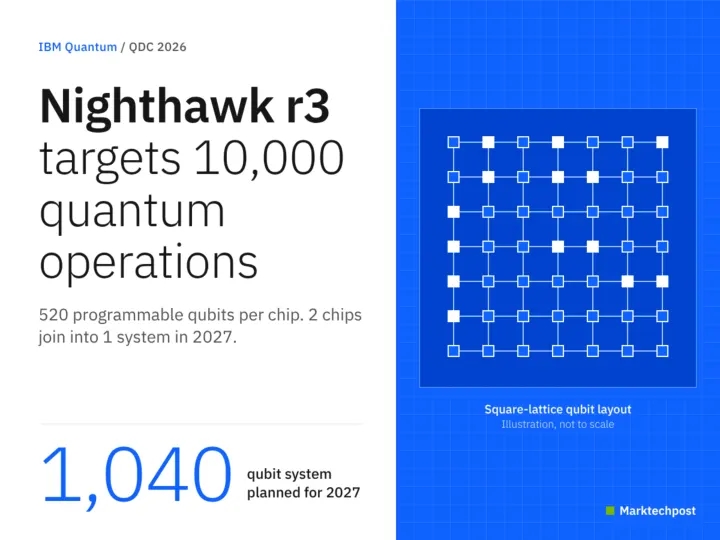
IBM Announces IBM Quantum Nighthawk r3: A New Processor to Support 10k Quantum Operations on 520 Programmable Qubits
IBM has announced IBM Quantum Nighthawk r3, its next superconducting quantum processor. It is designed to run 10,000 quantum operations accurately across 520 programmable qubits. In 2027, IBM plans to link 2 r3 chips into a single 1,040-qubit system. For developers, the announcement is speed. The current Nighthawk r2 already runs workloads up to 19x faster than IBM’s earlier processors. TL;DR Size: Nighthawk r3: 520 programmable qubits, 2,034 physical qubits, 10 l-couplers. Nightha

Why the data center you dread might never even be built
The data center boom is running into serious real-world obstacles, from widespread local opposition and permitting delays to a scramble for electricity. Before those challenges even come into play, though, there’s a more basic problem: A lot of the projects being announced may never get built in the first place. With billions of dollars in AI infrastructure […]

How backlash and red tape continue to slow data centers post-Blue Wave
The data center boom is running into serious real-world obstacles, from widespread local opposition and permitting delays to a scramble for electricity. Before those challenges even come into play, though, there’s a more basic problem: A lot of the projects being announced may never get built in the first place. With billions of dollars in AI infrastructure […]

AMD Launches Epyc SP7, Helion as AI Rack Demand Rises
AMD has begun shipping sixth-gen Epyc servers and is rolling out Helion AI racks, signaling a bigger push into enterprise and agentic AI infrastructure.

Google broadens its AI hardware portfolio with two new specialized chips
Google's new tensor processing units (TPUs) broaden its chip portfolio to more use cases: confidential model training and more memory capacity.