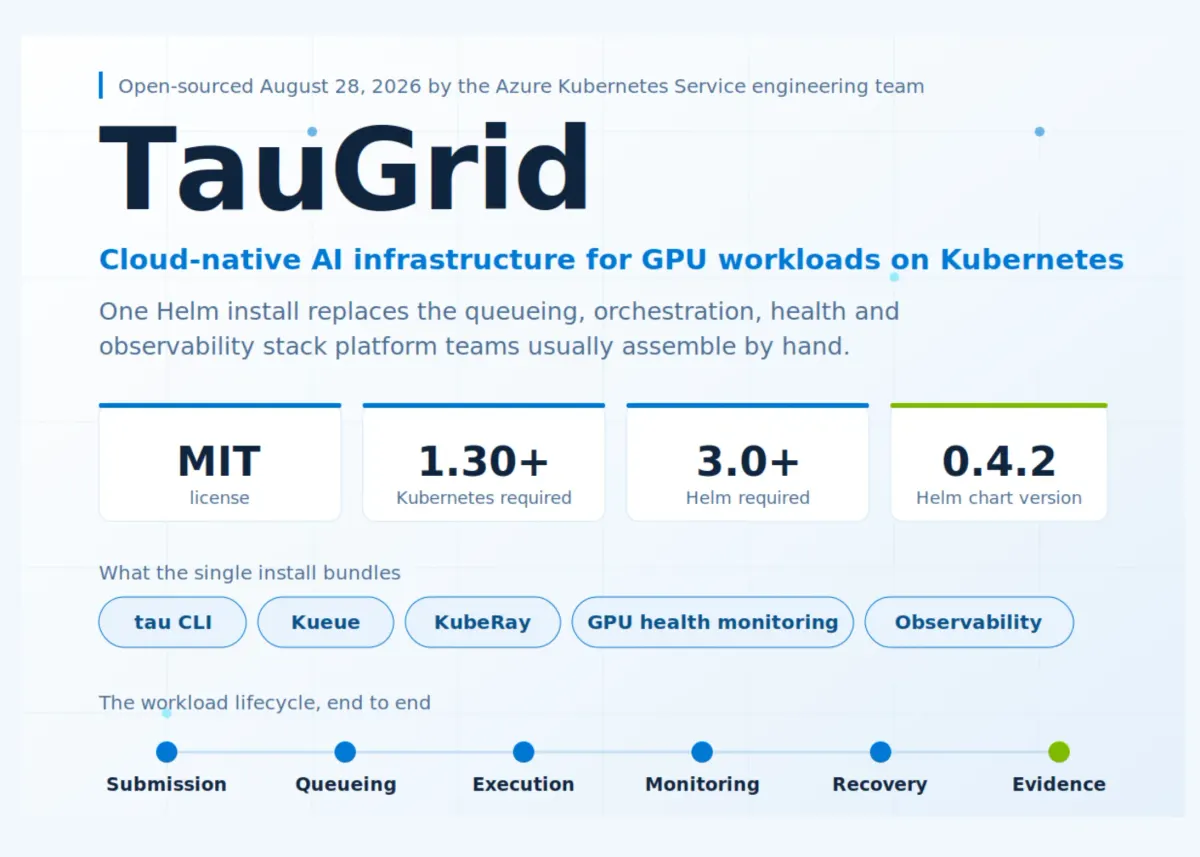
Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads
Platform teams running AI on Kubernetes rarely run one thing. They run a queueing system, a distributed runtime, GPU node health checks, dashboards, and a layer of submission scripts holding all of it together. The Azure Kubernetes Service engineering team open-sourced TauGrid, which collapses that assembly job into a single Helm install. Is it deployable? Yes, TauGrid is MIT licensed, with container images and Helm charts published as public OCI artifacts on Microsoft Container Registry. P
TauGrid is an open-source platform that simplifies running AI workloads on Kubernetes clusters by combining five components that platform teams typically have to assemble separately: a command-line interface, workload queueing, GPU cluster orchestration, GPU health monitoring, and observability tools. Platform teams define policies and infrastructure while researchers submit AI jobs through simple configuration files without needing to understand Kubernetes directly. The platform handles the stages of job submission, queueing, execution, monitoring, recovery through retries and checkpoints, and records evidence that makes runs reproducible and auditable. It can be installed on any Kubernetes cluster meeting basic version requirements and sends no telemetry to Microsoft by default.
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven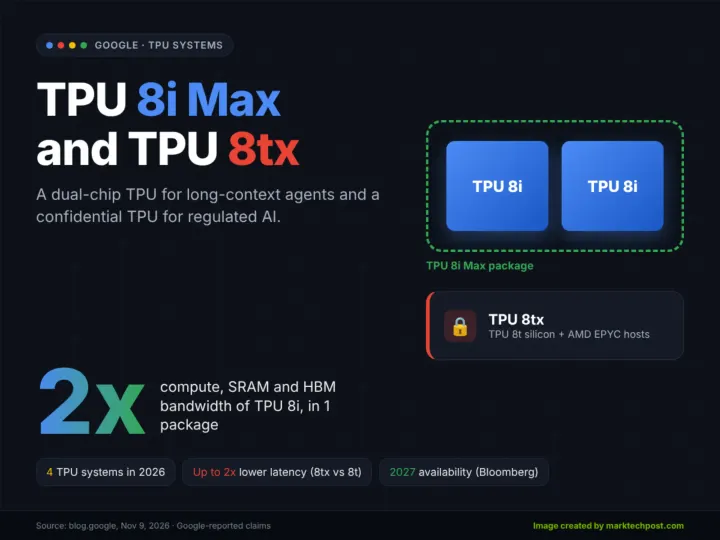
Google Unveils TPU 8i Max and TPU 8tx: A Dual-Chip TPU and a Confidential TPU
Google has added two new systems to its eighth-generation TPU lineup. TPU 8i Max targets massive context windows and rack density. TPU 8tx targets secure, confidential inference. Google TPU 8i Max is a dual-chip package built from 2 TPU 8i chips. Both arrive alongside TPU 8t and TPU 8i, announced in April. TL;DR Size: TPU 8i Max = 2 TPU 8i chips in 1 package. TPU 8tx = TPU 8t silicon plus 5th Gen AMD EPYC hosts. Runs on: Google Cloud TPU systems. Performance: 8i Max doubles TPU 8
Also reported by Data Center Knowledge
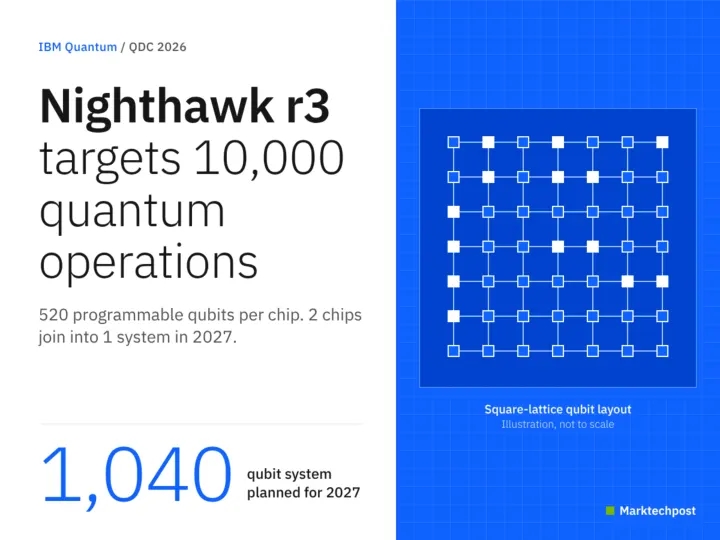
IBM Announces IBM Quantum Nighthawk r3: A New Processor to Support 10k Quantum Operations on 520 Programmable Qubits
IBM has announced IBM Quantum Nighthawk r3, its next superconducting quantum processor. It is designed to run 10,000 quantum operations accurately across 520 programmable qubits. In 2027, IBM plans to link 2 r3 chips into a single 1,040-qubit system. For developers, the announcement is speed. The current Nighthawk r2 already runs workloads up to 19x faster than IBM’s earlier processors. TL;DR Size: Nighthawk r3: 520 programmable qubits, 2,034 physical qubits, 10 l-couplers. Nightha

Why the data center you dread might never even be built
The data center boom is running into serious real-world obstacles, from widespread local opposition and permitting delays to a scramble for electricity. Before those challenges even come into play, though, there’s a more basic problem: A lot of the projects being announced may never get built in the first place. With billions of dollars in AI infrastructure […]

How backlash and red tape continue to slow data centers post-Blue Wave
The data center boom is running into serious real-world obstacles, from widespread local opposition and permitting delays to a scramble for electricity. Before those challenges even come into play, though, there’s a more basic problem: A lot of the projects being announced may never get built in the first place. With billions of dollars in AI infrastructure […]

AMD Launches Epyc SP7, Helion as AI Rack Demand Rises
AMD has begun shipping sixth-gen Epyc servers and is rolling out Helion AI racks, signaling a bigger push into enterprise and agentic AI infrastructure.

Google broadens its AI hardware portfolio with two new specialized chips
Google's new tensor processing units (TPUs) broaden its chip portfolio to more use cases: confidential model training and more memory capacity.