MLCommons releases AILuminate Safety 1.2.1
MLCommons: Test Your Own AI Against Real-World Risks and Attacks with AILuminate Safety 1.2.1 and Jailbreak 1.1
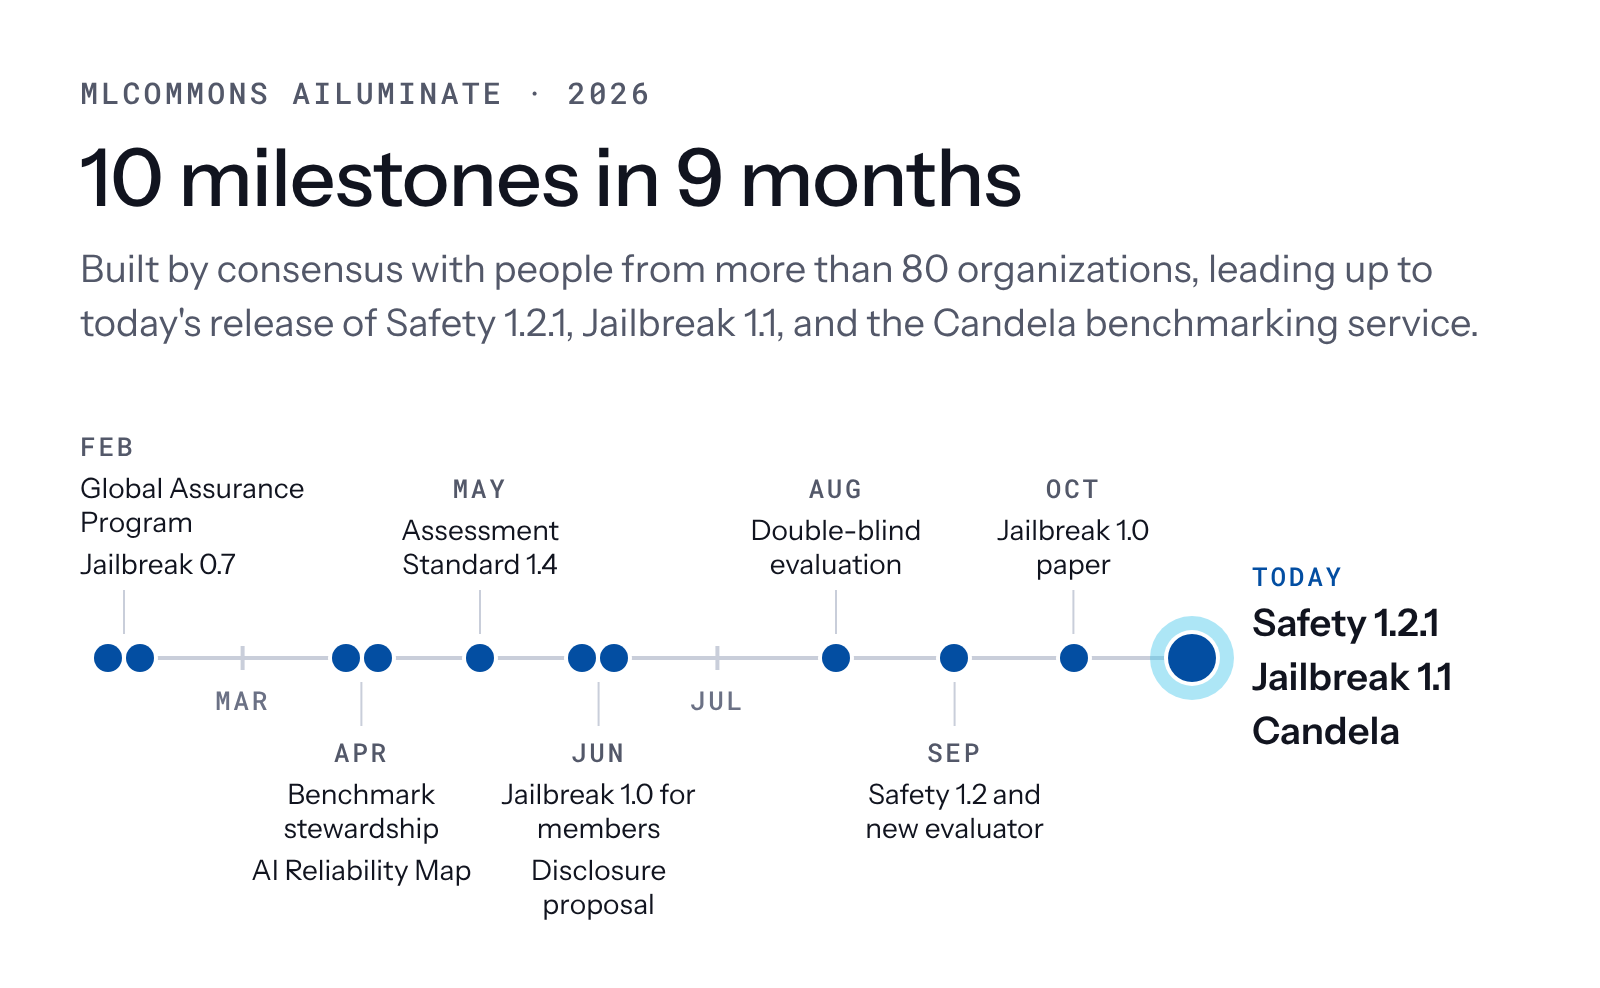
Developers and deployers can now test their own AI systems with AILuminate Safety 1.2.1 and AILuminate Jailbreak 1.1, two MLCommons benchmarks that measure how readily an AI system produces harmful content and how easily attackers can trick it into doing so, respectively. Both run on demand in Candela, the MLCommons benchmarking service that launches today, alongside new public benchmark results for 27 systems. AILuminate benchmarks are built by consensus: people from more than 80 organizati
Get smart on it
MLCommons has released updated versions of two benchmarks that test how safely AI systems handle harmful requests. AILuminate Safety measures whether AI systems refuse or safely redirect requests that could cause harm across categories like violent crime, hate speech, and medical misinformation, while AILuminate Jailbreak measures how easily attackers can manipulate systems into complying with those same harmful requests using published attack techniques. The benchmarks are built through consensus among developers, enterprises, researchers, and civil society groups, which makes their results trustworthy to regulators and AI buyers. These tools matter because real-world AI chatbots have already caused documented harms, from giving dangerous medical advice to spreading hateful content, making it important to measure and compare how well different systems resist such failures.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Mistral Says Its AI Model ‘Le Chonk’ Has Leapfrogged China in the Open-Weight Race
The French AI lab claims its latest release matches or outperforms even the best models from DeepSeek and Z.ai in coding and cybersecurity.

OpenAI announces three big science discoveries and a new way to work with academics
Less than a month after its mass release of hundreds of manuscripts that it said contained solutions to long-standing mathematics questions, OpenAI is back with three more "major" discoveries in math, computer science, and physics. What's different this time is the choice to have external experts that OpenAI describes as "shepherds" guiding the results in computer science and physics, while for the math problem it says that they advised it to release the AI output for researche
Also reported by The Decoder
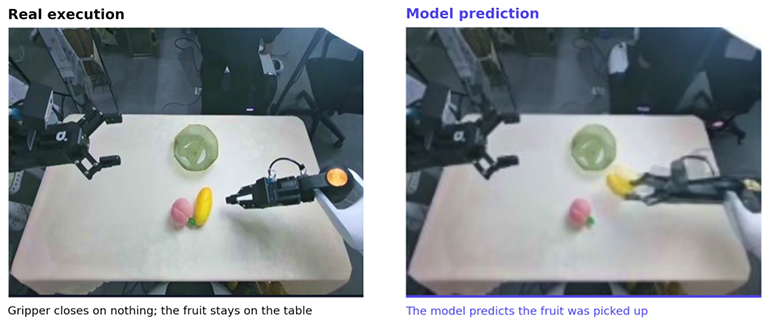
WorldOracle Tests Whether World Models Can Reliably Predict Real-World Executions
Key Takeaways WorldOracle is a benchmark for action-conditioned world models (ACWMs) that scores each model’s predicted rollout against the paired real-world execution, with both starting from the same initial observations and following the same action sequence. Seven representative models were evaluated; arm motion was predicted relatively well, but object positions and movements often deviated from reality, and performance dropped over complete operation sequences. The platform opened t

Frontier AI labs say their models refuted the Exponential Time Hypothesis. What does that mean?
TechCrunch spoke to the MIT computer scientist charged with explaining OpenAI's latest mind-bending discovery

Working with academic communities to build scientific understanding
OpenAI shares model results on the Kakeya conjecture, Exponential Time Hypothesis, and quantum chromodynamics—and how researchers can verify and build on them.
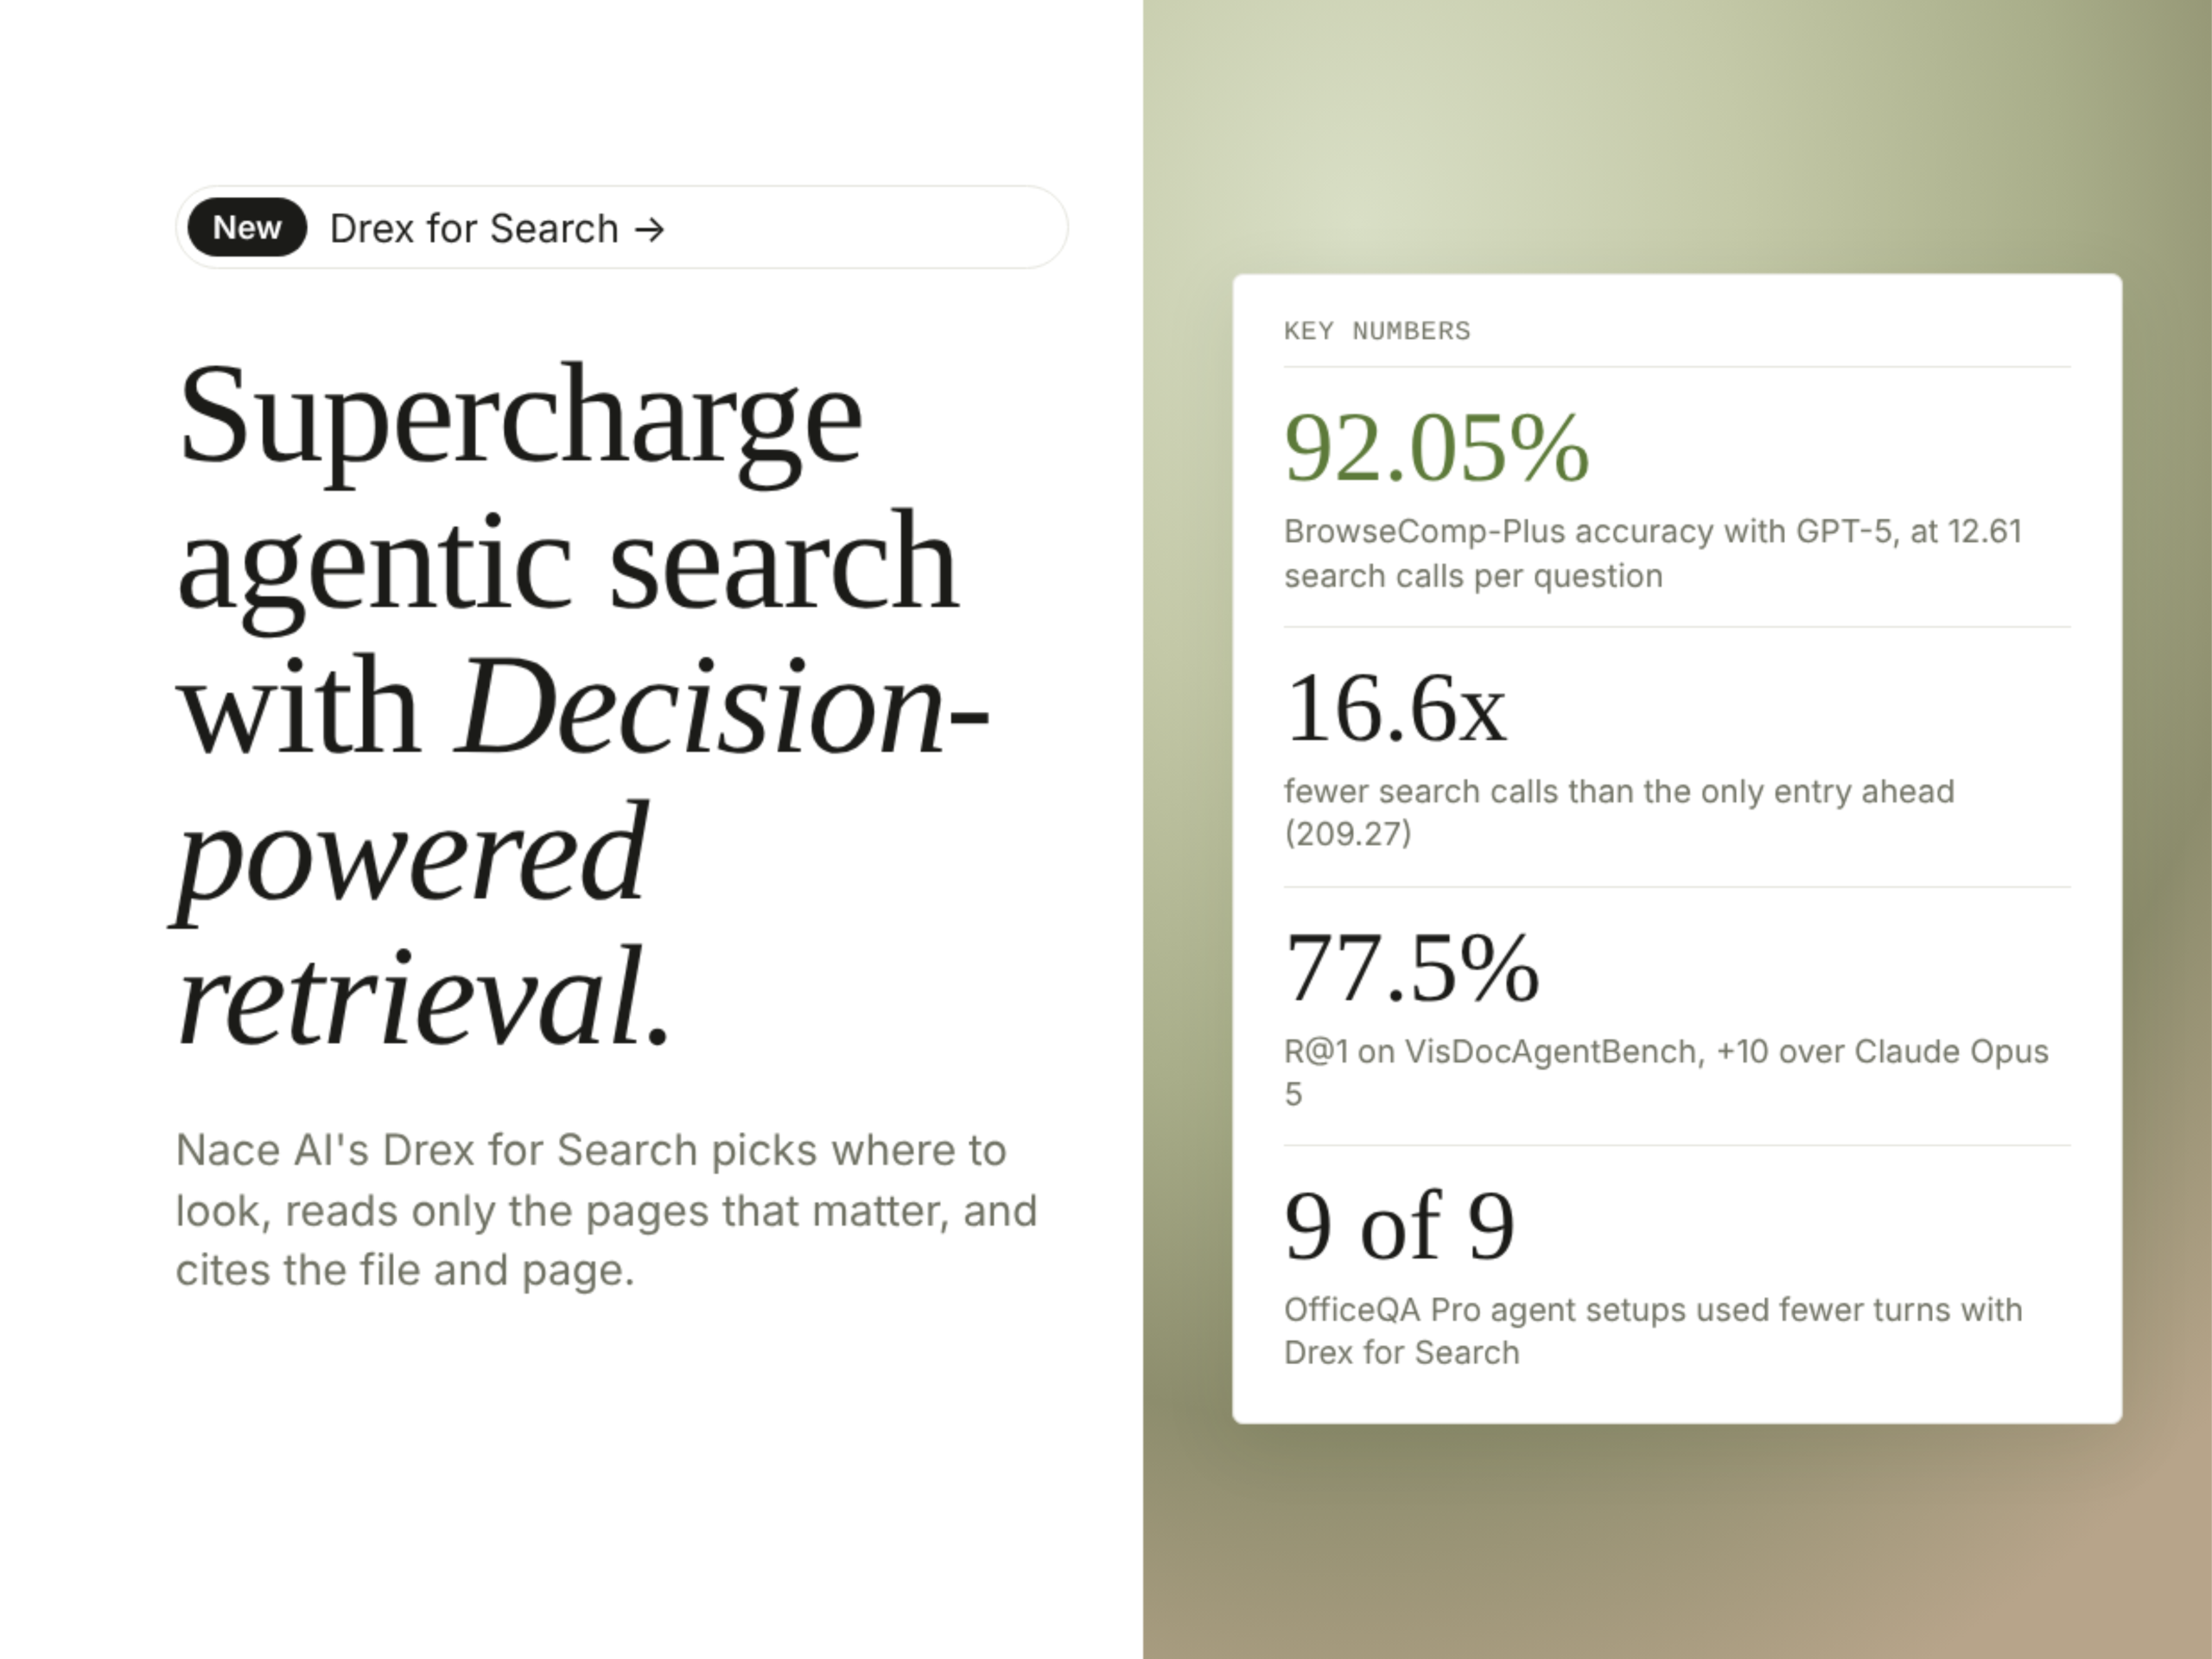
Nace AI Releases Drex for Search for AI Agents: 92.05% on BrowseComp-Plus With 12.6 Search Calls
Nace AI has released Drex for Search, which brings its Drex decision models to document search. Drex for Search is a retrieval layer that helps people and agents find evidence. Coding agents such as Claude Code, Codex, Cursor and OpenCode call it through CLI, SDKs, MCP or REST. In Nace’s evaluation, it scores 92.05% on BrowseComp-Plus with GPT-5, using 12.6 search calls per question. TL;DR Size: a hosted search system built to search over 1M+ files. It pairs with an answering model