MLCommons to develop MLPerf Agents benchmark with NSF funding
MLCommons: MLCommons Selected as Benchmarking Team for U.S. National Science Foundation–Backed AI Efficiency Challenge to Build MLPerf Agents
MLCommons has been selected as the Benchmarking Team for the STRIDE Ventures AI Efficiency Challenge, a program supported by the U.S. National Science Foundation Directorate for Technology, Innovation and Partnerships (NSF TIP). Through a $3.5 million award over two years, MLCommons will develop MLPerf Agents, a new benchmark that measures how efficiently agentic AI systems get real work done — from a delegated goal all the way to a verified outcome As a nonprofit consortium composed of comp
Get smart on it
MLCommons, a nonprofit consortium, has been selected to develop MLPerf Agents, a new benchmark tool funded by a multi-year award from the U.S. National Science Foundation. This benchmark will measure how efficiently agentic AI systems complete full workflows, from initial task to verified outcome, across components like model selection, tool use, and failure recovery. Existing benchmarks measure only individual model performance, but agentic AI works differently by operating across multiple turns and making tool calls, so a broader measurement approach is needed. MLPerf Agents will track cost, energy, and latency for successfully completed tasks and enable comparable results across different AI system architectures.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

The AI race is back on
Last week, Anthropic and OpenAI looked like they had the AI race to themselves, pulling ahead with increasingly powerful models that left their rivals in the dust. Google seemed hopelessly far behind, while Meta, despite spending billions to revive its floundering AI ambitions, had yet to establish itself as a serious contender. Even the latest models coming out of China, impressive as they were, appeared to be playing catch-up. Then, in the space of a few days, everything chan

Grok Voice 3.0 from SpaceXSI outscores OpenAI and Google on speech-to-speech index
Elon Musk’s artificial intelligence company SpaceXSI, formerly xAI, today released Grok Voice 3.0, a new version of the speech-to-speech model behind its Voice Agent API. SpaceXSI is pitching the model to businesses that handle customer support and sales calls with voice agents. Independent testing firm Artificial Analysis ranks it first among models of its type. Artificial […] The post Grok Voice 3.0 from SpaceXSI outscores OpenAI and Google on speech-to-speech index appeared first
Also reported by MarkTechPost
Google Deepmind's AlphaProof Nexus solved dozens of open math problems and actually got peer reviewed
Google Deepmind's AlphaProof Nexus solved dozens of open math problems, including nine Erdős problems two of which were unsolved for 56 years, per a study in Science. The publication comes as OpenAI faces a boycott for dumping AI proofs on GitHub without peer review. Deepmind had its results reviewed before publishing. The article Google Deepmind's AlphaProof Nexus solved dozens of open math problems and actually got peer reviewed appeared first on The Decoder.
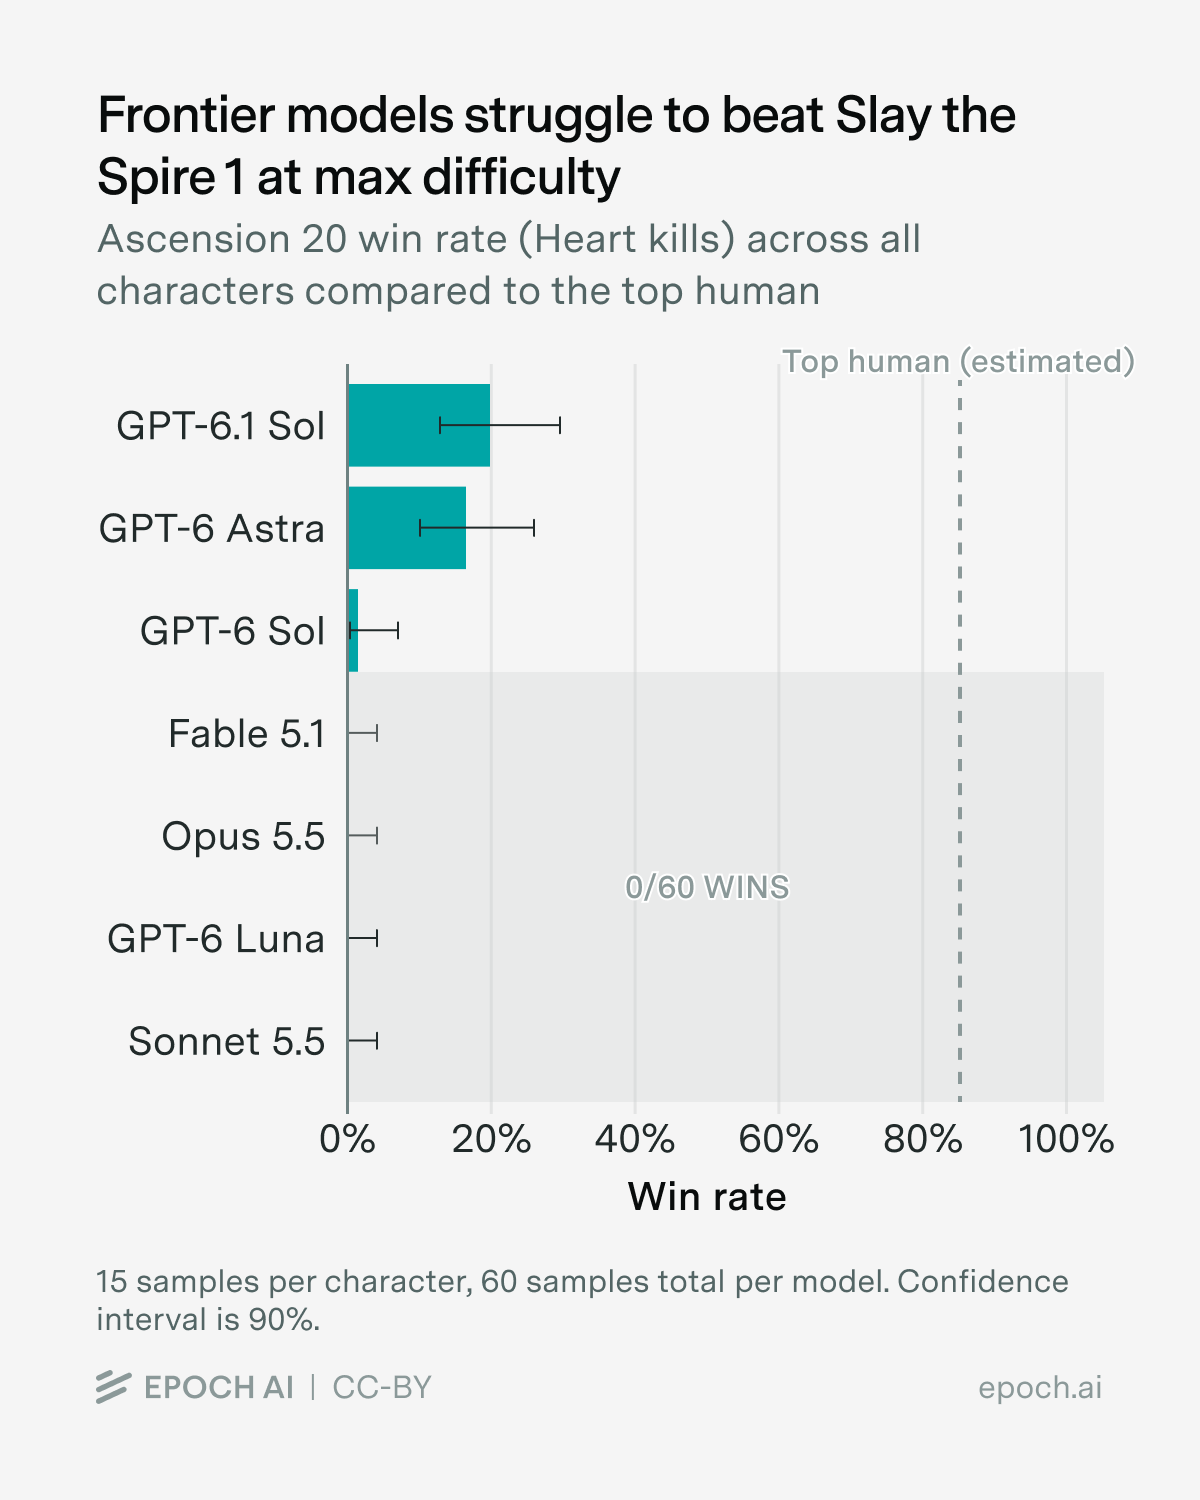
How well can AI play Slay the Spire?
Months ago, frontier models could barely beat Slay the Spire. Now they win 90%+ at the easiest setting and up to 20% at the hardest. Results from Epoch AI’s new SpireClimb benchmark.
AI guardrails designed to stop hackers are now blocking defenders, and Orion-1 aims to fill the gap
Artemis Security's new Orion-1 model is purpose-built for cyber defense and beats Claude Opus 5.5 and GPT-6 Sol on the company's own benchmark. The model fills a growing gap as general-purpose frontier models lock down their cyber capabilities, blocking defenders in the process. The article AI guardrails designed to stop hackers are now blocking defenders, and Orion-1 aims to fill the gap appeared first on The Decoder.

Open, peer-reviewed measurement for today’s AI buyers: MLPerf in the EU’s AI Gigafactories tender, and Endpoints v1.0 opens for submissions
As AI adoption is growing across the economy, AI buyers are asking a more complex set of questions about AI systems than simply a chip’s speed. They want to know what performance a deployed service will deliver, what it will cost for given workloads, and how much energy it will use. MLPerf has been the standard-bearer for measuring AI system performance since 2018; it’s evolving to address these more complex questions for every AI buyer. First, out of Europe: MLPerf has been chos