
Hebbia sees improvements in financial research with GPT-6 Astra
Hebbia tested GPT-6 Astra for financial research. Its prerelease evaluations found gains in source coverage, citation relevance, and presentation quality.
A financial research startup tested a new AI model to improve how bankers analyze acquisition deals by finding relevant source documents and creating presentation slides. The model scored higher than alternatives on two key measures: citing the right types of sources with relevant excerpts and meeting presentation formatting requirements that make outputs look professionally made rather than AI-generated. This matters because bankers base million-dollar decisions on AI outputs, so accurate citations and proper formatting reduce time spent verifying and reformatting while increasing confidence in the results.
- AI claimed a solution to the 167 year-old Riemann Hypothesis, and a human did, too · TechCrunch
- MLPerf Training v6.1: Bigger Clusters, Broader Hardware, and the Rise of Software-Driven Gains · MLCommons
- Can AI help scientists identify promising drug candidates? · OpenAI
- All of today’s AI news, biggest first →
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven
AI claimed a solution to the 167 year-old Riemann Hypothesis, and a human did, too
Mathematicians are having their minds blown by the latest AI-driven result—and there's a competing human solution, too.
Also reported by SiliconANGLE
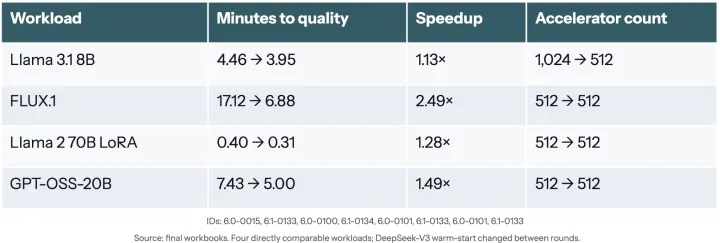
MLPerf Training v6.1: Bigger Clusters, Broader Hardware, and the Rise of Software-Driven Gains
The round at a glance MLPerf® Training v6.1 expands the benchmark suite and features even larger systems from our members. Two benchmarks join the suite: Qwen3.5-397B GRPO for agentic reinforcement learning, and DLRMv4-HSTU, a generative recommender. Google’s Ironwood and NVIDIA’s Rubin make their debut as Available systems. The largest jobs reached 10,240 GPUs (NVIDIA on GB300 and Azure on GB200, both training DeepSeek-V3) [1, 2], multi-node systems rose to 76% of the total, and the hardwar

Can AI help scientists identify promising drug candidates?
MedChemBench evaluates how well AI models interpret molecular structures, reason from experimental evidence, and select compounds in early drug discovery.
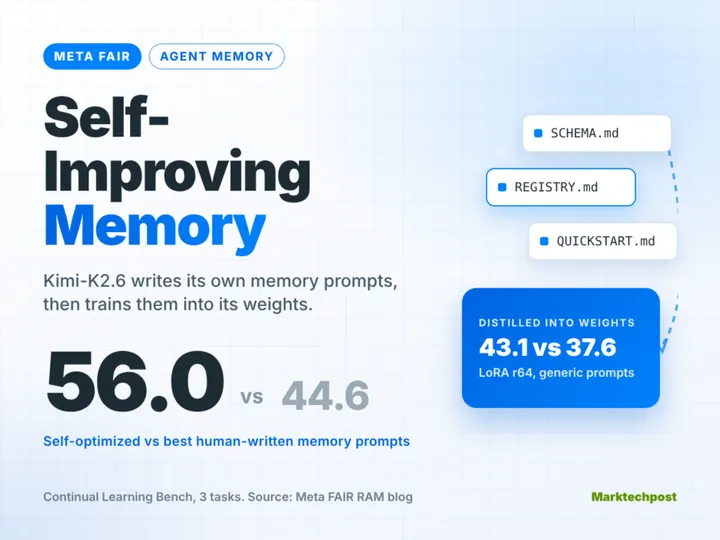
Meta FAIR Self-Improving Memory Hits 56.0 on Continual Learning Bench
Meta FAIR has introduced Self-Improving Memory, a method for AI agents that manage their own memory. The model first discovers its own memory instructions. It then trains those skills into its weights. Co-authors include researchers from the University of Washington and Johns Hopkins University. TL;DR Method: The base is Kimi-K2.6, a 1T-parameter MoE with 32B active and 256K context. Distillation adds a LoRA adapter (rank 64) on attention projections. Runs on: Training hardware is no
Research acceleration: The jagged frontier
OpenAI measures how coding agents are accelerating AI research, where their performance remains uneven, and what this signals about recursive self-improvement.
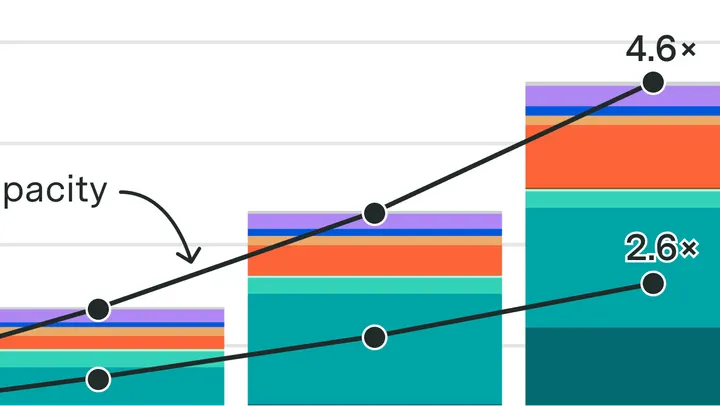
Agentic inference capacity grew 4.6× in a year, versus 2.6× for compute capacity
Our Inference Performance Index and chip sales data show agentic inference capacity grew nearly twice as much as 8-bit compute.