
Experts say exploiting Anthropic’s Fable isn’t how Kimi K3 got so good
"I don't think you get a model this strong and this quickly on the heels of Fable doing strictly distillation," one expert told TechCrunch.
A White House science advisor accused a Chinese AI company of copying a U.S. model while using export-banned chips, sparking debate about whether this explains the Chinese company's advanced capabilities. However, experts are skeptical that the copying method described would be sufficient to produce such a strong model in the short timeframe involved, noting that the required advanced techniques would be prohibitively expensive and time-consuming. The debate reflects broader concerns about access to advanced chips and whether frontier AI models from other countries contribute to Chinese AI development, though distillation is acknowledged as a common practice across the industry rather than unique to China.
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven
Google DeepMind just mathematically verified key parts of Signal
Google DeepMind researchers used agentic AI to mathematically prove, or “formally verify,” a number of the Signal protocol’s key cryptographic guarantees—a landmark development for the widely used cryptography and AI itself. Conducted as a sort of proof-of-concept project in just four weeks, the work is significant in two ways. It serves as further independent validation of the cryptography that protects massive quantities of the world's communications on platforms like the Signal app, Google Me
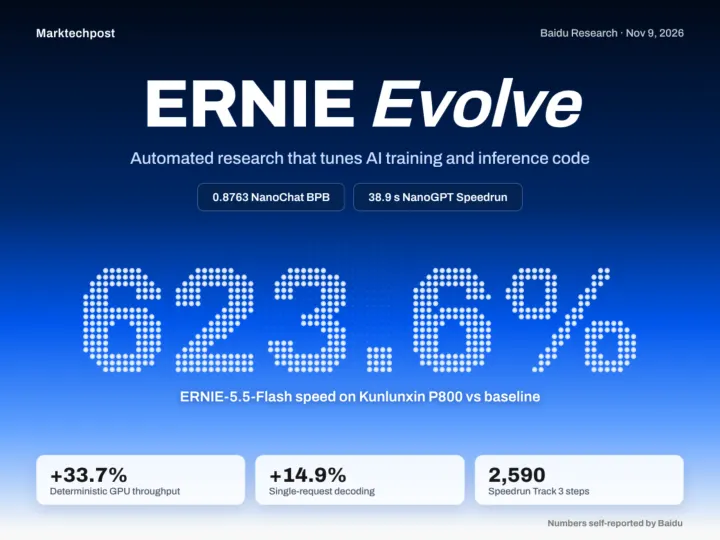
Baidu’s ERNIE Evolve Automated Research System Beats NanoChat and NanoGPT Records
Baidu has just released ERNIE Evolve, an automated research system that improves AI training and inference code. Given a repository, an objective and evaluation criteria, it picks research directions, edits code and runs experiments. Only changes that pass a hidden evaluator and a separate reviewer are kept. Baidu team tested the ERNIE Evolve automated research system on three public benchmarks. It then optimized inference for ERNIE-5.5-Flash, still in development. TL;DR Size: It is an
AI coding agents still need human cleanup on nearly three out of four tasks in a real-world test
Alibaba's new coding-agent benchmark, Co-Design Bench, tests AI agents on real user requests that already tripped them up in practice. Even GPT-6 Astra, the top performer, fully solves only 26.4 percent of tasks. On older benchmarks, the same models score above 99 percent. The article AI coding agents still need human cleanup on nearly three out of four tasks in a real-world test appeared first on The Decoder.
The gap between open and closed AI models in cyber capabilities keeps shrinking
In the Vals AI benchmark, OpenAI's GPT-6 Sol Daybreak hits 80.8 percent of attack objectives in simulated corporate networks. Worse, the open-weight model DeepSeek V4.1 Flash reaches 72.8 percent at a tenth of the cost. Because open models can no longer be restricted, analysts say the window for defenders is shrinking fast. The article The gap between open and closed AI models in cyber capabilities keeps shrinking appeared first on The Decoder.
Nine AI agents tried autonomous research on open questions from US national labs and none passed the experts' bar
The "Into the Unknown" benchmark tasks nine AI agents with tackling open research questions from U.S. national laboratories. None of the 135 submissions meets all requirements. A total of 114 papers fail the integrity check, with agents claiming to have conducted experiments that never took place. GPT-6 Astra performs best but still doesn't meet the experts' standards. The article Nine AI agents tried autonomous research on open questions from US national labs and none passed the expert
Ripple-65B Preview delivers strong agentic coding results as a fully Apache 2.0 open US model
Ricursive Intelligence is releasing Ripple-65B Preview, a 65-billion-parameter open-weight language model that the company says achieves the top score among open-source U.S. models on the TerminalBench 2.1 coding benchmark at a total R&D cost of $32 million. On other benchmarks, however, Ripple falls behind the likewise newly released western open model Inkling 2 Small. The article Ripple-65B Preview delivers strong agentic coding results as a fully Apache 2.0 open US model appeare