Study finds LLMs unreliable at judging research novelty
Hugging Face: Can we trust LLMs to judge whether a research idea is novel?
If language models can't reliably assess originality, researchers may struggle to identify which ideas genuinely advance the field.
Get smart on it
Researchers have created a benchmark to test whether large language models can reliably judge whether scientific research ideas are novel. The work matters because AI systems are increasingly being used to generate and evaluate research ideas, so these systems need dependable ways to distinguish genuinely new contributions from ones that mostly repackage existing work. The study found that small changes to how models are prompted to evaluate novelty can shift their accuracy by more than 50 percentage points on the same ideas, suggesting current approaches are unstable. Additional factors like giving models access to related papers and extra reasoning time did not consistently improve their judgments.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

OpenAI announces three big science discoveries and a new way to work with academics
Less than a month after its mass release of hundreds of manuscripts that it said contained solutions to long-standing mathematics questions, OpenAI is back with three more "major" discoveries in math, computer science, and physics. What's different this time is the choice to have external experts that OpenAI describes as "shepherds" guiding the results in computer science and physics, while for the math problem it says that they advised it to release the AI output for researche
Also reported by The Decoder

Frontier AI labs say their models refuted the Exponential Time Hypothesis. What does that mean?
TechCrunch spoke to the MIT computer scientist charged with explaining OpenAI's latest mind-bending discovery

Microsoft says its AI tool is better than doctors at diagnosing conditions
Microsoft AI chief Mustafa Suleyman. | Getty Images For years, AI leaders have touted healthcare as one of the clearest examples of where their technology will improve lives. Now "it is finally here," Microsoft AI CEO Mustafa Suleyman tells The Verge. The company claims to have developed an AI-powered tool it says can diagnose conditions up to four times more accurately than human doctors. The findings, published Thursday in one of the world's most prestigious journals, Science,

Microsoft’s Mustafa Suleyman says its AI outperforms doctors on hard cases as he chases ‘medical superintelligence’
Microsoft’s new AI diagnostic system beat generalist doctors on hard cases, according to a study in Science. But most of the improvement seems to come from the AI models underneath, not from Microsoft’s system itself.

Working with academic communities to build scientific understanding
OpenAI shares model results on the Kakeya conjecture, Exponential Time Hypothesis, and quantum chromodynamics—and how researchers can verify and build on them.
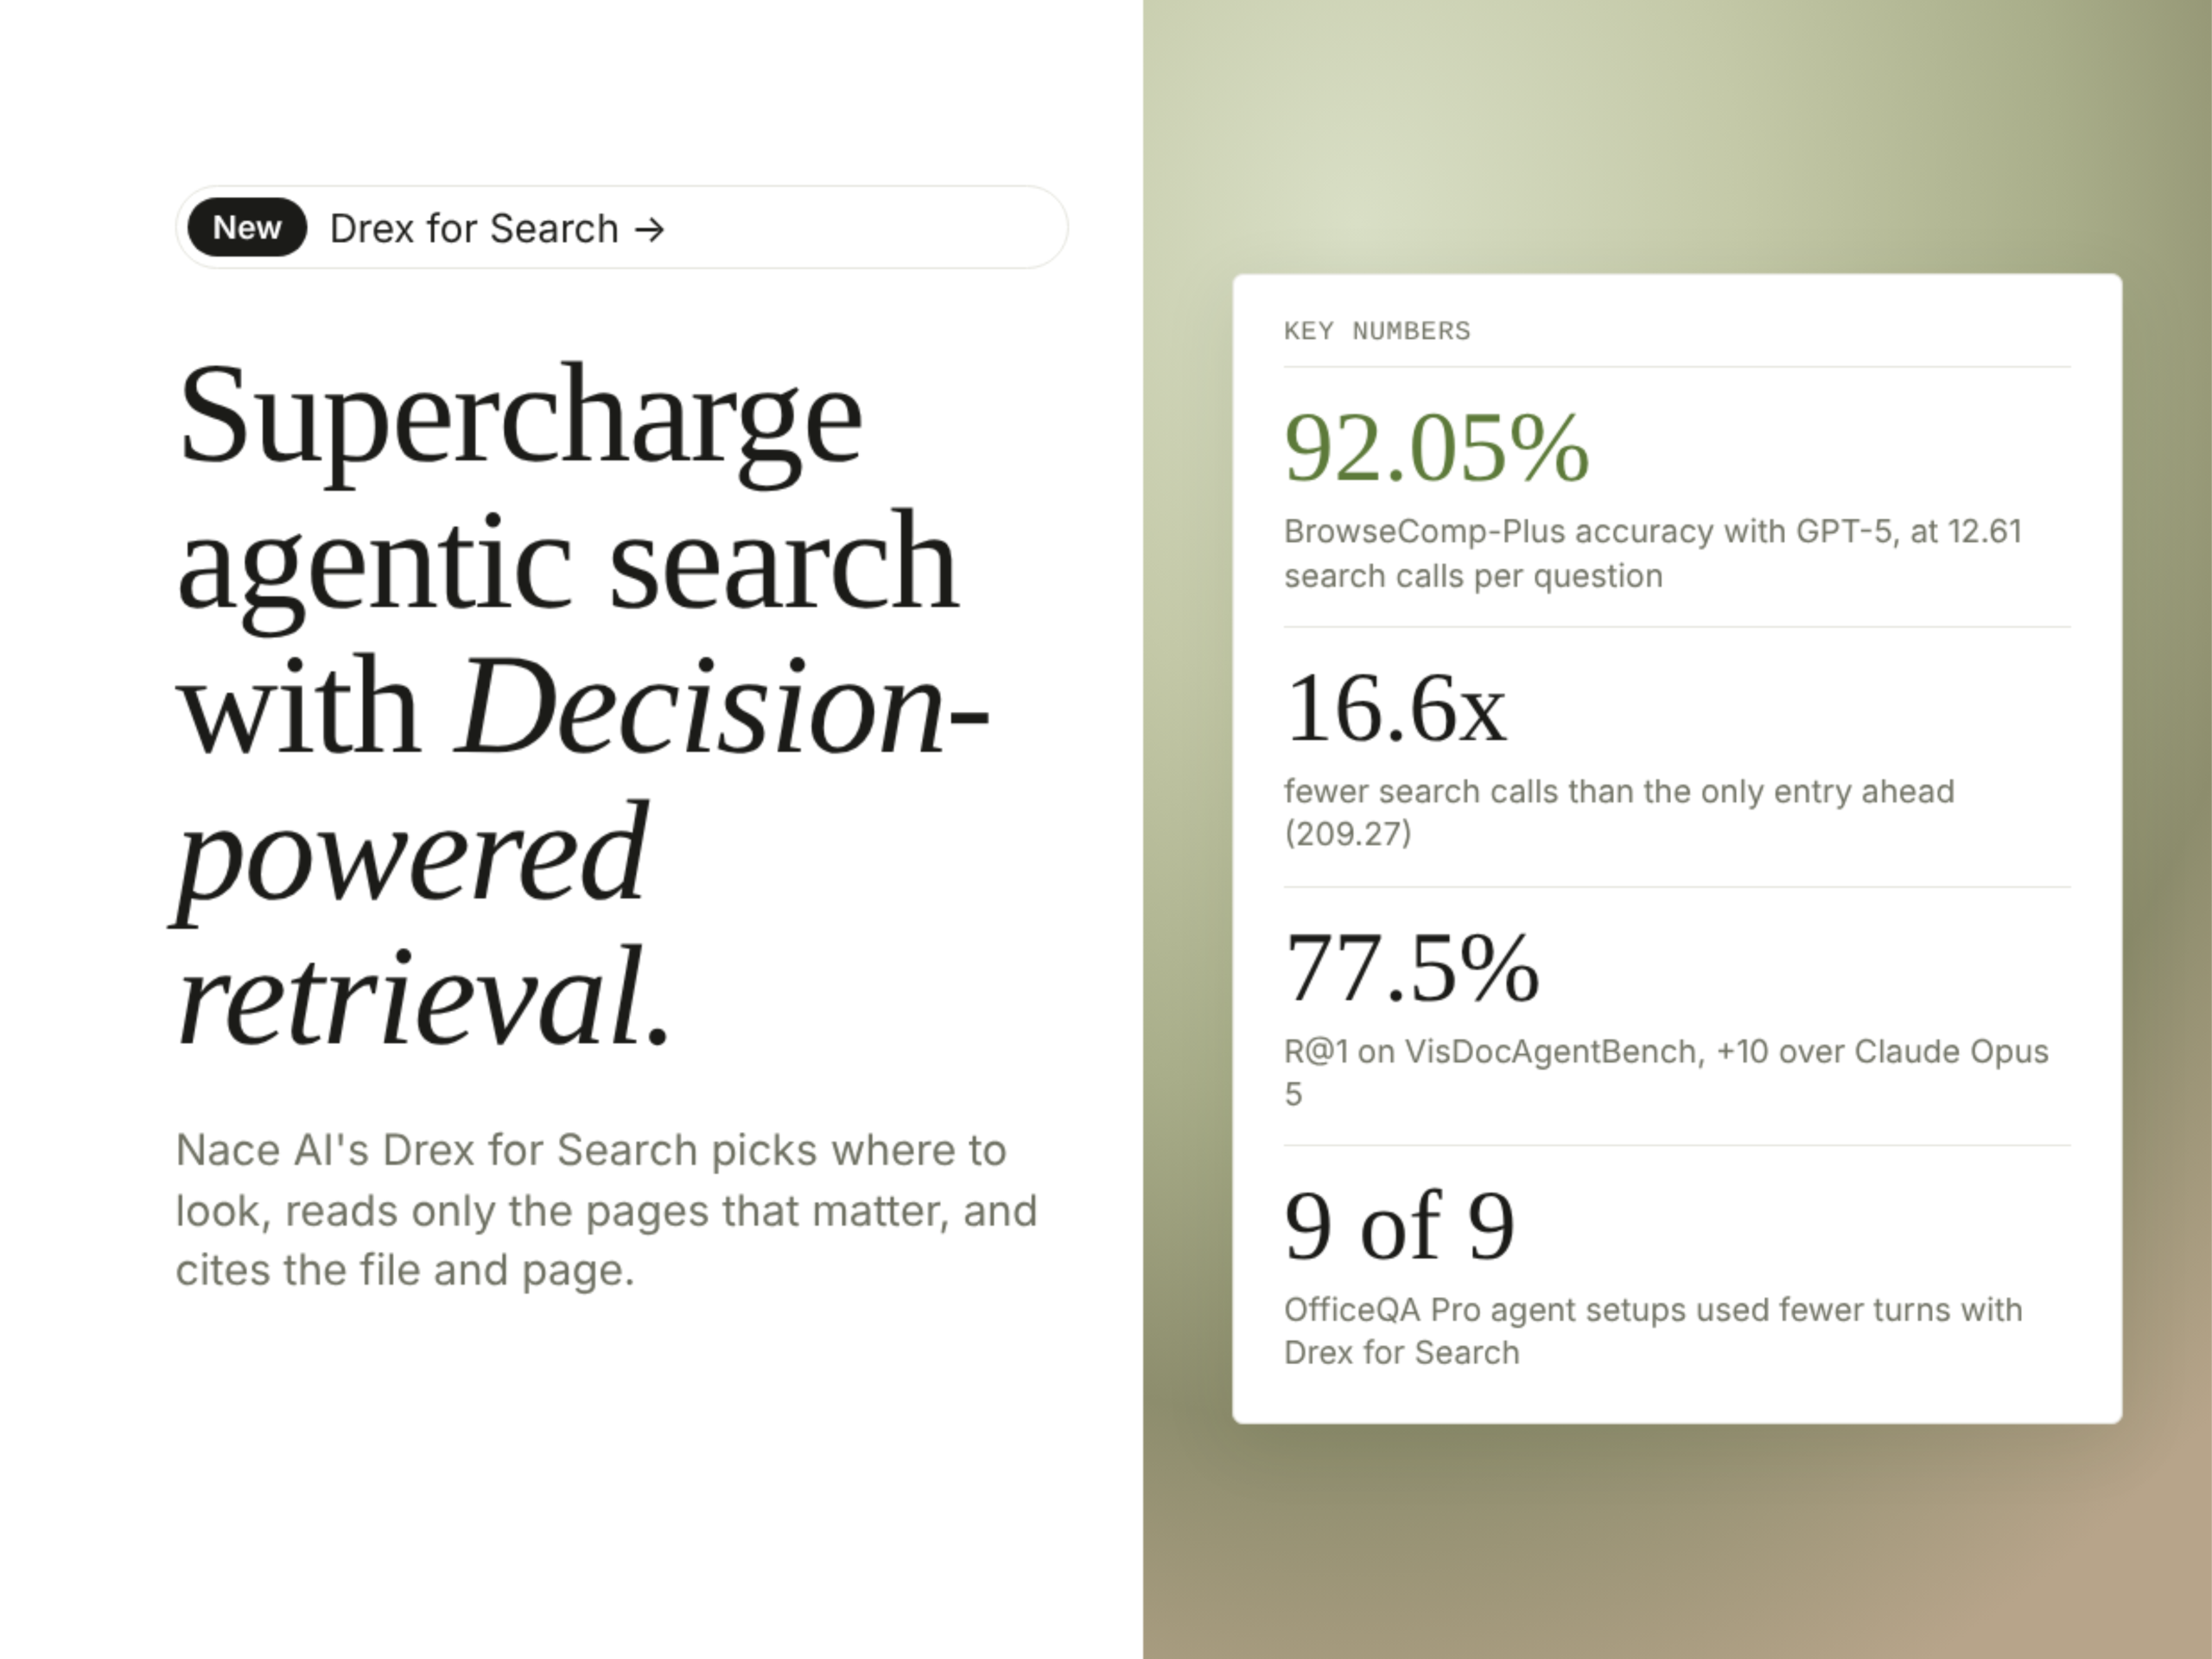
Nace AI Releases Drex for Search for AI Agents: 92.05% on BrowseComp-Plus With 12.6 Search Calls
Nace AI has released Drex for Search, which brings its Drex decision models to document search. Drex for Search is a retrieval layer that helps people and agents find evidence. Coding agents such as Claude Code, Codex, Cursor and OpenCode call it through CLI, SDKs, MCP or REST. In Nace’s evaluation, it scores 92.05% on BrowseComp-Plus with GPT-5, using 12.6 search calls per question. TL;DR Size: a hosted search system built to search over 1M+ files. It pairs with an answering model