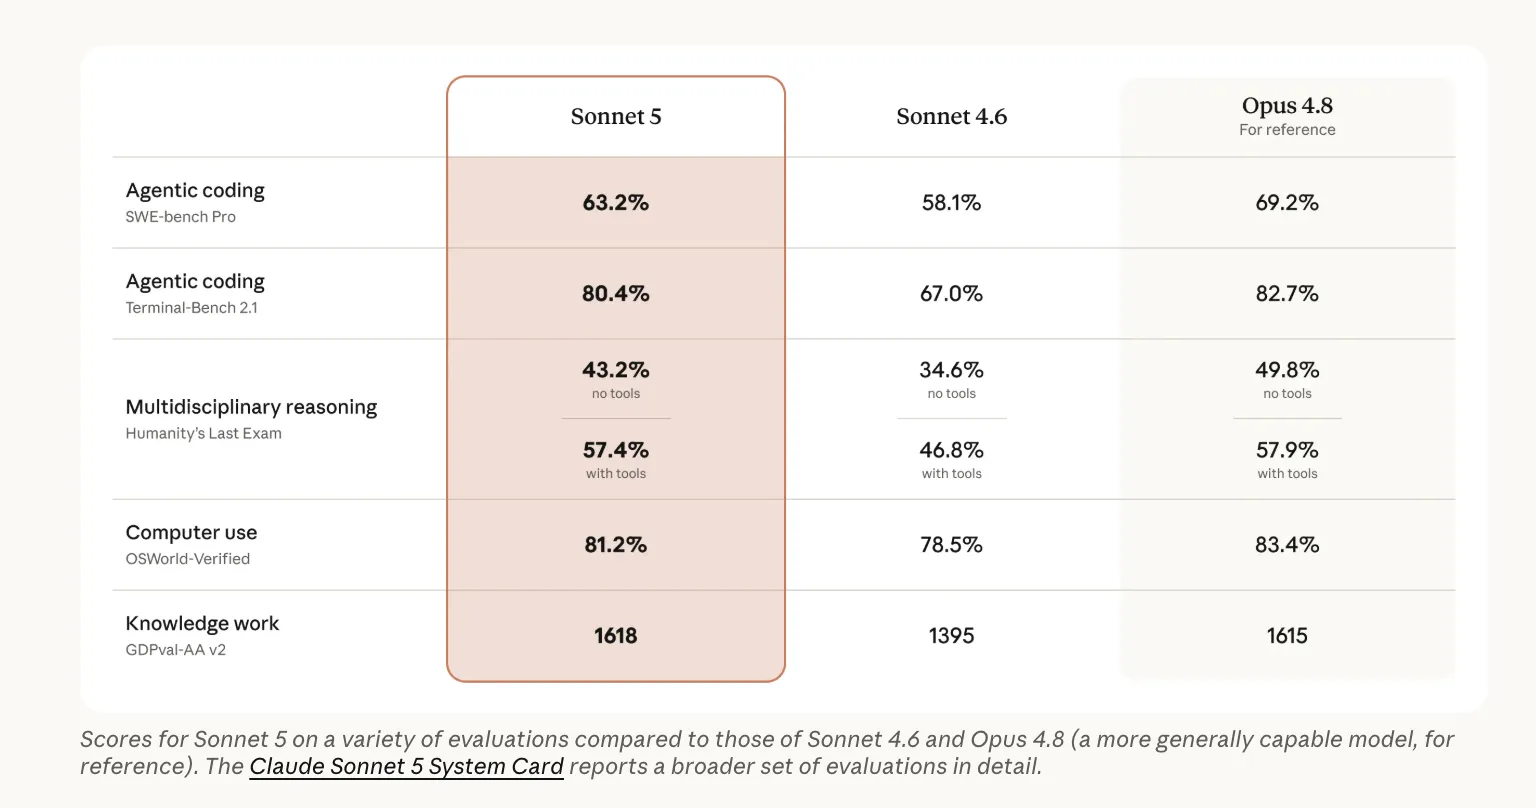
Anthropic Claude Sonnet 5 vs Sonnet 4.6 vs Opus 4.8: Agentic Coding Benchmarks, API Pricing, and Cost-Performance Tradeoffs Compared
Anthropic just shipped Claude Sonnet 5. They call it its most agentic Sonnet model yet. It plans, drives browsers and terminals, and runs autonomously across long tasks. Sonnet 5 is the default model for Free and Pro plans today. Max, Team, and Enterprise users can select it. It is also live in Claude Code and on the Claude Platform. TL;DR Sonnet 5 is Anthropic’s most agentic mid-tier model, closing much of the gap to Opus 4.8. Beats Sonnet 4.6 on every published benchmark: 6
Get smart on it
Anthropic released Claude Sonnet 5, a mid-tier AI model positioned between its cheaper and flagship offerings, designed to handle longer tasks and maintain better performance during extended work sessions. The model outperforms its predecessor across all published benchmarks, including agentic coding, computer use, and terminal tasks, though its flagship model still leads in most categories. Introductory pricing through August makes Sonnet 5 cheaper to run than the flagship model, creating a cost-performance tradeoff where it offers the best value for routine tasks but may cost more than the flagship option for very demanding work. The model introduces effort levels that allow users to spend more computational resources for higher quality outputs, with the choice of effort level directly affecting both task quality and cost.
Explainer: An AI Agent Just Operated on a Live Mouse Brain. Here's What Actually Happened.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Google launches Gemini 4 Carbon with a ‘significant leap’ in cybersecurity
Google has released its latest frontier model, Gemini 4 Carbon, offering "significant gains" in coding, agentic tasks, and cybersecurity. In an announcement on Wednesday, Google highlights Carbon's top spot on the Artificial Analysis Intelligence Index (v5.0) benchmark, with Claude Opus 5.5 and GPT-6 Astra trailing behind. The new Gemini 4 Carbon model offers improvements over Argon, which Google released earlier this month. It's currently only available to a select group of cy
Also reported by The Decoder and SiliconANGLE

LifeVal
Introducing LifeVal, a benchmark measuring how well AI helps people complete everyday tasks, from finding childcare to managing finances and government paperwork.
Mistral Says Its AI Model ‘Le Chonk’ Has Leapfrogged China in the Open-Weight Race
The French AI lab claims its latest release matches or outperforms even the best models from DeepSeek and Z.ai in coding and cybersecurity.
GDPx: Measuring Frontier Model Capabilities Across the Most Valuable Domains
GDPx is a benchmark that covers the most valuable domains for frontier intelligence. It aims to be the world’s best benchmark for measuring general agentic capabilities.We believe the first trillion dollars of AI revenue will be concentrated in sectors that can deploy frontier intelligence at high ROI, not broadly diffused throughout the whole economy. Building a general-purpose benchmark based on share of GDP or the SOC/O*NET occupational taxonomy is therefore a mistake. If your goal is t
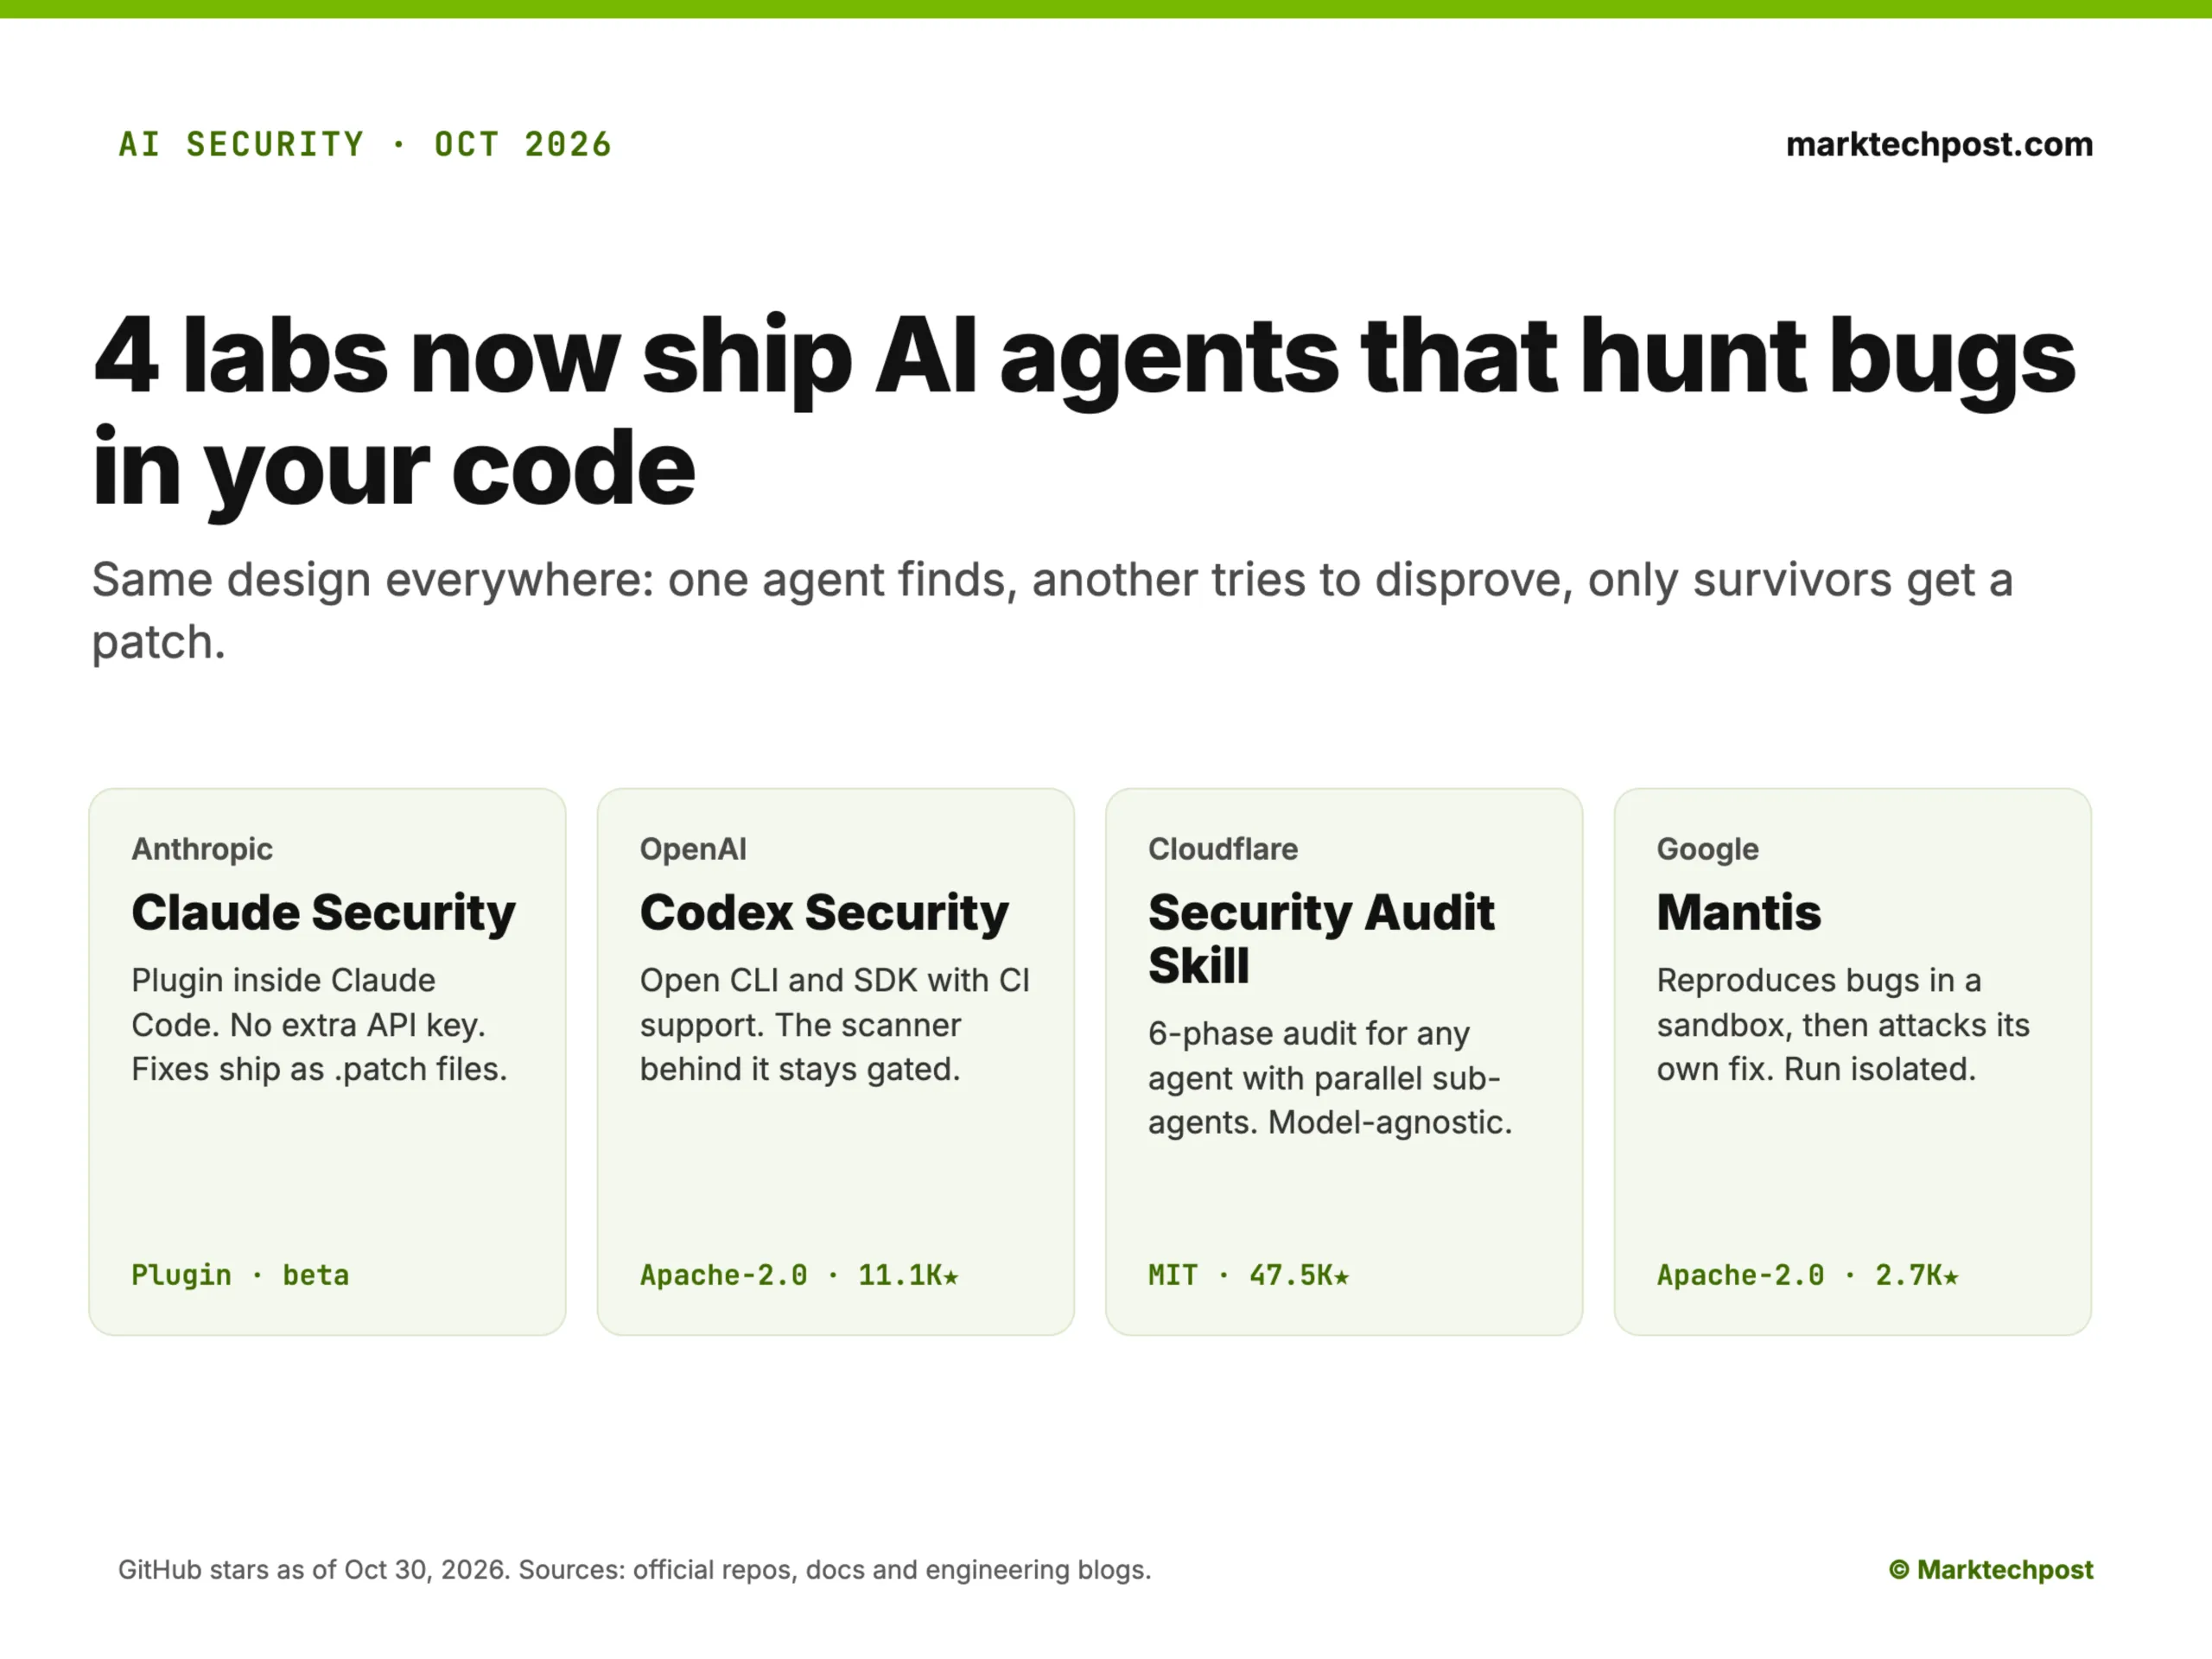
AI Security Agents Compared: Claude, Codex, Mantis, Cloudflare
Anthropic, OpenAI, Cloudflare and Google now each ship an AI agent that hunts security bugs in source code. We checked the repos, docs and technical details behind each one. The key finding: all 4 tools converge on one design. One agent finds a bug, a separate agent tries to disprove it, and only survivors get a patch. The differences are in where they run, who can use them and how much proof they demand. Key Takeaways 4 labs, 1 pattern: find, independently disprove, then patch. Cl
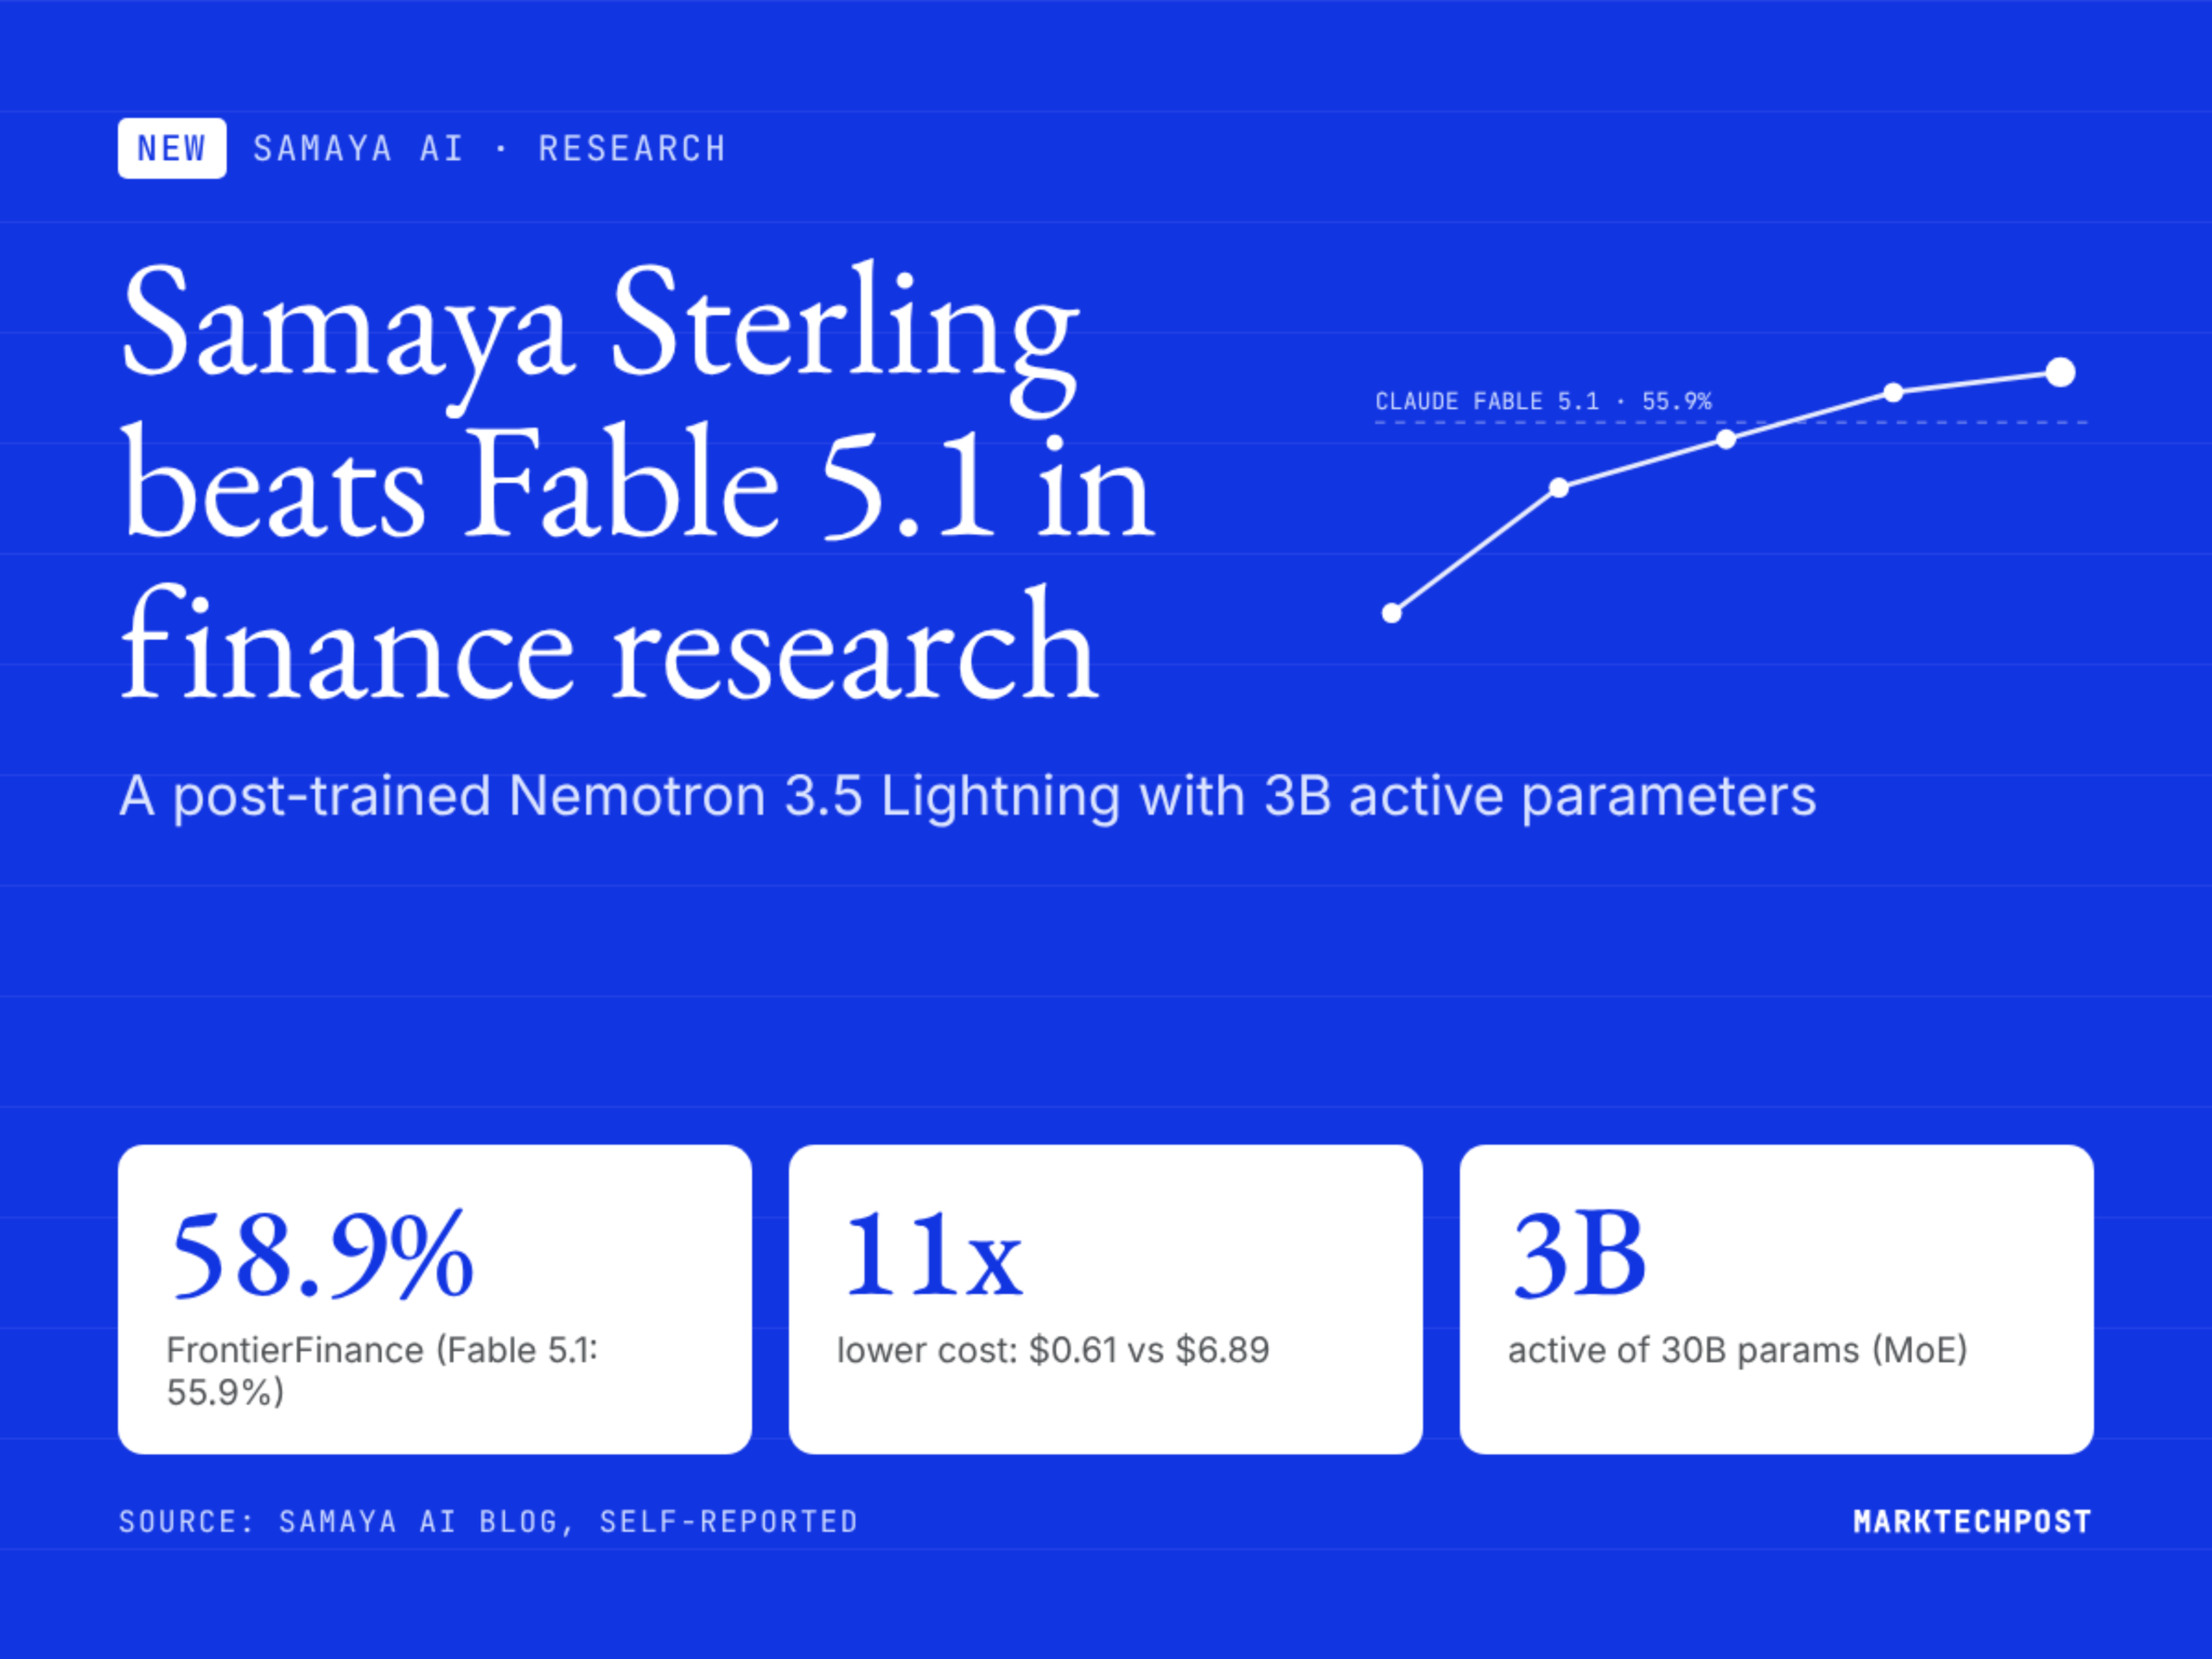
Samaya AI Releases Sterling: A 3B-Active Finance Research Agent Model that Beats Claude Fable 5.1 on FrontierFinance at 11x Lower Cost
Samaya AI has released Samaya Sterling, a post-trained model for agentic financial research. Sterling is built on NVIDIA’s Nemotron 3.5 Lightning, a 30B mixture-of-experts model with 3B active parameters. On Samaya’s FrontierFinance benchmark, it scores 58.9%. Claude Fable 5.1 scores 55.9%. Each Sterling question costs $0.61, against $6.89 for Fable 5.1. For developers, the takeaway is a concrete recipe: co-train a small model with its harness, and it can win in a narrow domain.