
Meta releases Muse Spark Open AI model for coding
Hugging Face: Welcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta
Open-weight models let researchers and companies build AI systems without relying on proprietary providers, potentially accelerating innovation across industries.
What happened
Meta released Muse Spark Open, an open-weight AI model with 816 billion parameters that processes text, images, audio, and video. The model activates only 42 billion parameters per token through a mixture-of-experts architecture and supports a context window of up to one million tokens. It is designed for coding tasks and agentic work and can run on consumer hardware, including Mac Studios with Apple's M5 Ultra chip.
What each outlet adds
- Hugging Face ↗: The model represents an advancement over the earlier Muse Glimmer model and enables developers to work with multiple input types through a single interface.
- The Verge ↗: Meta and Apple publicly supported each other's work on this collaboration, with both CEOs commenting positively, marking a rare partnership between the typically rival companies.
- The Decoder ↗: The model performs well ahead of competitors like Qwen, GLM, and Kimi on several benchmark tests but falls short of Meta's own paid Muse Wonder Full models, and commercial providers earning over 20 million dollars annually need a separate agreement with Meta.
- TechCrunch ↗: Running the model locally requires at least 1 terabyte of RAM and works best on Mac Studio computers with the M5 Ultra chip.
- SiliconANGLE ↗: The model was previously proprietary since its April debut, and on benchmark tests it performed strongly on tool-use tasks compared to other open models, though Chinese models scored higher on pure coding benchmarks.
- MarkTechPost ↗: The model can run on two Mac Studios connected together, which is notable because such large models typically require specialized data center equipment.
Why it matters
Open-weight models let researchers and companies build AI systems without relying on proprietary providers, potentially accelerating innovation across industries. Open-weight models offer advantages over proprietary models including lower costs, greater transparency, and more flexibility.
Get smart on it
Muse Spark Open is an open-weight multimodal model that processes text, images, audio, and video while generating text outputs. The model contains approximately 816 billion total parameters but only activates about 42 billion per token through a mixture-of-experts architecture, allowing it to run faster than its size would suggest while maintaining a context window of up to one million tokens. It was trained specifically for agentic coding tasks such as reading codebases, writing code, debugging, and calling tools, and represents an advancement over the earlier Muse Glimmer model. The model's design enables developers to work with multiple input types through a single interface for asking questions about different kinds of data.
Explainer: What Is a Mixture of Experts Model and Why Does It Use Fewer Resources?
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Gemini 4 Argon: Built to solve your hardest problems
The new model aims to handle complex reasoning tasks where current systems often struggle or fail completely.
Also reported by The Verge, Ars Technica, The Decoder and SiliconANGLE
Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialized always-on agents. Joining it are two new edge models: Nemotron 3.5 Bolt 74B-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3.5 Bolt E4B 4GB, optimized for intelligence per GB for fast conversational agents. Super VL and Bolt 74B-A9B are available now, with Bolt E4B coming Oct. 23. T
Also reported by The Decoder, SiliconANGLE and MarkTechPost
OpenAI will reportedly ship at least one model this year but its flagship still needs alignment work
OpenAI is racing to finish its next flagship model, which uses the same looped transformer technique as Astra to boost math and coding performance. The tradeoff is that looping makes safety monitoring harder. Microsoft accidentally revealed details about how the technique works on a public page. Whether or not the flagship is ready in time, employees say one or two new models will likely ship by year's end. The article OpenAI will reportedly ship at least one model this year but its fla

Welcome Beam: a 501B open model you can own, customize, and scale
Open-source alternatives to proprietary AI systems could shift control over large language models from commercial labs to individual organizations and researchers.

Welcome FLUX.3 Image Klein in Diffusers
The new model joins a competitive landscape of open-source image generators, offering developers another option for customizing visual AI tools.
Also reported by The Decoder
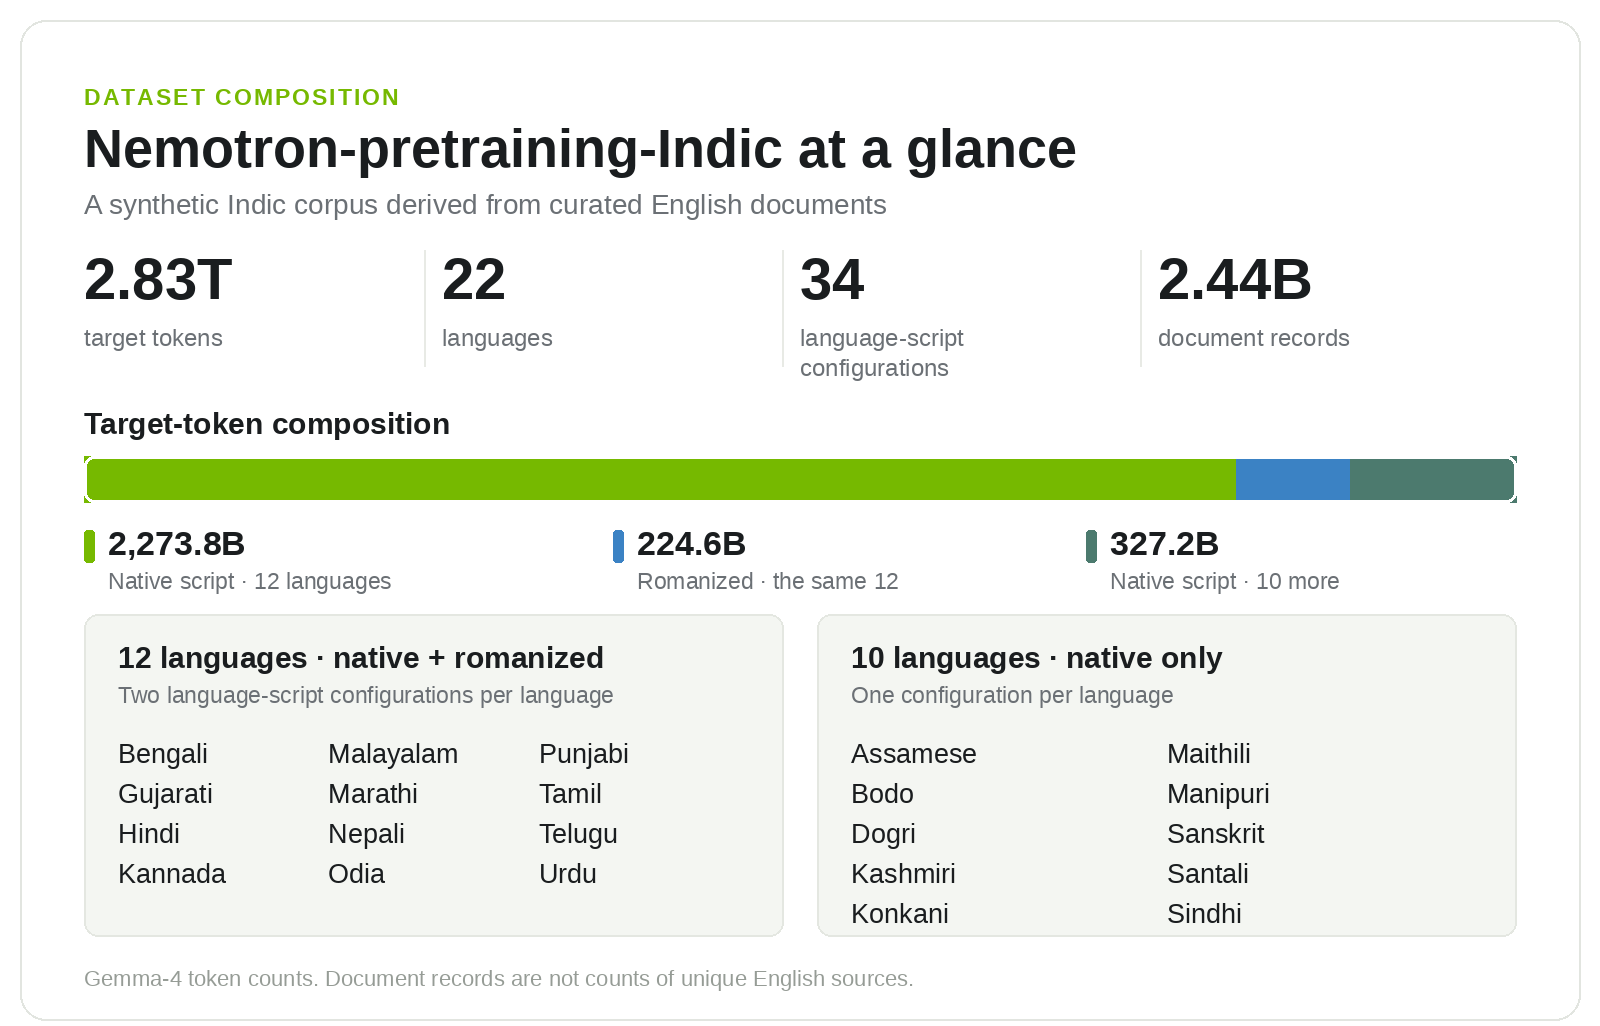
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
The effort addresses a gap in AI training data for Indian languages, which have historically received far less computational investment than English or Chinese.