
NVIDIA releases Nemotron 3.5 Bolt for local voice agents
MarkTechPost: NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
NVIDIA has just released Nemotron 3.5 Bolt E4B 4GB, an open small language model for fast conversational agents. It targets voice assistants, game NPCs and robot interfaces running locally on RTX, Jetson and Spark hardware. The model is post-trained from Google’s Gemma 4 E4B using reinforcement learning only. For developers, this is agent behavior in about 4GB of VRAM. That leaves room for speech and vision models. TL;DR Size: 8B total parameters, 4B effective, 64K context. Runs
Get smart on it
NVIDIA released an open small language model designed to run locally on consumer and embedded hardware for tasks like voice assistants, game characters, and robots. The model uses 4 gigabytes of memory and was created by applying reinforcement learning to an existing base model, skipping the traditional supervised fine-tuning step. In benchmark testing, it outperformed comparable models on most measures, though it showed weaker results on some language and reasoning tasks. The model is available publicly under an open license with code and training data included.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
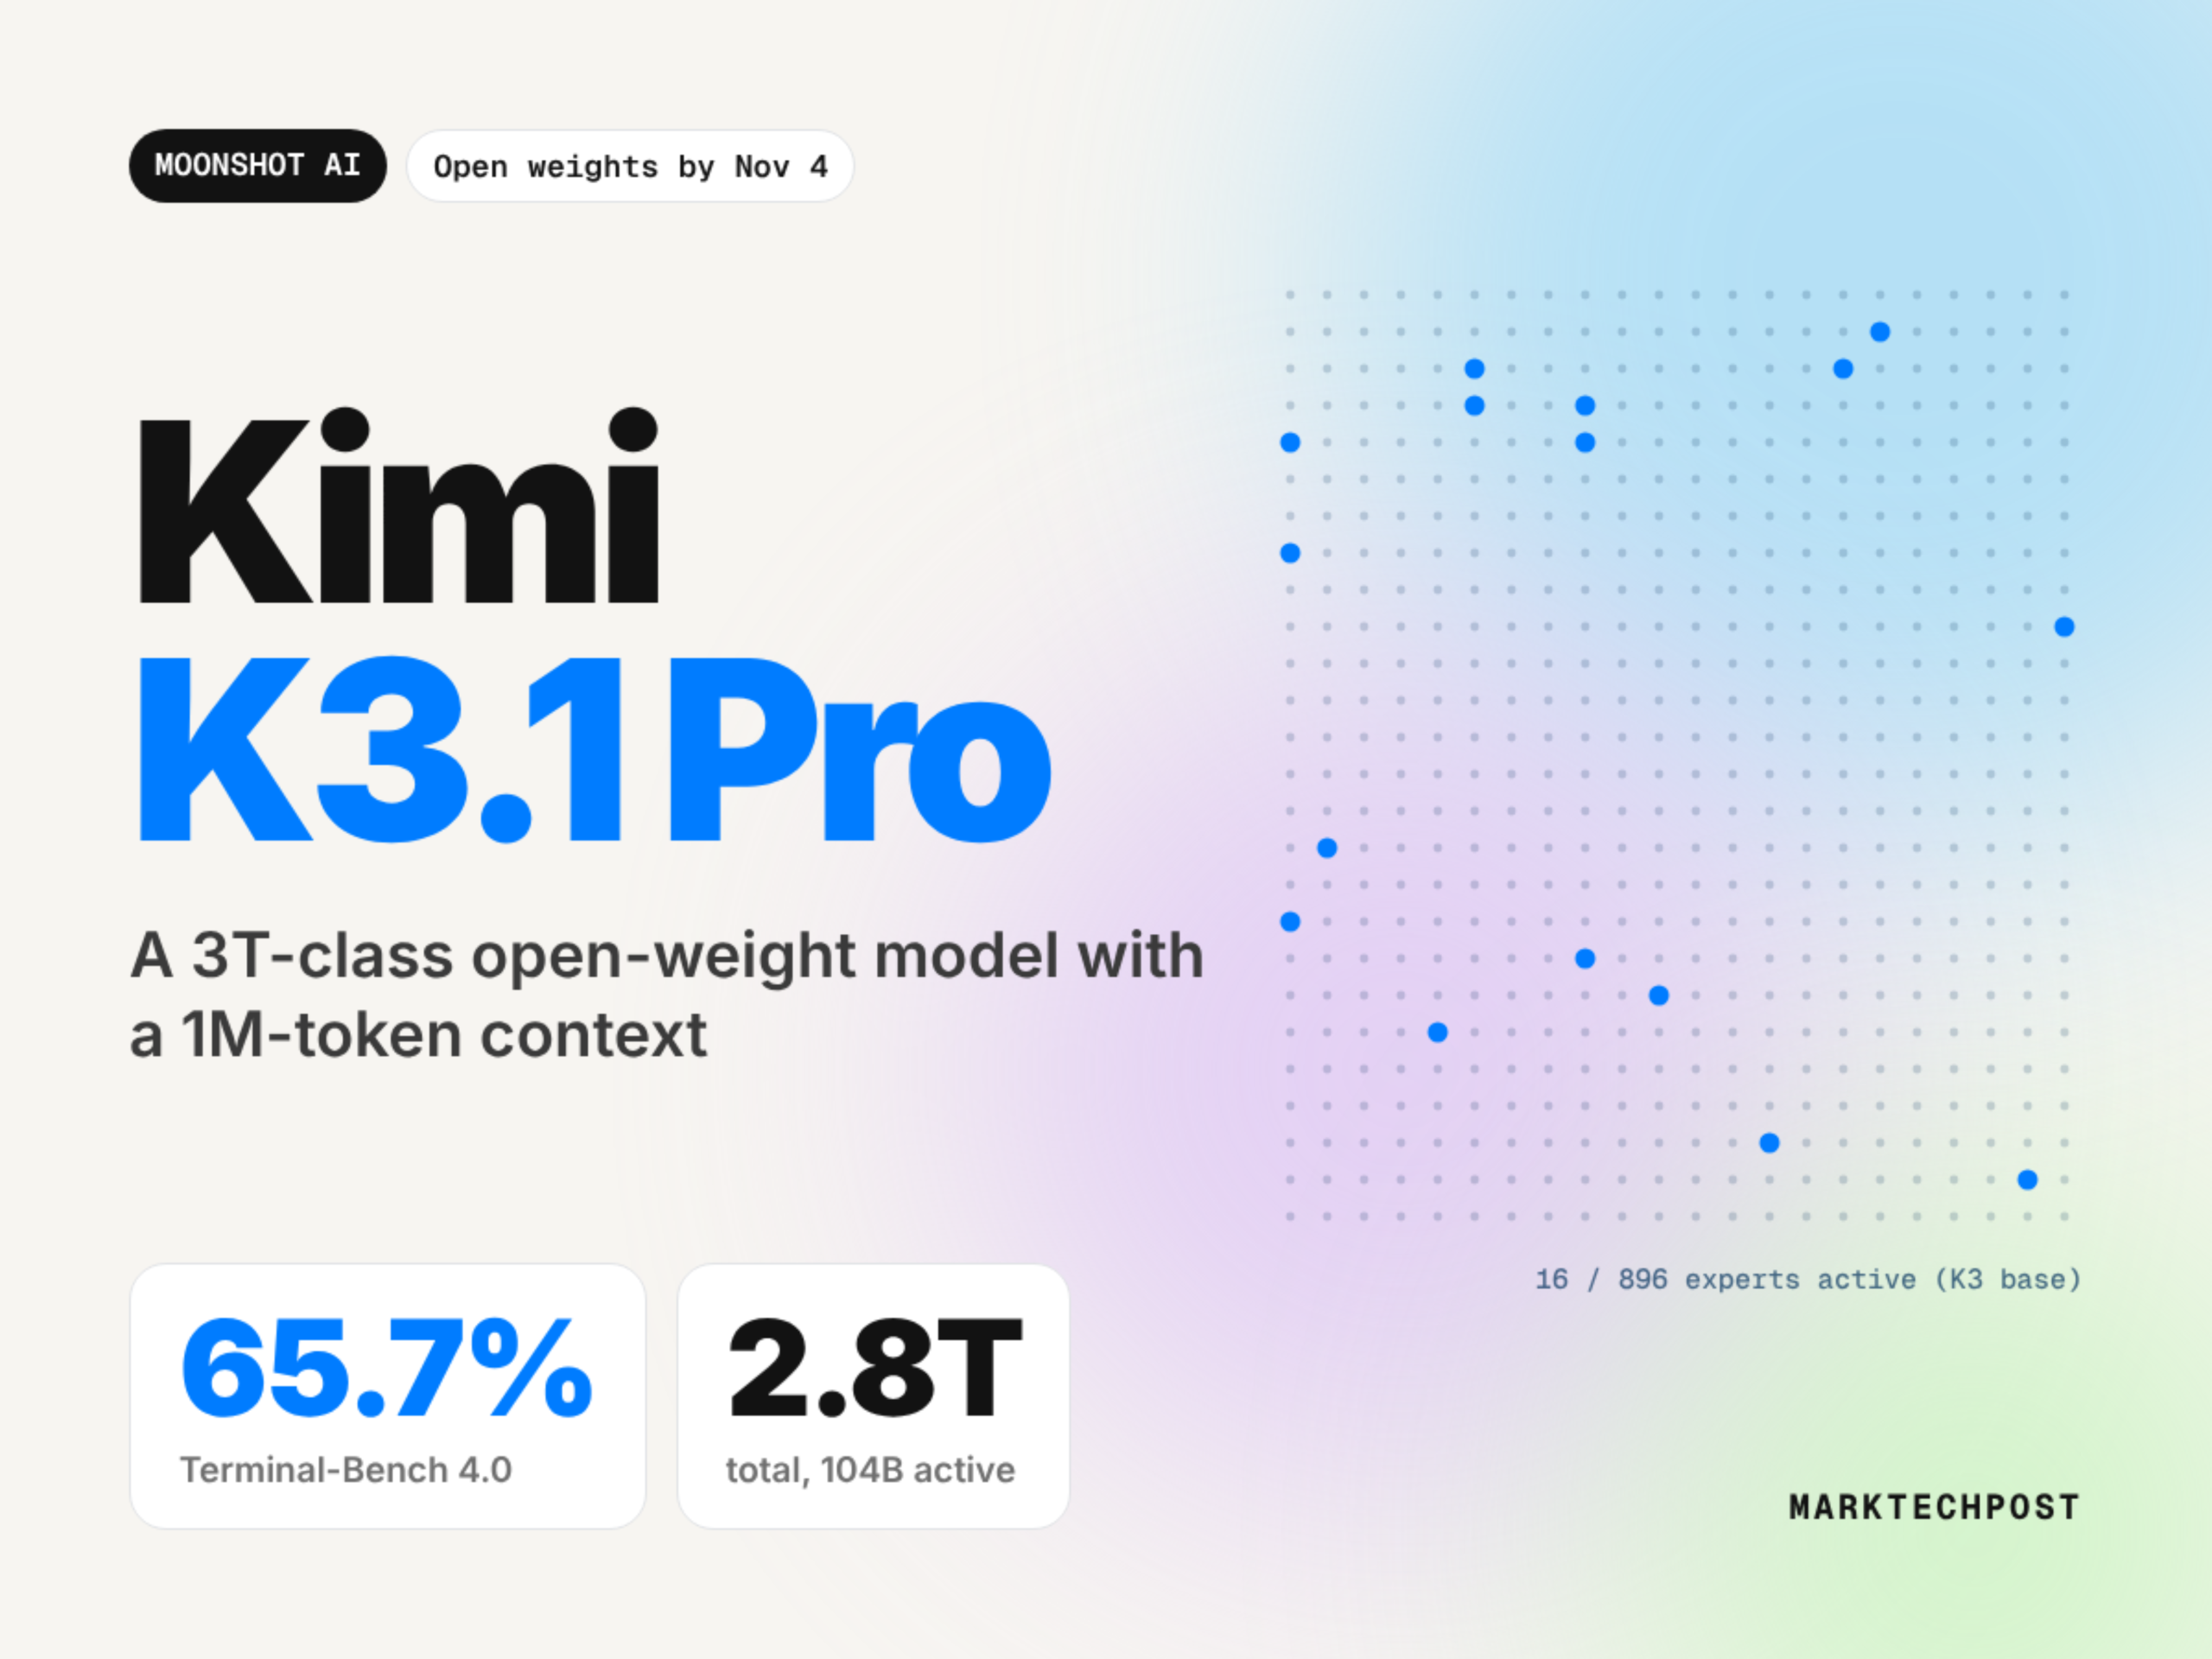
Moonshot AI Releases Kimi K3.1 Pro: A 2.8T Total/104B Active Params (MoE) Model with 1M Context
Moonshot AI has just released Kimi K3.1 Pro, the first model in its K3.1 series. Kimi K3.1 Pro is a 3T-class open-weight* model with a 1-million-token context window. Moonshot team positions it against the strongest proprietary models on coding, agentic and knowledge benchmarks. For developers, it is cheaper API pricing than K3 and open weights yet not available. *open weights are expected to release in November 2026. TL;DR Size: 2.8T total, 104B active parameters (MoE), 1M-token context
Also reported by SiliconANGLE and The Decoder
Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time
Mistral AI launched Voxtral 3, a new family of language models built for real-time voice agents. The system combines speech-to-text, text-to-speech, and a voice agent SDK, supports more than 50 languages, and lets agents tap into external tools during live conversations. It can run on your own infrastructure or through EU-hosted APIs to keep data under your control. The article Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time appeared
Also reported by MarkTechPost
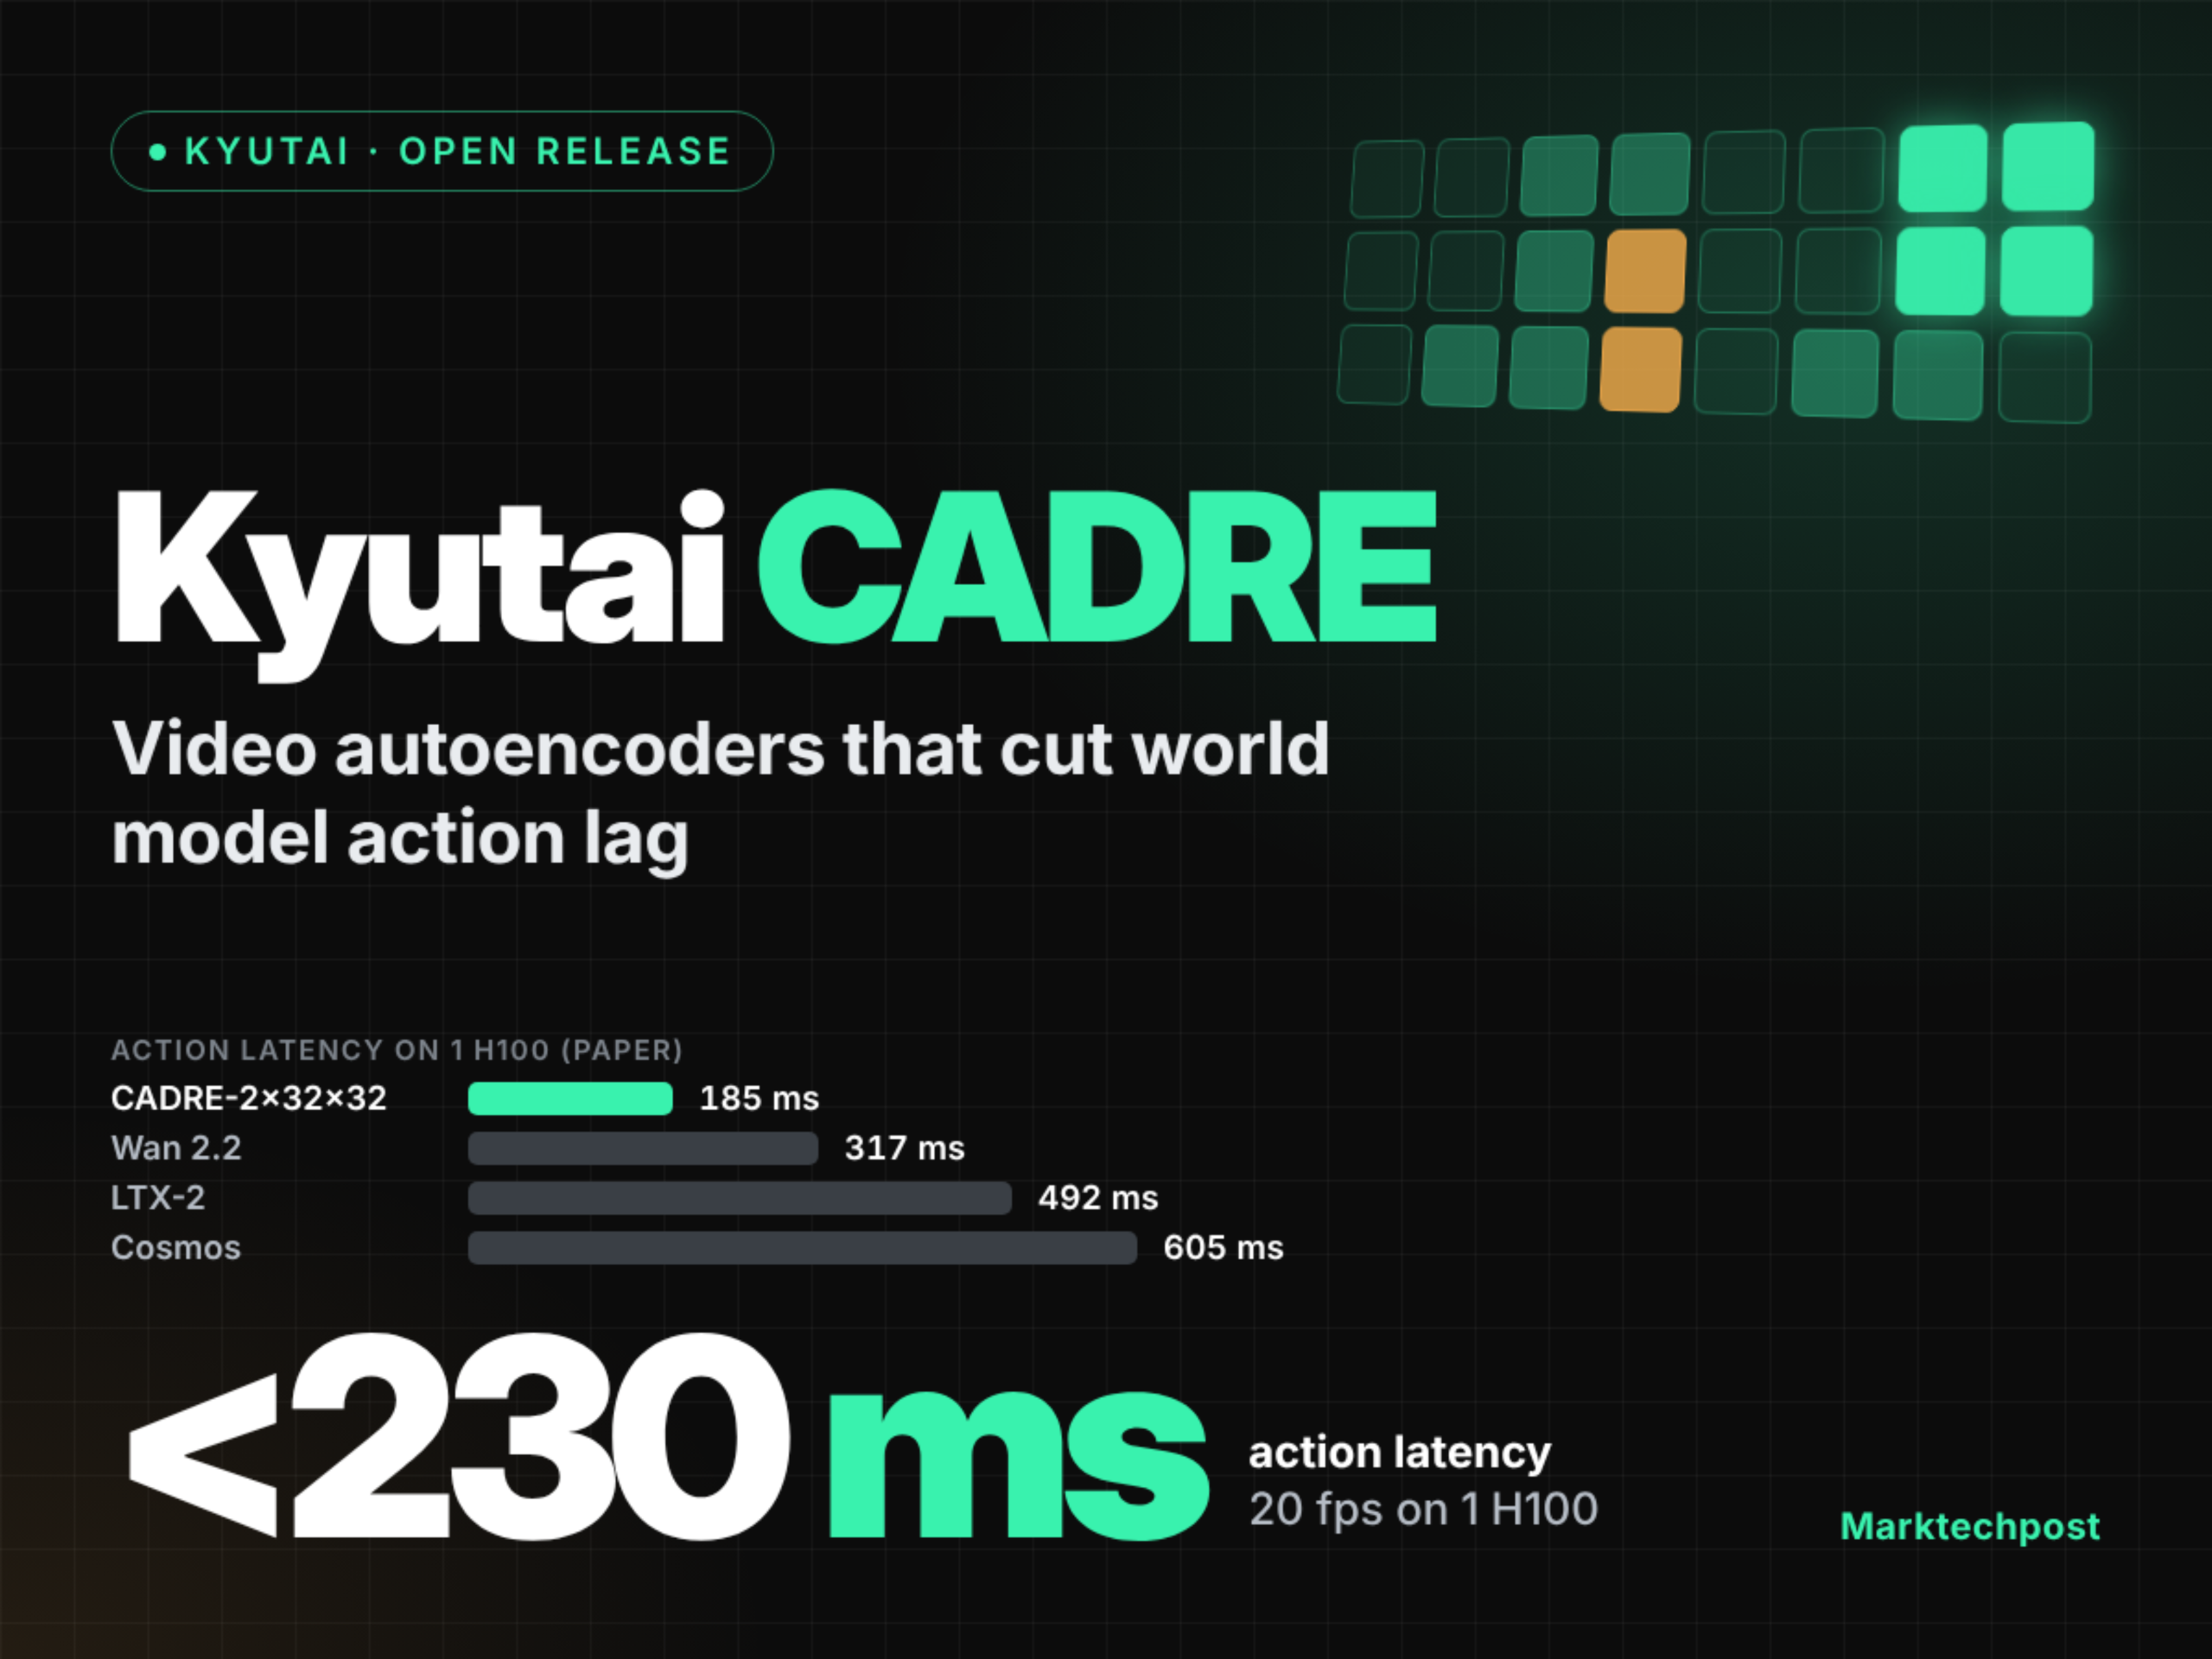
Kyutai CADRE: Video Autoencoders That Cut World Model Lag Below 230 ms
Kyutai has released CADRE, open causal diffusion representation autoencoders for interactive world models. The Kyutai CADRE video autoencoder targets one problem: action lag. Many world models borrow autoencoders from text-to-video generators. Those autoencoders pack many frames into one latent, so every action waits. Per the research paper, CADRE world models run at 20 fps on 1 H100 and react within 230 ms. TL;DR Size: 7 autoencoders, each about 476M trained parameters plus a frozen 86M

Canva releases its first image generation model
Canva is making its new image model available to all users, promising better, more customizable performance at lower costs.
Also reported by The Verge and The Decoder

Jack Dorsey’s Block made an AI model that talks to you like an awkward new friend
Jack Dorsey's Block announced an AI model called Dessa that's trained "from scratch on nothing but human conversation," and to show off the model, Block shared chats it has had with humans that can occasionally be a little awkward and uncanny. Take this one, for example, shared by Dessa lead Ragavan Thurairatnam. The conversation between the model and the speaker does have a mostly natural back and forth (though for some reason, the model initially mistakes the speaker for some

Recursive launches Flint, a laptop coding model it says was largely built by AI
Startup Recursive has released Flint, a free, laptop-sized coding model built largely by its own AI research system, as an early test of AI that improves itself.
Also reported by Wired AI and MarkTechPost