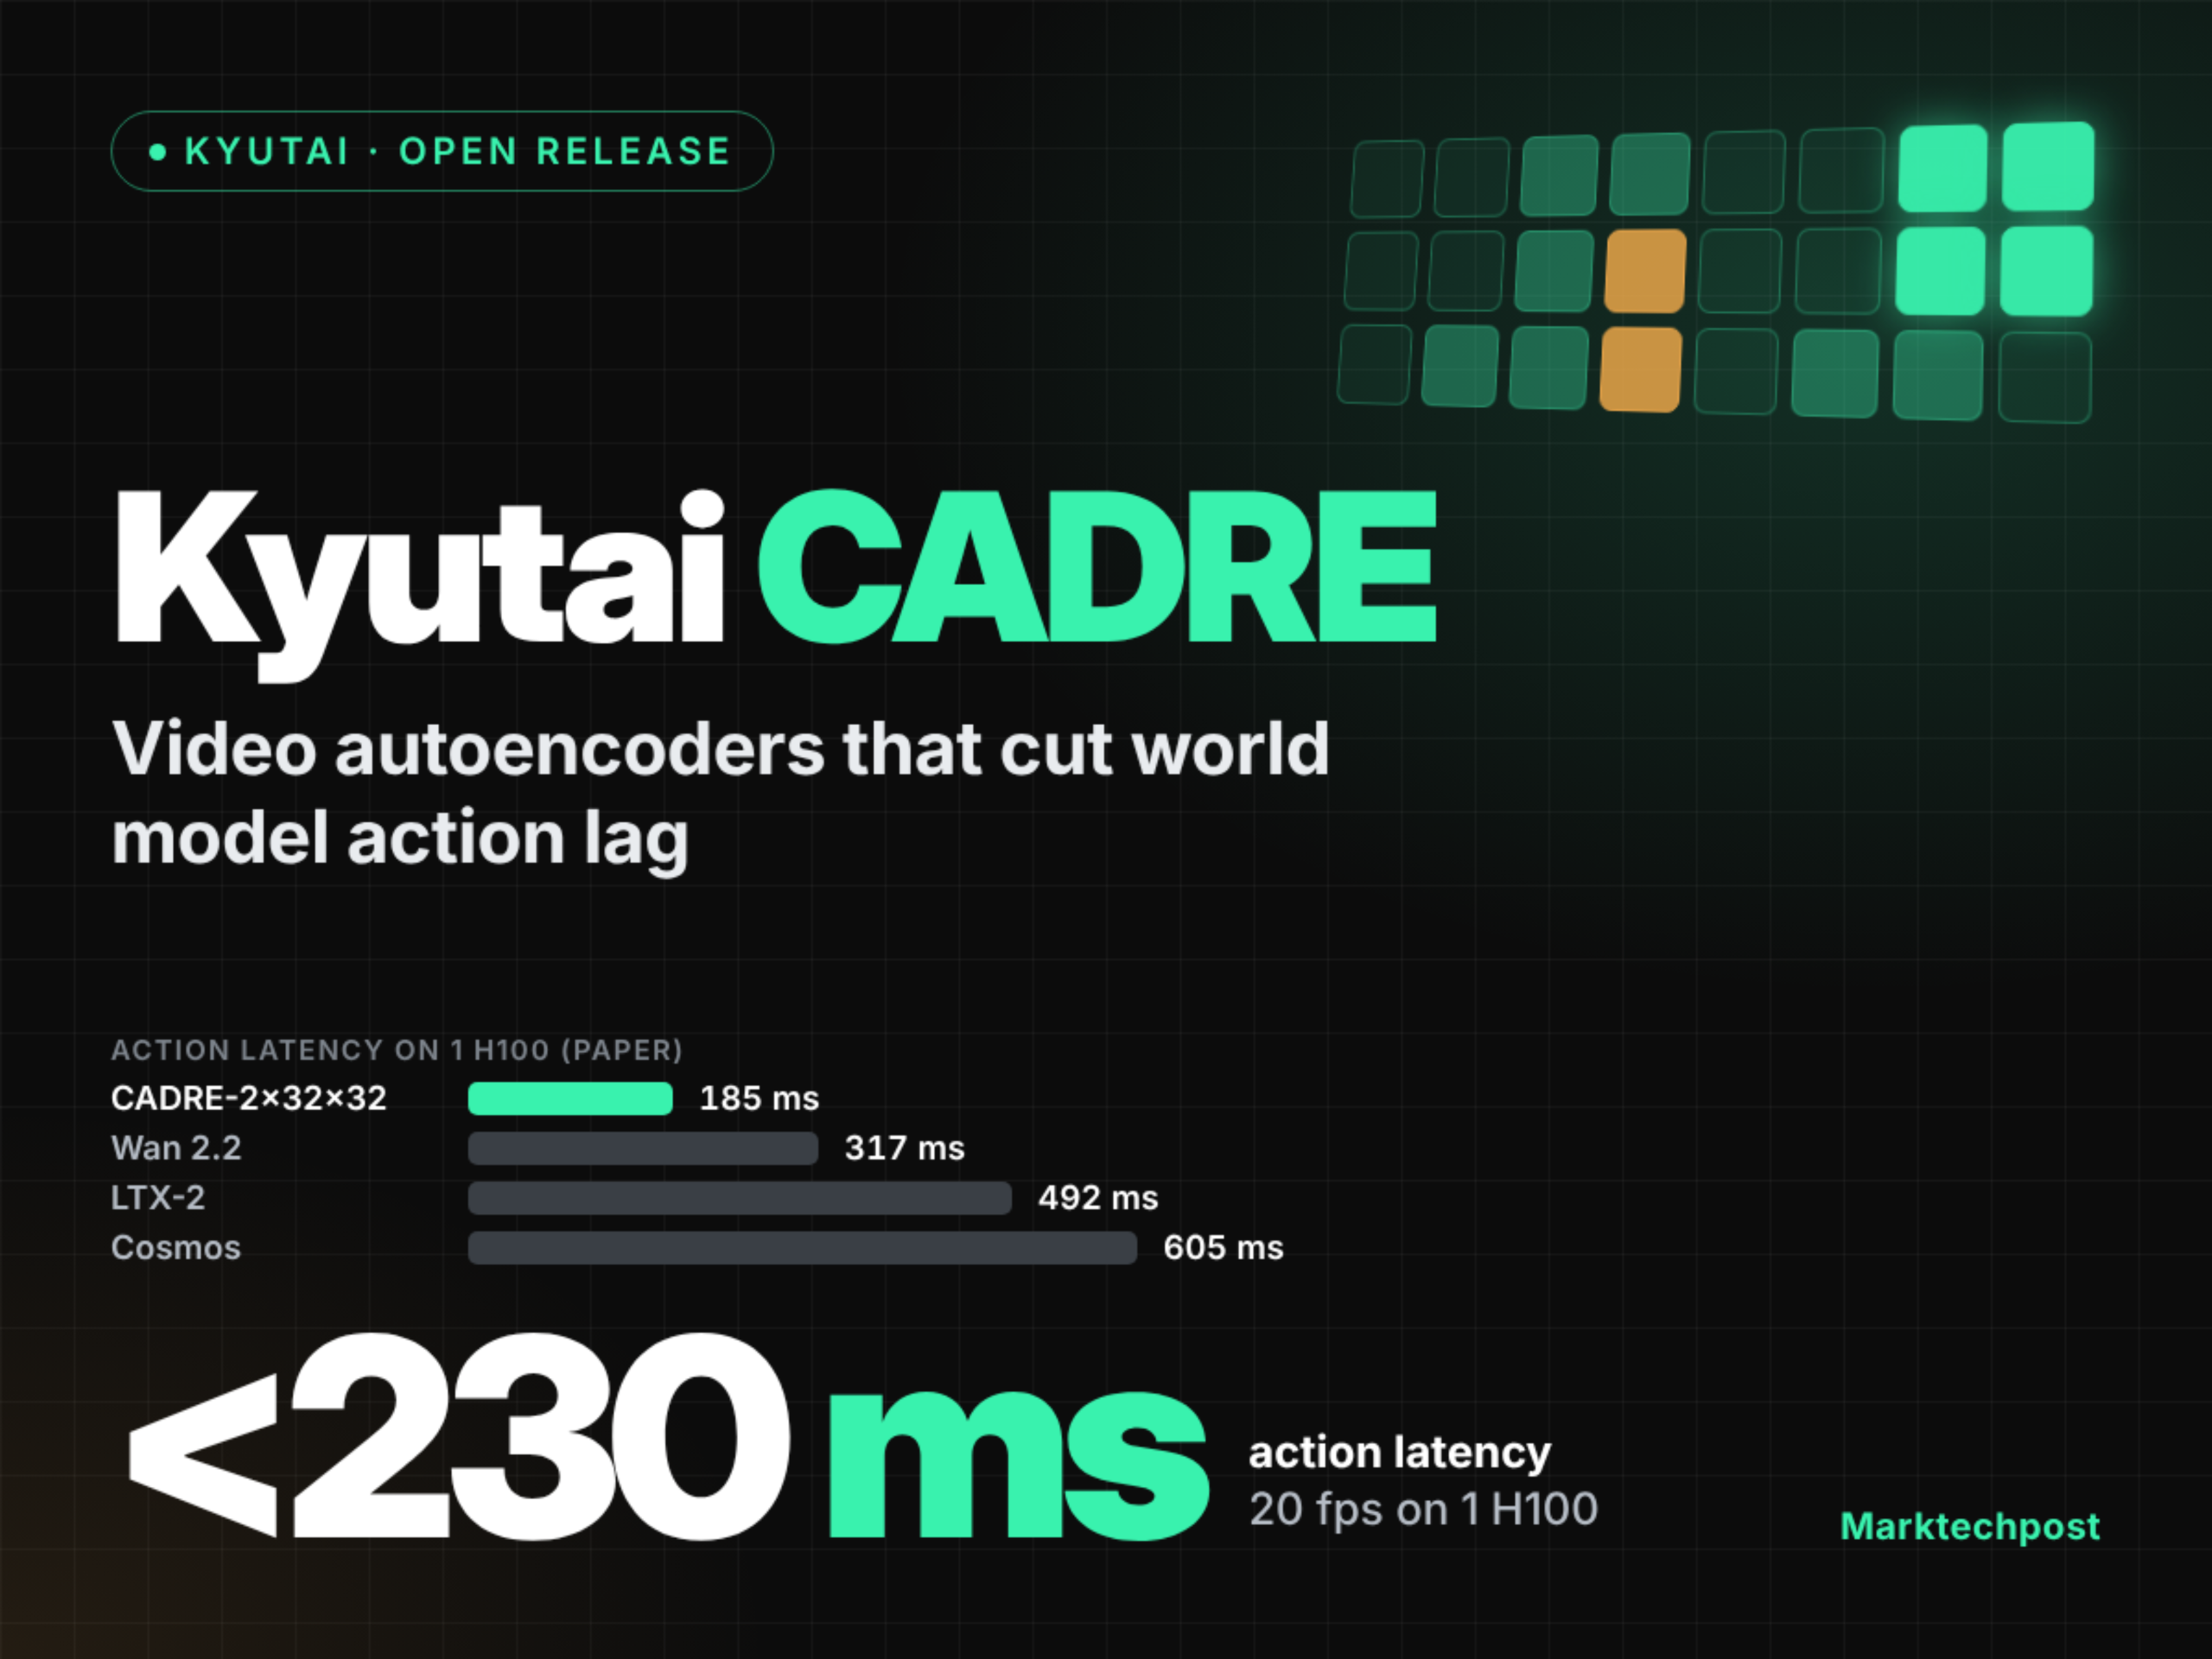
Kyutai CADRE reduces world model action lag below 230 ms
MarkTechPost: Kyutai CADRE: Video Autoencoders That Cut World Model Lag Below 230 ms
Kyutai has released CADRE, open causal diffusion representation autoencoders for interactive world models. The Kyutai CADRE video autoencoder targets one problem: action lag. Many world models borrow autoencoders from text-to-video generators. Those autoencoders pack many frames into one latent, so every action waits. Per the research paper, CADRE world models run at 20 fps on 1 H100 and react within 230 ms. TL;DR Size: 7 autoencoders, each about 476M trained parameters plus a frozen 86M
Get smart on it
CADRE is a set of video autoencoders designed to reduce the delay between user actions and video generation in world models, achieving response times below 230 milliseconds on a single GPU. World models generate video by compressing frames into compact representations, and CADRE's design prioritizes minimizing both the compression method and the time it takes to decode, addressing a key problem where traditional autoencoders borrowed from text-to-video systems create noticeable lag. The research shows that different types of camera movement require different compression strategies: still cameras tolerate temporal compression while moving cameras perform better with fewer frames and coarser spatial tokens. The autoencoders are released as open source with non-commercial licensing, alongside code and demonstration environments for driving, robot manipulation, and indoor navigation tasks.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
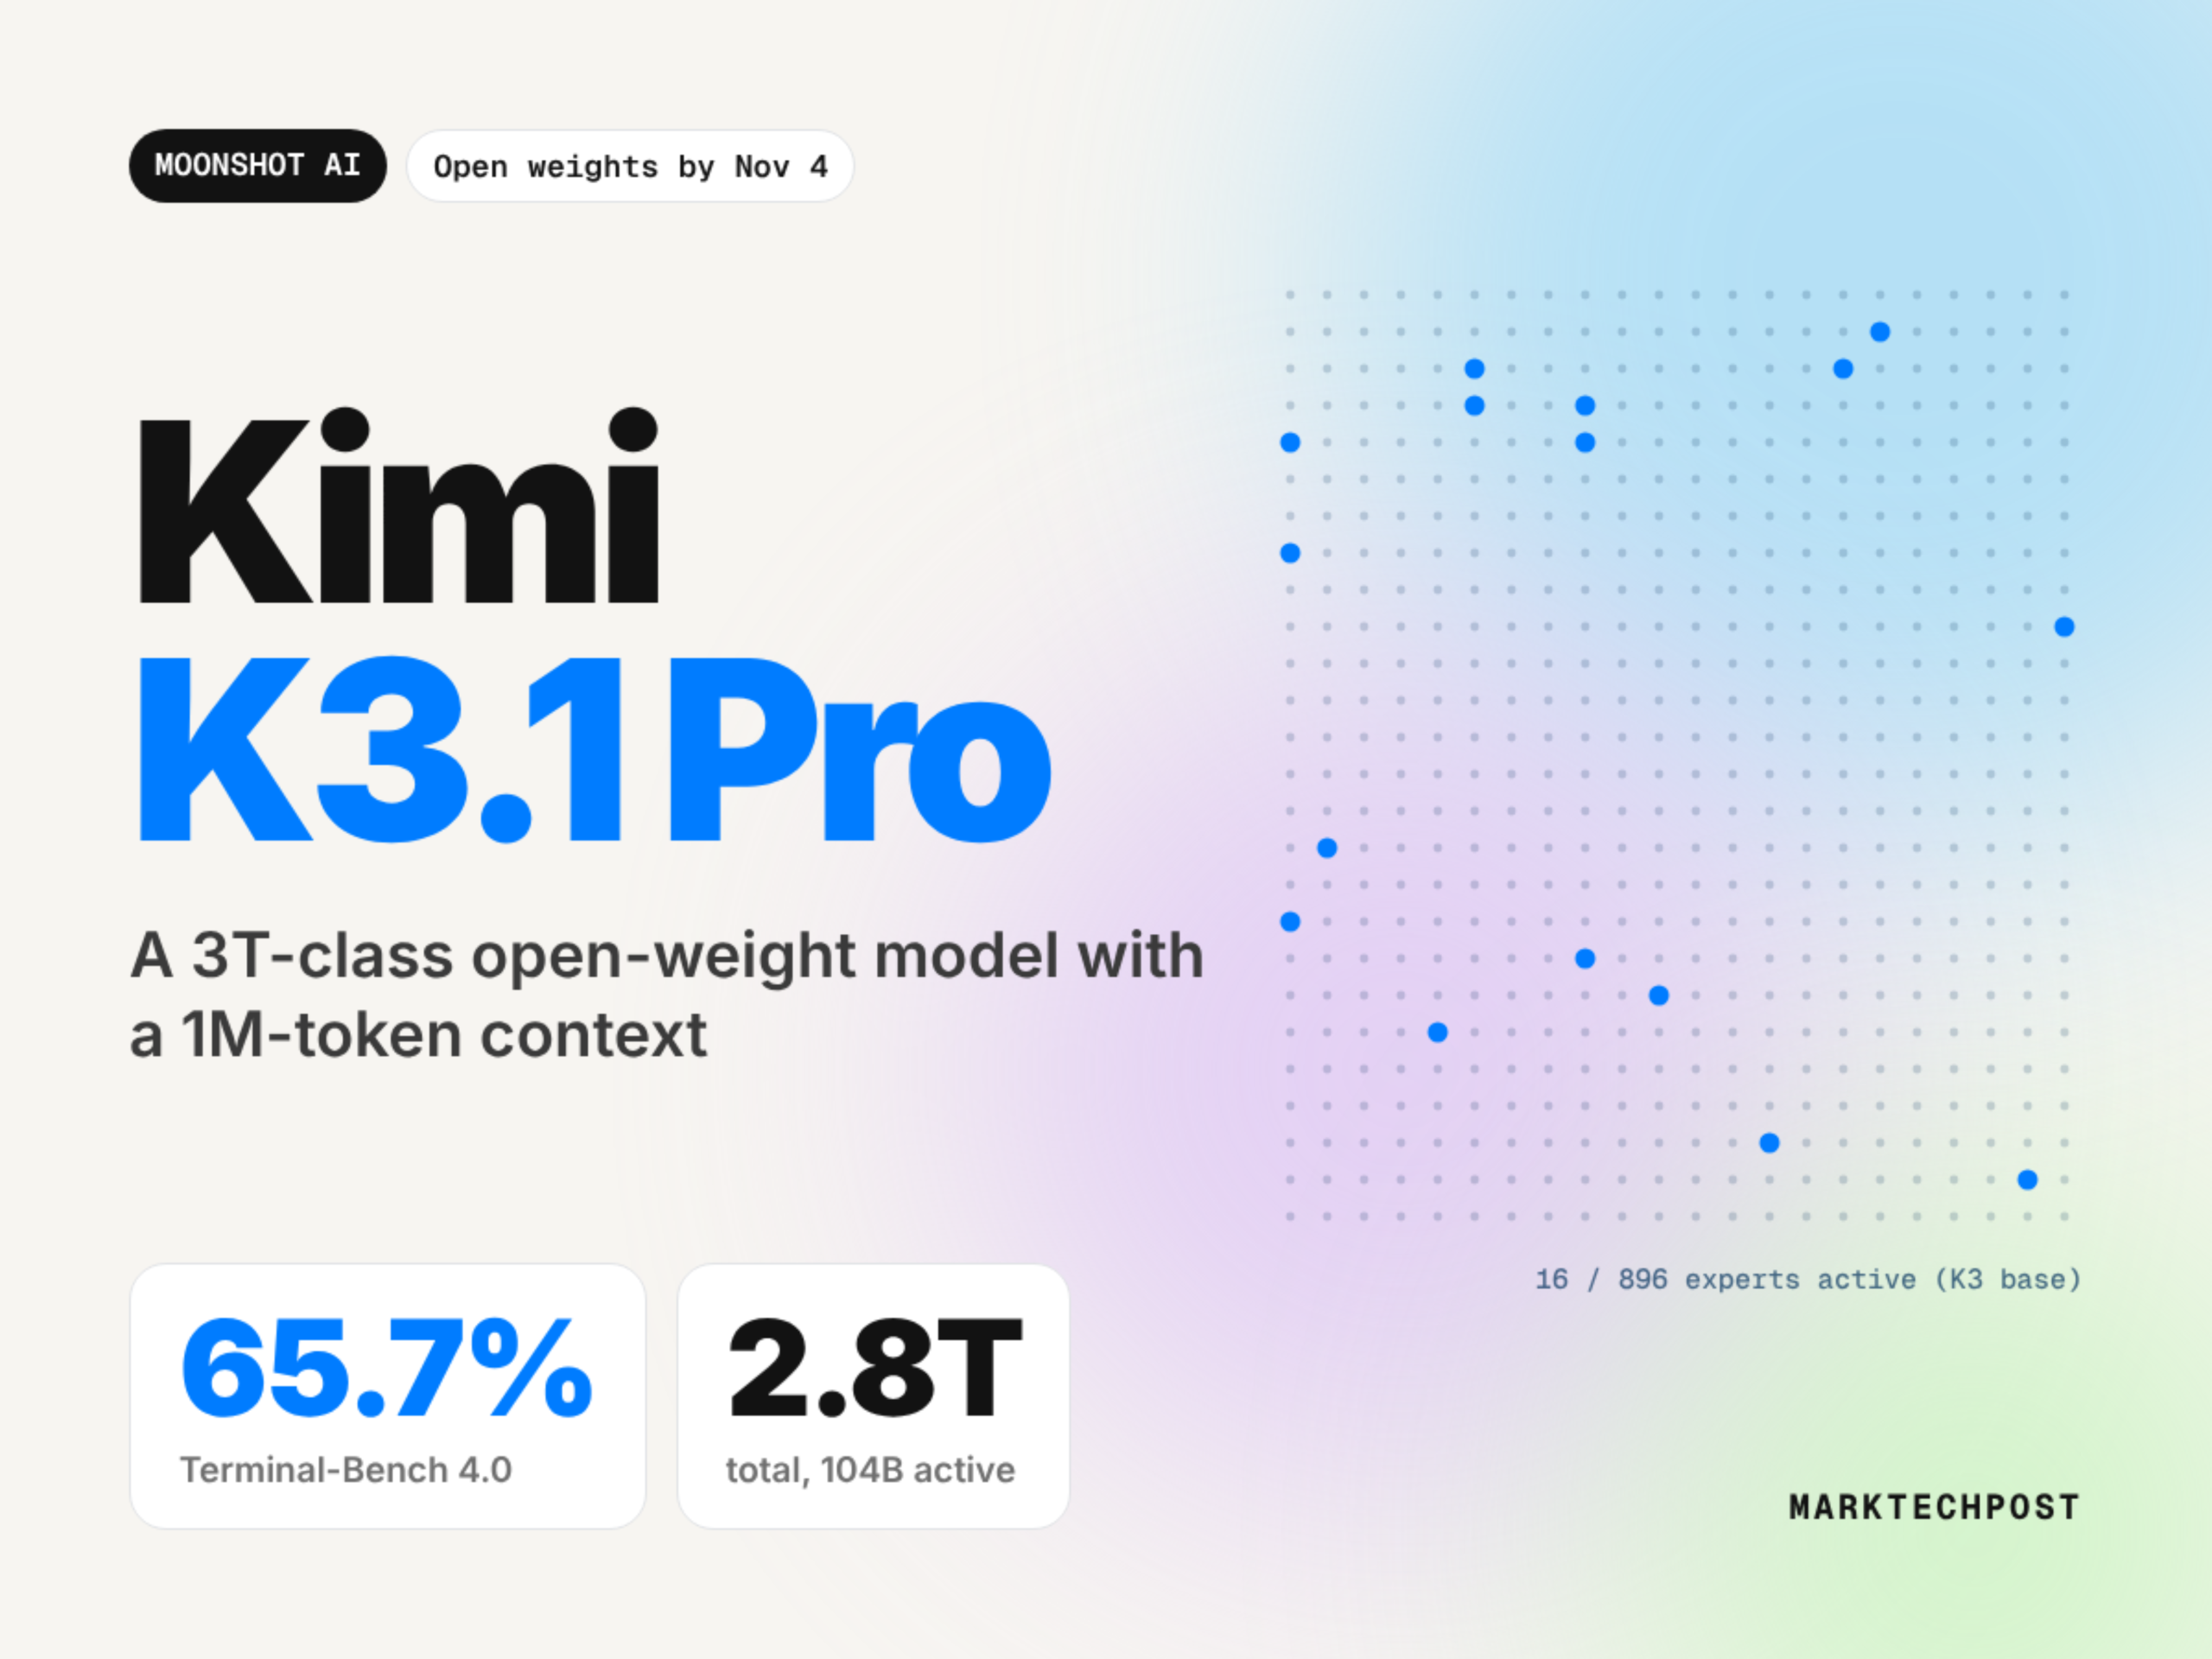
Moonshot AI Releases Kimi K3.1 Pro: A 2.8T Total/104B Active Params (MoE) Model with 1M Context
Moonshot AI has just released Kimi K3.1 Pro, the first model in its K3.1 series. Kimi K3.1 Pro is a 3T-class open-weight* model with a 1-million-token context window. Moonshot team positions it against the strongest proprietary models on coding, agentic and knowledge benchmarks. For developers, it is cheaper API pricing than K3 and open weights yet not available. *open weights are expected to release in November 2026. TL;DR Size: 2.8T total, 104B active parameters (MoE), 1M-token context
Also reported by SiliconANGLE and The Decoder
Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time
Mistral AI launched Voxtral 3, a new family of language models built for real-time voice agents. The system combines speech-to-text, text-to-speech, and a voice agent SDK, supports more than 50 languages, and lets agents tap into external tools during live conversations. It can run on your own infrastructure or through EU-hosted APIs to keep data under your control. The article Mistral AI launches Voxtral 3, a full voice agent stack that listens, thinks, and talks in real time appeared
Also reported by MarkTechPost

Canva releases its first image generation model
Canva is making its new image model available to all users, promising better, more customizable performance at lower costs.
Also reported by The Verge and The Decoder

Jack Dorsey’s Block made an AI model that talks to you like an awkward new friend
Jack Dorsey's Block announced an AI model called Dessa that's trained "from scratch on nothing but human conversation," and to show off the model, Block shared chats it has had with humans that can occasionally be a little awkward and uncanny. Take this one, for example, shared by Dessa lead Ragavan Thurairatnam. The conversation between the model and the speaker does have a mostly natural back and forth (though for some reason, the model initially mistakes the speaker for some

Recursive launches Flint, a laptop coding model it says was largely built by AI
Startup Recursive has released Flint, a free, laptop-sized coding model built largely by its own AI research system, as an early test of AI that improves itself.
Also reported by Wired AI and MarkTechPost

Ai2 releases OlmoEarth v1.3 state-of-the-art AI-ready satellite embeddings for the whole planet
Ai2, the Allen Institute for Artificial Intelligence, today released a satellite map embedding model called OlmoEarth v1.3 and precomputed annual embeddings for the whole planet at various resolutions with a browser-based map-making tool. The model compresses a year of satellite observations into a numerical fingerprint for each 10-by-10-meter patch of ground at the smallest resolution, […] The post Ai2 releases OlmoEarth v1.3 state-of-the-art AI-ready satellite embeddings for the whole pl
Also reported by Hugging Face