Kling AI releases version 4.0 video generator
The Decoder: Kling AI drops version 4.0 with stereo audio, multilingual lip sync, and a lighter Flash variant
Kling AI has released version 4.0 of its video generator with support for clips up to 30 seconds, ten keyframe images as input, and prompt comprehension expanded to 8,000 tokens. In comparisons with Wan 3.0 and Seedance 2.5, Kling 4.0 holds its own but doesn't pull ahead, which could be an early sign that the breakneck pace of progress in AI video models is starting to level off. The article Kling AI drops version 4.0 with stereo audio, multilingual lip sync, and a lighter Flash variant
Get smart on it
An AI video generator has released a new version featuring higher resolution output, extended video length up to 30 seconds per generation, and improved controls including keyframe inputs and expanded prompt comprehension. The update adds stereo audio and multilingual lip-sync capabilities across multiple languages, along with a faster, lower-cost Flash variant for quicker generation at reduced resolution. According to performance comparisons with competing systems, this version performs comparably to rivals but does not show clear advancement, particularly in areas like shot sequencing, physics, and dialogue naturalness. The new capabilities and pricing for the API are available or coming soon, with the interface now accessible through multiple technical pathways for automated workflows.
Explainer: Video AI Is Splitting in Two: The Seedance vs. Kling Control Divide
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Nvidia launches new open models to run agents in the enterprise and on PCs
Nvidia is leaning hard into the trend of enterprise companies wanting to run their own open models in their own data centers and also trying to make on-device, private AI agents a thing.
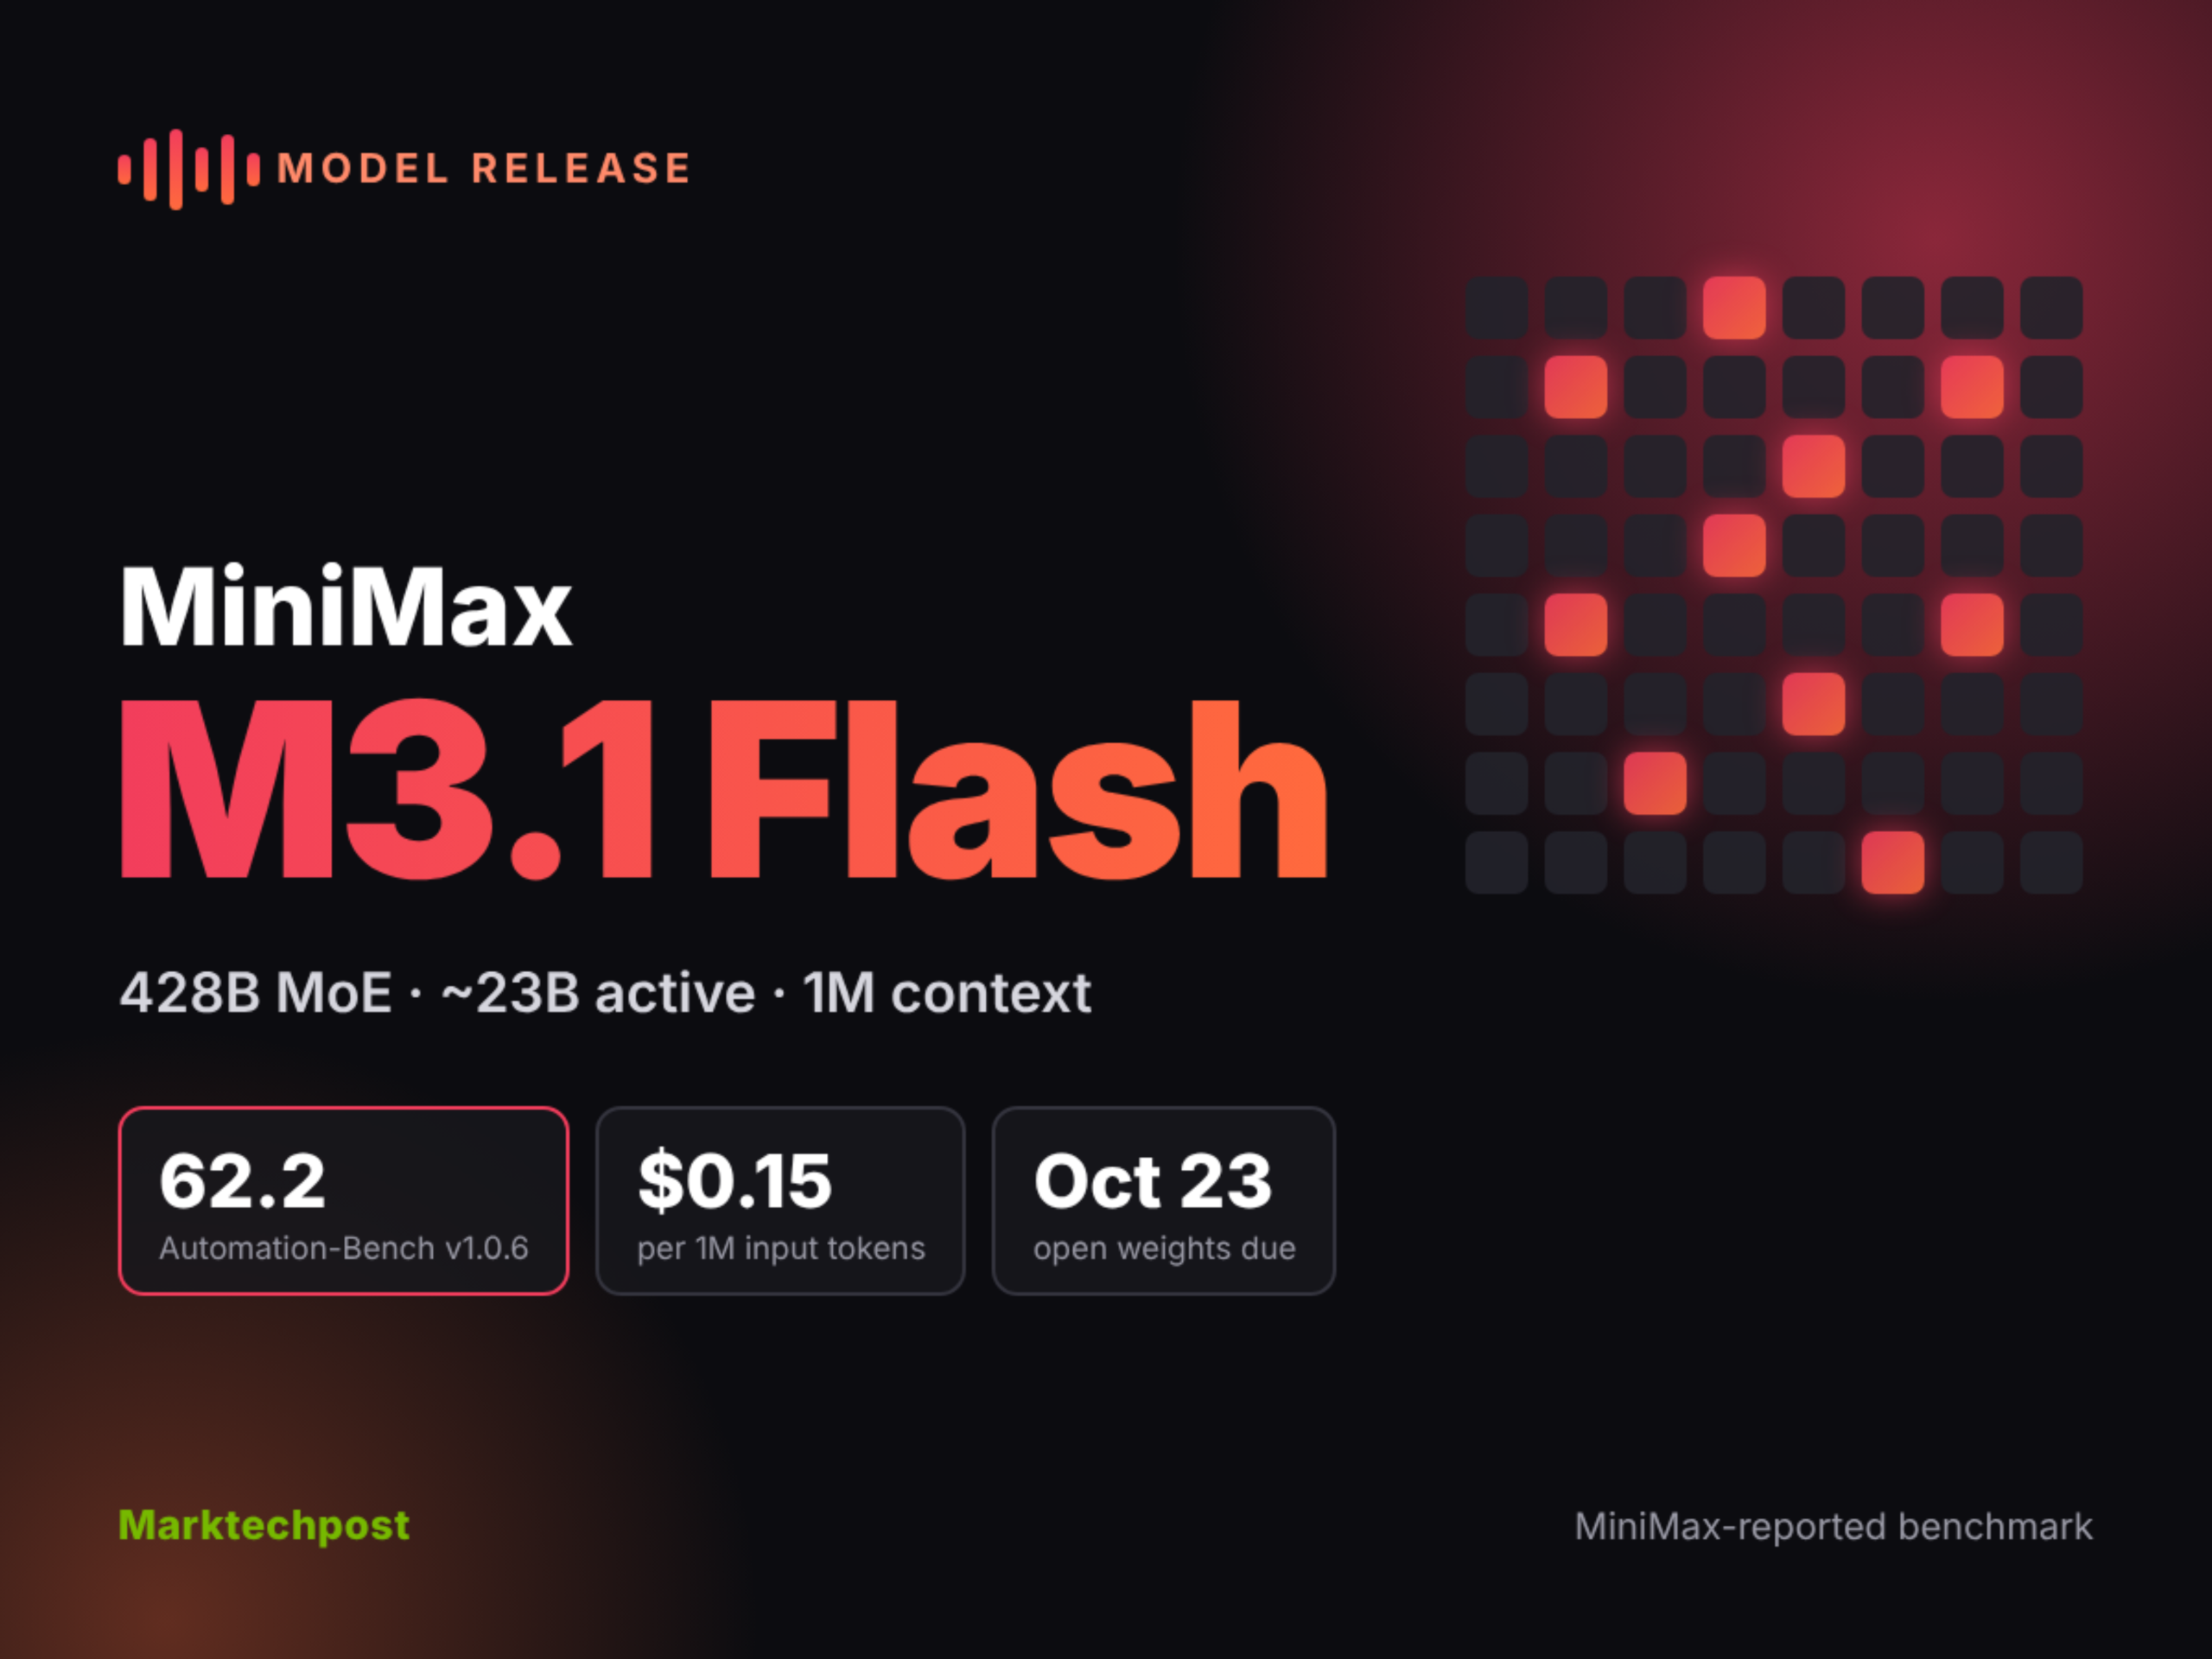
MiniMax Just Launched M3.1 Flash: 428B MoE Agentic Model at $0.15/M Input
MiniMax has just released MiniMax M3.1 Flash on its API, priced at $0.15 per 1M input tokens. MiniMax also confirmed that Space Bunny was an earlier M3.1 Flash build. That stealth model processed over 200T tokens. For developers, the message is near-frontier agentic scores at Flash-tier cost. Model weights are due in late October, 2026. TL;DR Size: 428B total parameters, about 23B active (MoE); 1,000,000-token context Runs on: MiniMax API, M Plan and MiniMax Code today. Self-hosting h
Also reported by The Decoder

Welcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta
Open-weight models let researchers and companies build AI systems without relying on proprietary providers, potentially accelerating innovation across industries.
Also reported by The Verge, The Decoder, TechCrunch and SiliconANGLE
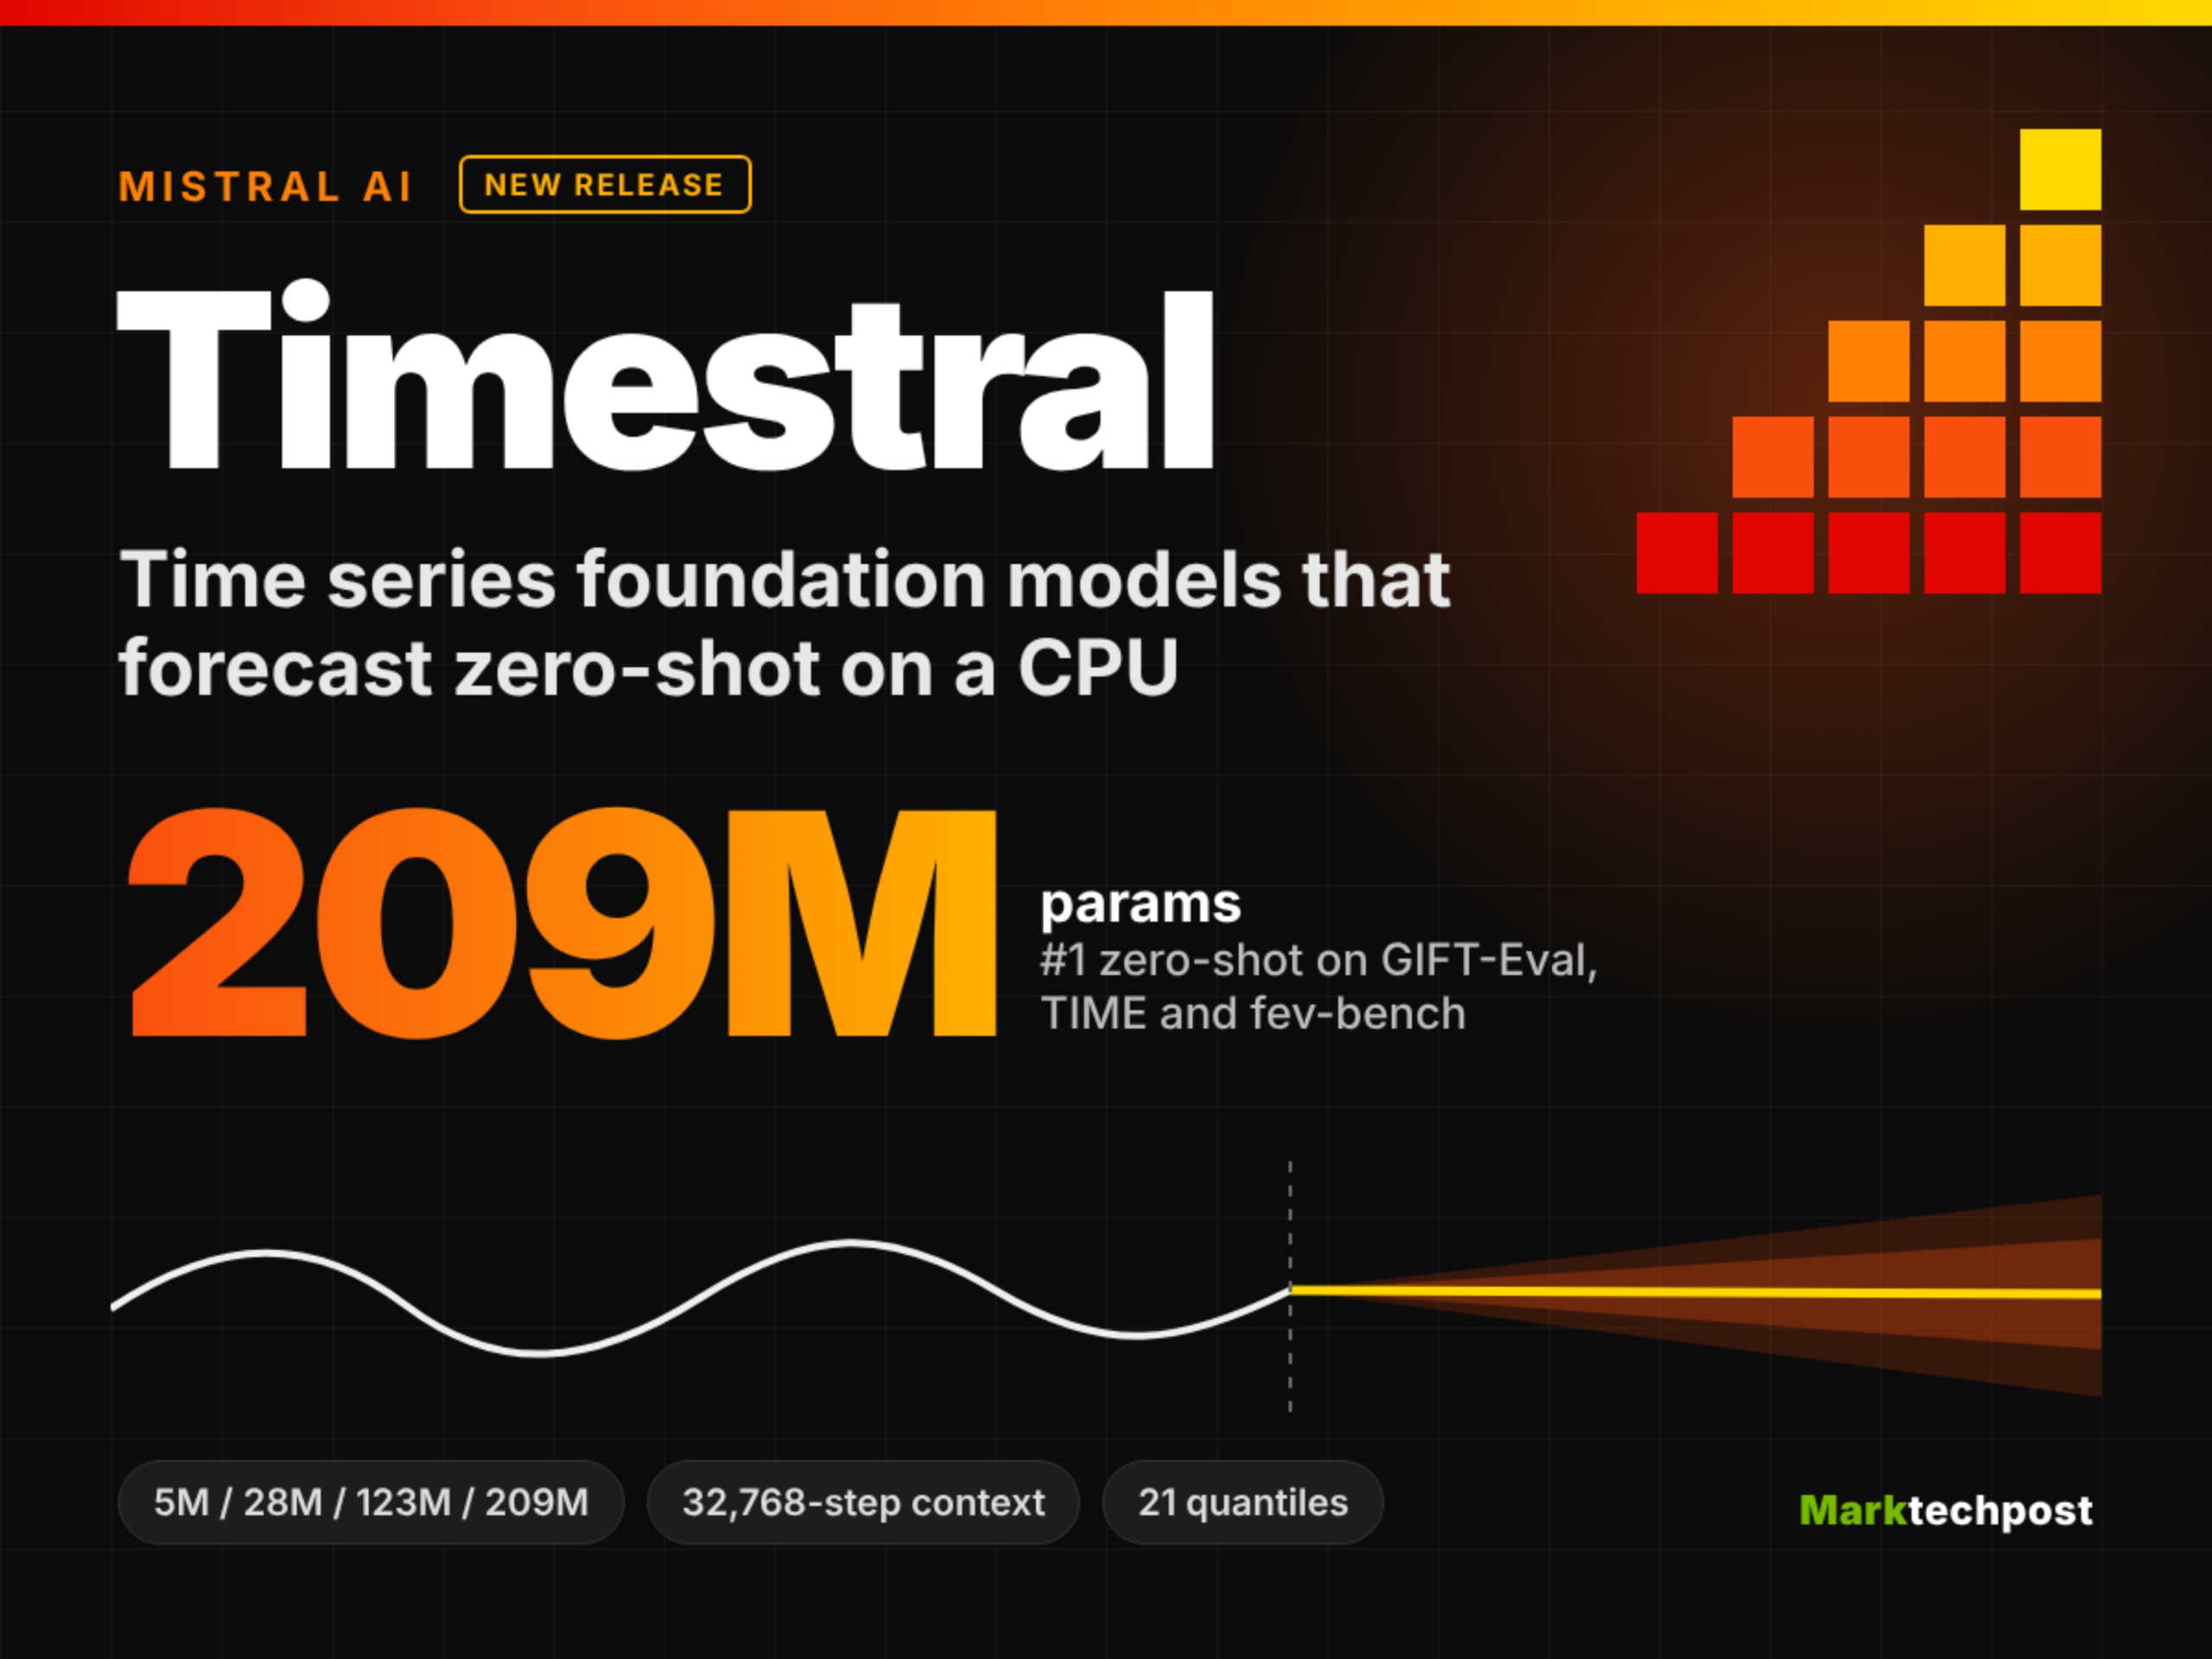
Mistral AI Releases Timestral: A 209M Forecasting Model Family That Outperforms Google’s TimesFM-3
Mistral AI has released Timestral, its first family of time series foundation models. Timestral is a set of 4 zero-shot forecasting models from Mistral AI, sized from 5M to 209M parameters. The largest checkpoint ranks first among pretrained, zero-shot models on GIFT-Eval, TIME and fev-bench. It does this without a GPU at inference. For developers, this Timestral time series foundation model means probabilistic forecasts on standard server CPUs, with open weights and inference code. TL;DR
OpenAI will reportedly ship at least one model this year but its flagship still needs alignment work
OpenAI is racing to finish its next flagship model, which uses the same looped transformer technique as Astra to boost math and coding performance. The tradeoff is that looping makes safety monitoring harder. Microsoft accidentally revealed details about how the technique works on a public page. Whether or not the flagship is ready in time, employees say one or two new models will likely ship by year's end. The article OpenAI will reportedly ship at least one model this year but its fla
Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialized always-on agents. Joining it are two new edge models: Nemotron 3.5 Bolt 74B-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3.5 Bolt E4B 4GB, optimized for intelligence per GB for fast conversational agents. Super VL and Bolt 74B-A9B are available now, with Bolt E4B coming Oct. 23. T
Also reported by The Decoder, SiliconANGLE and MarkTechPost