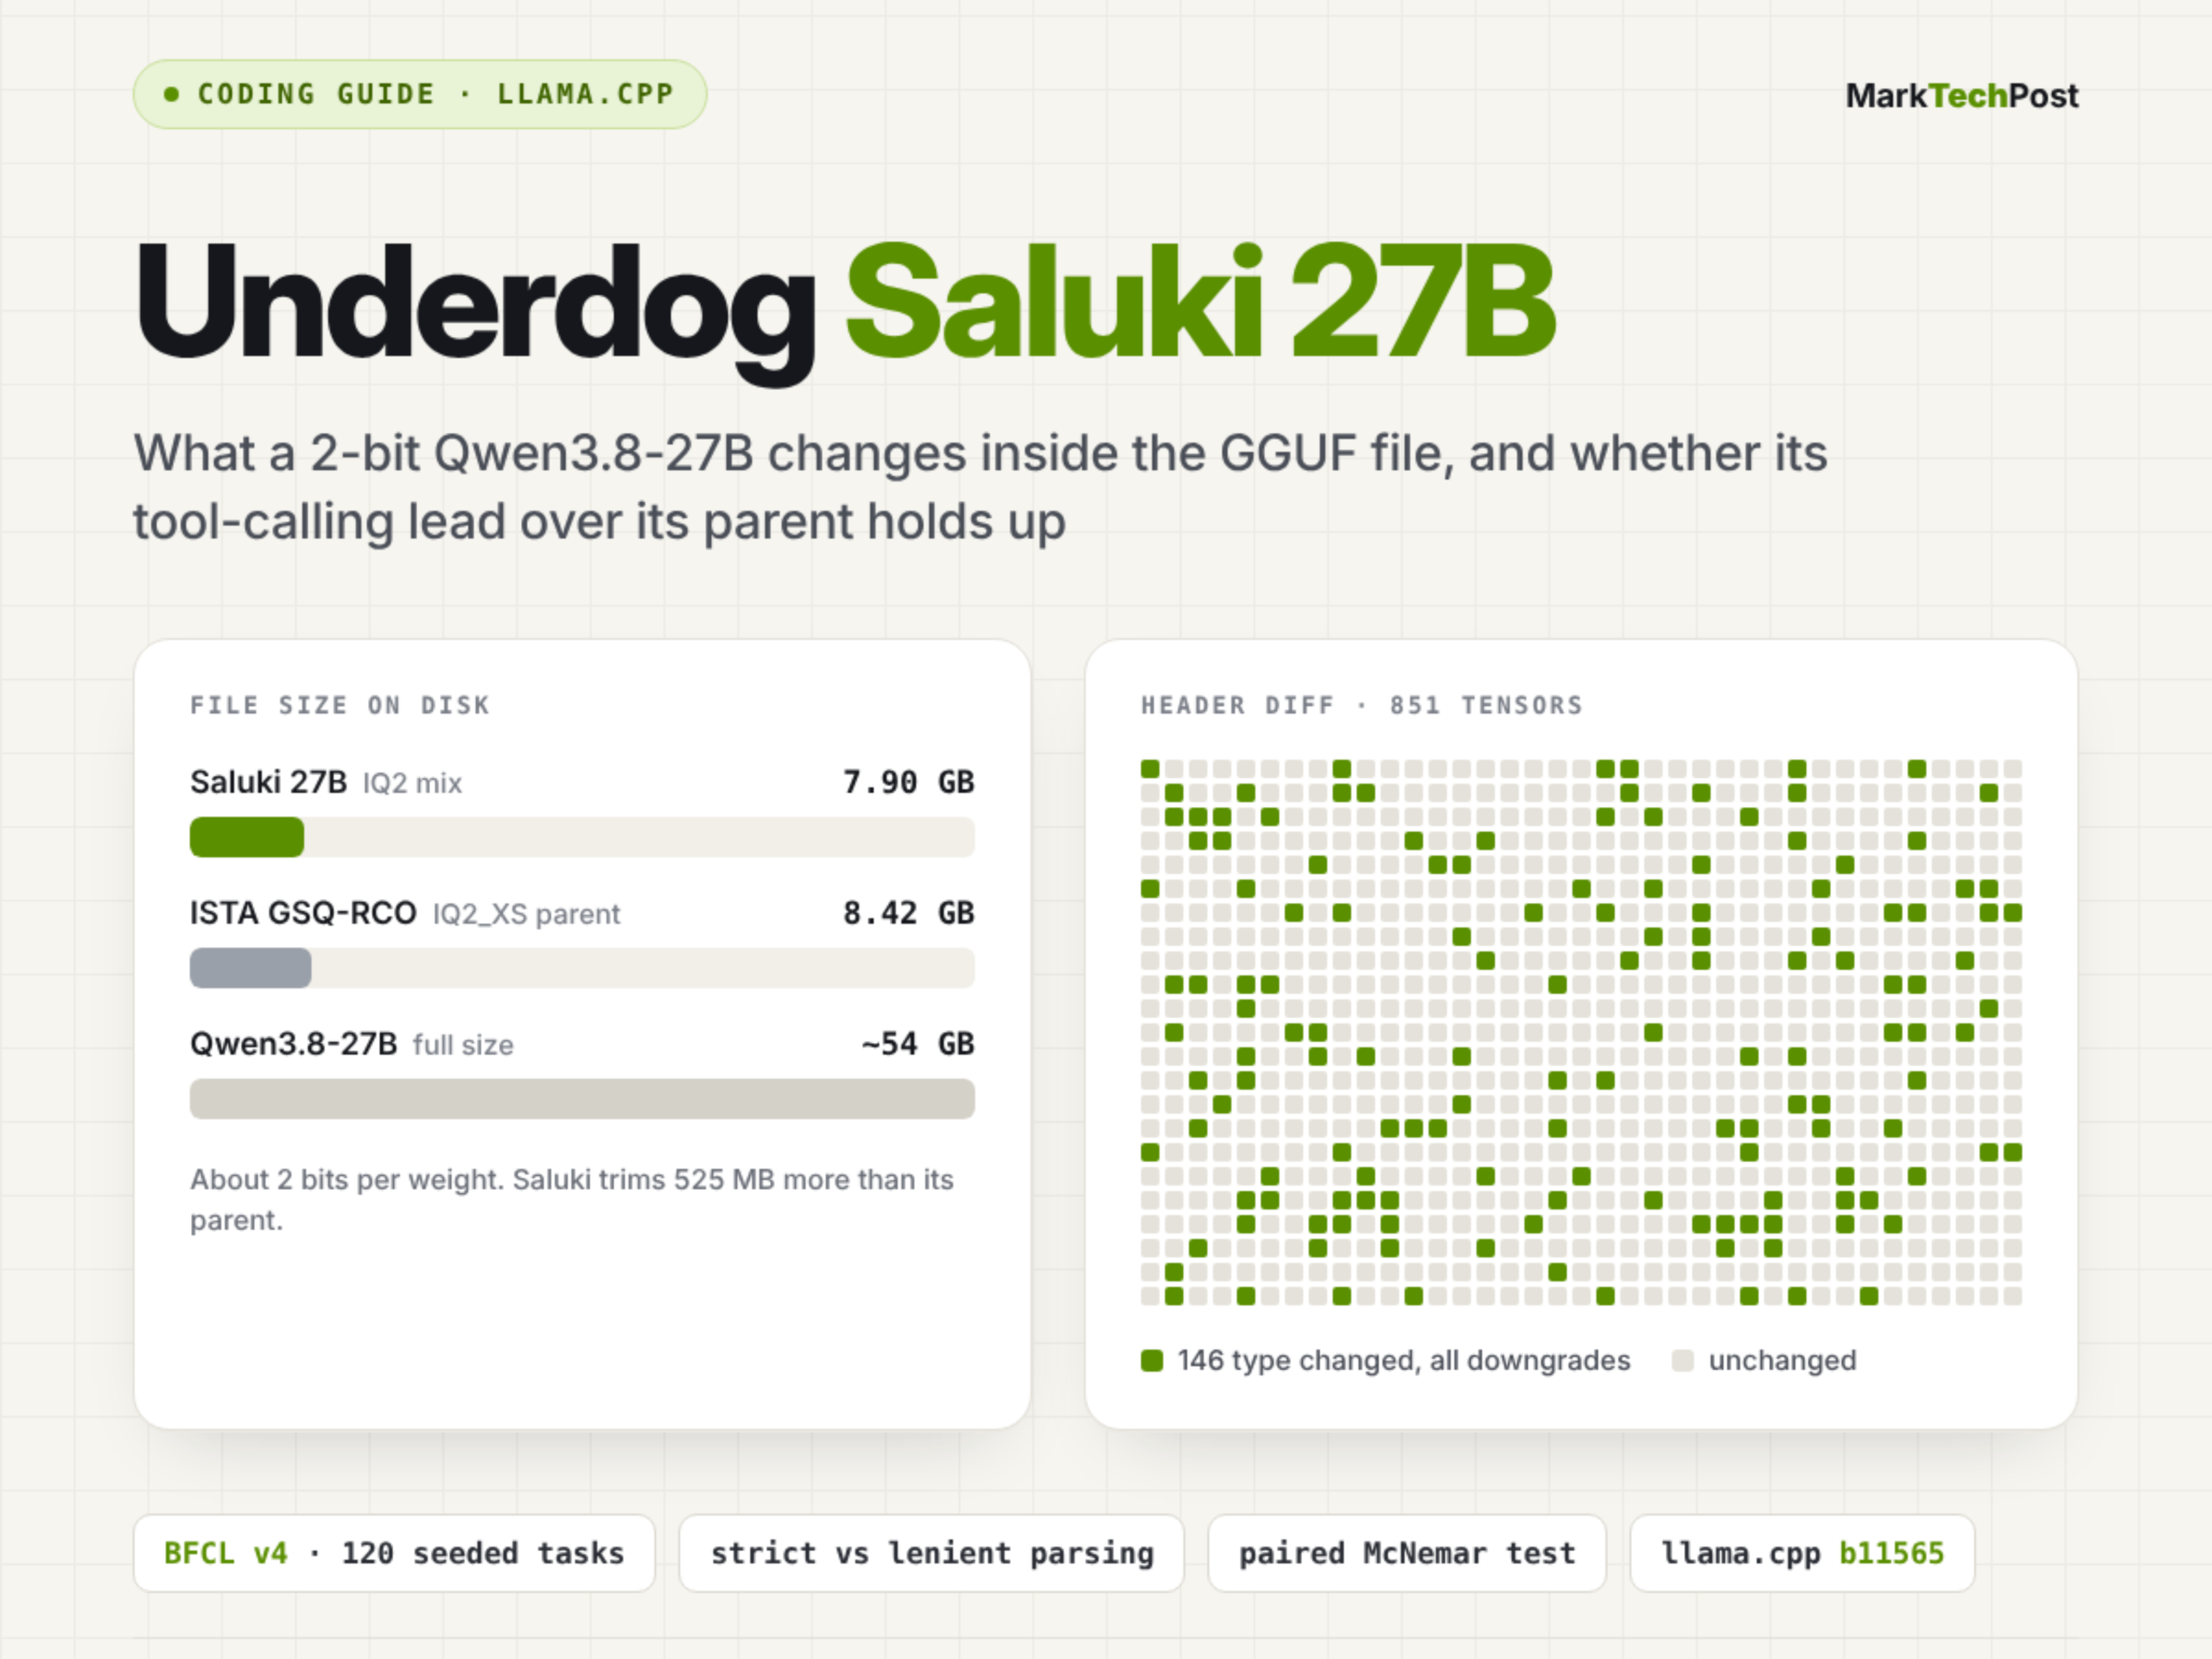
How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide
In this tutorial, we work with Underdog Saluki 27B, a 7.9 GB build of Qwen3.8-27B that its makers say keeps tool calling intact at about two bits per weight and even edges out the full 54 GB model on their own 120-task benchmark. Saluki is built on ISTA-DASLab’s GSQ-RCO quantization of the same model, so we put both files side by side in stock llama.cpp. We start with the files themselves: a tensor-by-tensor diff of the two GGUF headers, then a byte-level comparison that shows whether Sal
Get smart on it
The lesson for this story is being written.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Introducing GPT-6.1 Terra
Bringing fast and capable computer use to everyone
Also reported by SiliconANGLE
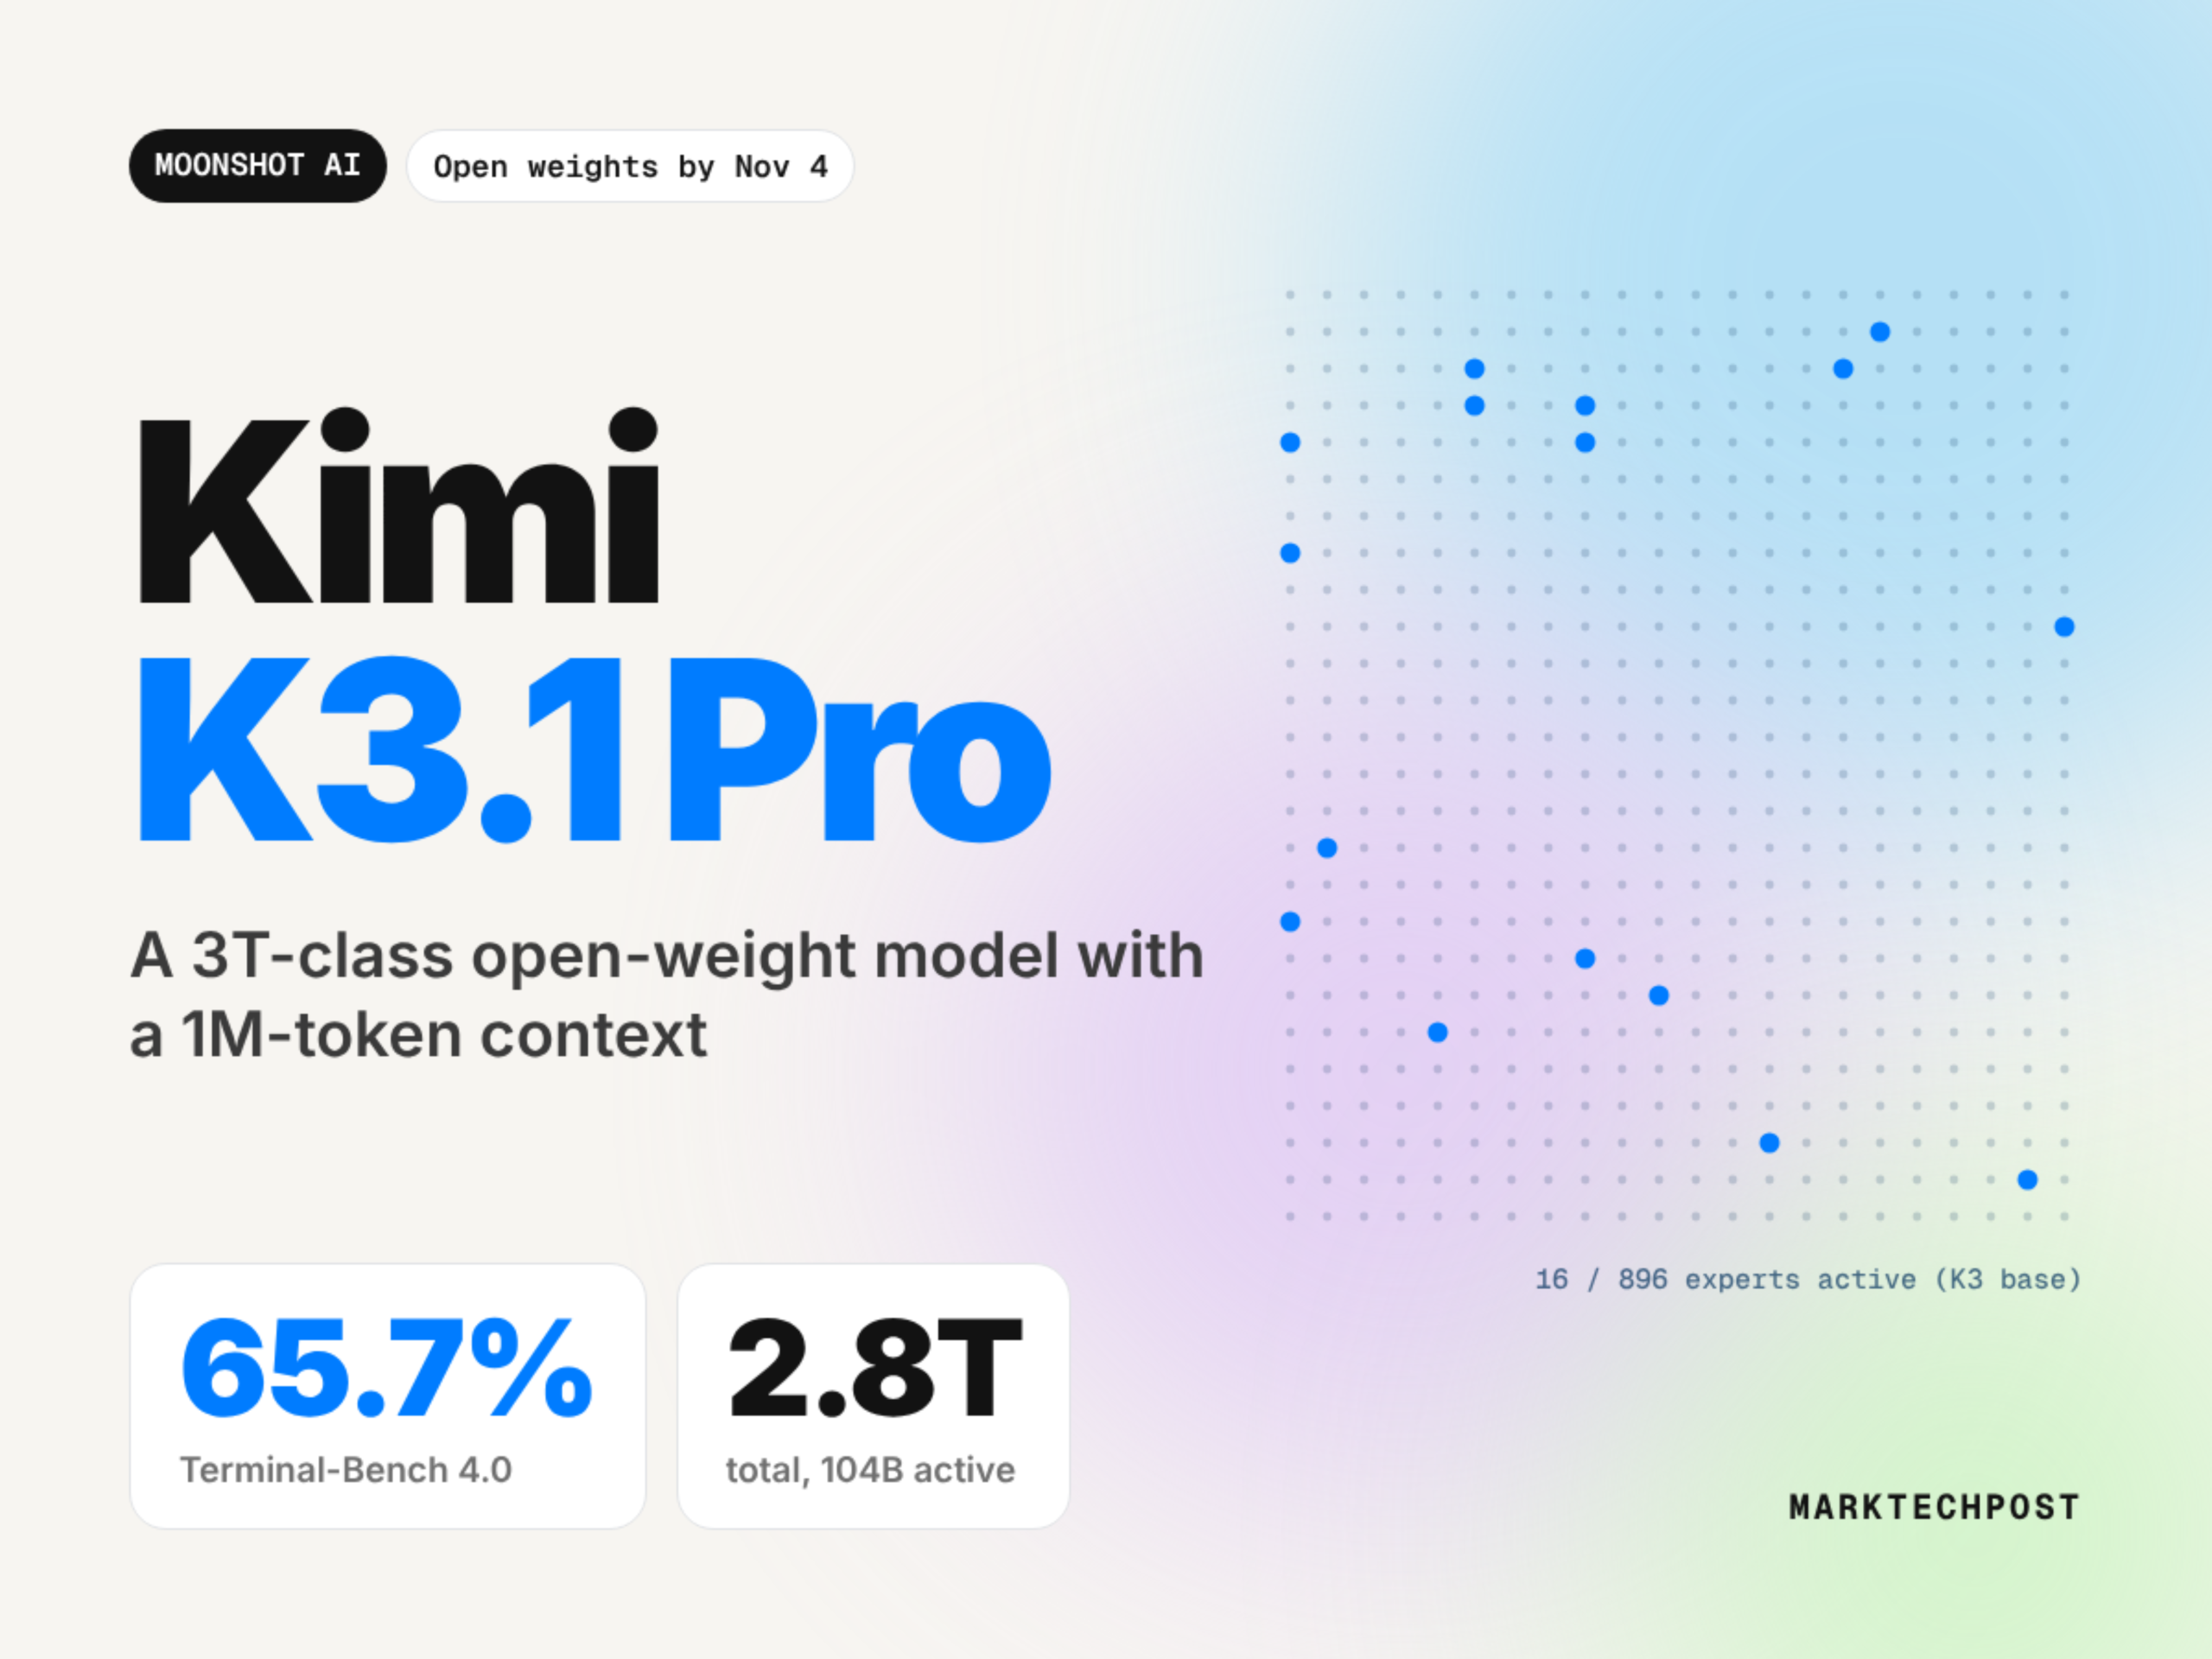
Moonshot AI Releases Kimi K3.1 Pro: A 2.8T Total/104B Active Params (MoE) Model with 1M Context
Moonshot AI has just released Kimi K3.1 Pro, the first model in its K3.1 series. Kimi K3.1 Pro is a 3T-class open-weight* model with a 1-million-token context window. Moonshot team positions it against the strongest proprietary models on coding, agentic and knowledge benchmarks. For developers, it is cheaper API pricing than K3 and open weights yet not available. *open weights are expected to release in November 2026. TL;DR Size: 2.8T total, 104B active parameters (MoE), 1M-token context
Also reported by SiliconANGLE and The Decoder

Jack Dorsey’s Block made an AI model that talks to you like an awkward new friend
Jack Dorsey's Block announced an AI model called Dessa that's trained "from scratch on nothing but human conversation," and to show off the model, Block shared chats it has had with humans that can occasionally be a little awkward and uncanny. Take this one, for example, shared by Dessa lead Ragavan Thurairatnam. The conversation between the model and the speaker does have a mostly natural back and forth (though for some reason, the model initially mistakes the speaker for some
Also reported by TechCrunch and The Decoder

Tsinghua AI Open-Sources AKV, a Cache Engineering Server for LLM Agents on SGLang
Tsinghua University and CUHK researchers open-sourced AKV, a serving system for KV cache engineering in LLM agents. Instead of summarizing old history, agents drop selected KV cache entries and keep reusing the rest. Across 3 models and 4 agent benchmarks, average cost falls 27.7%. Average task score rises 1.7 points. The code is Apache-2.0 licensed and builds on SGLang. TL;DR What it is: Serving system plus policy library, no weights. Tested on GPT-OSS-120B (5.1B active), MiniMax-M2.7 (

Canva releases its first image generation model
Canva is making its new image model available to all users, promising better, more customizable performance at lower costs.
Also reported by The Verge and The Decoder
Hugging Face Releases Carbon-X, a 14B Open DNA Language Model that Brings DNA and Natural Language Together for the First Time
Hugging Face has released Carbon-X, an open DNA language model with 14.8B parameters. Carbon-X is a decoder-only model from Hugging Face Bio. It reads raw DNA in a chat and answers in English. It predicts whether mutations are benign or pathogenic, flags regulatory regions, classifies organisms and predicts next bases. The weights ship under Apache 2.0, so labs can keep sensitive sequences on their own GPUs. Hugging Face built it with Zhongguancun Academy and TIGEM / University of Naples Federi