Alibaba Qwen introduces QwenGyre training framework
MarkTechPost: Alibaba Qwen Introduces QwenGyre: Elastic Reinforcement Learning RL for XLong-Horizon Agents
Alibaba’s Qwen team has introduced QwenGyre, an elastic reinforcement learning RL framework for extreme-long-horizon agent training. QwenGyre is an online reinforcement learning system from Alibaba that trains coding agents through unmodified, black-box harnesses. It targets rollouts that run for hours and process close to 1M tokens. The QwenGyre elastic RL framework was used on Qwen’s flagship Qwen 3.8 2.4T model. It rests on 2 core ideas. It moves idle GPUs between rollout and tra
Get smart on it
QwenGyre is a training framework that uses elastic reinforcement learning to teach AI agents to perform tasks spanning hours with hundreds of model interactions, such as generating full software repositories from specifications. The framework addresses two key bottlenecks: idle computing resources during long task executions and inefficient training data handling when agent runs branch into multiple paths. QwenGyre achieves this by dynamically shifting processors between rollout and training phases and by limiting training samples from branching agent histories to reduce computational overhead. Testing on large language models showed speedups of up to 1.85x compared to existing approaches, with task performance improving from 52.5% to 58.5% on one benchmark.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Meta releases its first frontier model, Muse Wonder
Meta's Superintelligence Lab released a pair of new state-of-the-art models on Monday, Muse Wonder and Muse Wonder Full, the company's first attempt at a frontier model.
Also reported by The Verge, Wired AI, The Decoder and SiliconANGLE
Odyssey-3 is a new generative world model that you can try for free
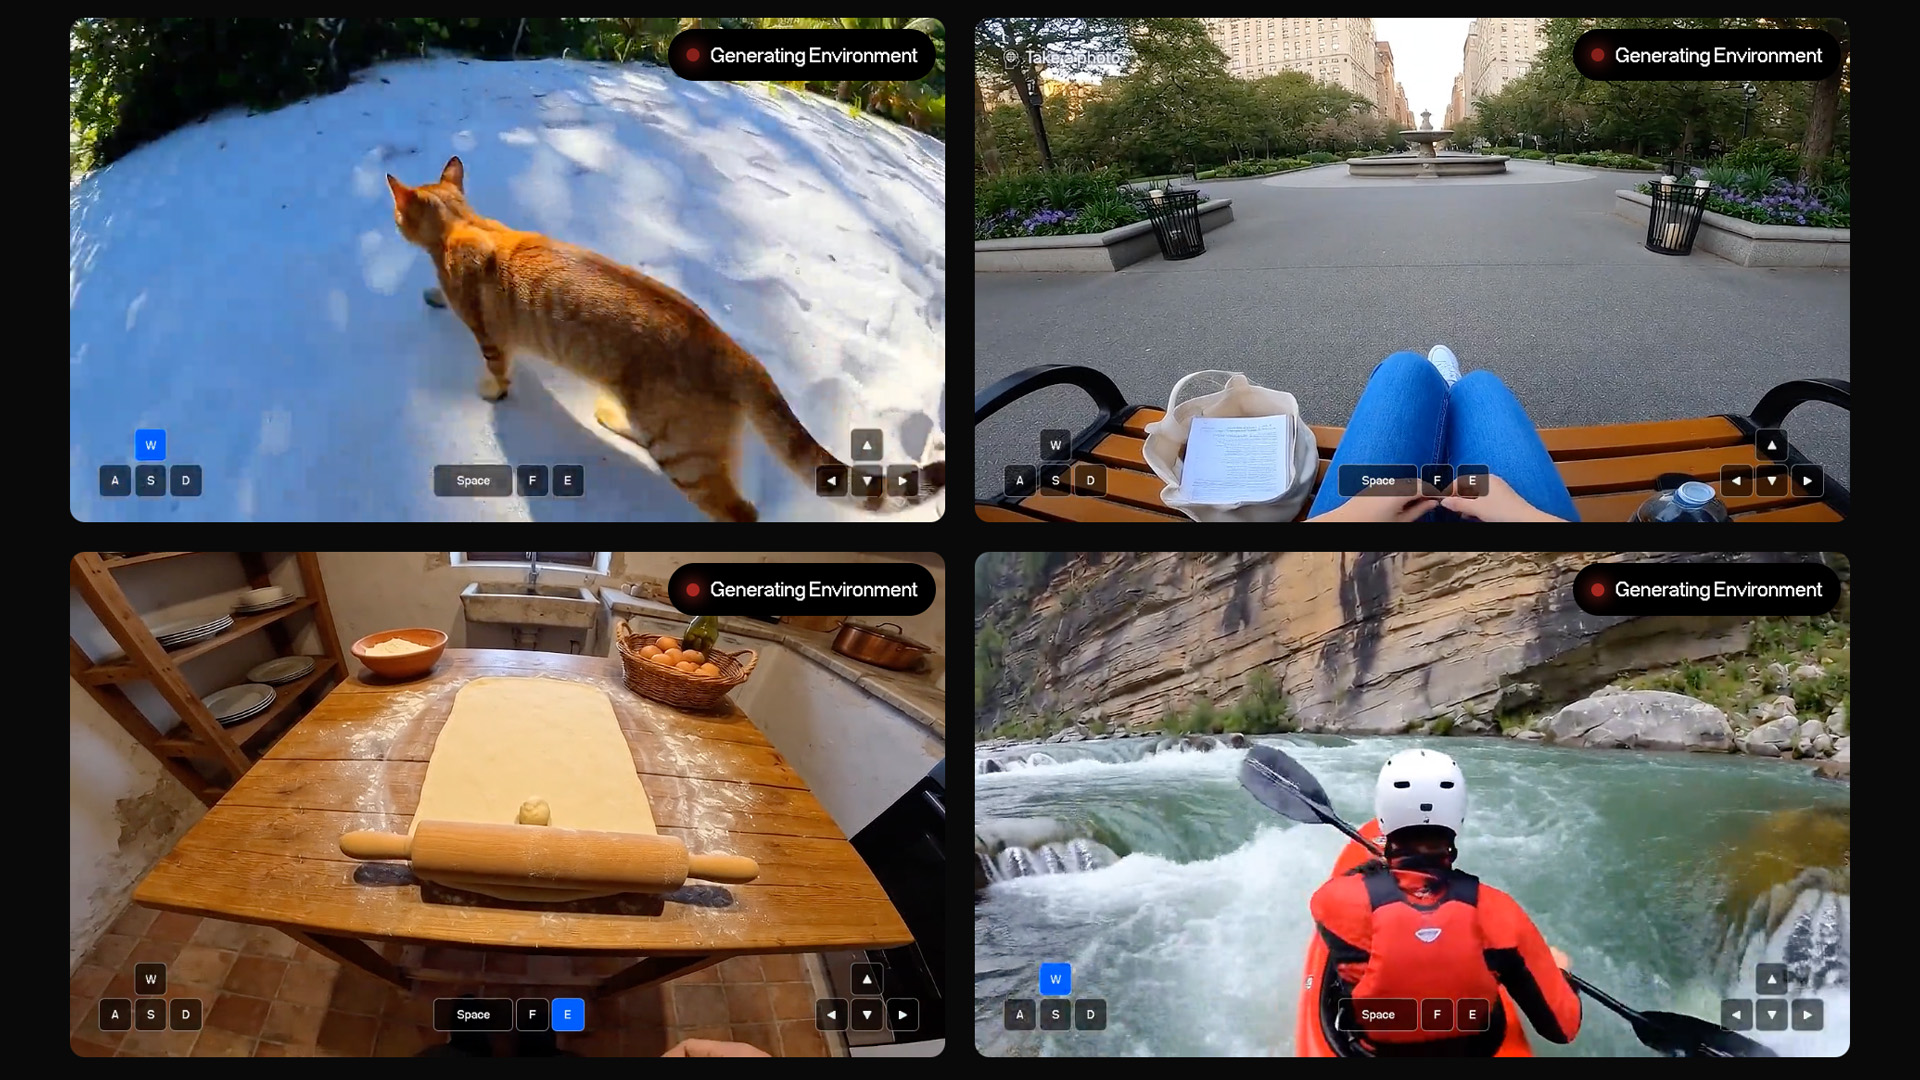
Odyssey is making its world model Odyssey-3 available as a public research preview. The 14-billion-parameter model generates interactive environments from text prompts in real time and can reportedly control robots, drones, and even GTA V. Odyssey claims top scores on physics benchmarks, though the methodology behind those results has limits. The article Odyssey-3 is a new generative world model that you can try for free appeared first on The Decoder.

The maker of non-text AI model Jev valued at $7.5B just weeks after launch
What has users and large corporations so excited about Jev is TypeSafe’s claim that it works significantly faster and uses far fewer tokens than LLMs.
OpenAI Decisions API Hits Public Beta With 10x Faster Typed Answers
OpenAI has released the Decisions API in public beta. It turns text and images into typed answers your code can branch on. OpenAI team states the OpenAI Decisions API runs about 10x faster than the Responses API. It targets a common pattern: prompt an LLM, then parse its text into a label. TL;DR Size: GPT-6 Luna parameter count is not disclosed. Its model card lists a 1,050,000-token context window. Runs on: OpenAI-hosted API only, via POST /v1/decisions. No open weights, no self-host
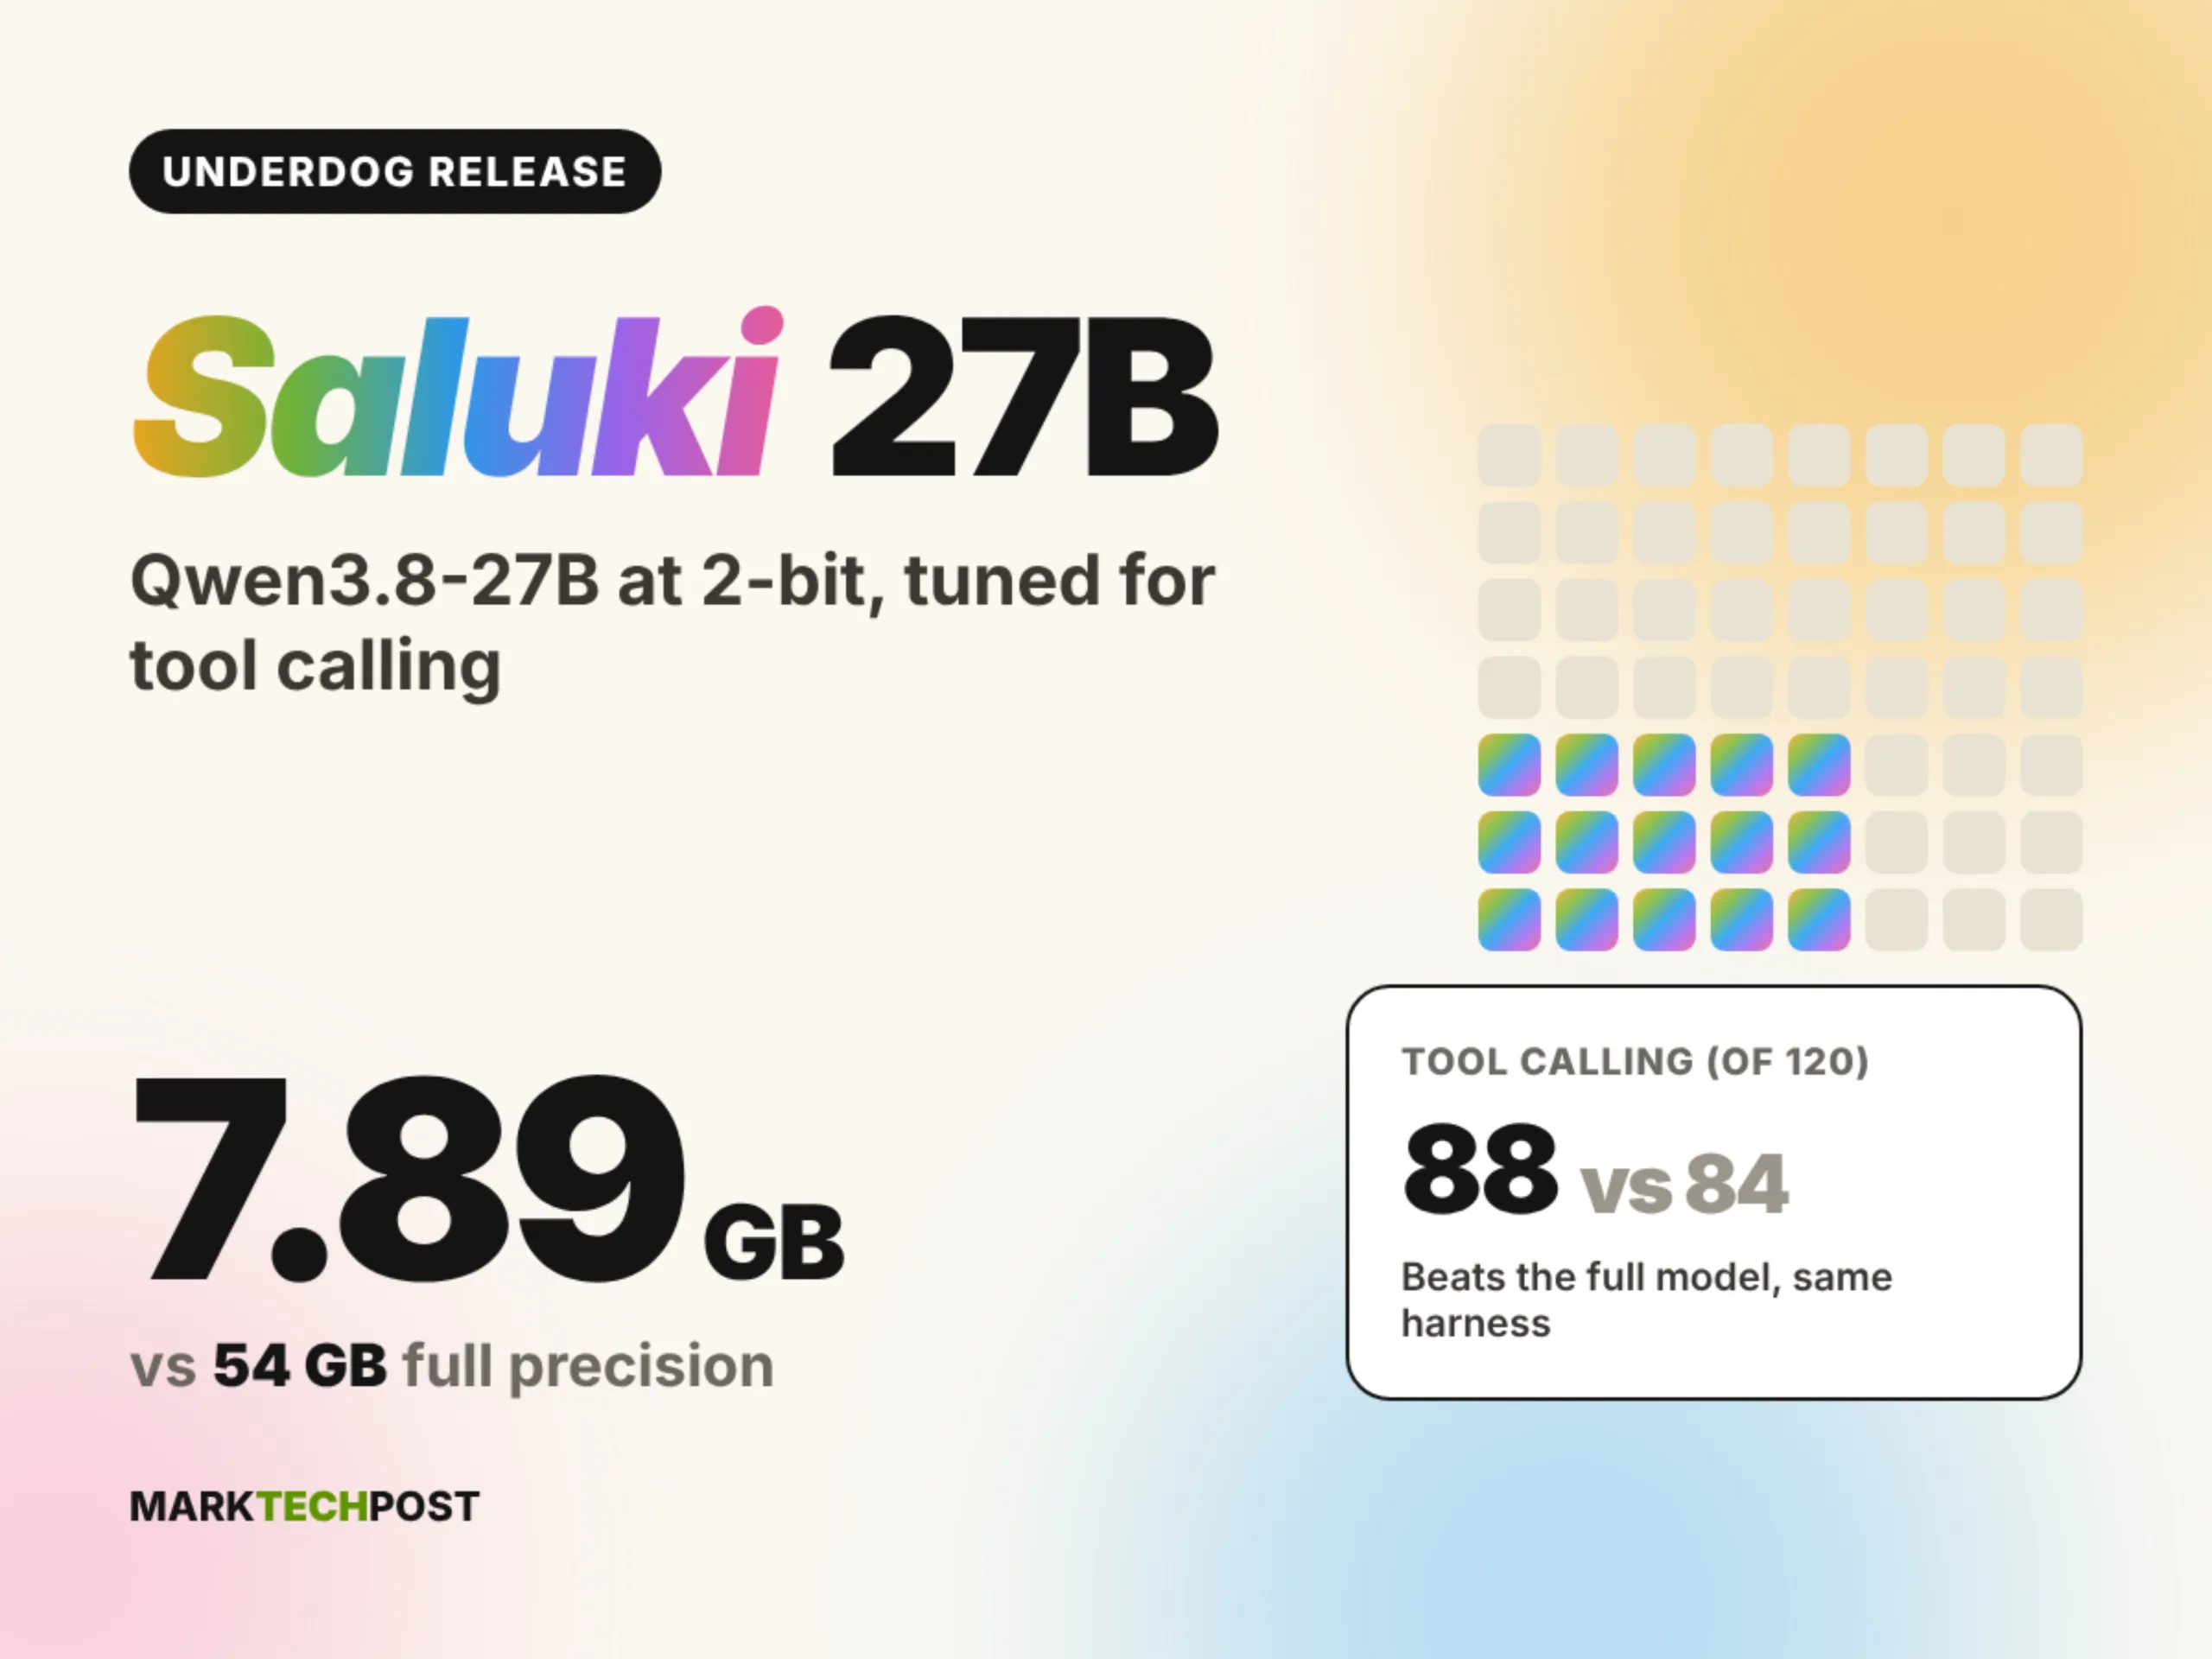
Meet the Underdog Saluki 27B: A 2-bit Qwen3.8-27B That Beats the Original at Tool Calling
Underdog, the on-device assistant from Conway Research, has released Saluki 27B under Apache 2.0. Underdog Saluki 27B is a 2-bit GGUF of Qwen3.8-27B that fits in 7.89 GB. The full BF16 model needs 54 GB. Underdog tuned the compression to protect tool calling, the skill that turns a chat model into an agent. For developers, that means a 27B-class agent model that runs in stock llama.cpp. TL;DR Size: 27B dense parameters. 7.89 GB GGUF versus 54 GB for BF16. Runs on: stock llama.cpp and

The model that didn't exist, so you made it yourself
Building custom models from scratch offers more control than relying on existing off-the-shelf options.