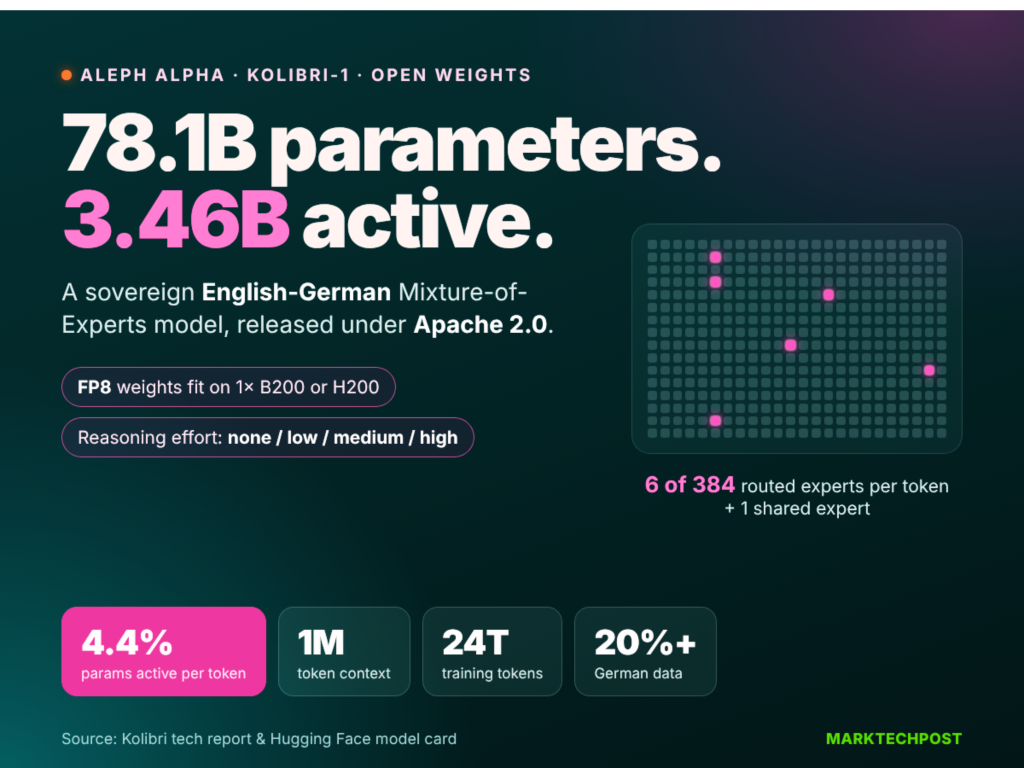
Aleph Alpha Releases Kolibri: A 78.1B Open-Weight English-German MoE Model With Only 3.46B Active Parameters
Aleph Alpha has released Kolibri, an open-weight Mixture-of-Experts (MoE) language model built for German and English. Kolibri has 78.1B total parameters but activates only 3.46B, or 4.4%, per token. It accepts up to 1,048,576 tokens of context, lets users set reasoning effort per request, and ships under the Apache 2.0 license on Hugging Face. The target is sovereign deployment in regulated sectors such as public administration, industry and aerospace. Is it deployable? Yes. The FP8 checkpo
Kolibri is an open-weight language model designed for English and German that contains 78.1 billion total parameters but only activates 3.46 billion per token, making it efficient to run on a single high-end GPU. The model uses a Mixture-of-Experts architecture where each token is routed to 6 out of 384 specialized experts plus one shared expert, and combines sliding-window attention with full attention layers to support up to one million tokens of context. It was developed entirely by teams in Germany using infrastructure in Germany and Finland, with training data that included over 20 percent German content, and is designed to meet European AI regulations including the EU AI Act and GDPR. The model is released under the Apache 2.0 license and benchmarks show it achieves the highest overall scores in English and German among comparable models while using fewer active parameters than denser alternatives.
Explainer: What Is a Mixture of Experts Model and Why Does It Use Fewer Resources?
- Introducing GPT-6.2 Astra and Sol · OpenAI
- Introducing Gemini 4 Neon · Google DeepMind
- Alibaba launches Qwen4-Max with training, attention optimizations · SiliconANGLE
- All of today’s AI news, biggest first →
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven
Introducing GPT-6.2 Astra and Sol
Introducing GPT‑6.2 Astra and Sol, with better professional outputs, coding, computer use, and efficiency at lower cost across ChatGPT Work, Codex, and the API.
Also reported by MarkTechPost and SiliconANGLE
Introducing Gemini 4 Neon
Google's latest model aims to compete with rival systems in reasoning and multimodal capabilities as the AI arms race intensifies.
Also reported by SiliconANGLE and MarkTechPost

Alibaba launches Qwen4-Max with training, attention optimizations
Alibaba Group Holding Ltd. today introduced Qwen4-Max, its newest and most capable large language model. The algorithm not only generates higher-quality output than its predecessor but also costs less. Those improvements are the result of a new architecture, Qwen4, that made the LLM’s training run more efficient. Additionally, Alibaba has equipped the model with an […] The post Alibaba launches Qwen4-Max with training, attention optimizations appeared first on SiliconANGLE.

Rumble-2-Flash: an open 0.5B speech model for 40+ languages
Smaller open-source speech models could democratize voice AI for developers working with languages beyond English and major European tongues.
Also reported by SiliconANGLE

Genie 4 is now available
The latest version expands capabilities for developers building generative applications across different domains.

Microsoft rolls out new first-party models and updates to agentic AI continuous improvement
Microsoft Corp. today rolled out new generative artificial intelligence models and updates to Foundry, the company’s unified enterprise platform that helps developers and organizations ground, test and deploy AI applications and autonomous agents. Updates to Foundry IQ, part of Microsoft IQ, now provide an enterprise knowledge graph out of the box, delivering a full estate […] The post Microsoft rolls out new first-party models and updates to agentic AI continuous improvement appeared firs