
Google Cloud releases llm-d 1.0 distributed inference stack
MarkTechPost: Google Cloud Ships llm-d 1.0 With Cache-Aware Routing for TPU and GPU Fleets
Google team have released llm-d 1.0, the first stable version of its distributed inference stack. This open-source, Kubernetes-native layer turns vLLM or SGLang model servers into one coordinated pool. They released it at the PyTorch Conference North America. It targets self-hosted agent and RL workloads, where round-robin load balancing breaks down. TL;DR A serving stack: Google reports a published benchmark on a 17,000-node multi-region GKE deployment. Runs on: Kubernetes with NVID
Get smart on it
llm-d 1.0 is a distributed inference stack that coordinates multiple model servers into a single pool to serve AI language models more efficiently across computer clusters. The system uses cache-aware routing to send requests to whichever server already holds the relevant cached data, reducing redundant computation and improving response times. This matters for self-hosted AI agents and similar workloads where traditional load balancing approaches fail to optimize performance. The technology was developed collaboratively by multiple organizations and is now in its first stable release, with reported performance gains including nearly 3x throughput improvements on large-scale deployments.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Hugging Face ❤️ TorchTPU: TPUs, Natively
Tighter integration between the popular open-source platform and Google's specialized processors could lower barriers for researchers training large models.
Also reported by MarkTechPost and SiliconANGLE

Google has joined Amazon in attacking Nvidia’s stronghold with AI app developers
Google has joined Amazon in releasing a developer tool that makes it easy for PyTorch users to move their apps off Nvidia GPUs.

CoreWeave’s debt is becoming the whole AI industry’s problem
CoreWeave had a bad week last week. Its bonds slipped into distressed territory by a common definition - when investors demand 1,000 basis points more in yield than they'd get from government bonds. Last Tuesady Chamath "SPAC King" Palihapitiya noticed the distressed debt, and also asked whether the AI buildout was a private credit bubble. Its shares are down more than 20 percent since Tuesday's close, which is kind of a lot! There even seemed to be some collateral damage in th

Amazon is taking its biggest shot at Nvidia yet with new TorchNeuron dev tool
Amazon wants to break Nvidia’s hold on PyTorch, the free toolkit used to build most AI apps, so that more developers run their apps on alternative chips like its own.
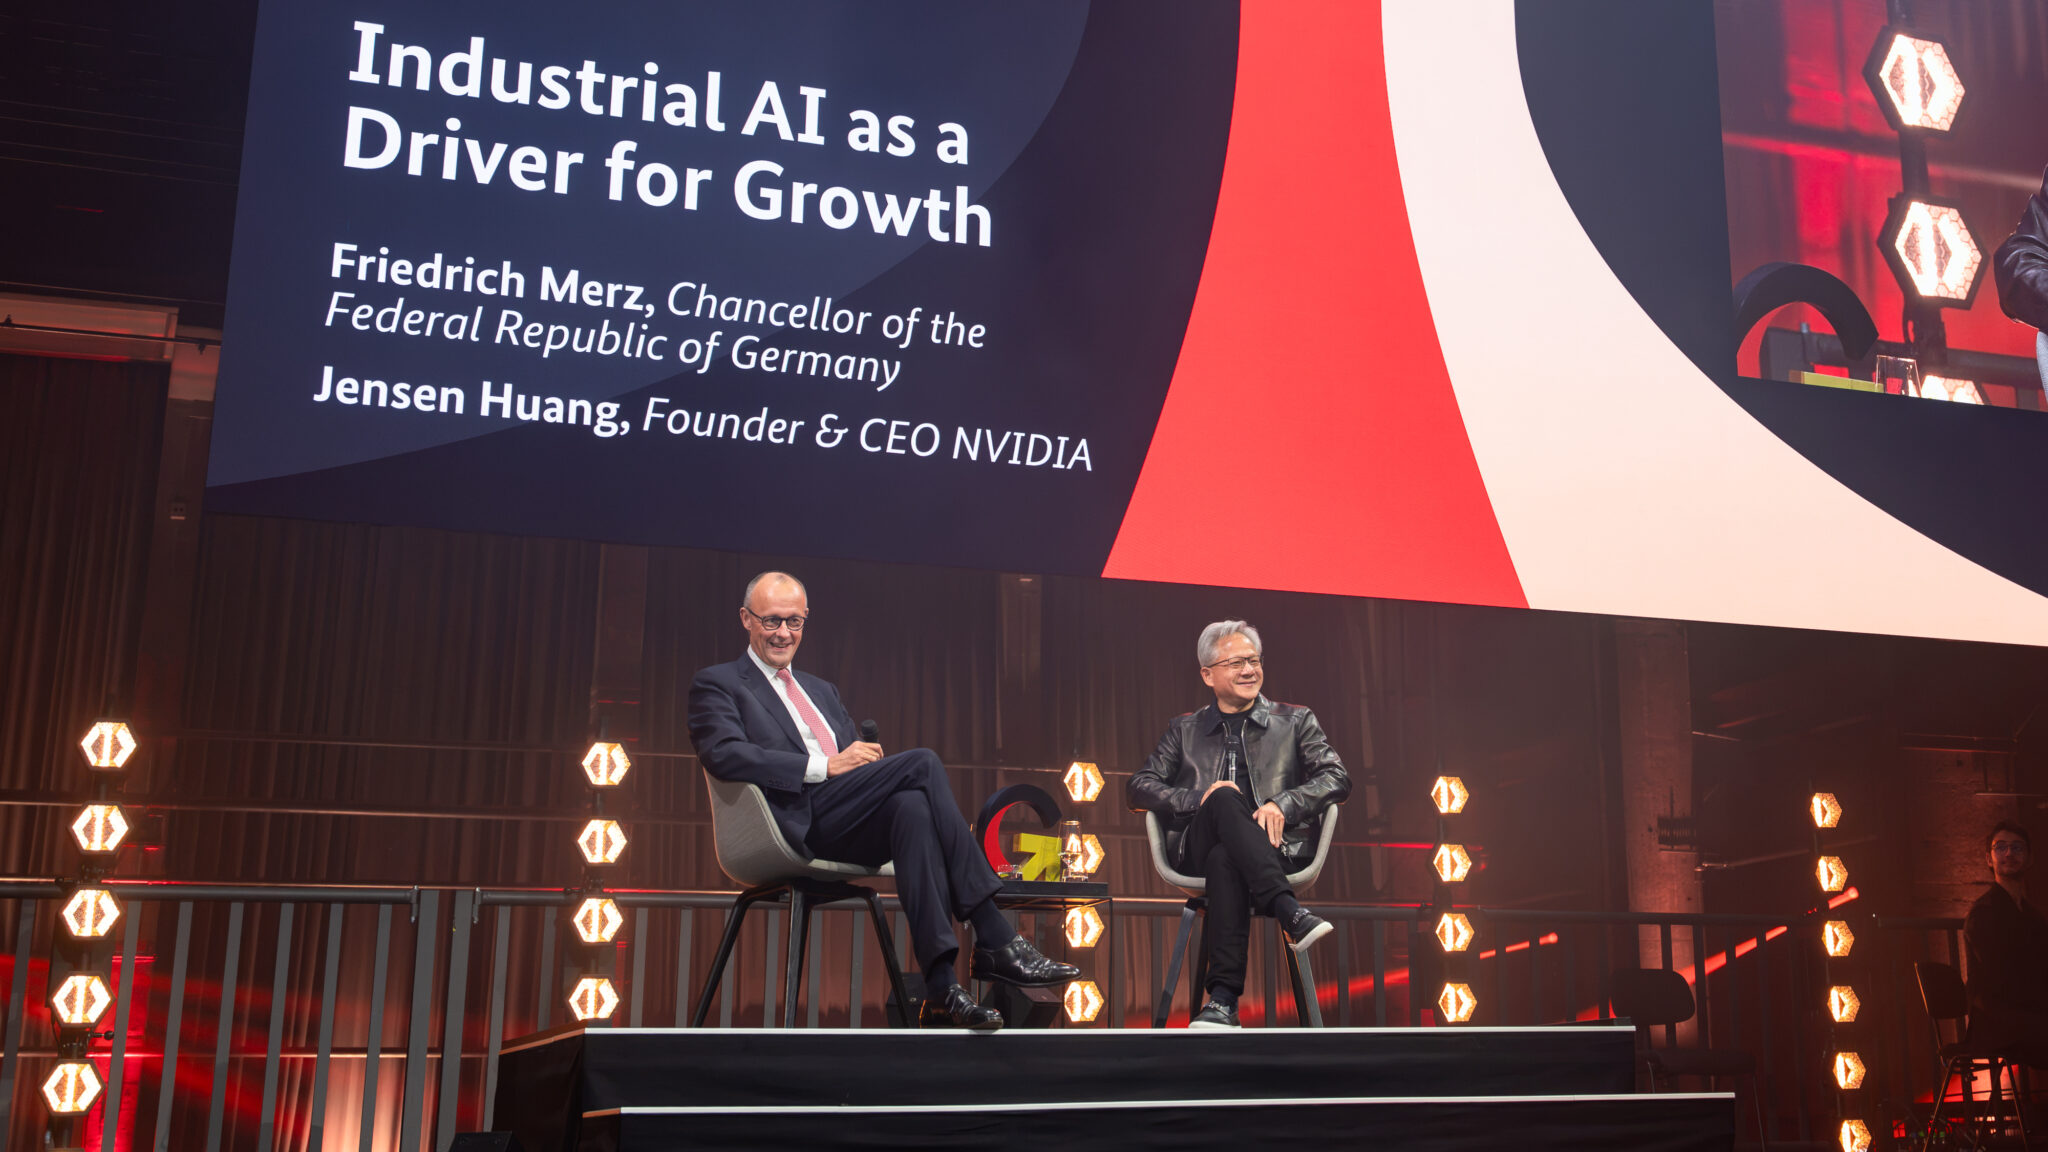
Germany Wants to Lead the World in Industrial AI: How NVIDIA Will Help
In the cavernous hall of Kraftwerk, a former power station in Berlin, German Chancellor Friedrich Merz and NVIDIA founder and CEO Jensen Huang sat down to discuss Germany’s AI roadmap, and in particular, the industrial applications of AI. Huang opened by tracing NVIDIA’s longstanding relationship with German industry, beginning with gaming systems, workstations and automotive design in the early 2000s and leading to today’s partnerships in autonomous vehicle development and digital twins for man
The neocloud shakeout is coming, and Nvidia has the most to lose
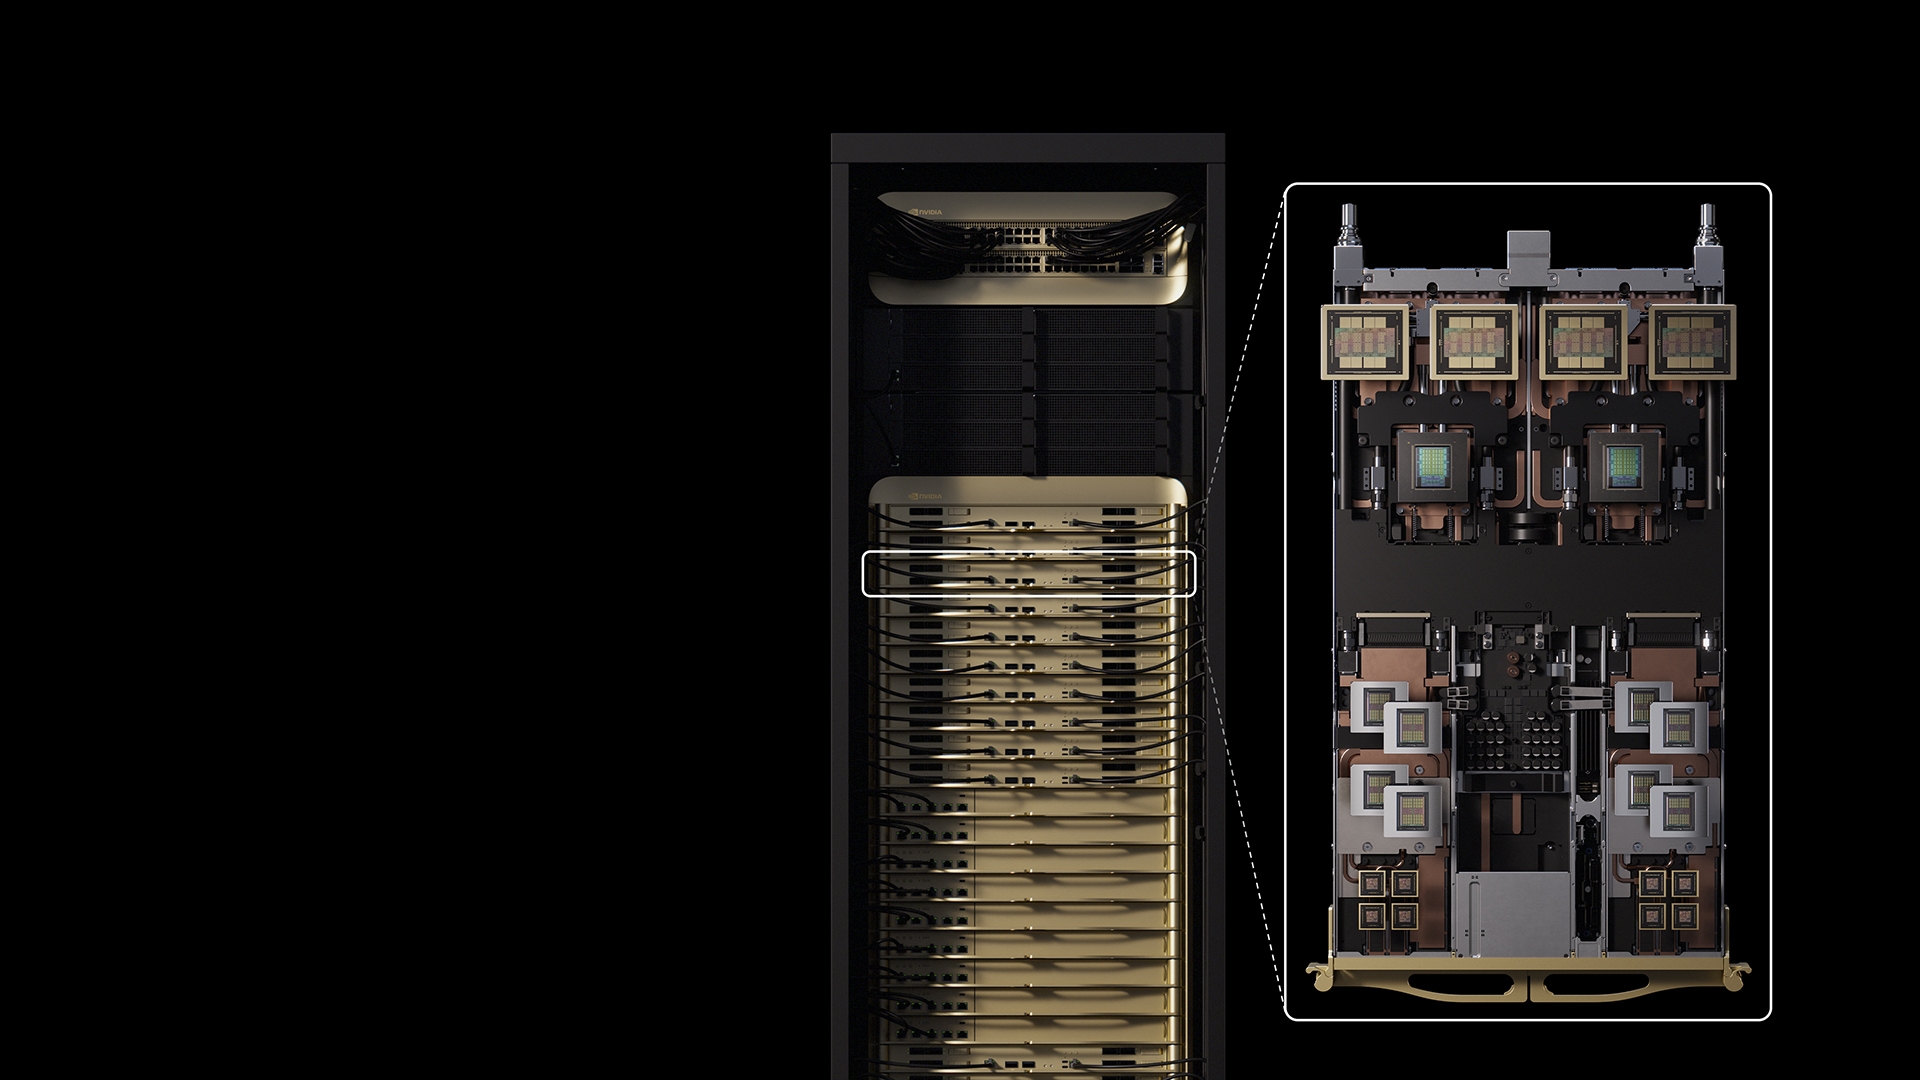
After stock crashes and Firmus's scrapped IPO, industry executives expect only seven to ten of the hundreds of AI cloud providers to survive. CoreWeave lost a quarter of its market value, and Microsoft pulled out of a deal with Nscale for 23,000 Nvidia chips. Nvidia has a lot riding on the outcome, since customers outside the hyperscalers make up 45 percent of its data center revenue. The article The neocloud shakeout is coming, and Nvidia has the most to lose appeared first on The Deco