
What We Learned by Reproducing 2,200 papers from ICML
Researchers found significant gaps when attempting to verify published machine learning results, raising questions about reproducibility standards in AI research.
A hackathon challenged community members to reproduce papers from a major AI conference using coding agents, with over 1,200 participants attempting to verify claims from about a third of the conference's accepted papers. The effort matters because the number of papers submitted to conferences has grown exponentially while reviewer capacity has not, making it difficult for human reviewers to thoroughly check research before publication. Coding agents can now attempt detailed verification work in hours rather than the days or weekends required by human reviewers, enabling large-scale checking of scientific claims. The results found that about half of examined papers had at least one claim independently verified, roughly a quarter had at least one claim falsified or contested, and the remainder had incomplete or inconclusive evidence.
- MLCommons Releases MLPerf Training v6.1 Results, Spotlighting Recent Advances in AI Training · MLCommons
- MLPerf Training v6.1: Bigger Clusters, Broader Hardware, and the Rise of Software-Driven Gains · MLCommons
- Research acceleration: The jagged frontier · OpenAI
- All of today’s AI news, biggest first →
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven
MLCommons Releases MLPerf Training v6.1 Results, Spotlighting Recent Advances in AI Training
Today, MLCommons® announced new results for the MLPerf® Training v6.1 benchmark suite. The two new benchmarks added in this round, and the submissions received, demonstrate the impact of recent architectural advances in AI training systems and the increasing diversity of the hardware used to train them. “We’ve reached an exciting new threshold for the MLPerf Training benchmark suite, with a higher level of participation in this round, the representation of both established and emerging hardw
Also reported by NVIDIA Blog
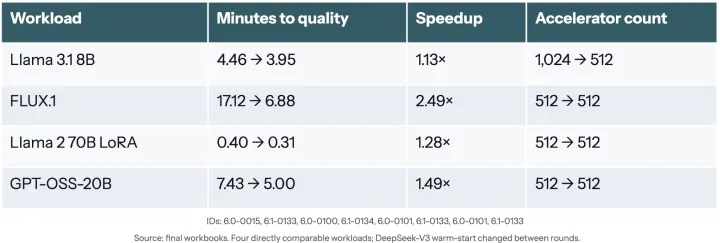
MLPerf Training v6.1: Bigger Clusters, Broader Hardware, and the Rise of Software-Driven Gains
The round at a glance MLPerf® Training v6.1 expands the benchmark suite and features even larger systems from our members. Two benchmarks join the suite: Qwen3.5-397B GRPO for agentic reinforcement learning, and DLRMv4-HSTU, a generative recommender. Google’s Ironwood and NVIDIA’s Rubin make their debut as Available systems. The largest jobs reached 10,240 GPUs (NVIDIA on GB300 and Azure on GB200, both training DeepSeek-V3) [1, 2], multi-node systems rose to 76% of the total, and the hardwar
Research acceleration: The jagged frontier
OpenAI measures how coding agents are accelerating AI research, where their performance remains uneven, and what this signals about recursive self-improvement.
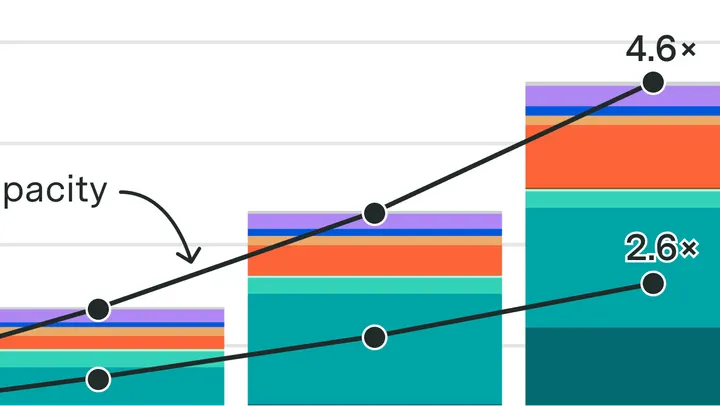
Agentic inference capacity grew 4.6× in a year, versus 2.6× for compute capacity
Our Inference Performance Index and chip sales data show agentic inference capacity grew nearly twice as much as 8-bit compute.
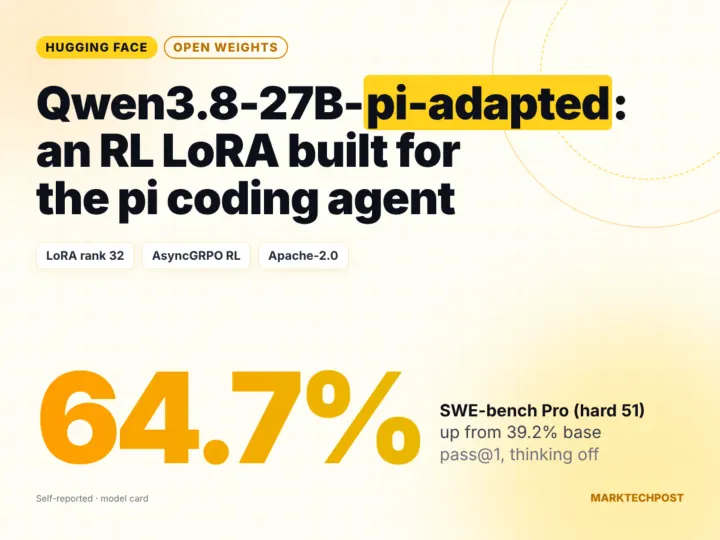
New LoRA Adapter Lifts Qwen3.8 Coding Success From 39% to 65%
Hugging Face’s harness-hub team has released Qwen3.8-27B-pi-adapted, a LoRA adapter for Qwen3.8-27B. It was trained with reinforcement learning to work inside the pi coding agent. The Qwen3.8-27B-pi-adapted LoRA adapter targets one harness instead of general chat. For developers running local coding agents, that is the point. You keep the open base model and swap in a small, harness-specific adapter. TL;DR Size: LoRA rank 32 (alpha 64) on Qwen3.8-27B, a 27B dense hybrid with 262,14
How good are Fable 5.2 and GPT-6.2 Astra at real work?
We tested Fable 5.2, GPT-6.2 Astra, and four other models on real Epoch work tasks. None met our employee standard, including the two that top our ECI.