
Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning
Comparing speech synthesis systems across languages and voices has lacked standardized metrics, making it harder to track progress in this rapidly advancing field.
The Open TTS Leaderboard is a tool for evaluating text-to-speech models using objective metrics like word error rate, processing speed, and speaker similarity, rather than relying solely on human preference voting. Existing arena-based leaderboards that compare models through user votes cannot keep pace with the rapid release of open-source TTS models and face challenges with voter consistency over time. This leaderboard addresses those limitations by using automated metrics that reduce evaluation time from weeks to hours, though the creators acknowledge these metrics do not directly measure naturalness or listener preference. The leaderboard supports multilingual evaluation and voice cloning comparisons, and includes a separate section where users can listen to and vote on model outputs to complement the objective metrics.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
- MLCommons Releases MLPerf Training v6.1 Results, Spotlighting Recent Advances in AI Training · MLCommons
- Anthropic says AI is eroding Nvidia's CUDA lead, cutting an AMD chip switch from months to three days · The Decoder
- Google Deepmind's AlphaProof Code verified Signal's cryptographic core in four weeks instead of years · The Decoder
- All of today’s AI news, biggest first →
One short email a day with the stories that matter. Free. Unsubscribe with one click.
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on Maven
MLCommons Releases MLPerf Training v6.1 Results, Spotlighting Recent Advances in AI Training
Today, MLCommons® announced new results for the MLPerf® Training v6.1 benchmark suite. The two new benchmarks added in this round, and the submissions received, demonstrate the impact of recent architectural advances in AI training systems and the increasing diversity of the hardware used to train them. “We’ve reached an exciting new threshold for the MLPerf Training benchmark suite, with a higher level of participation in this round, the representation of both established and emerging hardw
Also reported by NVIDIA Blog
Anthropic says AI is eroding Nvidia's CUDA lead, cutting an AMD chip switch from months to three days
Anthropic claims it used AI itself to breach Nvidia's CUDA moat. The company's in-house model Mythos reportedly ported Claude to AMD GPUs in just three days, with almost no human intervention. Anthropic now runs Claude on four chip families and aims to cut costs and reduce vendor dependencies. The article Anthropic says AI is eroding Nvidia's CUDA lead, cutting an AMD chip switch from months to three days appeared first on The Decoder.
Google Deepmind's AlphaProof Code verified Signal's cryptographic core in four weeks instead of years
Google Deepmind's AlphaProof Code mathematically verified Signal's cryptographic core code in four weeks, a process that typically takes years. AI agents powered by Gemini Carbon wrote more than six million lines of proof code and flagged only about one percent for human review. Deepmind plans to extend the method to critical infrastructure like power grids and medical devices. The article Google Deepmind's AlphaProof Code verified Signal's cryptographic core in four weeks ins

A step toward defining the Standard Model on a lattice
Explore a candidate nonperturbative lattice definition of the Standard Model and how GPT-6 Astra helped turn the idea into a detailed proof.
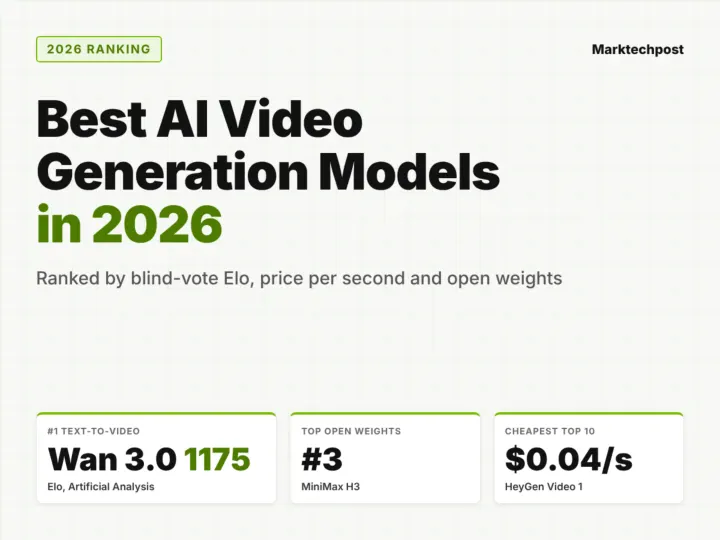
Best AI Video Generation Models in 2026: Elo, Price per Second, Open Weights
The AI video leaderboard looks very different from 12 months ago. Native audio is now table stakes. Clips run 15–30 seconds. And an open-weights model sits in the top 3. This ranking (as of Nov 13, 2026) uses one quality signal: blind human-preference Elo from the Artificial Analysis Video Arena. We pair it with API price per second and the license status of the weights. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension. Methodology Qua
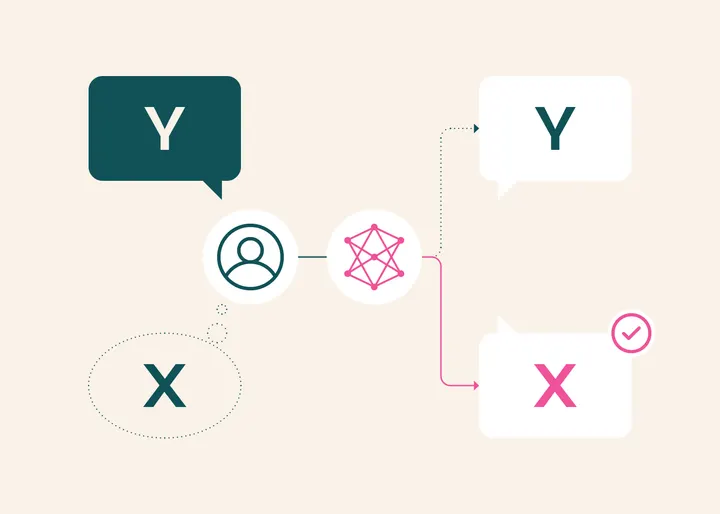
XYBench: Helping with the problem behind the question
Understanding what a question actually asks matters more than raw performance scores for building reliable AI systems.