MLCommons to develop MLPerf Agents benchmark
MLCommons: MLCommons Selected as Benchmarking Team for U.S. National Science Foundation–Backed AI Efficiency Challenge to Build MLPerf Agents
MLCommons has been selected as the Benchmarking Team for the STRIDE Ventures AI Efficiency Challenge, a program supported by the U.S. National Science Foundation Directorate for Technology, Innovation and Partnerships (NSF TIP). Through a $3.5 million award over two years, MLCommons will develop MLPerf Agents, a new benchmark that measures how efficiently agentic AI systems get real work done — from a delegated goal all the way to a verified outcome As a nonprofit consortium composed of comp
Get smart on it
MLCommons has been selected to develop MLPerf Agents, a new benchmark funded by a multiyear award from the U.S. National Science Foundation to measure how efficiently complete agentic AI systems accomplish tasks from start to finish. Unlike existing benchmarks that primarily measure model speed, MLPerf Agents will evaluate the entire workflow including the agent harness, model selection, tool execution, and failure recovery, while verifying that tasks are actually completed successfully. This matters because agentic AI systems work differently than single-prompt models, operating across multiple turns, calling tools, and managing growing context, requiring measurement approaches that capture this complexity. The benchmark will initially focus on software engineering, research and data analysis, and customer service workloads, helping both developers optimize efficiency and buyers make informed choices about agentic systems.
Explainer: How to Actually Read an AI Benchmark (Without Being Fooled)
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news

Elorian’s first AI model wants to reason with images, not just about them
According to Elorian's evaluations, Glimpse outperforms even GPT-6 Astra on scientific chart reasoning and short-form video captioning, with competitive results on other visual reasoning tasks.
Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months
Google Deepmind's Gemini 4 Argon scored 97.5 percent on the ARC-AGI-3 benchmark, making Google the second lab after OpenAI to cross the 95 percent mark. But the results swing wildly depending on the test setup: in the standard harness, the score drops to just 49.8 percent. Argon also trails rivals in math and software engineering. The article Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months appeared first on The Decoder.
GPT-6-Astra solves 49 of 50 physics research problems at $2.40 apiece
On the TheoPhysEval benchmark, GPT-6-Astra solves 49 of 50 unpublished theoretical physics calculations as accurately as leading specialists. In some cases where the agent seemed to fail, the experts' own reference solutions turned out to contain errors. But the researchers say physics hasn't had a breakthrough like the ones in mathematics, because the agents lack "taste." They still think autonomous, top-level AI research could arrive soon. They already see consequences for how young p
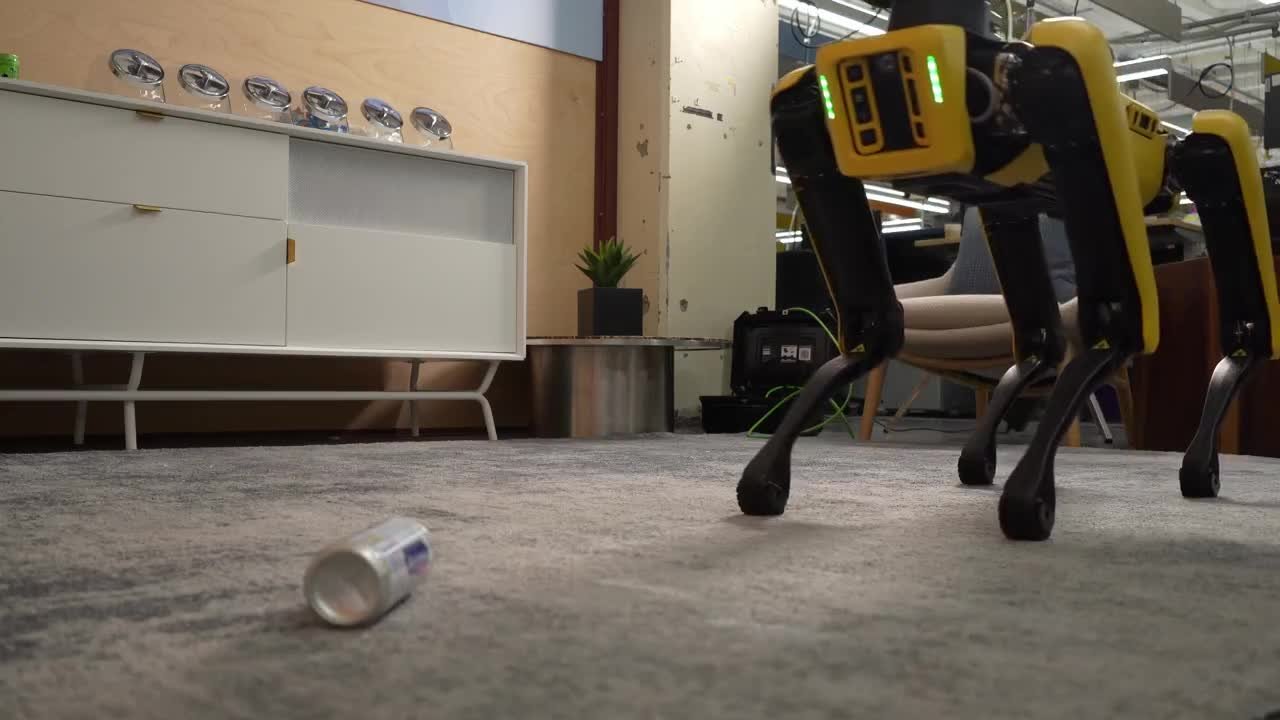
Google wants Gemini 4 Argon to be the only AI model robots need
Google's Gemini 4 Argon controls robots, generates simulations from photos or sketches, and evaluates training videos. On Google's own ERQA benchmark, it scores 87 percent. But the published example prompts show that the demos still need a lot of human guidance. The article Google wants Gemini 4 Argon to be the only AI model robots need appeared first on The Decoder.
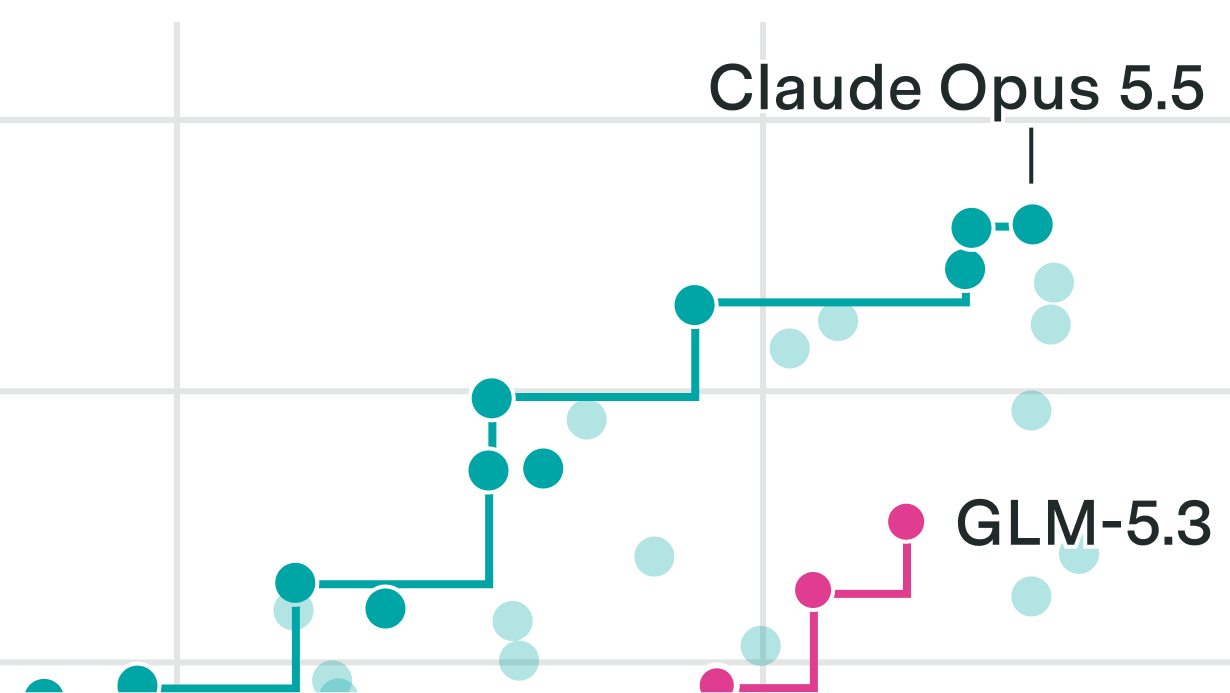
Open-weight models trail closed models in cyber capabilities by 6–7 months
Z.ai’s GLM-5.3 is the top open-weight model on Epoch’s Cyber ECI, scoring where the closed-weight frontier stood 6–7 months earlier.

The AI race is back on
Last week, Anthropic and OpenAI looked like they had the AI race to themselves, pulling ahead with increasingly powerful models that left their rivals in the dust. Google seemed hopelessly far behind, while Meta, despite spending billions to revive its floundering AI ambitions, had yet to establish itself as a serious contender. Even the latest models coming out of China, impressive as they were, appeared to be playing catch-up. Then, in the space of a few days, everything chan