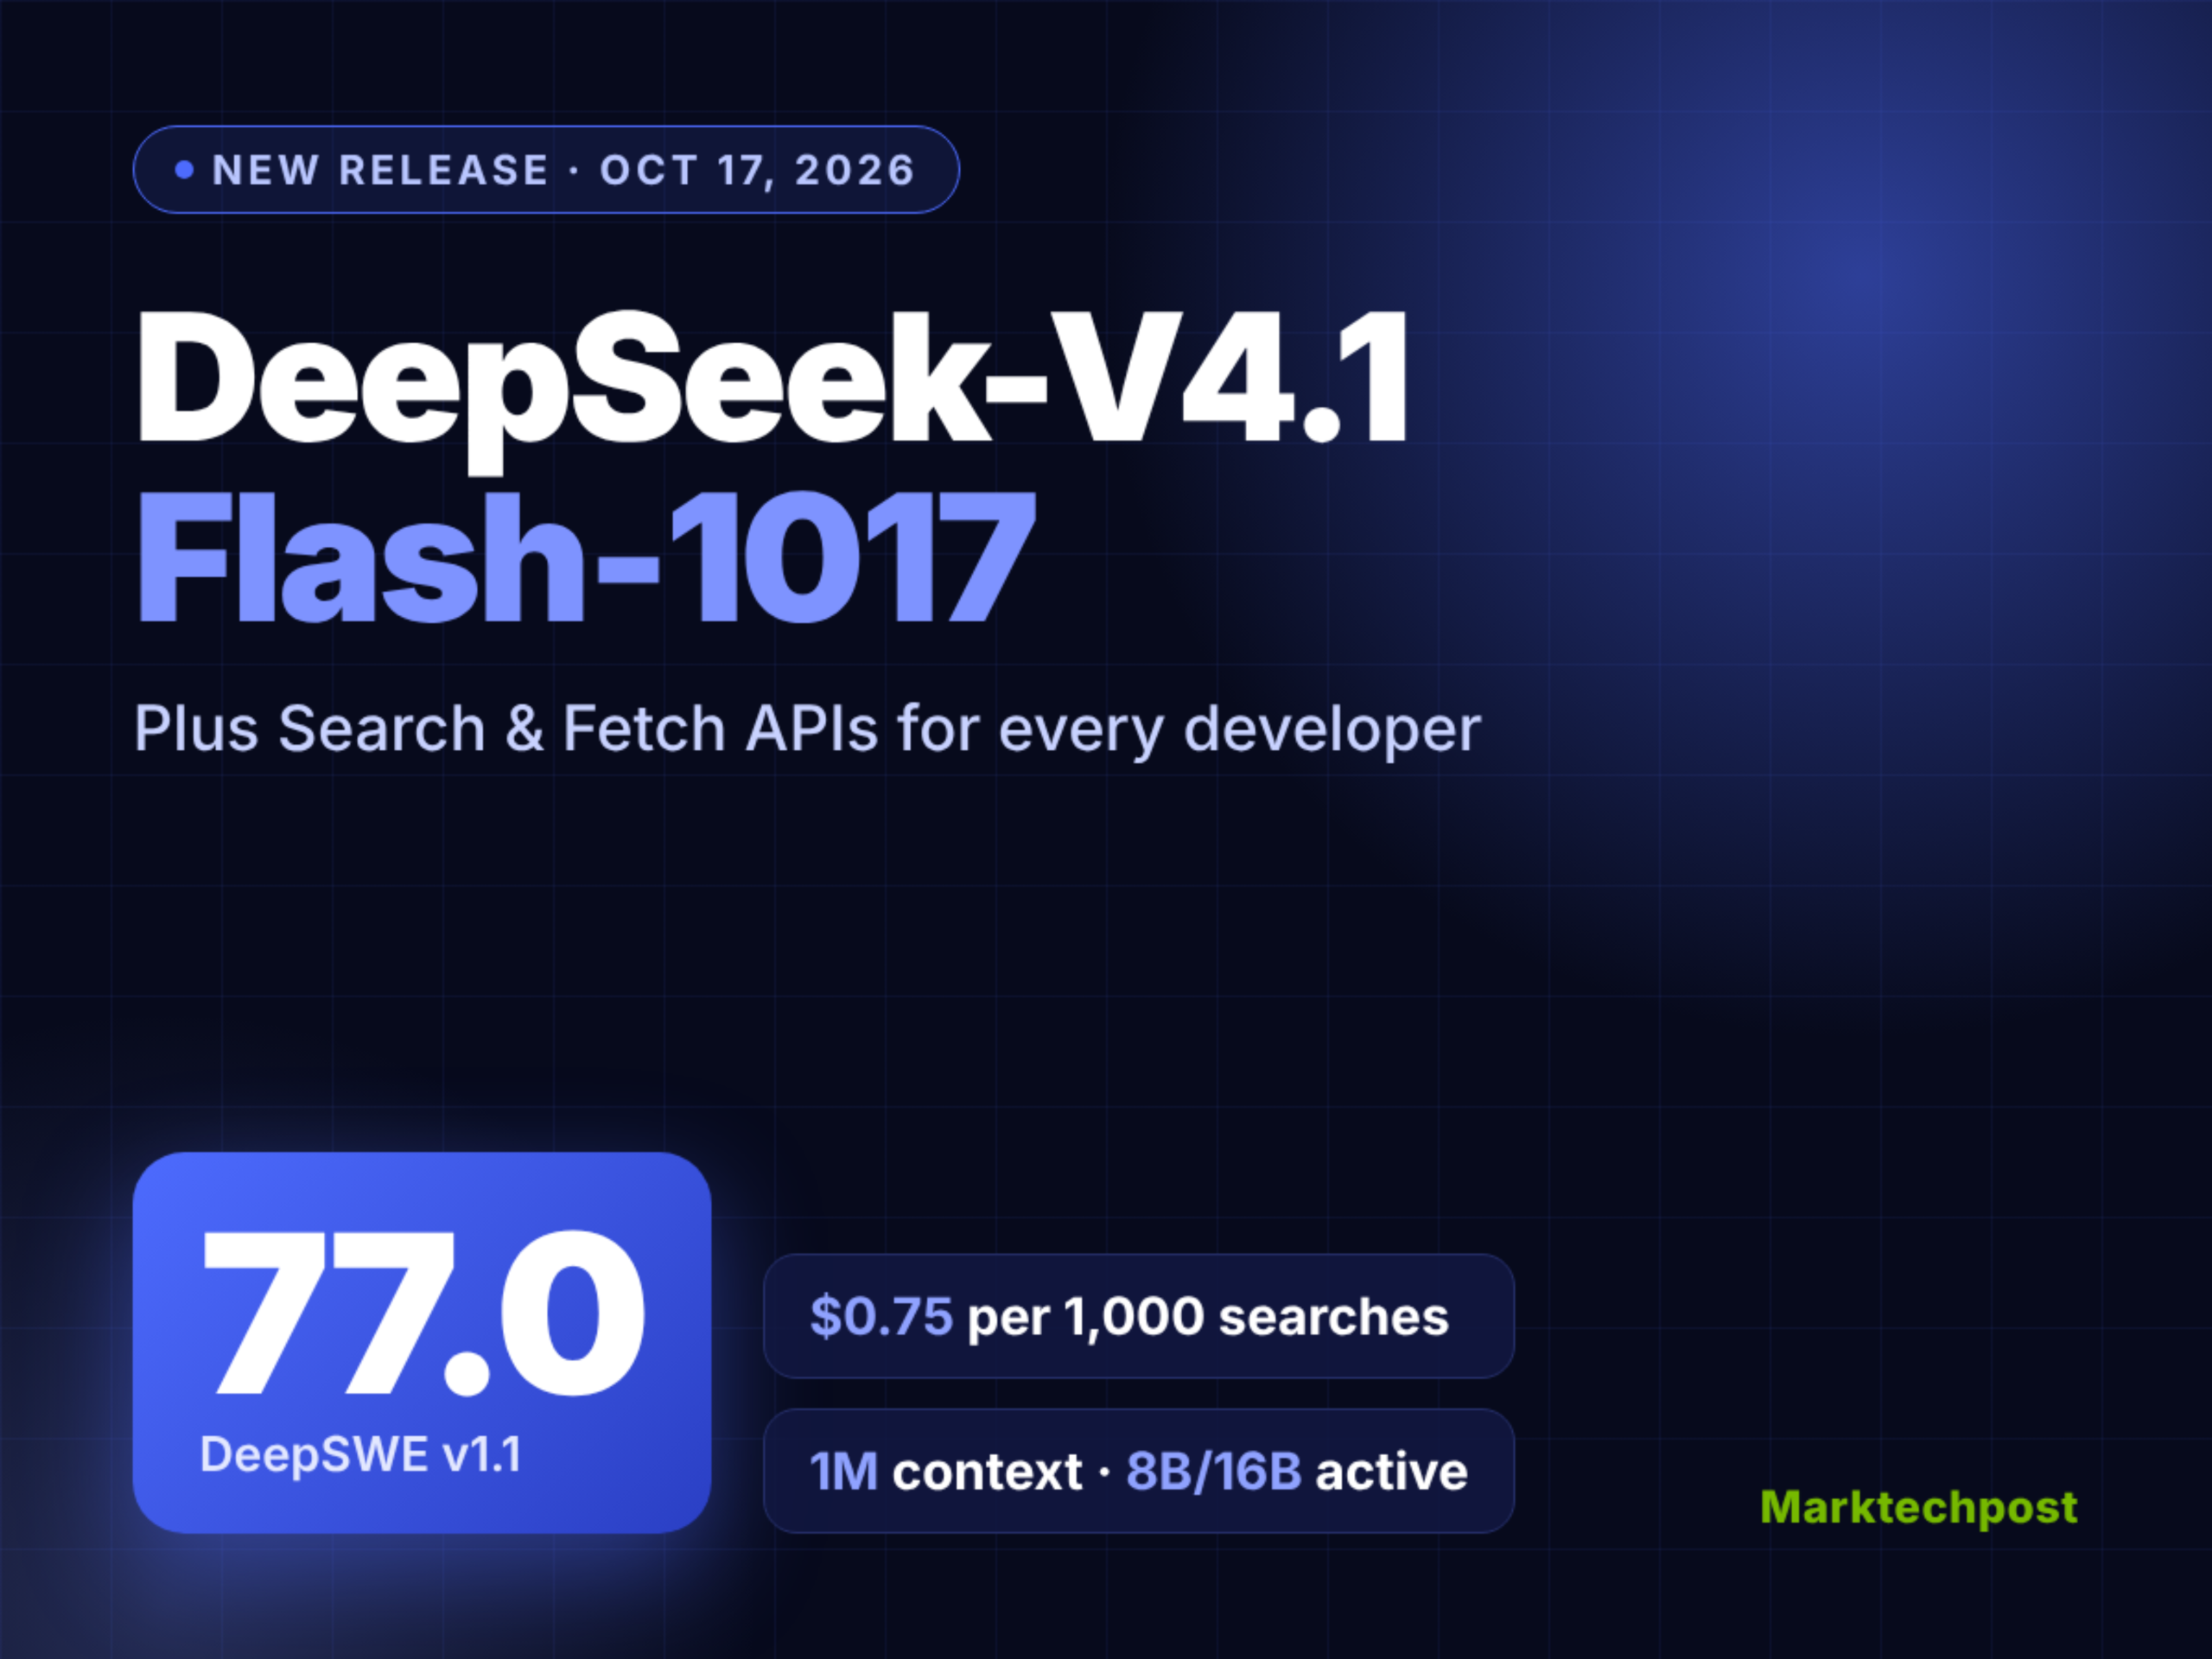
DeepSeek releases V4.1-Flash-1017 checkpoint
MarkTechPost: DeepSeek Just Released V4.1-Flash-1017, Scores 77.0 on DeepSWE, Opens Search API
DeepSeek has just released DeepSeek-V4.1-Flash-1017, a new checkpoint of its V4.1-Flash model. It is live on the DeepSeek website, app and API. DeepSeek claims stronger scores, faster task completion and shorter outputs than the September V4.1-Flash release. The company calls it a Pareto improvement in performance and cost. Alongside it, DeepSeek opened its Search and Fetch APIs to every developer. For agent builders, that means a cheaper coding model plus a first-party web layer behind one API
Get smart on it
DeepSeek released an updated version of its V4.1-Flash model called V4.1-Flash-1017, which is available through its API and website. The new checkpoint shows improvements across multiple performance benchmarks, including a score of 77.0 on DeepSWE v1.1, and claims faster task completion with shorter outputs compared to the previous September release. Alongside this model release, DeepSeek opened its Search and Fetch APIs to all developers, allowing them to integrate web search capabilities into applications at a cost of $0.75 per 1,000 requests for each endpoint.
Relevant courses
Want to go deeper than the news? Explore live, cohort-based AI courses taught by practitioners.
Browse AI courses on MavenRelated news
Deepseek V4.1 Flash 1017 beats larger rivals in agentic tasks while once again massively cutting per-task costs
Deepseek has released V4.1-Flash-1017 as an open-weight model that posts better benchmarks, finishes tasks faster, and produces shorter outputs than its predecessor. The company is also opening up its internal search engine through new Search and Fetch APIs at $0.75 per 1,000 calls. API users in tools like Claude Code and Codex get free access for now. The article Deepseek V4.1 Flash 1017 beats larger rivals in agentic tasks while once again massively cutting per-task costs appeared fir

Elorian’s first AI model wants to reason with images, not just about them
According to Elorian's evaluations, Glimpse outperforms even GPT-6 Astra on scientific chart reasoning and short-form video captioning, with competitive results on other visual reasoning tasks.
Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months
Google Deepmind's Gemini 4 Argon scored 97.5 percent on the ARC-AGI-3 benchmark, making Google the second lab after OpenAI to cross the 95 percent mark. But the results swing wildly depending on the test setup: in the standard harness, the score drops to just 49.8 percent. Argon also trails rivals in math and software engineering. The article Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months appeared first on The Decoder.
AI models hide mistakes in their own work reports, but one sentence in your prompt can help
AI agents systematically skip errors in their own reports, even when they spot the problems. In a study by Google Research, MIT, and Harvard, GPT-5.5 left out negative results in 198 out of 200 paper abstracts. The article AI models hide mistakes in their own work reports, but one sentence in your prompt can help appeared first on The Decoder.
GPT-6-Astra solves 49 of 50 physics research problems at $2.40 apiece
On the TheoPhysEval benchmark, GPT-6-Astra solves 49 of 50 unpublished theoretical physics calculations as accurately as leading specialists. In some cases where the agent seemed to fail, the experts' own reference solutions turned out to contain errors. But the researchers say physics hasn't had a breakthrough like the ones in mathematics, because the agents lack "taste." They still think autonomous, top-level AI research could arrive soon. They already see consequences for how young p
Google wants Gemini 4 Argon to be the only AI model robots need
Google's Gemini 4 Argon controls robots, generates simulations from photos or sketches, and evaluates training videos. On Google's own ERQA benchmark, it scores 87 percent. But the published example prompts show that the demos still need a lot of human guidance. The article Google wants Gemini 4 Argon to be the only AI model robots need appeared first on The Decoder.